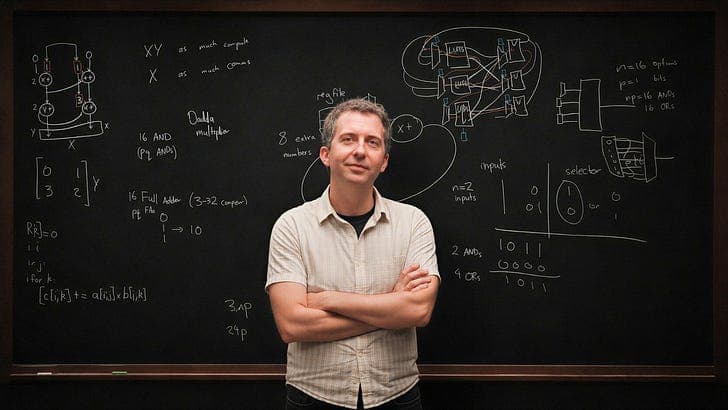

In short
Episode topic: Reiner Pope (CEO of Maddox) explains chip design “from the bottom up,” focusing on how AI chips implement multiplication/accumulation for matrix multiply, why low precision helps, and how systolic arrays reduce data-movement costs versus older GPU/CPU designs. He also covers clock cycles, pipelining, and FPGA vs ASIC tradeoffs.
Guest background
Reiner Pope is CEO of Maddox, an AI chip company. The host discloses he is an initial investor in Maddox.
Key claims
- Matrix multiply repeatedly performs multiply-accumulate (MAC), so MAC is the core primitive for AI chips.
- Low-bit formats (e.g., FP4 vs FP8) scale favorably because compute/area grows roughly quadratically with bit width; NVIDIA’s FP4/FP8 throughput ratios reflect this plus memory/bus packing effects.
- In prior designs, register-file data movement dominates logic cost; tensor cores/systolic arrays shift area toward compute by reusing the weight matrix locally.
- Clock speed is limited by logic delay; designers insert pipeline registers to meet timing, trading throughput vs latency/area.
Notable examples
- Demonstrates a 4-bit x 4-bit multiply with 8-bit accumulation, using AND gates for partial products and full adders for summation (p*q full adders in general).
- Explains MUX cost (AND/OR gate counts) as the “hidden” communication overhead.
- Describes systolic arrays (e.g., older TPUs cited as 128x128) and local weight storage with slow “trickle” loading via daisy-chain.
Written by AI. May contain mistakes. Listen to the episode to check what was said.
Chapters
Tap a time to open that second in VOUnderstanding AI Chip Fundamentals
0:45 to 1:30
Exploring the fundamental components and functions of AI chips.
“which are very simple things like and or not.”
The Importance of Multiplication in AI
1:30 to 3:00
Discussing why multiplication is central to AI chip functions.
“So there's a multiply these two terms, and then we're going to add in, so product of these two terms, and then we're going to add in an eight-bit number.”
Performing Multiplications Step-by-Step
3:00 to 5:30
Detailed breakdown of how to perform multiplication in chip design.
“but then when you accumulate, errors accumulate quickly, and so you need more precision here.”
Using Logic Gates for Partial Products
5:30 to 8:00
Examining how logic gates are employed to create partial products in multipliers.
“So let's take this number one, for example, here.”
Summation Processes in Chip Design
8:00 to 10:30
Describing the process of summing in a chip design and the use of full adders.
“like this is a carryout, whereas this was the sum.”
Fungibility of Chip Circuits
10:30 to 14:00
Analyzing the differences in functionality between FP4 and FP8 circuits in chip design.
“And this is sort of like the standard for how you do error-efficient multipliers using full adders.”
Understanding Floating Point Ratios
14:00 to 15:00
Explore the significance of floating point ratios in chip design.
“But so then when they report those numbers and they just happen to be the case of like it does 2x as many FP4 as FP8.”
Quadratic Scaling in Performance
15:00 to 18:00
Learn about the quadratic scaling of area and performance in GPUs.
“That's why smaller precision is even more favorable than your negative thing.”
Data Movement Costs in GPU Architecture
18:00 to 20:40
Analyze the costs associated with data movement in GPU architecture.
“from the register file to the ALU and back.”
Understanding MUX Functionality
23:00 to 25:40
Examine how multiplexers (MUX) work in chip design.
“And then we have a, so these are the inputs that are being selected between.”
Show all 31 chapters
Evolution of Tensor Cores in GPUs
25:40 to 28:00
Investigate the development of tensor cores and their impact on GPU efficiency.
“This kind of thing is what was inside the CUDA cores, and this sort of problem statement is what motivated the introduction of tensor cores, which are more generically called systolic arrays.”
Understanding Multiply Accumulates in Chip Design
28:00 to 31:15
Learn about the role and computation of multiply accumulates in chip design.
“And just make sure I understand why there's four multiply accumulates.”
Optimizing Matrix Storage in Systolic Arrays
31:15 to 34:15
Explore how to optimize the storage and retrieval of matrices in systolic arrays.
“So like just to complete the picture here of concretely how that looks, I swapped the three and the two here.”
Communication Strategies in Chip Design
34:15 to 36:58
Understand different strategies for managing communication in chip designs.
“That's what we can do in one clock cycle.”
Balancing Compute and Communication
36:58 to 39:14
Learn about the trade-offs between compute efficiency and communication in chip design.
“So already in what we've drawn so far, like, so AI chips all have this, this circuit in it.”
Clock Cycles and Parallel Computing in Chips
39:19 to 42:04
Delve into clock cycles and their significance in the parallel operations of chips.
“So I guess at baseline, it's sort of worth observing that chips are incredibly, incredibly parallel, right?”
Clock Cycle Optimization in Chip Design
42:04 to 46:02
Learn about the challenges and strategies in optimizing clock cycles in chip design.
“And is there ever, because the constraint here seems to be that if you add too much logic, then you might risk missing the clock cycle.”
Pipeline Registers and Performance Trade-offs
46:02 to 49:58
Explore the relationship between pipeline registers, clock speed, and area efficiency in chip design.
“This optimization that I showed here, this is just the sort of pipeline register insertion, it's called.”
FPGA vs ASIC in High-Frequency Trading
49:58 to 52:28
Understand the differences between FPGA and ASIC technologies in the context of high-frequency trading.
“So what you're hinting at is a dynamic where you can have really fast clock speed, but you're not getting that much work done.”
Field Programmable Gate Arrays Explained
52:28 to 56:00
Gain insights into the workings of FPGAs and their role in chip design and programmability.
“So, I mean, firstly, like, let's consider the sort of the business case for an FPGA versus an ASIC.”
Understanding FPGAs and MUXes
56:00 to 56:40
Learn about the role of MUXes in FPGA configurations and programming.
“Where are the wires that made that happen?”
Lookup Tables Explained
56:40 to 58:00
Discover how lookup tables function as programmable gates in FPGAs.
“And so there's a little storage device sitting next to every single one of these muxes saying, this is where you're going to source your input from.”
Cost of Lookup Tables in Circuits
58:00 to 1:00:00
Understand the cost implications of using lookup tables versus traditional gates.
“And so what it does is this table is stored in this blue configuration bit and then it views these four bits as binary, looks up the relevant row of the table and emits that bit.”
Deterministic vs. Non-deterministic Latency
1:00:00 to 1:02:20
Explore the differences between latency in FPGAs and CPUs.
“The MUX is the core of the lookup table.”
Memory Systems in CPUs
1:02:20 to 1:05:30
Learn how CPU memory systems and cache affect performance and latency.
“And then it can give me the equivalent of like, what's an interesting thing I can do here?”
Scratchpad Memory vs. Cache
1:05:30 to 1:07:40
Understand the difference between scratchpad memory and traditional cache in CPUs and TPUs.
“The cache is like two orders of magnitude faster than DDR.”
Modern Hardware and Parallelism
1:07:40 to 1:10:04
Discuss the relevance of the von Neumann architecture in modern parallel hardware.
“but I just don't, like, the FPGA is super parallel.”
Understanding Branch Prediction in GPUs
1:10:04 to 1:11:55
Learn about the role and mechanics of branch predictors in GPUs.
“And so stripping a lot of that out, as well as sort of making these register files tighter in a sense, is driving a lot of where the GPU gains.”
Energy Efficiency in Chip Design
1:11:56 to 1:14:09
Explore the energy consumption dynamics in chip design and its implications.
“You know, any neuron can connect to any other neuron and not in like ways where they'd be column lined or whatever.”
Comparing GPU and TPU Architectures
1:14:10 to 1:17:17
Discover the structural differences between GPUs and TPUs at a high level.
“and then it'll sit idle for a long period of time.”
Systolic Arrays and Data Movement
1:17:18 to 1:20:24
Understand the trade-offs in data movement between GPUs and TPUs.
“smaller vector unit and that is sort of what a an SM is.”
Transcript
Automatic transcript. May contain errors.0:00I'm back with Reiner Pope, who is the CEO of Maddox, which is a new AI chip company. Last time we were talking about what happens inside a data center. Now I understand what happens inside an AI chip. How does a chip actually work? Full disclosure, by the way, I am an initial investor in Maddox. So hopefully you have designed a good chip. Also, if you're listening to this on an audio platform, it's much preferable to watch this Blackboard lecture on a platform where you can see what's happening. So switch over to YouTube or Spotify. So I'll start with sort of the very smallest fundamental unit of chip design, and we'll sort of build up into what an overall, like actual production chip, what are the components of that.
0:41At the very bottom level of a chip, the primitives that we work with are logic gates, which are very simple things like and or not. And then these are connected together by wires that have to be laid out physically as metal traces on a chip. The main function that AI chips want to compute is multiplication of matrices, and really inside that is the fundamental primitive is multiply, accumulate of pairs of numbers. So we're going to sort of demonstrate what that calculation looks like by hand, and then sort of infer what a circuit would look like for that. It'll turn out to be sort of easiest if I do multiplication, of something like a four-bit number with another four-bit number.
1:29And then we're going to, the actual clearest primitive is actually multiply accumulate. So there's a multiply these two terms, and then we're going to add in, so product of these two terms, and then we're going to add in an eight-bit number. All right.
1:50And can I ask a clarifying question? Why is this the natural primitive for whatever computation happens inside a computer? Yeah. So there's a few reasons for this. It's a little bit more efficient, but the reason it's natural for AI chips is that if If you look what's happening during a matrix multiply, what is matrix multiply in very short? It is, there's a for loop over i and over j and over k of output i k plus equals to input I, J times other input, J, K. And so multiply, accumulate happens at every single step of a matrix multiply. Makes sense. And then the other observation is that the precision will almost always be higher in the accumulation step than in the multiplication step.
2:56This is maybe specific to AI chips, but you're multiplying low precision numbers, but then when you accumulate, errors accumulate quickly, and so you need more precision here. So this is why we've chosen to do a 4-bit multiplication and an 8-bit addition. Let me make sure I understood that. There's two ways to understand that. One is that the value will be larger than the inputs. And the other is that if it was a floating point number, it would be... Maybe that part is less intuitive to me, but it's maybe the same principle. It is really the same principle. I guess the separate principle is that as you are summing up this number, you are summing up a whole bunch of numbers.
3:34So you've got a lot of rounding errors accumulating. Whereas in this case, there's only one multiplication in that chain. And so there's not a lot of rounding errors accumulating in the multiplication. Why are you summing up a whole bunch of numbers? It's just two numbers, right? Just, I mean, this summation happens, it's repeated many times. So yeah, any errors accumulate. I see. Yeah, makes sense. So how would we perform this calculation by hand? I mean, as a human, we would probably separate it into two, but we can sort of do it all in one using long multiplication. So the multiplication term first, we're going to multiply this number, this 4-bit number here, by every single bit position in the other 4-bit number.
4:13So we write that out. First 1, 0, 0, 1 multiplied by this bit position, that is this number itself. Then shift it across by 1, we're multiplying by zero that gives us an old zeros number.
4:32Shifted across even one more to multiply by this one we get 1001 and then finally for this last bit position we get an old zeros number again.
4:47So this sort of gives us a bunch of terms that we're going to have to add for the for the multiplication. And then while we're doing that summation of this, we might as well add in the actual accumulated term as well. So we just copy that directly across.
5:09So this is the sum. It's a five-way sum that we're going to want to compute. compute.
5:17So firstly, what logic gates did it take us to even get to this intermediate step? We needed to produce all 16 of these partial products. How do I produce one of these partial products? So let's take this number one, for example, here. It is one, so what was it? How do we produce this number by multiplying this number by this one over here? We can actually to produce that by an AND gate. This number is one if both this bit is one and this bit is one. If either of them is zero, then the multiplication of one times one, of zero times anything is zero. So to produce all of this stuff, we ended up consuming 16 AND gates.
6:00Or in the general case, if I were doing a, like a P bit multiply times a Q bit multiply, then this will be like p times q, many ands. Exactly.
6:20Finally, I sum them. Actually, most of the work is gonna happen in the summing. And so let me describe sort of the other logic gate that we use here. And is almost the simplest logic gate that exists on a chip. It's almost the smallest. At the other extreme, typically the very largest logic gate that you'll use is something called a full adder.
6:46And what this does is sort of it does like coming from software you might think that a full adder adds 32-bit numbers together. In this case it just adds three single-bit numbers together. And so you can think of it as like adding 0, 1, and 1 together. Now when I add these together the result can be 0, 1, 2, or 3. So I can express that in binary using just two bits. So as input it has three bits and as output it has two bits, which in this case are one, like the number two in binary is one zero. So this is also known as a three to two compressor
7:26because it takes three bits of input and produces two bits of output. The two inputs are an x and a by value and then some carry that came in from like. Sorry, the three inputs are all bits that are in the same sort of bit position, like three bits that are in a column here. And then the two outputs, I have sort of drawn them vertically here and horizontally here to kind of match this vertical versus horizontal layout here, which is expressing that things that are in the same column are in the same like bit position. whereas things that are in the JSON columns, like this is a carryout, whereas this was the sum.
8:03So if the inputs in the full ladder are, let's say like 101, then the output would still be 10. If it was 111, it'd be 11. It was 000, it'd be 00. It was like 010, it'd still be 01. So yeah, it's just counting essentially the number of things and expressing that in binary. So this circuit actually can sort of capture what we as humans naturally do when we're doing something along a column. So I can show that sort of, I'll show sort of one iteration of using the full adder to sum. The way I sum here is gonna be a little bit unnatural for humans. Humans, we would sort of sum along the column and then remember the carry.
8:45But instead of remembering the carry, we'll actually just explicitly write it out. So in this, we proceed from the right-most column towards the left. On the right-most column, we sum the one and the one. and that produces like a zero here and a carry of one. So we've sort of used this full adder circuit on this pair of bits and produced a pair of bits as output. Now we can do the same thing with this column. We've got a column of one, two, three, four numbers and so maybe we'll like take the first three of them, run a full adder on them and that gives us a zero and a zero as output. So like the sum of these is 0, 0.
9:24So that's the full adder applied to all of these bits. As I've used up bits, I'm going to sort of just cross them out to indicate that I've handled them. Let's just keep going a little bit more. So we'll go here. I'll take these three numbers. I add them. That gives me a 1 and a 0. I've dealt with these three numbers. And now I take 1, 2, and I can even take these three numbers, for example. right now and add them and that gives me a one and a zero and I've dealt with these numbers.
9:59So I can sort of like the way I should view this is that I have this whole grid of numbers that need to be added. I'm going to just keep applying full adders to all the bits that are here, constantly removing three numbers from a column and then writing out two numbers as output. Keep going with this over and over and over and again until I eventually get like some just one single number coming out here, something like that. This is probably the wrong sum. So this approach that I've described here, this is called a data multiplier.
10:38And this is sort of like the standard for how you do error-efficient multipliers using full adders. Let's try and quantify the circuit size of this, just so we have got a sense of like how big things are, so we can compare to them later. How many full adders did I use? I started with how many numbers? I have the 16 partial products, which is the product of all of these terms, with all of these terms, plus the eight terms that I'm adding here. So I started off with 24 bits.
11:17And then I produced eight bits on the output eventually. And in every step, I was sort of crossing off three numbers and writing two numbers out in result. And so every single use of a full adder eliminates one of the bits here. And so how many full adders, it must be the 24 minus the 8. So there were 16 full adders in this circuit. In general, this is true in the general case as well, there will be p times q many full adders in this circuit. Let me make sure I understand the logic of that. So the input bits 24 is p times q plus p plus q. That's right. And the output bits is just p plus q. and so p times q plus p plus q minus p plus q equals p times q.
12:08That's right. So I think this explains sort of, or at least hints that, the second reason why we chose to do a multiply-accumulate. First reason being that's actually what shows up in matrix multiplication, but second reason being it gave us this very slick p times q, very simple algebra. So we've sort of described, like, this whole procedure, every single atomic step that I took here becomes a logic gate and then sort of the wires connected together. Like when I had these three inputs that I salvaged to produce these two outputs, like if I think of mapping this to a physical device, there would be a wire that runs sort of connecting all three of these things together into a logic gate that produced this output.
12:53Okay, so this is the main primitive at different bit widths that is inside an AI chip. We're going to build up from here to how would you use that to run all of the other operations you might want. This might be the wrong time to ask this question, but whenever NVIDIA reports that this chip can do X many FP4 or half as many FP8, it seems to imply that those circuits are fungible uh that there's not as dedicated like fp4 versus fp8 um but the way you you're mapping it out here it seems like you would need if it has to be mapped out in the logic you would need a dedicated um fp4 multiply accumulate and a dedicated fp8 accumulate basically can you can you funge them as drawn they're actually not particularly fungible.
13:47This is actually one of the main choices you have to make when designing a chip, which is how much of FP4, how much of FP8 do I have? And then sometimes I'll make that consideration from the point of view of like, what do I think is the customer requirement? Another way to take an angle on that is to say, what is the power budget for, equalize the power budget between FP4 and FP8. But so then when they report those numbers and they just happen to be the case of like it does 2x as many FP4 as FP8. They just happen to choose, like give equivalent die areas to all the floating points. And as a result, that ended up being.
14:21Like why is the ratio exactly 2x? Yeah, exactly. Yeah. So part of it is, I mean, surely that won't be exactly like exactly equivalent to die area. There's a data movement reason actually, and we'll maybe come back to this when we sort of look through how it goes into and out of memories. there's something really nice just from a software level of the fact that I can pack two four-bit numbers into the same storage as an eight-bit number. And so when I store that to a memory or something like that, the sizing of the buses that I wire within the chip actually makes that work out really nicely. Actually, come to think of it, it's not just 2x.
14:58It would be the amount of area it takes, it sounds like, is quadratic. It's quadratic, in fact. With the bit length. That's why smaller precision is even more favorable than your negative thing. This is a really big reason. In fact, NVIDIA made a change. Historically, up until B100 or B200, every time you have the bit precision, you double the flop count. That ratio is exactly, like for the reason you said, because of this quadratic scaling, that ratio is actually slightly wrong. It should be like an even bigger, you should get an even bigger speed up than you might otherwise think. NVIDIA's product specs have sort of started acknowledging that in B3 at 100 and beyond, where the FP4 is three times faster than the FP8.
15:47Though it should be 4x. Yeah, what I've shown here is like the simplest case of integer multiply. When you are dealing with floating point, as you do in FP4 and FP8, there's this sort of other term, which is the exponent that just complicates this calculation. So what can we see already from this? It's like, I think the big observation you've made is that there's this quadratic scaling with bit width, which is like very effective and is the single reason why low precision arithmetic has worked so well for neural nets. But the other thing we're going to do now is we're going to compare sort of the area spent on the multiplication itself with all of the circuitry that is around it.
16:31So we'll walk back in time a little bit and see how did GPUs prior to Tensor Cores work, which is the same way as the way that CPUs worked in fact. So which is like, where do we stick this multiply accumulate unit? So generically I'll describe like a CUDA core or a CPU. you'll have some register file which stores some number of entries, maybe it's like eight entries of like, in this case, I guess, 4-bit numbers, but typically like 32-bit numbers or something like that, which are numbers. So this is the, like, inside the CUDA core, I'll have some register file of some depth, and then I will have my multiply accumulate circuit, multiply and accumulate circuit.
17:25And what it's going to do, it's going to take three arbitrary registers from this register file, perform the multiply accumulate, and then write back to the register file. So it's going to maybe write to this one, but it was able to read from this one, this one, and another random one, so it'll take three inputs like this. So this is the core data path of many processes. Most processes look like this. You've got some set of registers, and then you've got some set of logic units or ALUs.
17:59We want to analyze the cost of the data movement from the register file to the ALU and back.
18:07So ultimately, there's going to be some circuit that says, well, I don't always have to select this guy. I might select any of the registers at any point in time. And so sort of a first question is how can I build a circuit? The circuit that I'm going to look for is a MUX. So in this case, it's going to have eight inputs, one from each entry of the register file. And it's going to have one output, which is actually producing this output.
18:35And then like, what is the cost of this thing? It's like all we have to build it out of is and and or. And so how do we build it? We do the dumbest thing possible. We like form a mask saying, okay, when we want to read like the third entry, we're going to and every single entry with either one or zero based on whether that's what we want to read. And then we're going to or all of them together. Okay, just to make sure I understand the basics. What the mux is doing is just like selecting. Just selecting. Just selecting an input. Yeah, so like invisible to software is like you say I want input number three, that means there's a MUX.
19:12Yeah. And so like what is the cost of this MUX? So an N input MUX
19:21operating on p bits.
19:27Well, I'm going to... So I have N rows, that's this eight rows and I've got like each row is p bits wide. Well, I have to AND every single bit. So I get n times p many AND gates. Every single input I have to say, am I gonna like mask it out or not? And then I'm gonna OR them all together. And so there's gonna be like n minus 1 times p many OR gates. Which is saying I've got all of these different things, almost all of them are zeros, but I need to sort of collapse them down into like from my eight options down into one option. And so every step I need to or like one row into an existing row. Got it.
20:09Yeah. It's actually kind of funny that you would sort of, you don't think at the level of hardware, you sort of just think like, oh, I'll just select element three. And something as simple as that is a sort of like in and of itself a quite complicated circuit. Yeah. I mean, this is the first step of all of the hidden data the movement costs that are sharp. And so like the thing, like we're just going to like compare, like I have to pay this cost and I've got one max here. And then in fact, I have two more copies of that for each of the three inputs to my multiply accumulate operation. And so I have this cost, which is like three times n times p and gates over here compared to this p times q, like sort of gates in the actual circuit that is doing the thing I care about.
20:57And if we plug in actual numbers, like this n being 8, I get 24 times p gates over just in the data movement compared to if q is 4, 4 times p gates just in the adder, multiply adder. Sorry, where is the 3 coming from? Three different inputs here. Got it. So the case, really just what I'm hinting at here is that all of this work, which scales like as the size of the register file, and this is a very small register file, all of this work just moving the data from the register file to the logic unit is many, many times more expensive than the logic unit. In the most recent ClusterMax report, Semi-Analysis ranked almost 100 different GPU clouds.
21:44Crusoe was one of only five that made the gold tier. Semi-Analysis found that gold tier providers like Crusoe had a total cost of ownership that was 5 % to 15 % lower than silver tier ones, even when they had identical GPU pricing. This makes sense because total cost of ownership is downstream of a bunch of different things that don't necessarily show up in the sticker price, but that Crusoe has optimized. Things like how well you detect faults and how quickly you replace failed nodes. For example, Crusoe was one of the first clouds to adopt Envy Sentinel, NVIDIA's own GPU monitoring and self-healing software for enhanced GPU uptime utilization and reliability.
22:20This sets Crusoe make use of everything that NVIDIA has learned about why chips fail across all their different fleets and deployments so that Crusoe can catch faults earlier in the process. And once they identify a failure, Crusoe can swap in a healthy node in less than 10 minutes. Because they're not running bare metal, Crusoe doesn't have to spend time installing an operating system or configuring drivers. They can just spin up a new VM on an already running and pre-qualified host. If you want to learn more about this or the other reasons that Crusoe made Gold Tier, go to crusoe.ai slash Dwarakash.
22:52It may be helpful to just see what a mux looks like, maybe like a 2-bit or a 4-bit mux. Yeah, great. So we'll take some inputs. We'll have maybe like, we'll just do a two-way mux. So we've got two different numbers.
Read the full transcript
23:09We've got these two inputs. And then we have a, so these are the inputs that are being selected between. And then we have a selector.
23:23which says which can either be like i want this one or or it could be i want the other one so this is a one-hot encoding um so so this is what we all start with
23:40and then we the output we want to produce like let's focus on this case so so this is the actual input we got. We just want to produce this guy as the result. And so like sort of very laboriously what we do is we AND this bit with all of these and so that produces like ANDing this bit with this row and likewise we AND this bit with this row that produces all zeros. So this was the, there's four ANDs here, there's four ANDs here. And then finally, we just OR these two together. This gives a one, we OR these two together, this gives a one. We OR these two together, gives a zero. We OR these two together, then it gives a one.
24:26And so this is the four ORs. So, like, this actually ends up looking a little bit like addition, in fact. Like we did exactly the same set of ands here. So we've added all of these things together, but then instead of collapsing it by using these full ladder circuits, we just get a very simple collapsing with OR gates. But I guess that doesn't look like n times p. So yeah, so this was with n equals 2 inputs. Ah, right. In the general case, we will have n, sorry, this is n rows, and then we'll have p bits per row. So that gives us the n times p many and gates. So this circuit I've described here, almost all of the cost, like 7 eighths of the cost is in the reading and writing the register file, and only a tiny fraction of the cost is in the logic unit itself.
25:32So this is the problem to solve. This essentially was the state of play prior to the Volta generation of NVIDIA GPUs. This kind of thing is what was inside the CUDA cores, and this sort of problem statement is what motivated the introduction of tensor cores, which are more generically called systolic arrays. So if we think about how are we going to solve this problem, like we're spending almost all of our circuit area on something that we just really don't care about and is hidden to the software programmer, and the thing that we actually care about is not most of the area. Well, make this one bigger somehow while keeping this at the same size.
26:09That's the goal. So sort of the evolution was like we had baked this much into hardware in this stage. This single line is a multiply accumulate, and this single thing was baked into hardware. The idea of a systolic array is to sort of go two levels of loop up and bake this entire loop out here into hardware. And so the idea being that if we have a much bigger granularity fixed function piece of logic, maybe the taxes we pay on the input and output are much smaller. It sounds like you're suggesting that if you go up one step in the matrix multiply loop, that you can tilt the balance more towards compute than communication.
26:54That's right. There's two effects that we're going to take advantage of here. One is just that we can do more stuff per every trip through a register file. And then the other thing we're going to take advantage of is, in fact, In some of this loop we can take advantage of, for example, some certain things staying fixed. So let's sort of visually we're going to look at this matrix multiplication. So this portion of the loop corresponds to a matrix vector multiplication in fact. So we'll take a matrix and multiply it by a vector. So how do we do this? We take every column gets multiplied by the vector and then summed.
27:36So we're going to sum sort of along columns. So this 0 and 3 gets multiplied by the 3 and 7 and gets summed, and then the 1 and 2 gets multiplied by the 3 and 7 and gets summed. So there is a multiply accumulate associated with every single one of these entries in the matrix. So we'll just draw out these four multiply accumulates.
28:04And just make sure I understand why there's four multiply accumulates. So if each entry in the column that corresponds to the output vector is a dot product, and in this it'll be like two multiplications and then the addition of those two multiplications, so like you're accumulating. Yeah, so the addition, so really there's only one addition per dot product, but like we'd like to start with zero. We include the initialization of zero. Yeah. So what we're going to aim for is to have, so we want to have quadratically more compute. We do, we have, we've got sort of x times y as much compute as we had before.
28:51but we're going to want to somehow aim for having only x times as much communication. And this is sort of the intention so that we get this advantage term going as y. So we've laid down the multiplications. We're going to want to bring in a vector of size 2, And so that sort of already is in line with our comms target. That's fine. However, we need to somehow manage the communication of this matrix, which exceeds our budget of X. And so the idea is that in an AI context, this matrix is actually going to stay fixed for a long period of time. And so instead of like bringing it in from the outside, so we've got some register file sitting over here, We don't want to have like the amount of stuff coming out of this register file.
29:47This is the term that we want to go sort of as X in some sense. We don't want to bring this full matrix in from the register file every cycle, because we don't have enough. That would cost too much in terms of wiring from the register file. And so instead, we're gonna store... Our key trick is that this matrix can be stored locally to the systolic array. And so we'll store these numbers 0, 1, 2, and 3 in just like a gate called a register that like physically stores these numbers and we're going to reuse these numbers over and over again for a large number of different vectors. And so the optimization here is that like The nature of matrix multiplication is you can store this square quadratic thing directly where the logic is happening, which has an extra dimension compared to the inputs which you keep swapping in and out.
30:56That's right. I mean, this is the nature of what a matrix multiplication is, is that you do a lot of multiplication to get one value out. Like a dot product is the result of a lot of multiplications. And so that optimization means that you're just like, you can stuff a lot of like multiplication in before you get some value out of it. That's right. That's right. Yeah. So like just to complete the picture here of concretely how that looks, I swapped the three and the two here. Three and two. So just like this 0 and 3 is going to multiply by the 3 and 7, and so we're going to form a dot product sort of along columns here.
31:35So somehow we're going to feed a 3 and a 7 in here. These participate in sort of this feeds into this multiplication and also feeds into this multiplication. Likewise, the 3 feeds into here and also into here. And then we're going
31:57going to sum sort of along here with like starting at the top of a column we feed in zeros and then coming out the bottom we get results coming out. So sort of just to visually see what we've got there's a dot product that is performed along columns in a matrix and that that sort of maps exactly to what is done spatially in the systolic array here. So this is one dot product summed vertically and this is a second dot product also summed vertically. And then what is the data that needs to go into and out of the register file? We have X amount of data that's coming out here on the output and we also have sort of this data coming from the input, X amount of data from the input.
32:41And so with respect to the input and output vectors at least, we've sort of met our goal of having only x as much data going in and out of the register file. This leaves open the question of like, I said that the weight matrix is stored locally in the systolic array. How did it get there in the first place? Is sort of like, at some point you need to boot your chip and populate this data. And so where did that come from? The trick is just, we just do it very slowly. So we very slowly trickle feed it in into the systolic array. The simplest strategy is that we run this daisy chain that says feed a number into here, and then on the next clock cycle it'll move down to the next entry with the systolic array.
33:28And so we can do that in every column in parallel, and that gives us the sort of... This is also gonna come from here, and this is gonna be another factor of approximately x units of bandwidth coming in. Can you just... Would you mind repeating that sentence one more time? So we know that we're going to be bringing in numbers only rarely into the matrix. And so we just want to come up with any construction at all such that the amount of wiring that actually feeds into sort of crosses this boundary of the systolic array, like this boundary right here, we just want to keep that bounded to X and not go as XY.
34:06And so a particularly simple strategy is that we sort of bring in a number into the top row of the systolic array. That's what we can do in one clock cycle. And then for like, for Y consecutive clock cycles, we're going to be bringing in the top row every time, and then sort of shift all of the other rows down by one. And that keeps the sort of the wiring that needs to come from this expensive register file only down to a factor of X rather than X. I see. Okay. So there's two questions in terms of communication. There's like communication time, and then there's communication bandwidth. Yes. And you're saying, since we're only going to be loading this in once, let's minimize bandwidth.
34:50That's right. Because bandwidth equals die area. And let's just like load it in slowly over like smaller lanes, because we're just going to keep this value in there for a while. Exactly. Exactly. Interesting. So it's interesting to me that when we were talking last time about inference across many chips, the big high level thing we're trying to optimize for is increase the amount of compute per memory bandwidth, that is to say per communication. And here also we're trying to increase the amount of like actual multiplies or actual additions relative to transporting information from registers to the logic.
35:27So in both cases, you're trying to maximize compute relative to communication. Yeah, this shows up sort of all the way up and down the stack. This is sort of close to the bottom, sort of like to the gates. there's sort of a version that's maybe even closer to the gates of just like even the precision of number format that you choose to use. We saw that same effect. There's like a square cube law or like squared versus linear term going on both in just purely the precision of this ALU, but then also in terms of the size of the matrix. Yeah, very interesting. So this unit is sort of the next bigger unit.
36:06we had like the multiplication circuit and then on top of that we have a pretty large systolic array. I drew it as two by two but in like for example older TPUs they were described as 128 by 128 of this circuit shown here. And this circuit ends up being, this is the most efficient known mechanism for the circuit for implementing a matrix multiply. I see. So we've talked about sort of, it seems obvious that you should try to maximize compute relative to communication. What are non-obvious trade-offs that actually keep you up at night about, should we do X or should we do Y? And it's not obvious what the answer is.
36:50Yeah. So, I mean, I think most of the decisions in chip design are sizing decisions. And so, So already in what we've drawn so far, like, so AI chips all have this, this circuit in it. They have a systolic array and then somewhere near it, a register file providing inputs and outputs. The two sort of, like, even within this scope, sizing questions that you have are, how big should I make my systolic array? And how big should I make the, the, the register file? the um so and and then the trade-off for the size of this size of the systolic array actually these two questions are coupled is um one way to think of it is to say i'm gonna like have a budget for um how much what percentage of my chip area i want to spend on data movement so maybe i just say that i want this to be 10 and the systolic array to be 90 um and then sort of i can size my register file.
37:53Bigger register files are more flexible. They allow me to run sort of more, I can get more application level performance out. But then they sort of take away from this area spent on the system like a rate. Yeah, makes sense. I recently ran an essay contest where I asked people to write about what I consider to be some of the biggest open questions about AI. The submission window closed last week, so I used cursor to create a couple of different interfaces to help me review the entries. One interface anonymizes submissions and hides unnecessary information. It lets me group responses by question, add notes, and record my scores.
38:25The other interface helps me review entrants who also want to be considered for the researcher role that I'm hiring for. The UI puts the applicant's essay right next to their resume and their personal website so that I can see everything at once. Cursor's Harness is really good at helping these models see and improve their UIs. I watched it render these interfaces in the built-in browser, take screenshots, click through sections, and keep iterating. At this point, Cursor is where I do most of my work. Whether I'm reading and visualizing a bunch of research papers, or coding up an interface to review applications, or making flashcards for my Blackboard lectures, Cursor just makes it very easy for an AI to look at whatever I'm looking at and help me understand it and work with me on it.
39:04So whatever you're working on, you should do it in Cursor. Go to cursor.com slash Dwarkesh. Where does the clock cycle of a chip come in? what determines what that is. Yeah. And what is a clock-slip of a chip? So I guess at baseline, it's sort of worth observing that chips are incredibly, incredibly parallel, right? You've got 100 billion transistors in a chip. A key thing that you need to do whenever you have massive parallelism is you need to synchronize between the different parallel units. In software, typically, you have these very expensive synchronization methods like a mutex. So one thread will finish what it's doing.
39:42It will grab a lock somewhere stored in memory and then notify the other thread that it's done. On chips, we take a very different approach and say that every nanosecond or so, all circuitry in the chip will kind of pause for a moment and then synchronize every... So it actually synchronizes every single nanosecond or so. And so that is the clock cycle. The entire chip typically all in sort of one fell swoop goes in lockstep to the next operation that happens. And so what this looks like in circuitry is that you will have... It's typically drawn... So the clock is sort of mediated by registers, which are these storage devices that we've drawn elsewhere.
40:31And the way to think of it is that I have some storage, which is storing like a bit, which might be zero or one. And then I have some sort of cloud of logic, which maybe is like this systolic array or this multiplier or something like that. And then I've got some, and that's going to produce some output. So my inputs, I've got a bunch of inputs feeding to this cloud of logic. And then eventually later there's going to be some output register that this writes to. There is a global clock signal. Which drives all of these registers. and it says at a certain instance in time when the clock strikes
41:14whatever value happens to be on this wire at that instant that's what's going to get stored in there and so the the sort of the challenge here is like i i would like to have my clock speed run as fast as possible because if i can run at two gigahertz i can get twice as many operations done per per second than if I run at one gigahertz. But what that ends up meaning is that I'm very sensitive to the delay through this cloud of logic because any computation that is going to happen in here needs to sort of finish before the next clock cycle hits. So a major point of sort of optimization on any chip then is to sort of make this delay, delay from here as short as possible.
42:03Interesting. And is there ever, because the constraint here seems to be that if you add too much logic, then you might risk missing the clock cycle. But if you don't add enough, then you're leaving potential compute on the table. is there ever a situation where you're like, you'd take a probabilistic chance that a computation finishes and, or is it just like, no, either it's going to finish by clock cycle or not? Yeah. In standard chip design, you margin it such that, I mean, there is a probability, but it's like many, many standard deviations, like way standard deviations out such that for all intents and purposes, it is a reliable part.
42:47It will always meet the clock. There are some weird exceptions to that. There are clock domain crossings where you go from one clock to the other clock, and then you actually do have to reason about this probability. Interesting. In the main path, you just like, you margin it such that you'll get there like 25 % of the clock cycle in advance. So it's very unlikely. And this, the clock, where the clocks synchronize, I guess, where the registers are, this is not something you determined as a chip designer. This is sort of just like an artifact of, hey, I want whatever sequence of logic. And then the software you use to convert your Verilog into the thing you send to TSMC, that just determines like, hey, in order to make this work, you've got to put a register here, here, and here.
43:38to make sure that there's no one step that is too long, such as it makes the whole clock cycle of the entire chip longer than it has to be. Yeah. So this is actually a huge part of the work of designing a chip, actually, is inserting them. So it is done in a combination of manually and automatically. So, I mean, just to show the very sort of dumb version of what you can do here, you can take this logic and split it in half. And so, say, actually, instead of just one cloud of logic, I'm gonna have two smaller clouds of logic, which do the same thing, but split them up by a register. Right. Feeding in like this.
44:20And this is like, if you split it like in the middle, you can hit twice the clock frequency, that's great, you get twice the performance at the cost of this extra register. And so at the cost of some more storage. And so stepping back, why do we need to synchronize the whole chip? Like if you imagine playing Factorio or something, there's no like global clock cycle. It's just shit is done when it's done. There's iron on the plate. You can take it if you want. Yeah. So taking that analogy, the thing that you need to be mindful of is if I've got two different pads through some logic. So I have to do a computation like F here and then computation G here, and then they're going to come and meet for computation H somewhere here.
45:01Yeah. And so, there's gonna be manufacturing variance here. In some chips, F will take a little longer, maybe in some chips, G will take a little bit longer. And so if I've got some signal that's propagating through here, and the result from F and G have to sort of meet up at H, the thing that can go wrong is that F can get there early, and it meets the previous value of G, or the next value of G, or something like that. And age needs to know when to start. Exactly. Like when has this next iteration of... And so this explains why different chips made at the same process node, the same like TSMC technology can have different clock cycles.
45:46Like two chips made at three nanometer might have different clock cycles based on whether they were able to optimize making sure that like Like there's no one critical path that is so long that it slows down the whole ship's clock cycle. That's right. This optimization that I showed here, this is just the sort of pipeline register insertion, it's called. We've inserted in the middle of the pipeline register here. This is a sort of pure tradeoff between clock speed and area. This is the easy case. There is a harder case too, which is, sort of drawn it as a pipeline of logic here, but in other cases, you may have some calculation which actually feeds back in on itself.
46:32So it runs some function f and then writes back to itself like this. So for example, this might be this addition, like you've got some number that you're adding into every clock cycle. And so this could be like a plus where adding in some number every clock cycle. So this little circuit, essentially it's just gonna sum all of the numbers that are presented on different clock cycles. And the challenge is, if this plus takes too long, what can I do? If I try and put a pipeline register right in the middle of it, like here in the middle of it, this will end up changing the computation that's done.
47:17Instead of forming a running sum of everything that comes here, I will actually have two different running sums. I'll end up having a running sum of the even numbers and a running sum of the odd numbers. So this constraint where I have a loop in my logic, which all chips have somewhere, this is actually the thing that is the hardest thing to address and sets the clock cycle. I don't understand why it would be a problem to have that. Or I'm not sure even what it would mean to have a register there. Like, it's a sort of atomic operation, right? Yeah, well, so plus is not really atomic. Like, I think...
47:50As we just demonstrated. Yeah, yeah. It took a whole lot of work to do a summation. And so, like, you can take the early parts of that work and then stick a register in the middle and then take the late parts of that work. Okay, okay. Yeah. And I guess it's then up to... So TSMC offers a PDK, which says, hey, here's the primitives of logic that we can grant you. in the chip and it's up to them to determine that no primitive is bigger than like the clock cycle they're hoping a process node targets. But other than that, is there like, what further optimizes? Can't you just say like, hey, here's all the primitives from TSMC and keep adding registers in between the primitives as much as is needed until you get to your desired clock cycle?
48:34Yeah, as a logic designer, like the chip architect set the clock cycle. So just for one example, the primitives you get from TSMC are on the order of like AND gates or full adders. They depends a lot on voltage and which library you choose and so on. But generally, you can typically have about like 10 or 20 or 30 of these in a clock cycle sequentially. So these primitives are very, very fast, like 10 milliseconds or something like that. And so as a logic designer, I mean, like in principle, if you literally just had like register and then AND gate kind of in a loop like that, you could get an insanely fast clock speed, like more than four or five, six gigahertz, something like that.
49:21But if you take this really sort of simple circuit and you look at the area you're spending here, this is maybe like one, I mean, this is called one gate equivalent in size. So like unit of one in area and this thing is like unit of eight in area or something like that. And so this is just, again, almost all of your cost has been this synchronization or communication cost compared to the actual logic. And so this would be a case where you've gone too far. You've made your clock speed really, really fast at the cost of spending almost all of your area on pipeline registers. Interesting. So what you're hinting at is a dynamic where you can have really fast clock speed, but you're not getting that much work done.
50:05Yeah, yeah, yeah. And so you can have like low latency, but low bandwidth or throughput rather. Yeah, it hurts your throughput, in fact, because the throughput of your chip you can think of as the product of how much do I get done per clock cycle, which is based on this area efficiency thing, times how many clocks I get per second. This is actually so similar to the thing we were discussing last time about batch size, where if you have a low batch size, then any one user can receive their next token really fast, but the total number of tokens that are processed in, say, an hour will be kind of lower than it could otherwise be.
50:45Yeah, exactly. You get less parallelism out if you drive your clock speed up. I see. Language models are starting to compete against the best human forecasters. I sat down with two senior Jane Streeters, Ron Minsky and Dan Pontecorvo, and asked, at some point, does AI just do what Jane Street does? There's a world that we should take seriously where we're going to build large language models or some other AI systems that are strictly smarter than all humans on the planet and more capable at all cognitive tasks. Trading in particular feels to me as like kind of AGI complete, sort of like NP complete, because at the end of the day, trading involves figuring out what things are worth, which means making predictions about the future.
51:27Jane Street isn't betting against AI. They just signed a$6 billion compute deal. But Ron's view is that the edge keeps moving. I have never been more desperate to hire more engineers and more traders than I am today. You know, you have the usual thing of like the other hard parts that we don't yet know how to automate. Well, that ends up being where the competitive edge lies. You can find these open positions and watch the full interview at jainestreet.com slash Thoracash. Okay, so I remember talking to an FPGA engineer at Chain Street, Clark, who actually helped me prep for the previous interview we did together.
52:01And he was explaining why they use FPGAs. And I imagine that for high-frequency trading, throughput is less important than latency. And so having very specific control over the clock cycle in a deterministic way is the most important thing. Maybe it'd be interesting to talk about how you – why you can't just achieve that with an ASIC or why FPGA is the – yeah, why you might use an FPGA to have deterministic clock cycles for like high frequency trading? Yeah. So, I mean, firstly, like, let's consider the sort of the business case for an FPGA versus an ASIC. FPGAs and ASICs use largely the same sort of conceptual model, which is that I have a series of gates built from ANDs or 6ORs, those like very small primitives, connected together with a fixed clock cycle and connected together with wires that are running in a fixed clock cycle.
53:01So anything you can express in an FPGA, you can express in an ASIC too, and it'll be about an order of magnitude cheaper and like better energy efficiency on an ASIC than an FPGA. The trade-off is that the first FPGA costs you$10 ,000, whereas the first ASIC you make costs you$30 million because it requires an entire tape out. So sort of the business use case for an FPGA would be that I want something that has this very deterministic latency and fast runtime and high parallelism.
53:36But, you know, I'm going to change it very frequently, change what I do every month or something like that. And so then I don't want to pay the tape back cost every time. Now, how does an FPGA actually implement? It sort of like it emulates the ASIC programming model, but in a fixed piece of hardware. And so how does that work actually? So what it has at the base is it's got the two components we just talked about. It's got these registers as storage devices. And then it's got these, these are called LUTs, lookup tables, which actually provide all of the gates. So and then we're going to see even the sort of the third component.
54:21we then have like sort of a swarm of these registers and lots.
54:35And all of these are available and then they are connected by sort of this big set of sort of MUXs. So in front of every single one of these we've got something like one of these MUXs which selects one input from everywhere else, sort of selecting from all of these different things. You know, we've got a whole bunch of different options feeding into all of these things.
55:04So what this allows is essentially a, when I program my FPGA, I can say that I'm going to take all of these components and I'm going to sort of superimpose on top of this a particular wiring which goes through this lot and then feeds into this lot and then goes to this register and then feeds into this lot or something like that. So what I've drawn in orange is how you... FPGA means field programmable gate array. The orange is what has been programmed in the field, whereas the white is all of the wires that must exist in the FPGA in order to actually make the device in the first place. What does it mean to be programmed into a field?
55:43Programmed in the field. So like the device has been deployed in a data center, it's sitting in the field and then you can come and program it. That field isn't like an electric field, that field isn't like out there in the world. Yeah, that world. And so if I look at how the field programming comes out of the first lookup table and goes into the second one, how is it? Yeah, how? Where are the wires that made that happen? Yeah. Yeah. So I got a little bit like lazy in drawing all of these. Every single device here has a MUX sitting in front of it, which can select from all of the nearby circuits that are available.
56:27And so the actual configuration of the FPGA amounts to it. It is the MUX control. So in this MUX here, we have the data inputs, and then we have the control that selects. And so there's a little storage device sitting next to every single one of these muxes saying, this is where you're going to source your input from. Got it. And so programming it consists of configuring every single one of these muxes. So that makes sense. What is happening inside of the lookup table? Yeah. So the purpose of the lookup table, so it's going to also have a little bit of control feeding, telling it what to do as well.
57:07The purpose of the lookup table is to function, to be able to configurably take the role of an AND gate or gate XOR, any of those different things. So there's many ways you could consider doing that. The way it is done in sort of traditional FPGAs is to say it will support. So it will be a lookup table will be. it will have four bits of input, one bit of output. How many different functions are there from four bits to one bit? There are 16 different functions. And so you can actually just tabulate this as like 16 different numbers. You've got a table of 0, 1, 1, 1, 0, 0, 1, 16 entries. And so what it does is this table is stored in this blue configuration bit and then it views these four bits as binary, looks up the relevant row of the table and emits that bit.
58:18So this is a truth table view of lookup tables essentially. Okay, so the lookup table, if you think about an AND gate, OR gate, NOR gate, XOR gate, These are all like take as input. Those are like two input functions. Sometimes we have like more complicated, like a three input function would be a three-way XOR or a four-way XOR. And in this case, how many, it just depends how big it is. Typical size for LUTs is four input, which is sort of just a sweet spot between, there's another computer communication trade-off like here. Like if it has too few inputs, then you need to use more LUTs if it has too many.
58:53But basically the lookup table is like a truth table. It's a truth table. Yeah. And with a truth table, you can program in any gate you want. That's right. And so it's a lookup table, just think like a programmable gate. That's right. And so, I mean, one of the things you can do here is you can see why, where the rule of thumb that an FPGA is like an order of magnitude more expensive than an ASIC comes from, is to count how many gates would be inside this lookup table. Yeah. So we can view this lookup table essentially as one of these muxes. And so it is a MUX with, has to select between 16 different values.
59:30And so it is a MUX with sort of n equals 16 options, p equals 1 bits. And so what we saw way earlier is that this circuit costs like n times p many gates. and so it's like, so it costs like n times p equals 16 AND gates and also 16 ORs. This circuit being the MUX. Yeah, exactly, the MUX. The MUX is the core of the lookup table. The MUX that goes into the lookup table. So the lookup table itself, you can think of as being actually a big MUX that like selects from all 16 rows down to one output. Yeah, okay, I see. That is the lookup table. But the way you've drawn it here, there's like a MUX and then a lookup table.
1:00:19It's muxes all the way down. So, I mean, there is a second mux that is inside here. This mux is this mux. Got it. Okay. And then the other mux is just saying... Where it came from in this sort of mess of gates. Right. And then the second mux is, okay, now you have one value, but that value is still a four-bit value. Yeah. So I've selected four bits from the soup. Right. And then I use those four bits to select which entry in the lookup table I'm going to use. Right. Okay. So like suppose in the first MUX, there's like eight nearby, you're pulling from eight nearby registers as input. And so that's like a total of like 32 bits going in.
1:01:03And then out of that, four bits come out. Those four bits go into the second MUX, which is inside the lookup table. So actually I would say in this case, these registers are single bit registers. So if there are eight nearby registers and lookup tables, then I have eight bits total coming in nearby. I select from eight down to four different values. So there's actually like four different MUXs, one associated with each of these input, like little MUX associated with each of these input bits. Each of them is selecting one out of eight. And where are those eight coming from? nearby registers in other LUTs.
1:01:41And each register is one bit? Yes, yeah. And so I guess AMD or whoever makes these FEJs still has to be opinionated about what registers should connect to which registers. And then you can program in the actual gates, but they add a wire in the communication topology, right? Yeah, so there's sort of like, you get flexibility in a local grain thing. there's a sort of nearby neighborhood where you can select from, but then more grossly, like more coarsely, longer distant connections, they form an opinion on that. Right. Yeah. And the reason it's 10x slower is why? So if you look at the cost of like building this lookup table, it's like 32 gates.
1:02:25Yeah. And then it can give me the equivalent of like, what's an interesting thing I can do here? I can do a four-way and gate. And so that's like, I'm using 32 gates of lookup table to sort of implement like a four-way and means like what is a four-way and I would do like and and and then and of and so to like this is a circuit that I could implement in an asic directly using these three and gates but using a lot I can also implement it but it's going to take like these 32 gates instead of three and so the overhead is really coming from the like the fact that the lookup table, the mux in the lookup table is, there's a more concise way to describe a truth table than listing out every single possible combination of inputs, which is just to like write out the gate.
1:03:19Yeah, like to like place down the polysilicon and the lines and so on. That's right. Yeah. Interesting. One important point he made to me is that the reason they prefer FPGAs to CPUs is because they get deterministic clock cycles. They know when a packet will come in and go out. Why is it not a guarantee in CPUs? So you can actually design a CPU that has deterministic latency as well. And in fact, like the processes that are inside a lot of AI chips actually also have deterministic latency too. Grok has advertised this. TPUs have that in the core as well.
1:03:57The challenge is getting sort of deterministic latency and high speed at the same time. And so where does the non-determinism in latency come from? Non-deterministic latency comes from specific design choices in a CPU. It's actually possible to remove those design choices and make a CPU that has deterministic latency. Those are not very attractive in the market, and so people don't make those CPUs anymore. But actually in some sense, like deterministic latency is maybe a sort of a simpler designing starting point. And then like some chip designers have added things in to be non-deterministic. To take a concrete example of that, probably the most important example is on a CPU just like the CPU cache itself.
1:04:49So in a CPU, you have the CPU, this is the CPU die itself, and then there's a memory off on the side. This is the DDR memory off on the side. And then you have a cache system here. Inside it is the cache that sort of remembers recent accesses to DDR and stores them. And so when I'm running through my CPU instructions, every time I have an instruction that accesses memory, it first checks in cache, was the data stored in cache? And then if not, it feshes out to DDR. This is a huge optimization. The cache is like two orders of magnitude faster than DDR. If you never use the cache, basically all programs would run 100 times slower.
1:05:44So the presence of a cache is absolutely necessary for a CPU to run at reasonable speed. But whether or not you get a cache hit is dependent on the sort of ambient environment of the CPU, like what other programs are running, what has run recently, what is the random number generator inside the cache system doing. And so that is a big source of non-determinism in the runtime of a CPU. So this is sort of the memory system for a CPU.
1:06:12The big thing that you can do differently is instead of having the hardware say, I'm gonna like read memory and then decide, the hardware decides whether or not it comes from cache or not, you can actually bake this decision into software. So a different design philosophy is to, so, and you see this in maybe, for example, TPUs. The TPU instead has, I mean, I'll draw the same diagram, but I'll call it a scratch pad. And so the main difference is, so this would be like a TPU and then HBM in this case rather than DDR, but it's still an off-chip memory. And instead of like the software saying first access like memory and then the hardware decides, you've got some instructions that go here.
1:07:01This is like one kind of instruction and then a totally different kind of instruction that goes to HBM. And so this style is generically known as Scratchpad. instead of cache. The key distinction being that you have like one kind of instruction that says read or write scratch pad and a totally different instruction that says read or write HBM. So scratch pad being the cache? Yeah, this thing here is the scratch pad. Just to be clear. So stepping way back, people say computers have the quote unquote John von Neumann architecture where there's this serial processing of information. And maybe just because we've been talking about parallel accelerators, but I just don't, like, the FPGA is super parallel.
1:07:48The kinds of AI accelerators, TPUs are super parallel. Even CPUs are super parallel, if you think about all the cores they have. And so is it actually, like, in what sense is modern hardware actually the von Neumann architecture? Is that actually a fair way to describe modern hardware? I think it's a fair way to describe CPUs. Like just the amount of parallelism, like on a CPU, the amount of parallelism you get is about 100 cores times maybe like 16-way vector unit. So 106, about a thousand-way parallelism on a CPU. Yeah. One question is, what is the, there is a die that is being used for the CPU.
1:08:22and if there's fewer threads, just as a matter of like transistor voltages are like switching on and off, is it just that there's like literally one control flow, like a small part of the die where like voltages are switching on and off? Or like in what, how do you actually occupy the die area of a CPU if there's only, as opposed to - If there's so few cores, like what am I spending all the time? What is happening in there? The cores are just much bigger and more complicated. So, I mean, like, so I guess we should compare like a CPU core, which takes up one hundredth of the die to like, I mean, to a LUT.
1:09:01Like a LUT is just only these 16 gates. So like, it's clear why there are so many more LUTs in an FPGA than cores in a CPU. But then sort of maybe the, like, why are there more CUDA cores, for example, than CPU cores, I think would be like, why, what's the difference between a CPU core? and a GPU or something like that would be a big difference. Inside the CPU you have, so one big use of, so the sort of the top unit uses of area in a side of CPU are the cache. Very little is actually the ALUs. Like mostly it's like these register files rather than the logic units. And then both of these things have equivalents in a GPU.
1:09:47And so that's not a big difference. But the thing that does not have an equivalent in a GPU is the sort of this branch predictor. And so there is a whole big area in the CPU, which is sort of just a whole bunch of predictors that are saying, when will my next branch be and where is the branch target for that? And so stripping a lot of that out, as well as sort of making these register files tighter in a sense, is driving a lot of where the GPU gains. And what is the purpose of the branch predictor to execute both branches at once or what does it do? So the issue is that when I've got a series of instructions, like instructions, instructions, instructions, instructions, I, if I have a branch like here, if this instruction is branch,
1:10:38the actual processing step of processing an instruction takes a really long amount of time. It takes like maybe five nanoseconds or something like that. So like the time to actually notice that I've got a branch and then like
1:10:54evaluate the boolean, whether it's true, and then update the program counter to the new target and then read from the instruction memory for that. That could take like actually five nanoseconds to finish. And so in reality, this may finish somewhere down here. um i don't want to like but like i want to run a clock speed that is much faster than what five nanoseconds allows like like five nanoseconds is 200 megahertz clock speed i would like to run at one or two gigahertz or something like that and so um i need to run other instructions while the branch is is being evaluated and so i like i really just want to keep running the following instructions that happen after me.
1:11:38But that might have been wrong. Like if the branch ended up being taken, then I need to know that instead of evaluating these instructions, I actually need to like jump to wherever the target is and run these instructions instead. And so the purpose of the branch predictor is like genuinely to predict based on like before you even get to this instruction to be like five cycles earlier to predict there was going to be a branch that's going to happen. So if I think about how the brain works versus what you're describing here, At a high level, the differences might be that while you can do structured sparsity in these accelerators and then save yourself some area that you would have otherwise had to dedicate to these gates, in the brain, there's unstructured sparsity.
1:12:20You know, any neuron can connect to any other neuron and not in like ways where they'd be column lined or whatever. Then there's the fact that memory and computer co-located. I guess you could say in a way the membrane computer co-located on... This is exactly the co-location in some sense of the membrane computer. That's right. That's right. Yeah. Yes, maybe that actually isn't a big difference. And the other, maybe a big difference is that the clock cycle on the brain is much slower than on computers. and partly that's to preserve energy because the faster the clock cycle, the bigger the voltage needs to be in order to identify, for the signal to settle and to identify what state of transistor is.
1:13:05Yeah, that's right. I don't know if you have other high-level takes about how any commentary on what the brain might be doing versus how these chips work. Yeah, I mean, so let's take the clock speed one first, actually. Yeah.
1:13:24The clock speed is quite high on a chip because that, I mean, drives higher throughput. Like when we compare a GPU running some workload, it's running batch size 1 ,000 or something like that. Whereas like the brain is not running batch size 1 ,000. There's only one of me. And so you could sort of imagine saying, well, take a GPU and like instead of running at a gigahertz, run at a megahertz or something like that. And that would start to look maybe a little bit more like sort of equivalent things that you're talking about in the brain. There is, in the way that silicon works, there are, like, that does not give you a 1000x advantage in energy efficiency.
1:14:08So what it ends up looking like is you can, like, you sort of just end up running this circuit once to stabilization, and then it'll sit idle for a long period of time. It doesn't consume a lot of energy while it's sitting idle because most of the energy is consumed in sort of toggling bits from 0 to 1 and back.
1:14:32So actually, let's talk about the energy consumption of a circuit like this. The way to think of a bit being stored is you've actually deposited some charge in a capacitor somewhere, sitting somewhere in the chip implicitly. So it becomes charged when it becomes a one, and then it becomes discharged when it next goes to a zero. And that cycle of like charging the capacitor and then dumping that charge out to ground, that is where the energy is consumed. This is called the dynamic or switching power. This is most of the energy consumption of a chip. There is some other energy consumption just coming from the fact that insulators aren't perfect insulators, but we'll discard that.
1:15:11most of the energy consumption actually comes from just the charging and discharging of, like toggling from zero to one and back to zero. So if you run a chip much slower and you only clock it once every thousand clock cycles or something, you will have a thousand times fewer transitions. It'll be about a thousand times less energy consumption, but not a substantial advantage in energy efficiency. Okay, so you've described how a TPU works at a high level. So what is the difference at high level between how a GPU and a TPU work? Yeah. So, I mean, I think there's sort of a high level organization principle that is different.
1:15:50And then there's sort of inside the cores what are different. But we'll look sort of outside the, like at the high level. So we'll take a GPU and a TPU and what does like sort of the top level block structure look like. If you think of this as the whole chip in each case, the organization of the GPU is mostly a bunch of almost identical units, which are these, these are the SMs. And then they've got an L2 memory in the middle, and then a bunch more of these SMs on the bottom. And so there's sort of this fairly regular grid of cores. And then like if we look at a TPU in comparison, you end up with much coarser grained units of logic.
1:16:44And so you end up with something like some large number of maybe just a few matrix units. These are the big systolic arrays, and then in the middle you've got some vector unit, and then you've got your matrix units at the bottom. So now, matrix units with a vector unit in the middle, this is the whole TPU chip. You can think of scaling this thing down into a really tiny unit with a smaller matrix unit, smaller vector unit and that is sort of what a an SM is. So sort of at a very high level point of view the the GPU has a lot of tiny tiny TPUs sort of tiled across the whole uh whole chip. Oh interesting so like you're suggesting the tensor core within a streaming SM is analogous to an MXU.
1:17:42Yeah it's very very similar yeah. I see and so if you had more like more lack of structure having a bunch of tiny TPUs makes a lot of sense. Whereas if you kind of just have like huge matrix multiplications, you're like, why don't we just, why don't we avoid the cost of having the individual SMs with their own registers and warp schedulers and things like that? Why don't we just like make a huge thing and like amortize those costs across the whole thing? And I mean, I think this shows up in how large you can grow things. We've sort of seen this theme, like especially with a systolic array where larger systolic array amortizes the register file costs better yeah um this sort of design allows you to have larger systolic arrays this whereas the sort of gpu design constrains you to having small units of everything um there is a trade-off however um the there ends up being um because of this sort of coarse grained separation of things there you you need to move a lot of data from the vector unit to the matrix units.
1:18:45And so like you need to move a lot of data through a sort of like two lines of perimeter here. Whereas if you sort of look at the equivalent thing here, you've got vector units everywhere and you need to move data through this line, through this line, through this line, through this line, through this line, through this line. So the amount of data you can move between a vector unit a matrix unit is actually much higher in a GPU than in a TPU because instead of having to move all the data through these just two lines, you're moving all these data through like 16 lines or something of wiring instead in a GPU.
1:19:27Right, but also you might have to move across less area. Which is also a saving. like it's an energy setting. So data ends up moving, like if you can operate entirely within an SM, the data movement is much smaller. But then the moment you want to operate across SMs, like it becomes sort of more complicated and expensive. So you don't have to comment, but one might expect that a thing Maddox might try to do is to get the GPU-like smaller structure of systolic arrays surrounded by SRAM, but also at the same time make it so that like the things you need in an SM to support the CUDA architecture but take a bunch of space you might discard.
1:20:13Yeah we've talked publicly about something which we call a splittable systolic array which is sort of in some sense you can think of as like big systolic arrays that can be small systolic arrays as well. Cool okay I think that's a good note to close on. Reiner thank you so much. Thanks Rakesh.
From the publisher
New blackboard lecture with Reiner Pope: how do chips actually work - starting with basic logic gates, and working up to why GPUs, TPUs, FPGAs, and the human brain each look the way they do.
Reiner is CEO of MatX, a new chip startup (full disclosure - I’m an angel investor). He was previously at Google, where he worked on software efficiency, compilers, and TPU architecture.
Watch this one on YouTube so you can see the chalkboard. Read the transcript.
Sponsors
* Crusoe was one of only five GPU clouds that made the gold tier in SemiAnalysis' most recent ClusterMAX report. Gold-tier providers like Crusoe delivered 5-15% lower TCO than silver-tier clouds, even with identical GPU pricing. This is because optimizations like early fault detection and rapid node replacement don't necessarily show up in the sticker price, but still matter a ton in the real world. Learn more at crusoe.ai/dwarkesh
* Cursor is where I do most of my work—from reading research papers to visualizing technical concepts to coding up internal tools for the podcast. Most recently, I used it to build two different review interfaces for my essay contest, one that anonymizes submissions for scoring and another that lets me see applicants' essays next to their resumes and websites. Whatever you're working on, you should try doing it in Cursor. Get started at cursor.com/dwarkesh
* Jane Street let me ask Ron Minsky and Dan Pontecorvo, two senior Jane Streeters, a bunch of questions about how they use AI. We discussed everything from the types of models they're training to how they think about the future of trading to why they're more bullish than ever on hiring technical talent. You can watch the full conversation and learn more about their open positions at janestreet.com/dwarkesh
Timestamps
00:00:00 – Building a multiply-accumulate from logic gates
00:16:31 – Muxes and the cost of data movement
00:26:10 – How systolic arrays work
00:39:11 – Clock cycles and pipeline registers
00:51:51 – FPGAs vs ASICs
01:03:25 – Cache vs scratchpad
01:07:27 – Why CPU cores are much bigger than GPU cores
01:12:00 – Brains vs chips
01:15:33 – A GPU is just a bunch of tiny TPUs
Get full access to Dwarkesh Podcast at www.dwarkesh.com/subscribe



