
In short
Latent Space: The AI Engineer Podcast Episode Summary
Podcast Overview Title: ICLR 2024 — Best Papers & Talks (ImageGen, Vision, Transformers, State Space Models)
Guests
Durk Kingma, Christian Szegedy, Ilya Sutskever Description: This episode discusses key highlights from the International Conference on Learning Representations (ICLR) 2024, focusing on significant papers and talks related to image generation, vision learning, transformers, and state space models.
---
Key Themes and Topics
- Introduction to ICLR 2024
- General Context: ICLR is emerging as a prominent conference in deep learning, focusing on innovative research and architectural developments.
- Audience Engagement: Encouragement for listeners to share the podcast for further discussions and insights.
- Best Paper Awards and Highlights
- The episode begins with discussions on the Best Paper Awards at ICLR 2024, specifically focusing on:
- Variational Autoencoders (VAEs) and their implications.
- Image Generation advancements, particularly diffusion models, and their applications.
- Detailed Paper Reviews
A. ImageGen, Compression, and Adversarial Attacks
- Key Papers Discussed:
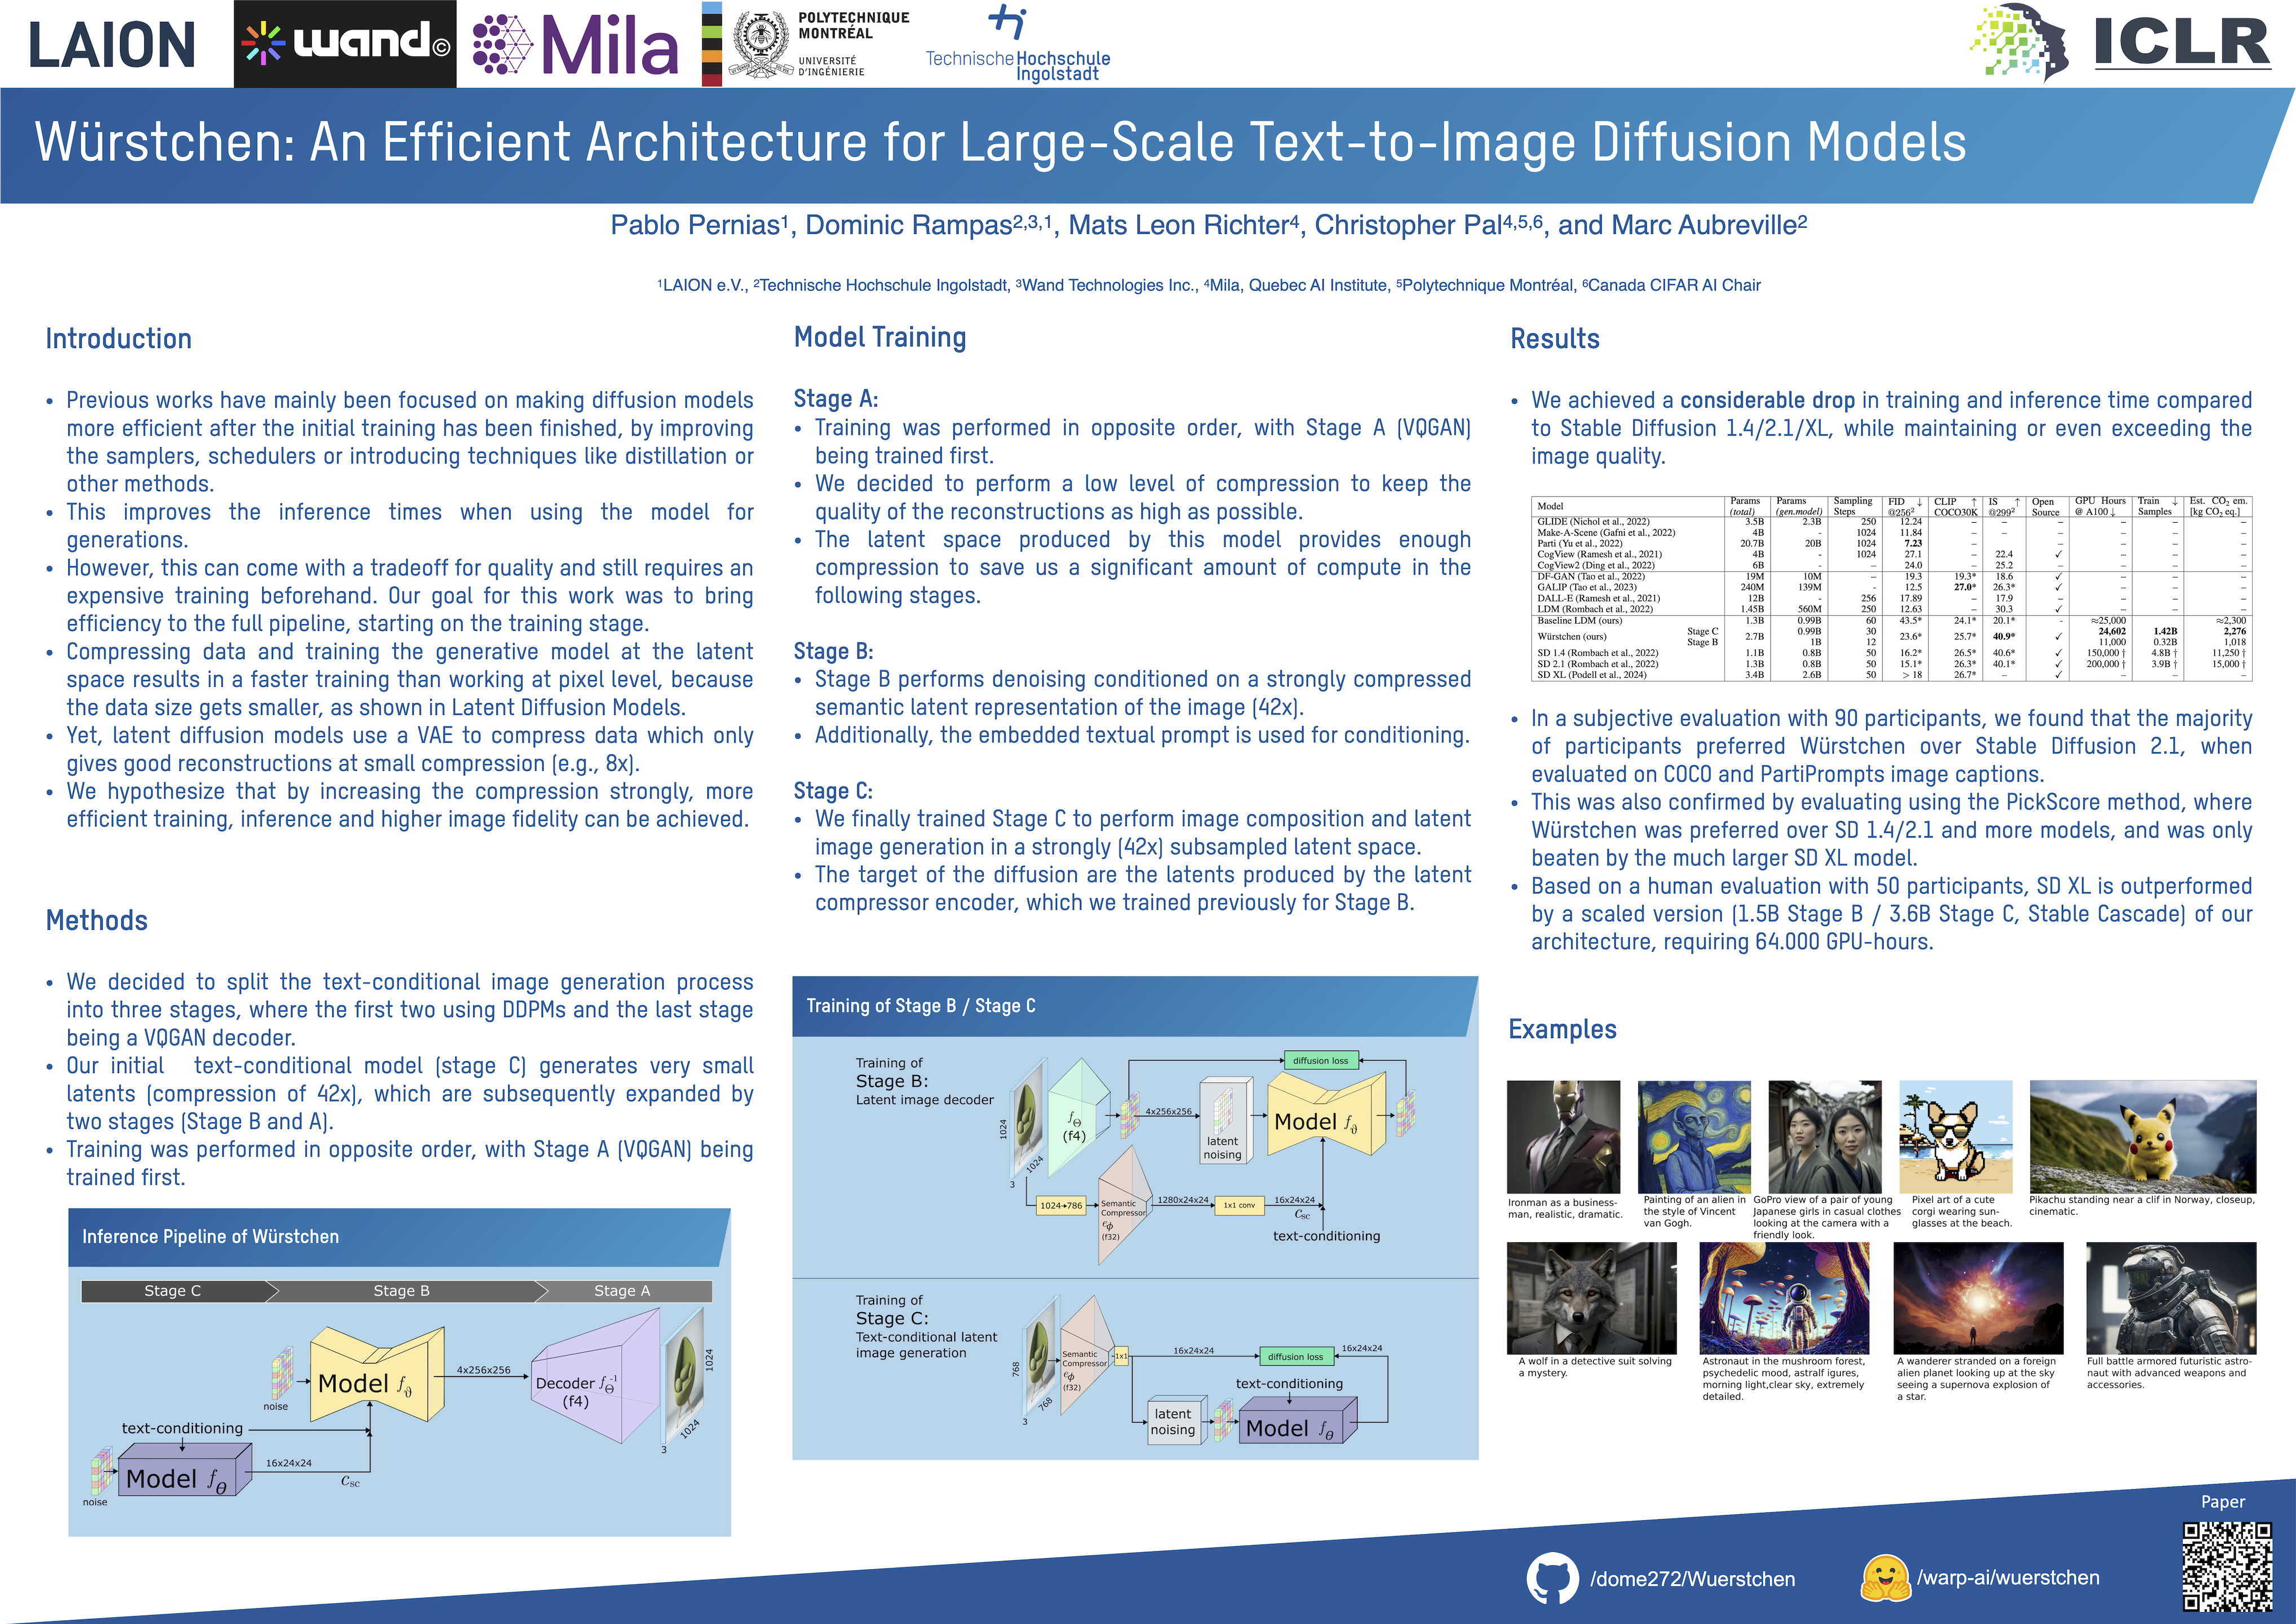
- Würstchen: An efficient architecture for large-scale text-to-image diffusion models.
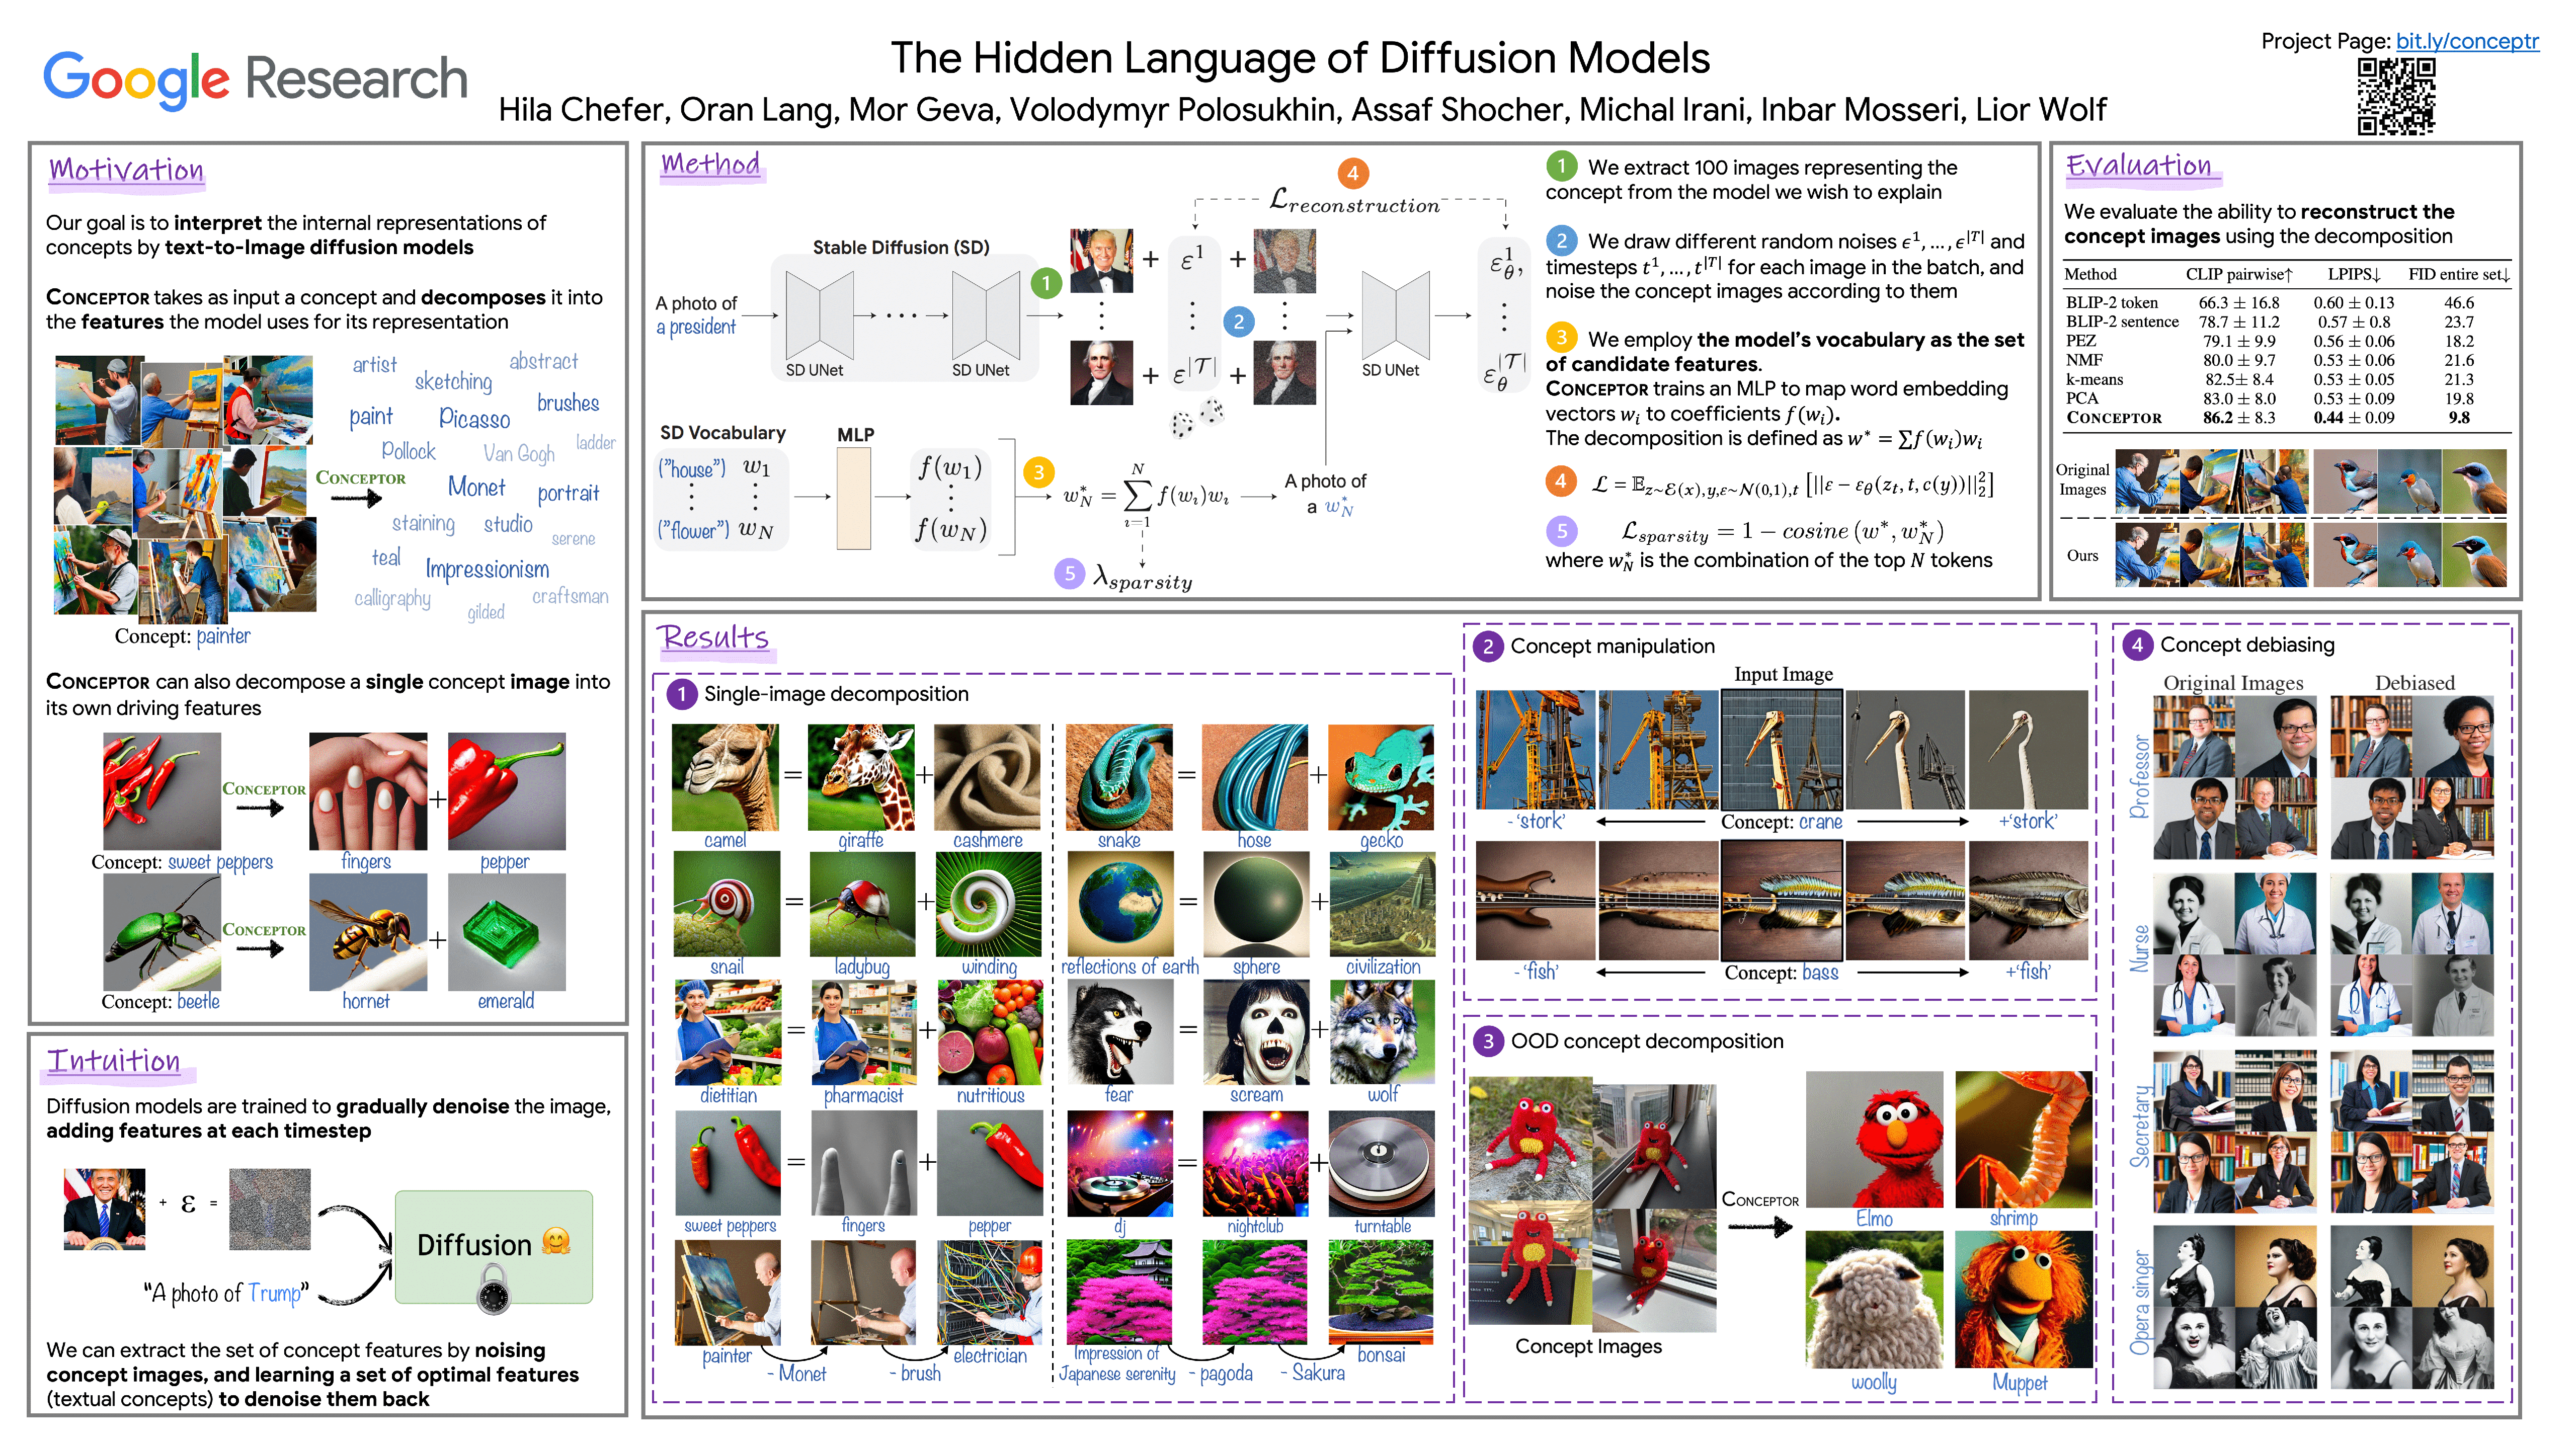
- The Hidden Language of Diffusion Models: Investigation into the interpretability and functioning of diffusion models.
- Christian Szegedy's Talk: Discussed the properties of neural networks and their vulnerabilities to adversarial attacks.
B. Vision Learning and Weak Supervision
- Key Papers Discussed:
- Vision Transformers Need Registers: Introduced the concept of "registers" to improve attention mechanisms in vision transformers, reducing artifacts.
- Training with Pause Tokens: Explored the impact of introducing pause tokens on model performance across various tasks.
C. Extending Transformers and Attention
- Key Papers Discussed:
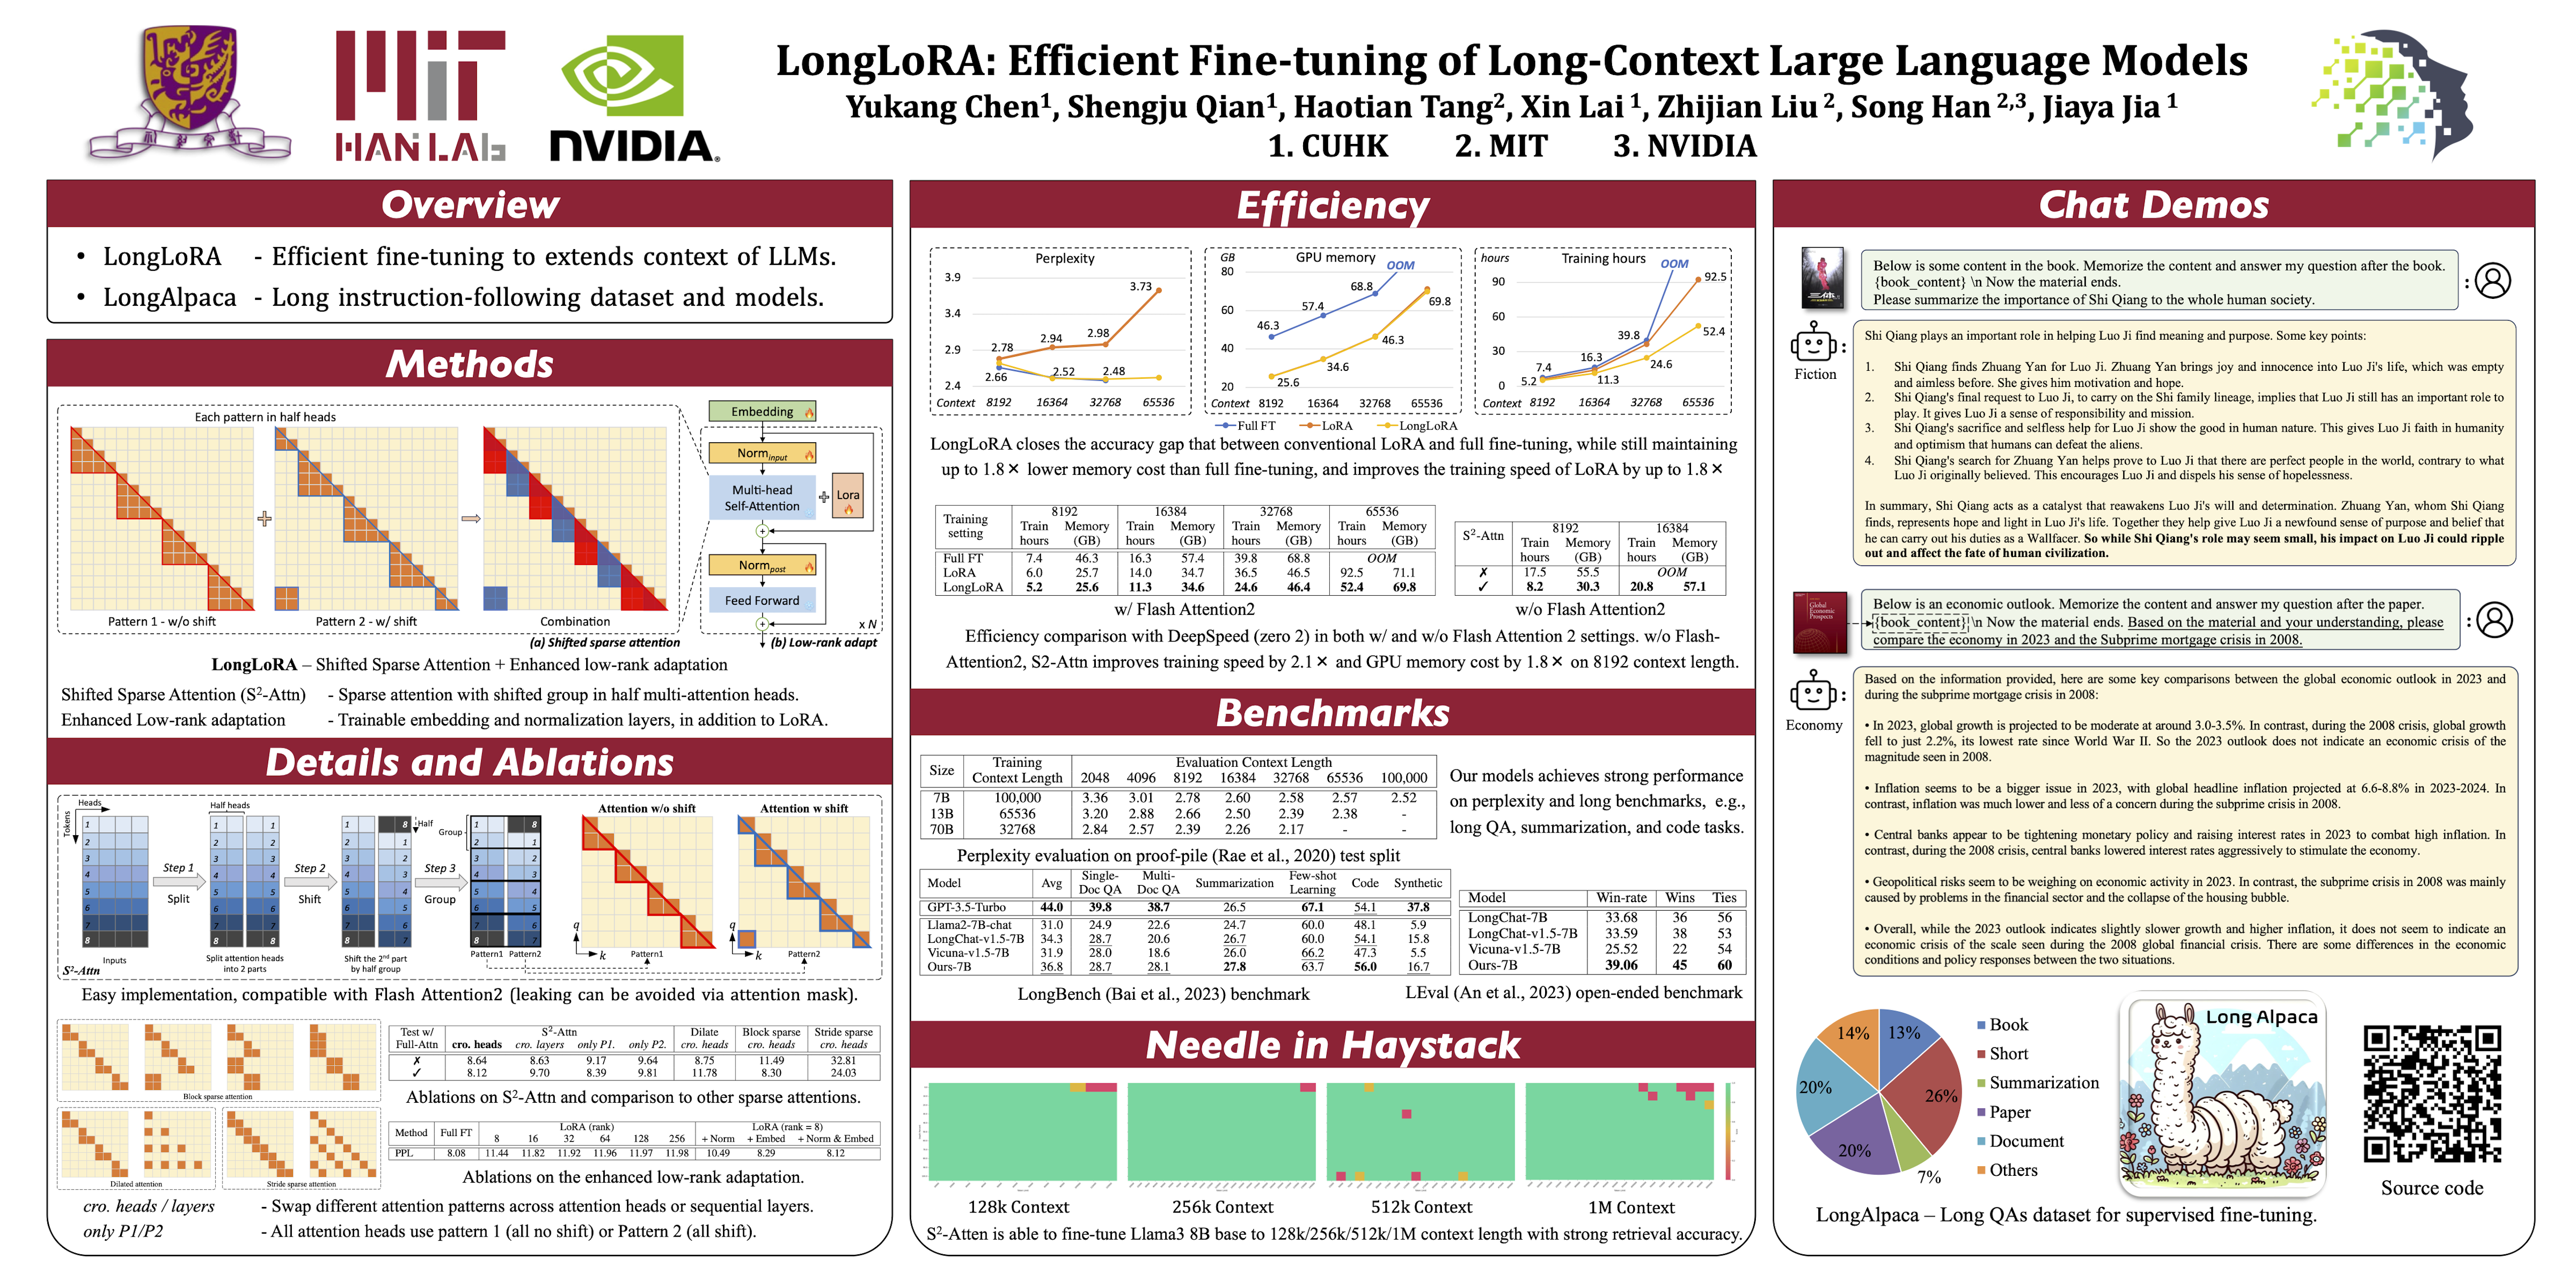
- LongLoRA: Efficient fine-tuning methods for extending the context of large language models.
- YaRN: Introduced a context window extension method for large language models that showed promising results.
- State Space Models vs. Transformers
- Key Insights:
- Discussion on the importance of training methods and data-driven priors when comparing different architectures like state-space models and transformers.
- The necessity of pre-training models to achieve optimal results, especially in tasks requiring long-range dependencies.
---
Key Takeaways
- VAEs and Diffusion Models: These architectures have fundamentally changed approaches in generative modeling, combining efficiency and effectiveness.
- Vision Transformers and Attention Mechanisms: The introduction of registers and adaptive mechanisms can significantly improve model performance while reducing artifacts.
- Importance of Contextual Awareness: Models need to be designed with an understanding of long-context requirements in mind, with innovative approaches like LongLoRA and YaRN demonstrating potential.
- Future of Architecture Design: The integration of theoretical insights with empirical results is crucial for advancing the efficacy of machine learning systems.
---
Conclusion
- The episode serves as a comprehensive round-up of ICLR 2024's major contributions and ongoing research discussions in the AI and machine learning community.
- The next episode promises to explore reasoning and agents, which are becoming increasingly pivotal in AI engineering.
For more details, refer to the full show notes and additional resources available on [Latent Space](https://latent.space).
Written by AI. May contain mistakes. Listen to the episode to check what was said.
Transcript
Automatic transcript. May contain errors.0:07Welcome to the Latent Space podcast, ICLR edition. This is Charlie, your AI co-host. This month we attended the 12th International Conference on Learning Representations in Vienna, Austria. ICLR is a newer conference, but already gaining a lot of popularity as a deep learning-focused academic research conference, roughly half the size of Neuropies. Many of you absolutely loved our NeurIPS coverage last year. And while we can't do that for every conference, we're proud to bring you a special two-part episode covering our attempt at giving you an audio experience of ICLR. If you'd like to see us return to Vienna for ICML, let us know by sharing this episode on X and LinkedIn.
0:51For our subset of AI engineering concerns, which you can see on the Latin Space About page, we're saving agents and reasoning topics and introducing everything else we saw at ICLR. This episode covers the best papers across Section A, Image Generation and Diffusion, Section B, Computer Vision and Weak Supervision, Section C, Improving Attention Algorithms, Section D, State Space Models, and the rest of the poster sessions we saw. This is the first of two episodes covering ICLR and will be overwhelmingly academia-focused. If you're interested in production AI engineering and industry, you should join us at the first AI Engineer Worlds Fair this June, where we have now announced many of our speakers from all the big clouds, including Microsoft Azure AI and GitHub CEO Thomas Domka.
1:44All the large model labs including OpenAI, DeepMind, Mistral and Adept. All top AI-enabled developer tools and Codigen agents including fan-favorite guest Chris Latner of Modular and Scott Wu of Cognition Labs Devon. Major GPU and inference providers like NVIDIA, GroK, Fireworks and upcoming guest gradient AI. all the rest of the emerging LLMOS stack of startups and open source tools across RAG, Multimodality, LLMOps and agent frameworks like Instructor, Langchain, Lomindex, DSPi, Unsloth, Crew AI, disruptive startups like MidJourney, Perplexity and Character AI and for the first time, talks about AI deployed at massive scale from Salesforce to Novartis to Tinder to Coinbase to Khan Academy.
2:38Get your tickets now and see you in San Francisco from June 25th to 27th. We'll start this episode with an extended meditation on what deep learning representations really entail. The inaugural ICLR Test of Time Award went to Kingmer and Welling for auto-encoding variational bays, the paper that introduced the variational auto-encoder, a key precursor to diffusion models. But first, we'll introduce what VAEs are, and then have Dirk Kingmer talk about his 10-year retrospective on the VAE in his Test of Time Awards speech. But first, the best way to introduce VAEs is to start with a clip from the Archive Insights YouTube channel, which we've linked to in the show notes.
3:21We start from a basic knowledge of autoencoders, build-up to denoising autoencoders, and then the key things to know about variational autoencoders. Watch out and take care. Okay, so that's the basic idea behind autoencoders. But there are a few very clever tricks that you can apply to an autoencoder to have it do some really fancy stuff. So imagine that you start with a normal MNIST digit. It's a clean image, nothing's wrong with it. But then you add a whole lot of noise to it and you're going to run that noisy image through your encoder network. You get through the bottleneck representation and then you try to reconstruct the image, but instead of reconstructing the noisy image, what you're going to do is try and reconstruct the original clean image.
4:03And if you train this network on a whole bunch of these noisy MNIST digits, you're going to try and force the encoder step to actually get rid of the noise. And this is what we call a denoising autoencoder. And so you can see here that by using this approach, you can actually train a denoising autoencoder that is very good at removing noise from input images. And denoising images isn't the only thing that you can do with this type of approach. So in this case, for example, you take an input and instead of adding noise to it, you simply crop a rectangular area out of the image and you throw it away.
4:33You replace it with white or black pixels, you feed that input image through the network and you try to reconstruct the original full image. And this technique is what we call neural impeding. It's where you take a small part of the image, you throw it away and then you ask the network to reconstruct whatever was there in the input image. And with this approach, you can do simple things like removing watermarks from images, but you could also remove a parked car, for example, if you are filming on a movie set in a natural setting. Okay, so now that we have the basic concept behind a normal autoencoder, let's introduce variational autoencoders.
5:05So the idea behind variational autoencoders is that instead of mapping any input to a fixed vector, you want to map your input onto a distribution. So the only thing that's different in a variational autoencoder is that your normal bottleneck vector z is replaced by two separate vectors, one representing the mean of your distribution and the other one representing the standard deviation of that distribution. And so whenever you need a vector to feed through your decoder network, the only thing you have to do is take a sample from the distribution and then feed it to the decoder. And so to train a variational autoencoder, the loss function in this case actually consists of two terms.
5:42The first term represents the reconstruction loss. So this is really the same as the autoencoder step, except that here there is an expectation operator because we are sampling from a distribution. And then the second part of the loss functions is what we call the KL divergence. I'm not going to go into all of the details because there is a lot of math involved there, but basically what you want to make sure is that the distribution that you're learning is not too far removed from a normally distributed Gaussian. So you're going to try and force your latent distribution to be relatively close to a mean of zero and a standard deviation of one.
6:17And so finally, before we can start training our variational autoencoder, we have one final trick that we have to use. Because if you look at the computation graph of our network right now, we have a problem. In the middle of that network, after the bottleneck, we have a sampling operation. There is a node there that takes a sample from a distribution and then feeds that sample through the decoder. But the problem is that you cannot run back propagation, you cannot push gradients through a sampling node. So this is an issue. And so in order to run your gradients through the entire network and train everything end to end, we're going to use what we call the reparameterization trick.
6:51And so the trick goes as follows. If you look at the latent vector that you're sampling, you can actually look at that vector as the sum of a fixed mu, which is just a parameter that you're learning, plus some kind of a sigma, which is also a parameter that you're learning, and then multiply it with an epsilon, and this epsilon is where we're going to put the stochastic part. So this epsilon is always going to be standard caution. It's always going to have zero mean and standard deviation of one. We're going to sample from that epsilon and then multiply it with sigma, add mu, and we have our latent vector.
7:22And so the clever thing here is that now our mu and our sigma, those are the only things that we actually want to train. So there we have to be able to compute gradients and run backpropagation. But that epsilon, well, that doesn't really matter because we don't want to change that epsilon ever again. That epsilon is a fixed stochastic node. Okay, it's still stochastic, but we don't have to run backpropagation through it. So it doesn't matter that it's a sampling operation. And so this is the reparameterization trick, where instead of having a full stochastic node that is blocking all of your gradients because you can't do backpropagation through it, you're going to split it up into a part where you can do backprop and then another part which is still stochastic but which you don't want to train because it's fixed.
8:03Pretty clever, right? Once again, that was the very excellent Archive Insights channel which we felt was the best explanation of VIEs and the reparameterization trick we could find. However, to really understand VAEs, there is a lot of math and code that we are skimming over for the sake of time. Check the show notes for more helpful videos. We return to ICLR to hear Dirk Kingma talk about his 10-year retrospective on the VAE in his Test of Time Award speech. This work is great because it brought ideas from deep learning and probabilistic models together and introduced many novel techniques, such as amortized inference, reparameterization trick, and the use of lower bound to jointly optimize both the encoder and decoder.
8:50In fact, the ideas are so good that two groups of people came up with it at the same time. So there's another paper on this concurrent work shortly after, proposed by Danilo Rezende, Shakir Mohamed, and Dain Vastra, which was published in ICML 2014. maybe they'll also get a test of time award in the same conference venue. So, well, now 10 years after, looking back, we can all agree that this was a great contribution and we are very happy to have this paper as the first ever inaugural test of time award for iClear. So thanks to both the authors and the other co-inventors and everybody else who's been using these things to make this really great.
9:36And this has given a lot of progress. Lots of things have come out of this great work. So looking forward to your talk. So please take it away. All right. So let me first say that it's an absolutely huge honor to get the first ever Test of Time Award. So thank you very much to the conference chairs as well as the award committee to award this to us. I'll quickly start because we have a lot to say. So first a little bit of history. Let me kick it off with a few historical notes. Of course, a very key important part of the variational autoencoder is the encoder, the autoencoder, in fact. And so here, the first paper I could find is from Mark Kramer in 1991.
10:21And the idea is, of course, that you have a deterministic map from a high-dimensional signal space into a low-dimensional code space and then try to predict it back out. And because you have to compress the representation, you will find interesting sort of structure in there. In 2008, an important follow-up from that was the denoising autoencoder, where you add noise to the input, and then you ask the model to reconstruct the input despite of the noise. And that releases it from having to deal with lower dimensional representations. Later, it was also connected to score matching. And of course, we all know that score matching is very important for modern sort of diffusion models.
11:04The paper that I recall that we extensively discussed working on the VE was the Helmholtz machine. So the Helmholtz machine does have already a recognition network and a generative network. But it's also different in many ways. It has many stochastic layers. These units are binary. It was trained using mean field methods. And more importantly, the objective has changed to what's called the wake-sleep algorithm. where for the optimization over the recognition network, you flip the order of the arguments of the KL. But it is interesting that in that paper, you already find the elbow objective. And then finally, as was already mentioned, I want to mention this paper, which came out concurrently called stochastic backpropagation.
11:46And you'll find almost all of the things that we did in the variation autoencoder paper also mentioned in this paper. And I'll hand over to Dirk, who will tell you the discovery process. I think it's interesting to look back a little bit on the context around when we wrote this paper. And obviously, one of the things that happened a few years prior is the development of deep learning. So deep learning at that time was really mainly a method for large-scale supervised learning. Essentially, it's a recipe where you combine a deep fear forward neural network with the maximum likelihood objective and the STD optimizer.
12:30So supervised deep learning was really a method for efficiently optimizing fully observed directed graphical models. So this is a subset of graphical models where all variables are observed during training. So there are no latent variables. And this setup sort of extends to a lot of interesting models, including a lot of models that we're still using today, including language models, which are autoregressive models, but they're fully observed in this sense. So we were wondering whether we could extend this family of models or the success of deep learning to a broader family of models. So one big disadvantage of fully observed models is that it doesn't really scale well to very high dimensional input spaces.
13:22So you can scale fully observed models to high dimensional spaces using outer regression, right? This is today still used in language models. But one big downside of this approach is that it doesn't really scale well to spaces is because you have to sample the dimensions one by one conditioned on the previous dimensions. It's still okay for language models, especially if you use a tokenizer, because that reduces also the input dimensionality. But for images or videos, etc., it's not really an ideal approach. So you need to do something else. So one way to solve this is to introduce latent variables.
14:00So what are latent variable models? In these types of models, we introduce a latent variable z, and we assume that the data that was observed is generated by first generating a latent variable z, and then we have some non-linear mapping, for example, a neural network that maps that relatively simple space of z to the observed space x. And we also then often define some joint distribution p of x given z, which is then often vectorized as pz times p of x given z. So an advantage of this model type, there's a couple of advantages. So one is that sampling can be a lot more efficient, especially on parallel hardware.
14:43So given Z, the distribution of P of X given Z can be factorized over dimensions. So we can generate all dimensions of X in parallel, which is great on GPUs, for example. It can result in an interpretable and controllable latent space, which allows for controllable generation. and another advantage is, for example, that we can map from a discrete x space to a continuous z space and back. However, it also comes with a lot of challenges. The main one is optimization. So the marginal likelihood p of x is in general intractable to compute. The posterior of p z given x is intractable to compute, which also means that maximum likelihood is intractable to do exactly.
15:27So we need to come up with approximations to solve this interactability problem. And before we came up with VAEs, we tried a couple of other approaches. So one is MAP, where you simply treat each latent variable as an optimization parameter. You can just apply SGD to those parameters just as any other parameter. But the problem is that you need an iteration per data point to find the optimal parameters, and it can overfit fairly quickly. Another approach is to do Bayesian inference per data point to find a true posterior or an approximation of it. This solves the overfitting problem, but it's very slow because you need iteration per data point.
16:09Or you could use wake sleep from the 90s and this works okay. It's very fast, but the problem is that it doesn't really result in great models in general we found because it's a poor approximation to maximum likelihood, at least in our experience. and in our experiments. So that was essentially the context of VAEs. In our paper, Autoencoding Variational Base, from 10 years ago, we introduced the framework of variational autoencoders. And it's essentially consisted of three main ideas. The first one is amortization. So we introduce an inference model, Q of z given x, which approximates true posterior P of z given x.
16:52And this enables very fast inference over the latent variables given the observed variables. We optimize ELBO, the evidence lower bound, with respect to Q and P jointly. And we use reparameterization to do this efficiently. And this results in an algorithm that is fast for inference of the latent variables, fast training, and also optimizes a proper objective, a bound on the log likelihood. All right, let's go. Reparameterization. So this was a technique that was inspired by dropouts, which was introduced just a year before, I think, or two years. So this essentially is the following. If you're training a VAE, you're sampling from your inference model the value of z from q of z given x.
17:40So this is a stochastic variable. And then you evaluate your generative model on that value of z and compute your objective, the elbow. and then you want to backpropagate essentially through the value of z to get a gradient with respect to the parameters of your inference model. But if z is a stochastic variable, there's no obvious way how to do backprop through that. And the way we solved this was to reparameterize it. So you can say for a lot of distributions, you can reparameterize it in such a way that the source of stochasticity is sort of kept out of the path of computation So Z now becomes a deterministic function of an external noise variable and the parameters of the inference model.
18:26Right. So one other thing we described in the paper was a fully Bayesian treatment. So you can also use reparameterization to actually estimate full posterior over all the parameters of the neural network in the generative model. And we did a lot of experiments with that, but those didn't end up in the paper, but we did describe the full methods in the appendix. This is apparently also used by some follow-up work. Okay, so on to some very retro, old-school videos of VAEs. So this is going to look very old-fashioned because it feels advanced so much in 10 years, but here we go. So on the lower left, you see the two-dimensional latent space, of an MNIST model.
19:13And so each point is the posterior of one data point in a validation set. The color is the class label. And this is essentially their position in the course of training. And you see that as the model trains, it sort of learns a latent space where the data points are evenly distributed over ZSpace. And you get some clustering as well, according to the classes. Another fun video we made around that time, 2014, is on color images. So this is, I think, one of the first or maybe the first color generative model that was out there. Of course, you also had RBMs, but I don't think they produced images that were that great.
19:49And I think it's important to note also that the framework is not really restricted to simple graphical models. So you can go wild in terms of what kind of directed probabilistic models you apply this to. So you can have hierarchies of latent variables. You can have conditional priors. You can have all kinds of conditionals. So not just Gaussian, you can have all kinds of distributions in there. So one simple extension is to condition everything on the class label, but you can also have a hierarchy and stuff. And we did a lot of follow-up work exploring different architectures. Right. And others as well, of course.
20:27So here we go. This is a, I think, very aesthetically pleasing video of a class conditional model trained on street view house numbers. and I think one thing that's interesting to note is that the model really learned to disentangle the class label from the style and yes, this was really one of the first works that showed that this was possible in an unsupervised way. So yeah, so one way we could apply this was to say, okay, you can input any image you want from the validation set or whatever and then infer the style of that image and then you can let the model generate new images with the same style but a different content.
21:08And obviously, this doesn't look super impressive maybe now in 2024, but like back then, this was state of the art. Yeah, there's unfortunately also a couple of challenges with training VAEs, as a lot of people who have tried them can also tell me. So one problem is, for example, is that if you just optimize the elbow, that the inference model, if you look at its objective, it's actually optimized towards the reverse scale. So the usual objective in deep learning is the forward KL, but this is the reverse KL. And this is kind of victoriously hard to optimize and can lead to bad optimization behavior.
21:46Also, if you have a hierarchical prior, and you're changing the inference model, then essentially you're changing the targets of the generative model in the prior. So there's no stable target to learn. And all these things together, they can lead to bad local optima. and in the worst case, even posterior collapse where latent space doesn't encode any information. But there has been various super interesting follow-up works that aimed to mitigate these problems. And I really encourage you to look into these works. I'm just listing a few here, but there's a lot more. Yeah, so one, I think, other important connection that we really need to make in this talk is that diffusion models, which are very popular obviously nowadays, they can be viewed as a special case of the VAE.
22:34This was already noted in the first paper by the future models by Jashjashvold-Dickstein. It's a brilliant paper. But essentially, you can view this as kind of circumventing the problem of having to learn a latent space. So in the future models, you just say, I'm not going to learn a latent space. I'm just going to define a Q and a P such that I can keep Q fixed. I have a fixed latent space, and I'm just learning my generative model. So there's no problems with forward scale or reverse scale in the inference model. And as we've all learned, this is an amazing way to learn generative models for images and audio, et cetera.
23:14So in the past few years, we have explored this connection a little further. We found that, I think one of the things we found is that a lot of the state-of-the-art models nowadays are still optimized towards the elbow. So you can sort of rewrite the objective functions that are used into the elbow plus a little bit of data augmentation in X space. So they can really be seen still as a special case of the VAE, but just with some augmentation of the training data. Cool. Another place where they show up is in latent diffusion models, such as stable diffusion. So in this case, VAEs are used to produce a lower dimensional latent space in which it's a lot more efficient to learn a generative model.
23:58So here it just projects the original data to a lower resolution and a little more channels. All right. So now I'll talk a little bit about the applications of the VAE. And of course, this is maybe the most rewarding part of writing a paper that other people start to pick up this idea and are going to apply it into their own domains. We had the good fortune that this was not only applied in the machine learning community, but also picked up in the sciences. So now I'll just describe some of these applications in a little bit more detail. But I have to say I'm going to bluff my way through this.
24:32I'm going to use words I don't really understand very much. But anyway, I'll try to do my best. Also, if you don't find your application in here, it's not on purpose. I just randomly picked a few representative ones, but there's tons and tons more, of course. So this one is VAE, which takes the discrete input space, which is a binary matrix of interactions between users and items. It maps it into a latent space that's continuous and then predicts back the interactions again. And the latent space is being used to then recommend new items to new users by proximity, basically, in the latent space.
25:13It turns out that almost by construction, the VAE is very good at compression, in particular lossy compression. So this is from a somewhat more recent paper where the VAE was used to do video compression. and I read this citation here, the quote here that says, the VAE framework is an especially good fit for the problem of lossy compression because it provides a natural mechanism for training of rate and distortion as measured by the two VAE loss terms. And now, of course, you can sort of reweight them separately and there's a lot of work afterwards like the beta VAE, which explicitly did that.
25:50This one I chose because it had a particularly astute title, Dr. VAE is Drug Response Variational Autoencoder. It's an application in healthcare by these authors where the input now is pre-treatment gene expression data gets mapped into a latent space. There is also an input or reconstruction for post-treatment gene expression. And then in the latent space, you'll observe a shift if the actual, you know, the treatment had an effect, which you can then predict again from the latent representations in this space. So here is an application in neuroscience. This is an actual time-dependent version of a VAE.
26:30So the input here are spiking neurons, a whole bunch of them. They get mapped to a continuous latent space where the factors evolve over time. These are now continuous factors that try to model the activations or the spike patterns of the neurons. And when you predict out, you predict the spike rates. And with this, you can understand better how the brain works and how inputs get represented in the brain. This one is in chemistry. So this was used to do Bayesian optimization over molecules. So you pick a molecule, you map it into latent space. That's now nice and continuous and structured. And so now you can search in the latent space for molecules with prescribed properties, which you might want to use, for instance, to develop drugs.
27:17Here is one for genetics. So here the input are multiple sequence alignment data. And the task is to try to predict from every protein which amino acid in that protein is predictive for disease, pathogenic, as they call it. And so that's a nice application. And then one in astronomy, where people try to reconstruct galaxies from gravitationally lensed images of these galaxies, because they have to pass through some black hole or around some black hole. V is being used here for that. In high energy physics, where there's a huge number of sort of events happening when these particles collide in one of these rings.
Read the full transcript
28:02and you need to find very fast the anomalous events such that you can take them out and study them better to see if there's maybe new particles in there. Okay, so those were the applications. Now a quick brief view into the future. Well, to understand the future, to predict the future, I guess you need to understand the past. So I want to go back to 2015, the first paper that really kicked off the diffusion models. And the title of that is Deep Unsupervised Learning Using Non-Equilibrium Thermodynamics. So it was clearly inspired by thermodynamics and a particular stochastic thermodynamics. And you can think of a diffusion model as basically in the forward pass where you noise something up that's following just usual second law of thermodynamics.
28:48You're just breaking something down. You're increasing the entropy. You're removing information. And you're monitoring that process. And you try to invert it. You try to undo that by learning. And you can map that very beautifully to doing work and generating heat in a thermodynamic process. I won't go into all the details here, but I think we'll see a lot of interesting future development on this intersection of these two fields. In fact, there's a huge number of connections that are emerging recently. So I just threw some random sort of papers out here of things that I read and I thought was very interesting.
29:28So there's a paper here that connects optimal control to diffusion-based generative modeling. There's a paper that connects stochastic thermodynamics to learning. This paper here is computational fluid mechanics as an optimal transport problem, a connection between diffusion models and MCMC methods, in particular annealed importance sampling, and so on and so on. So this is pointing to something deeper. I feel that at least the mathematics is all very much the same. And for instance, you take the VAE objective, which is the free energy or the elbow. So written up here in the right corner. And then you parameterize Q and P basically as a Markov chain of some kind.
30:12And with this, either you have your final distribution, something that you know you want to sample from, or you have data from it, or you have a reward function for it. But with that, you can basically understand all of these problems here on the left hand side. Variational inference and sampling methods, optimal control G flows, Schrodinger bridges and optimal transport, which is sort of zero noise limits of those, and then diffusion models and normalizing flows, which are also zero noise limits of those. All of that around the free energy. And then I'll end by giving it back to Dirk to conclude.
30:44Yeah. So, quickly to summarize, essentially, at VAEs, they provided an efficient framework for training and inference in deep-named variable models. There's numerous applications in machine learning and in the sciences. And I think one sort of interesting unsolved problem that I encourage people to look into is that I think it's in principle should be possible to train something like VAE that scales to the largest scales. And that would provide numerous benefits like fast parallel sampling. You can get rid of the tokenizer. You have more credibility of what you're trying to generate. So I think it should be possible to train large language models and image models with that.
31:28Diffusion models are not quite there yet, in my opinion, because we're not learning Z-space. It just feels suboptimal. So yeah, that's, I think, one challenge I would like to end with. Thank you.
31:43Note the comments in their talk about models being excellent compressors, which is a tautology that we'll return to shortly. Ten years after publication, the legacy of the VAE paper on generative AI was visible all over the ICLR poster sessions. We'll just cover two papers that stood out to us. First, we'll have Pablo Panayas of Stability AI presenting VersChin, an efficient architecture for large-scale text-to-image diffusion models, released this February as Stable Cascade, a three-phase VAE and diffusion model architecture. For both papers, we highly recommend pulling up our website show notes, where we link to both the papers and the posters, which you should have in front of you as visual aid.
32:29Let's dive in. In this video, we are presenting Verstian, which is an efficient architecture for large-scale text-to-image diffusion models. Previous works have mainly been focused on making diffusion models more efficient after the initial training by improving the samplers, the schedulers, or introducing techniques like distillation. This improves the inference times when using the models for generations. However, this can come at a trade-off for quality and still requires an expensive initial training beforehand. Our goal for this work was to bring efficiency to the full pipeline, starting at the training stage.
33:07This work is inspired by latent diffusion models and its observation that compressing data and training the generative model at the latent space is faster than training the model at pixel level because the data size shrinks. However, latent diffusion models use a VAE to compress data, which only gives good reconstructions at a small compression of up to 8x, meaning a 1024x1024 image gets encoded to 128x128. Our goal was to dramatically increase this to 42x. This would mean that the same image can be encoded to 24x24, while reconstructing it with minimal loss of information. For example, learning a diffusion transformer in the VAE latent space would give a sequence length of 16 ,384 while using a compression of 42x would reduce that to only 576.
34:03It is obvious that this would drastically reduce training and inference time for the generative model. In order to achieve our compression goals, we decided to split the process into three stages instead of two. This allows us to have an initial text conditional model, or stage C, that generates very small latents, and two upsampling stages, stage P, that uses diffusion to get a good reconstruction, and stage A, which is a regular VQGAN. Stage A, the VQGAN, is trained in a very standard way. We decided to perform a low level of compression to keep the quality of the reconstruction as high as possible.
34:42The latent space produced by this model provides just enough compression to save us a significant amount of compute in the following stages. Stage B is also an autoencoder, but unlike stage A, this model combines a simple and efficient encoder with a powerful diffusion decoder. The latents produced by the encoder have a much higher compression than the ones from stage A. These latents are then used to condition the diffusion decoder to obtain faithful reconstructions of the original images. Finally, stage C will perform text conditional generation. The model will be trained to generate latents like the ones produced by the encoder from stage B.
35:20Since those latents are highly compressed, training on them and the subsequent inference is extremely efficient. These latents produced by stage C will be used as a conditioning for stage B, which will in turn produce latents that can be decoded into a full image by stage A. While this process would seem more complex than a two-stage approach, offloading the work into three stages allows us to both train and inference faster and requiring less compute. We see this play out in the measurements of the inference time where we found a massive speedup compared to Stable Diffusion 2.1 and XL, which were state-of-the-art benchmarks at the time of the evaluation.
35:59Text-to-image models are commonly evaluated using the Fechette inception distance, which is, however, known to have limitations as it captures reproduction of a distribution and not so much the actual fidelity of images. We therefore additionally ran a randomized trial for a subjective evaluation in which 90 people participated. For it, we sampled randomly from the textural descriptions of the Coco and PartyPrompts dataset and presented pairs generated by both Wurstian and StableDiffusion 2.1. Across the board, we found that the Wirstein model was preferred by the majority of participants, even though it was trained on the same dataset and only used a fraction of the GPU hours of the stable diffusion.
36:38Since more subjective evaluations using a substantial subject pool would have been hard to carry out for us as academic researchers, we performed an algorithmic evaluation of image preference as proposed by the PICC-PIC paper. We used this to evaluate against more models and and we report the percentage of Wurstjen being preferred. Also in this, Wurstjen significantly outperformed stable diffusion 1.4 and 2.1, both of which were trained considerably longer, and it was only beaten by the much larger stable diffusion XL. Finally, here's some exemplary images generated by Wurstjen. We make training and inference code available on GitHub and the diffusers library.
37:15The weights are available from Hugging Face. Thanks so much for your attention. Second, we'll listen in on a poster session from Harle Scheffer of Google Research and the Google Lumiere team covering the hidden language of diffusion models, a diffusion interpretability work with some resemblance to Anthropik's recent monosemanticity paper that spawned the hilarious Golden Gate Claude, but done in the text-to-image domain and usable for any arbitrary concept. Basically, the goal of this work is to interpret the internal representations of concepts by diffusion models. So, for example, we have this concept painter, and the diffusion model generates all these wonderful, diverse images.
37:55Our goal is to understand how the model actually did that. Or, in other words, what are the features used by the model to represent that concept internally? So our overall goal in this work is twofold. One, we would want to kind of decompose the concept into its own features. And two, we would also want to decompose a single image into the features used to the generation of that specific image. because we know that Stable Diffusion can generate very diverse images for a single concept. So each image can only contain so many features from that decomposition. So what we're going to do to achieve this goal is going to be very, very intuitive and very, very simple, I promise.
38:30We're going to use the vocabulary of Stable Diffusion as the prototype set of features for that decomposition. And why do we use the Stable Diffusion vocabulary? Stable Diffusion is based on the clip vocabulary, which is very, very rich and very semantic. It has 50 ,000 tokens, including emojis. And here's a fun anecdote. Kendrick Lamar is a single token in that vocabulary. So basically, this is a very, very semantic vocabulary, a great prototype for our learned decomposition. And then what we're going to do is we're going to learn a lean MLP that you're seeing here. This MLP is going to learn to map each one of the tokens in the vocabulary to its own coefficients.
39:07So we would want to map tokens to a high coefficient if they are very influential on the generation, and a low coefficient if they don't have an influence on the generation at all. Right? That's our objective. After we learn to map each token to its own coefficient, the decomposition that you're seeing here is defined simply as a linear combination. So the decomposition is a linear combination of the entire vocabulary where each token in the vocabulary is weighted by the learned coefficient. And the way that we're training this MLP is we're going to take 100 random concept images from the concept that we want to explain.
39:42For example, if we want to explain the concept of president, we'll generate 100 random images of presidents, we'll noise them to different noising steps in the diffusion process, and then we'll train the MLP to best denoise them. Meaning this MLP is trained to give higher coefficients to features that are good to denoise those images and lower coefficients to features that will not be useful to denoise these images. Okay? And then you have this linear combination of the entire vocabulary where each token in the vocabulary gets a weight. So that's the decomposition that we're learning for the concept.
40:16Now if we want to do single image decomposition, it's going to be very, very simple. We're going to generate that specific image with a specific seed with this linear combination. And if you take a look here, you can see that the combination actually reconstructs the concept images. That's one of the most important things. That's how we evaluate the decomposition. The decomposition needs to be faithful to the concept. So you can see here that the images are reconstructed pretty accurately using that decomposition. So when you want to explain a single concept image, you can take the decomposition and generate a photo of a W star where W star is your decomposition with a specific scene.
40:52Now you can try to remove features from the decomposition, just zero them out and see if they influence the generated images or not. If the inference will generate images, then that feature is important to generate that specific image and vice versa. So what you're seeing here and here are single image compositions produced by our method for different concept instead of the fusion. And this is where I said to my co-authors, guys, we have an issue, there's a bug. When I saw just these textual correlations, I couldn't understand the meaning or the correlation between the different tokens. So for example, what's the connection between sweet peppers and fingers?
41:27Textually, they seem very remote and unrelated. But when we look at the generated images, we can actually see the connection. So the model learns to make connections between concepts that are based on visual features, semantic features, that exceed or supersede their textual meanings. So sweet peppers are generated as finger-shaped peppers. Okay? Here's another cool, fun decomposition. A camel is connected to cashmere because the texture on the nose of the camel and on the The neck of the camel is similar to the cashmere texture, and the color is also similar. A snake is decomposed into a host plus gecko.
42:03Again, connections that are based on semantic features, visual features that exceed or supersede textual correlations. Here's another cool thing that we found. We know that diffusion models tend to kind of take inspiration or overtake inspiration from existing artists. So you can see that when we generate a picture of a painter and remove Monet from it, the painting that the painter paints disappears, meaning the model uses the artistic style of Monet to generate the painting in this image. So you can kind of find points where the model steals or gets inspiration from existing artists. Here's another cool application, concept manipulation.
42:41So what you're seeing here are two concepts that have dual meanings. A crane can be either the bird or the machine. Bass or bass can be either the fish or the guitar. So you can see that in the original input images the model interpolates between the two different meanings of the concept and we can actually use the decomposition to see how each feature influenced the generated image so we can take crane and take the coefficient that corresponds to stork and reduce it or increase it to see how stork influences the output image and you can see exactly how the model interpolates between this meaning which is the machine and this meaning which is the bird to generate a machine shaped like a bird's head.
43:20Here again, a bass guitar, where the body of the bass guitar is actually a fish's body. Another thing that we can do is out of distribution concept decomposition. So say we have this plushie from the Dreambooth data set, where we want to understand how the model represents it internally. You can see again that the model makes connections that are very visual, make a lot of sense. It connects it to Elmo because of the color and the shape of the toy. and to a shrimp based on the hands and the legs of the toy, which kind of look like a shrimp. The final thing that we can do that I like the most probably is concept de-biasing.
43:57Say you have a concept like professor or nurse, where one of the features in the decomposition is a bias. Male, female or obese in the case of opera singles. We can remove or reduce the coefficient corresponding to that bias term in order to get a fair presentation. And here's one of my favorite things. Take a look at this example here. we did change the identity of the person in the image so it was a man and it turned into a woman but the other features of the concept are preserved pretty nicely so the spatial structure is the same the suit is kind of the same the man has glasses the woman has glasses there's a library in the background that desk that they're working on has notebooks with the same pencil so basically you can surgically remove features from a concept to obtain a concept that is the bias or change in I'm not very familiar with interpretability research, but yours seems a lot more approachable.
44:48I think you're a very good explainer of things. Thank you. What are the different kinds of approaches to interpretability? What school of thought in interpretability does this belong to? It's definitely more related to concept-based explanations. We should put this in context. Up until not that many years ago, we were mostly focused on interpretability and interpretability on classifiers and very nuanced things. And then generative models kind of changed everything. In that field as well. So basically when we had classifiers we were based on mostly heat maps Showing the parts in the image where the model looked to make a prediction But now when you have a generative model, it's almost useless because the model generates content from scratch So basically, I think we're going to have to develop a whole new Theory and class of works of how to explain generative models because that's a really really hard task Even defining what an explanation is for a generative model is not trivial I mean, this is just my interpretation or my suggestion of how I would like to see an interpretation.
45:46But someone else could come along and give you an entirely different explanation as to what the interpretation should look like even. So this is something that is really at its infancy right now. As we're developing generative models, I guess we're going to need to develop tools to understand them. If you're talking about language models, there's a whole class of mechanistic interpretability, which kind of tries to understand a specific neuron, what activates it, what it learns. This is more of kind of a global approach to an explanation, taking a concept and understanding how the model represents it.
46:17But another approach could be, let's take a look at a specific neuron in the network and see what activates it, see what that neuron specifically does. So there's a lot of approaches for explainability and interpretability. I think for vision, it's still at its infancy. Language and NLP are more advanced in that. I can't resist. We mentioned Lumiere in a walk. what would you like you don't have to talk about Lumiere itself or anything like that but what would you like to see in terms of interpability for video for temporal dimension control ability I think it's something that you emphasize a lot I mean I am very passionate about controllability for video models is this control control ability is that what you're talking about I mean not specifically for generation for video generation and image generation but I'm talking about controllability it's more it's more yeah prompting visual prompting the ability to give a complex input such as a segmentation map and being able to generate based on.
47:11So your ability to control where objects are located and how the image is generated. So that's what I'm talking about when I say controllability. But I do think that people often miss the connection between explainability, interpretability, understanding internal representations, and controllability. We have works dedicated specifically to that, showing that once you understand the internal representations of a model, via the attention layers, via whatever mechanism you choose to. You can actually manipulate the model by manipulating its internal representations. This is similar to the concept of devising that you're seeing here, and it's actually something that we can do.
47:46You can extract abilities from the model that we didn't have before by just understanding how the model operates and what's in its internal representation. Is that a paper that you worked on? Is there any names that people can look up? Yes, there's a Tendon site where we did exactly that. we saw that the model neglects to generate some subjects in the input prompt and what we did was we used the internal presentations the attention maps as a direct loss so what you're doing is you're kind of extracting the explanation from the internal of the model and then using that explanation as a loss function to encourage the model to do something else so once you kind of understand the internal presentations understand what the model does you can manipulate it and control it, to do things the way you want them to be done.
48:28Perfect. That's all I wanted to get some touches on. Thank you. You're great at explaining things. Thank you. Thank you. Now we're going to return to the topic of learning representations being compression, which is going to sound like a detour, but is really in the same neighborhood as auto encoders and generative models. To introduce this subtopic, we invite none other than Ilya Satskeva, the recently departed chief scientist and co-founder of OpenAI, speaking at the Simons Institute last year, who also had learning and compression on his mind. Ilya is co-author with our next guest, who received the Test of Time Runner Up Award.
49:06Listen closely. First of all, what is unsupervised learning? What is it? supervised learning is like, yeah, you've got your data that says here, do this, here, do that, and you have all this data. You do well in your training error. Your training error is low. You have more training data than degrees of freedom in your function class, parameters, but maybe other things too, degrees of freedom like bits. And you say, okay, supervised learning will succeed. But what is unsupervised learning? What can you say at all about unsupervised learning. And I'll say that at least I have not seen an exposition of unsupervised learning which I found satisfying.
49:46How to reason about it mathematically? We can reason about it intuitively, but can we reason about it mathematically? And for some context, what is the old dream of unsupervised learning? Which, by the way, this dream has been fulfilled, but it's fulfilled empirically. Can we go just a tiny bit beyond the empirical results? Like the idea that you just look at the images or you just look at the text without being told what to do with them. And somehow you still discover the true hidden structure that exists in the data. And somehow it helps you. Why? Why should it happen? Should it happen? Should we expect it to happen?
50:25You don't have anything remotely similar to the supervised learning guarantee. The supervised learning guarantee says, yeah, like, get your low training error and you're going to get your learning. It's going to be great success. unsupervised learning, it appears it appears that it's not this way you know, people were talking about it for a long time in the 80s the Bolson machine was already talking about unsupervised learning and unsupervised learning also did not work at small scale, but the old ideas were there, like the noisy autoencoder for those of you who remember it, it's like BERT or the diffusion model it's a tiny twist, the tiniest of twists the language models of all times they also generated cool samples for their time, but their unsupervised learning performance was not as impressive as those of today.
51:16But I wanna make the case that it is confusing, because it's like, why is it confusing? You optimize, like how does unsupervised learning work? You say, okay, let's optimize some kind of reconstruction error, or let's optimize some kind of denoising error, or like some kind of self-supervised learning error. you optimize one objective, right, oh yes, I just said that, but you care about a different objective. So then, doesn't it mean that you have no reason to expect that you'll get any kind of good unsupervised learning results, or rather, you do get them empirically, but like, is it going to be, the level of mystery is quite high, I claim.
51:56Like, it seems totally, like a totally inaccessible phenomenon. You optimize one objective, but you care about another objective. And yet, It helps. How can that be? Magic. I'm going to say something which is only 90 % true. Unsupervised learning doesn't, you could say, okay, so you just learned the structure in the input distribution and it helped you. But then, you know, what if you're training from the uniform distribution? Then all your unsupervised learning algorithms will fail. How should you think about that? So what can we say? Do we need to make assumptions? What kind of assumptions? So I'd like to present potentially a way of thinking about unsupervised learning, which I think is, I personally find it interesting.
52:46Perhaps you'll find it interesting too. Let's find out. So I want to show you one way of doing unsupervised learning, which is not necessarily widely known because it never became the dominant way of doing unsupervised learning. but it has the cool feature that, similarly to supervised learning, it has to work. So what kind of mysterious unsupervised learning procedure where you're not given any labels to any of your inputs is still guaranteed to work? Distribution matching. Distribution matching. So what is distribution matching? Say I've got my data. I've got X and I've got Y. Data sources. There's no correspondence between them.
53:36Just two data sources. Data source X and data source Y. Language 1, language 2. Text, speech. No correspondence between them. Let us look at this criterion. Find the function F such that the distribution of F of X is similar to the distribution of y. It is a constraint on f. And in the case of machine translation and speech recognition, for example, this constraint might be meaningful. Like you could say, yeah, if I have like long sentences, if you tell me that you have a function such that the distribution, you take your distribution of English sentences, you apply the function f to them and you get something which is very similar to the distribution of French sentences, you can say, okay, I found the true constraint about F.
54:35If the dimensionality of X and the dimensionality of Y is high enough, that's gonna give you a lot of constraints. In fact, you might be able to almost fully recover F from that information. This is an example of supervised learning, of unsupervised learning, where it is still guaranteed to work in the same sense that supervised learning is guaranteed to work. Also, substitution ciphers, like little simple encryptions, will also fit into this framework. So that's the thing. Okay. And so I independently discovered this in 2015. And I got really fascinated by it because I thought, wow, maybe there is something mathematically meaningful that we can say about unsupervised learning.
55:30And so, but let's see. The thing about this setup is it's still a little bit artificial. It's still real machine learning setups aren't like this. And the way we like to think about unsupervised learning isn't that also. Okay, now I'll present to you the meat of what I wanted to say. How a proposed way to think about unsupervised learning that lets you, that puts it on par with supervised learning. and says, okay, what is it doing mathematically? How can you be sure that your unsupervised learning is good? Compression to the rescue. Obviously, it is well known. I shouldn't say obviously. It is not obvious, but it is well known that compression is prediction.
56:22Every compressor can become a predictor, and vice versa. There is a one-to-one correspondence between all compressors and all predictors. However, I would argue that for the purpose of thinking about unsupervised learning, the language of compression offers some advantages. At least for me it did. Perhaps it will for you too. So consider the following thought experiment. This thought experiment is the most important slide. Say you have two data sets, X and Y. Two data sets, two files on your big giant hard disk. And say you have a really great compression algorithm, C, which takes data in and outputs compressed objects out.
57:19Say you compress X and Y jointly. You concatenate them. You take the two data sets and you concatenate them and you feed them to your compressor. What will happen? Well, let's see. What, and in particular, an important question is, what will a sufficiently good compressor do? My answer is, very intuitively, it will use the patterns that exist inside X to help it compress Y and vice versa. You could make the same claim about prediction, but somehow it's more intuitive when you say it about compression. I don't know why that is, but I find it to be the case. So that's our clue. And you can make an equation like this, where you say, hey, if your compression is good enough, if it's like a real great compression, compressor, it should say that the compression of your concatenation of your giant files should be no worse than the separate compression of your two files.
58:19So any additional compression that was gained by concatenation is some kind of shared structure that your compressor noticed. And the better your compressor is, the more shared structure it will extract. The gap is the shared structure or the algorithmic mutual information. That's interesting, right? You can see what I'm alluding to. Y is the data of your supervised task. X is your unsupervised task. But suddenly, you have some kind of mathematical reason for the information for the patterns in X to try to help Y. Notice also how it generalizes distribution matching. If we are in the distribution matching case where you've got your X is language one and Y is language two, and you are saying, and you know that there exists some simple function F that transforms one distribution into the other, surely your compressor, if it's good, will notice that and make use of that.
59:22And maybe even internally try to recover this function. I think that's pretty cool. We've closed the circle. So how do we formalize it then? What will be the formalization of unsupervised learning? Let's see. Let's see if I can do it. Consider an ML algorithm. So here, by the way, in what follows, I'll be a bit sloppy. and I will use compression and prediction interchangeably. Say you have a machine learning algorithm A. It's an algorithm A and it tries to compress Y. And say it has access to X. X is file number one and Y is file number two. You want your machine learning algorithm, your compressor, to compress Y and it can probe X as it sees fit.
1:00:10The goal is to compress Y as well as possible. We can ask ourselves, what is our regret of using this particular algorithm? You'll see where I'm getting at. Regret relative to what? If I do a good enough job, being low regret means that I've gotten all the help that I can possibly get from this unlabeled data. This unlabeled data has helped me as much as possible, and I don't feel bad about it. I don't feel bad. I don't feel like I've left some prediction value on the table that someone else with a better compression algorithm could have used. That's what it means. And in particular, it's like, yeah, you can go and you can sleep happily at night knowing that if there is some information in the unlabeled data that could help my task, no one else, no one could have done as good of a job as me.
1:01:04I've done the best job at benefiting from my unlabeled data. So I think that is a step towards thinking about unsupervised learning. You don't know if your unsupervised data set is actually useful. It may be super useful, it may have the answer, it may be totally useless, it may be the uniform distribution. But if you have a low regret unsupervised learning algorithm, you can say, whether it's the first case or the second case, I know I've done my best. I know I've done my best at benefiting from my unlabeled data. And no one could have done better than me. We think it's interesting that even Ilya Sutskeva also uses a Bezos-like regret minimization framework to think about self-supervised learning.
1:01:49Great minds think alike. Now we've had the best introduction in the world for the compression topic. You might understand the controversy around his collaborator and our next guest, Christian Segeti of XAI, who publicly criticized an ICLR paper from Google DeepMind titled Language Modeling is Compression as Stating the Obvious. We caught up with him on the expo floor to get his more nuanced thoughts, which we also linked to in the show notes. Basically, this was a fun exchange because I criticized his paper on Twitter, saying that it's basically stating the obvious. I mean obvious, I mean something that has been known for long.
1:02:29Actually, one of the authors is Markus Futter, who had this compression prize. And we are measuring the performance of language models in bitrate, which means it's like for 20 years now. So basically, it's very well known that compression... Modeling is compression. Compression objective. And I just wanted to figure out what is the novelty in this paper, because they tried to make some statements. So basically what I joked about is that they destroyed one of my interview questions when I do interviews at Google and XAI. What did it use to be? Yeah, it's like if you have a language model, then how do you use it as a compressor?
1:03:09I expect a candidate who works on language modeling or compression, but especially language modeling, should know this basic fact that basically you are training with a compression objective and you can use arithmetic coding to actually use it as a compressor. That's a very classical result from, let's say, 80s or something like that. So that's why I was like, okay, what is the new thing here? And I learned some interesting tidbit, and that was very interesting, that if you take a language model trained on text only and use it as a compressor for images, and it never seen any image, it still compresses pretty decently, which is a surprising fact to me.
1:03:46So I like that in the paper. I think that's the main takeaway for me. You guys recently hired Houtian to make ROC into a vision-enabled model. Is that a similar insight that you can compress vision onto the same latent space? So all these generative models, autoregressive models, they compress. They are compressors, so everybody knows that. That's a basic thing. It doesn't matter if they are images or text. But here the surprising thing in this paper was for me, is that if you train on text, it generalizes to images. That is not clear, but it's not a useful, practically useful thing. It's a very interesting observation, but it's not something that is, I can't see how it would, it doesn't have an immediate impact on things.
1:04:37Another related result that I found extremely interesting is a friend of mine working at Percy Liang and others. Stanford. Stanford, they published this paper that they completely randomized the embedding table. of a transformer after every instance and they still can predict pretty well next token so that's a very interesting insight because it's like a lot of people think that those embeddings matter but they don't really and actually the good thing is that if you okay if you don't do that aggressively you only like permute a bit or disturb the embedding table but i mean also like you only do it for very frequent tokens because this comes with a price because the first two tokens are hard to predict because since you randomly generated the embeddings, you don't know which embedding corresponds to which token.
1:05:23But then out of context, the model learns that. But yeah, in the first half of the sequence, typically you get poor results, but after that it gets very good. And it's kind of similar because it has this kind of in-context learning aspect. And then the model trained this way gets pretty good at better at in-context learning than other models. So that's the really interesting. And that's a practically useful observation in my opinion. Yeah, yeah. So that's related to this thing because it again shows that whatever your embeddings are, they are not so important. What really matters is the relationship between the embeddings.
1:05:59Got it. Perfect. I noticed that you guys are here as a sponsor as well. A lot of our listeners are grad students and engineers. They might be interested to work at XAI. What are you hiring for? What do you think are undervalued skills that you are trying to look for? I mean, we always look, we have a very small team compared to other companies. So we always hire for particular purposes where we lack talent and manpower. So currently we're hiring on diffusion and image generation and video generation kind of expertise. But we also hire a lot of infrastructure people and some product people. So we are a bit like very strong on talent on the research side, but we have much less talent on the like still is strong talent on large scale systems.
1:06:54Do you just need Kubernetes gods or what kind of large scale systems? That's a good way to formulate, but it's not just the Kubernetes itself. It's got like whole ecosystems of like various. So you can also make another buzzword like the full stack. because basically you want to have engineers that can build products that is highly distributed and can do work with databases, work with large-scale data pipelines, and high reliability authentication, etc. It's official. XAI is hiring researchers for image and video generation and in engineering across infrastructure and product. I wonder if they picked up a lot of stability AI people at ICLR.
1:07:41Anyway, we turn now to Christian and Ilya's paper that won the ICLR Test of Time Award runner-up prize, which along with Wojcik Zaremba, Joan Bruner, Dumitru Erhan, Rob Fergus, and Ian Goodfellow, started the field of adversarial machine learning, which eventually led Ian to work on generative adversarial networks. There's a through line here from compression to adversarial attacks. See if you can spot it. This paper was remarkable in that it first pointed out some essential robustness problems with deep neural networks. Specifically, it showed that neural networks can be vulnerable to small, almost imperceptible changes to the input.
1:08:24This idea led to a flowering of research on adversarial learning and also adversarial defense. And it also connected research on machine learning with other areas of computer science, which are interested in building safe and secure systems. As AI gets broadly deployed in real-world safety-critical applications, this work is more relevant than ever.
1:08:53And now Christian will give a retrospective talk. I also, so I'm kind of feeling very nostalgic because actually this was my first deep learning, machine learning paper in general. and I was very new to this domain. And it's also kind of like a very strange paper. So this is the result that I'm most proud of of my whole career and the worst paper that I have ever written. So, I mean, it's true and I don't think my co-authors would contest that. So basically the story was and I want to use this occasion to express my gratitude to my old friend Hartmut Neven, who actually should have been on the paper.
1:09:40And we wanted to write this paper, basically two of us, on the adversarial examples. And somehow we were just too lazy to write it up in 2011. And poor Hartmut couldn't get on the paper because we wrote it together. So basically Wojciech contacted me in 2013. and ask, yeah, you have this result in your drawer, please write this paper with us with some other results. And then I don't think those other results in the paper are something that I would like to present today because nobody decides this paper for those other sections. So I will only talk about adversarial examples here, which I think is a...
1:10:22I'm very proud that basically my first paper started a subfield in machine learning that is now basically when you go to any conference, you have a special track on adversarial example, robustness and adversarial examples. So saying that, so basically, I felt very ashamed when Hartmut later came to me and asked, okay, why am I not on this paper? And he is right. He should have been on this paper. And several people who had good ideas and they didn't actually even come into the paper, they are co-authored, but that's a different story too. So, but whatever. So basically, this is a very massive paper.
1:11:02I still have a few learning to share with you, especially. So one of the reasons that this paper was delayed so long was that I talked to several very prominent researchers at Google. I don't want to name names. And everybody said, yeah, this is just overfitting. This is trivial. This is already known. Don't mess with this. You are not even a machine learning researcher. And that was true that time. I mean, I was not really into this field. And that made me, okay, I tried to make the best of it. And I will tell you how they helped me to improve the results. So it was, I like criticism. But after this experience, when I talk to young people, I never tell them that something is trivial or not new or not novel or don't do this or that's boring.
1:11:57So that's the first learning I took from this experience. So let's start with after this. I also, I'm very nostalgic, so I put up a slide that I would like to thank to my good friend, Daniel Varga, who is also in the audience. And this slide is from my first prize in machine learning. That was the Inception model. and my question is, do you think that this, so basically this is a picture from the Inception presentation from 2015 and because this is a misclassified example. So do you think it's an adversarial example or not? What's your opinion? So basically, so the Inception, so this was a camel and I like that because it's basically the shape of the object was used, which was at that time not trivial.
1:12:52so I would say no because adversarial examples are more like bullets rather than meteors so if a meteor falls on your head it's not adversarial, it's just bad luck so what makes an example adversarial is that you have an intent behind it so for example I would say this image is starting to become adversarial it makes you think and I would like to share, so this is a presentation I gave to Jeff Hinton before this whole paper was written. So this is a slide from the very first presentation on this topic. And so basically the idea of adversarial examples in machine learning is very trivial is just saying, okay, how can I change this image minimally so that I end up with a misclassification?
1:13:46So basically you want to have the smallest possible X so that you add to the image and changes the output of a neural network like some classification result. So how do we find such a perturbation? How do we find a minimal perturbation? And now these are all parts of this paper and finally, so this paper is probably so poorly written that most people cite much later papers on this method. That was because the funny thing is that the gradient sign method, which is much faster than this, came out a year later. I will cite that paper later. But this work used a relatively sophisticated optimization method.
1:14:32And it finds smaller perturbations because it optimizes the perturbation explicitly. And actually, we used some relaxation of it is that we say, okay, we want to optimize instead of having a constraint on the loss, we are just optimizing this relaxed version of the objective until the label classification changes. So basically, you're iteratively trying to minimize this relaxed version of using LBFGS back then. Also, that's a very interesting historical fact. So why did I use LBFGS? So you can guess what language did I use to produce this paper. It was written in MATLAB. So that's how this thing is.
1:15:24And MATLAB had an LBFJ. That was one of the optimizers that had actually box constraints. And if you look at the formulation, the box constraints are super important. So don't ever forget, my first examples were not that good, so they were even smaller perturbations. But if you forget that you want to keep the image, the pixel intensities in the allowed range, then you need box constraints. So that's why that's super important. So the only box constraint solver in MATLAB was LBFGS back then. Also, most of the results were done in MNIST. And later, Wojciech came by and he did the image experiment on AlexNet.
1:16:12So let me just show you some first examples. So basically, this was my first paper. So I was taking Andrew Eng's excellent tutorial on this UFLDL. That was the first. That was how I learned deep learning from that tutorial. so I just took his code base and then I modified it to find adversarial examples. So also that's one of the reasons that you find autoencoder based models in this paper as well because people thought, okay, but what if you pretrained the model with autoencoder then do you still have the adversarial examples? Of course, and I tried it. So you can see that even a linear classifier, so the left hand side are adversarial examples for a linear classifier, They are all misclassified by a simple logistic regression trained model, and SVM works the same way.
1:17:05And you will see that you cannot even tell by that side what. So the difference between adversarial examples and the original examples. So if you try a deeper network, then the results are even worse. So you can even have like smaller perturbations that cause the classifier misclassified the examples. So also the other funky thing in this paper is this Cochrane. I'm not sure. Has anybody heard of Cochrane here? That's like cool. So basically Cochrane, that was a very famous result in 2011. So it was basically a patch connected vision network. And that was the biggest network that time that was ever trained.
1:17:53So it was like half a billion parameter or something like that. And it was really, really poor because it was not a COPNET, but somehow that was the only vision network that was bigger than MNIST. And then we tried to basically work with that. And it was a pain because we didn't even have GPUs. So, and then the second experiment was done on COPNET. So I had to hack into this belief, which was a terrible experience. But yeah, I did it. that so these two cars are classified. One is classified as car, the other is not. And you can see that the intensity actually is increased by 10x and still you can hardly see the difference between the two examples.
1:18:34So I went to several people at Google and everyone, yeah, that's boring and not interesting, etc. But then I gave a talk, a very small circuit talk to Jeff Hinton and Jeff was like standing around for half an hour, not saying much. and then after half an hour said that, oh, if this is all correct, what you say here, which I'm not sure, then we are in trouble. And that's because you could actually, that presentation was a lot about the adversarial aspects, that how you could exploit these models, for example, circumvent captures, et cetera. So I was giving several ways of ethics that people could use this to attack Google systems, which, of course, there was a problem.
1:19:24So that started. And then when we started to think about publishing it. And then when we saw that the same results applied to LXNet, then it was clear that this should be known. And so these are examples again. Again, the differences are amplified 10x between the two images. and you can see that they are basically indistinguishable. So today people can do much better. So if you do adversarial training, which was also presented in a follow-up paper, but obviously, actually, I was doing it myself. I just didn't put it in the paper. I just started to see whether it helps and it didn't have that much.
1:20:11So today's models are doing much better because they are trained on much larger amount of data. So that's definitely one way to alleviate it a bit, but it's not solving completely. So you can see this is the dog picture. This is the difference. So if you squint a bit, then you can see some kind of dog-like features in it, but you don't really see a real structure in this adversarial example. So the difference between the adversarial example and the original example. So there are several interesting results in that paper that I think go under the radar. So basically, that's where I come to those people who told me that, okay, this is boring and overfitting.
1:20:55So I said, okay, if it's overfitting, let's take it at face value. And then I said, okay, if it's overfitting, then what if we try completely different models and see whether adversarial examples work on one model? If you generate them on one model, do they work on other models? So, you can see that this first slide introduces a few models. These are MNIST models with one to three layers. And you can see that actually deeper networks are more susceptible to adversarial examples, but even linear classifiers are too. They just need bigger perturbation a bit. and the funny thing was that really convinced me that there was something happening here is that adversarial examples on one models were having problems also on other models so that allows backbox attacks on systems that basically you don't need to have the model you can just generate them on one few models and then you get attacks on other models so that's kind of was very important and very interesting and in a follow up paper where we addressed it, but not fully.
1:22:10We try to figure out why is that. Also, we try to say, okay, if it's overfitting, then what if we take different models on different data sets? So I split MNIST into two parts, two partitions, and then I trained completely different architecture on different partition. And still, the adversarial examples transfer to some extent. So these are very interesting results that I think still today are a lot of people are not even aware of these things, but I think they are very, the most interesting results in this paper. So that's the same. So these are the two models trained, and you can see that that is still, still translated.
1:22:50So generalization of adversarialness from one model to the other. So this is a public conversation with Dumitru, who was like in 2021, and I was just like on the memory lane back then and so I posted this cat picture which I liked so I looked at my old slides and then so that was a conversation so Dimitri asked then so what do I think would adversarial examples discovered how long would it have taken to discover them if I wouldn't have published it and and my answer was yeah probably it was almost already there so it's kind of was not, so several people were somewhat aware, but not crisply. But I think that the cross-dataset and cross-model generalization is something that I think is still a valuable part of this paper.
1:23:43So it was a good result in my opinion. So, and there is also a section on spectral analysis on this paper, like trying to explain adversarial examples. and I would say don't read that section. Think it's just bad. And actually that's one of the other learning lessons I would like to tell people who do machine learning and junior researchers. Don't listen to people who want to put stuff in your paper. I tried, I fought it very hard and still I just gave up. I'm not a person who likes to be very confident confrontational. So I was saying, okay, put it in. And instead read the follow-up paper, which has a much better analysis.
1:24:36So Ian made a very, very, so that's mostly the work of Ian. And he made an excellent analysis on both cross-dataset and cross-model generalization. And basically he refused that section there with very convincing experimental arguments. So that's why I'm so confident saying don't read that section. So let me just conclude my talk with this. Decide whether this is an adversarial example or not. It's up to you to decide. Thank you very much for your attention.
1:25:13Those were some great stories and reflections from Christian. And that also brings us to the end of section A of today's podcast. We learned about VAEs, a modern variation of diffusion, the state of interpretability research on diffusion, the equivalence of learning and compression, and adversarial networks, all of which define various elements of image-generative AI today. We especially argue that adversarial attacks are possible because neural networks overfit to clean images from their data set and learn to compress different features than humans do, which is one form of the sour lesson. Our next section, Section B, deals with some of these flaws in learning, primarily in the vision domain, but of course it has more generalisable lessons as we will show.
1:26:01In this section, we will cover some of the ICLR Outstanding Paper Awards, including...
1:26:31Strong image encoders from one long unlabeled video by Shashank Venkataramanen of Inria. Take a deep breath and let's delve in step by step. Hi everyone, my name is Timothée Larce. I'm a PhD student at Meta and Inria. And today I'm going to talk about vision transformers need registers, which is our latest work conducted with my advisors, Maxime, Julien and Pietre. Today's program is very simple. We're going to talk about vision transformers, you guessed it, which is basically an architecture for vision, which is pretty common nowadays. We're going to study them and find some weird artifacts. We're going to try to understand what's going on, formulate a hypothesis, and, considering it, develop a fix for the artifacts.
1:27:13Let's start right now with attention maps. Attention maps are a very simple concept. It's a visualization you can do with vision transformers. To get an attention map is very simple. Consider any self-attention layer, any of the layers of a vision transformers, and the input of this layer is one CLS token and a set of patch tokens, and the same set of tokens is going to be outputted afterwards. In this self-attention layer, the tokens will interact through self-attention, and you can calculate these attention scores to create the interaction going on between the different tokens. In particular, we're going to look at the attention scores given by the CLS token to the patch tokens.
1:27:54Knowing that the patch tokens correspond to a patch, which can be reshaped into the image, we can similarly reshape these attention scores into a heat map, which is simply the attention map. This tells us where is the CLS token gathering information from. Because remember that the CLS token starts from the layer one with no information about the image, and by the end must have gathered the information. And there's only the self-attention layers which enable cross-communication between tokens. So these attention maps really sum up where the information is flowing from to the CLS token. So it's a very interesting interpretability tool because it enables some kind of attribution of prediction built into the model, into the architecture of the model.
1:28:41You don't need to do any grad cam or anything. Now, that's very nice, of course. So as soon as vision transformers were published, people started looking at that. They looked at it, and yeah. It doesn't look good. It looks very bad, actually. the attention maps are very noisy are weirdly full of artifacts more specifically they often have the same shape the CRS token does not attend to almost not to all of the image but it attends very strongly to a few specific patches which are in yellow here these patches are seemingly random often in background areas such as the sky in the first image or the wall in the second one and it's very weird Adding to this weirdness, Dino, published shortly after Vision Transformers, showed that when training with self-supervised learning, Vision Transformers do not exhibit such artifacts and have smooth attention maps.
1:29:36But then two years later, Dinov2 was published and it has artifacts. So what's going on? We're going to try and understand what is going on. And for that, we need to choose a model and study, which is Dinov2. And we're going to dive into it and try to find some properties of these attention maps. The first thing we should notice very quickly is that these spiky attention maps attend strongly to tokens which are outliers in terms of norm. These tokens are very high norm compared to the rest of the token. You see in Dino, most tokens have the same norm. In Dino V2, a few tokens have an extremely high norm.
1:30:12And you can plot the histogram of the distribution of token norms, and you see that there are outliers token with a norm like 500, extremely high. and this is an interesting property because it enables very simple criterion to designate okay we're going to select the patches that have a norm higher than 200 and we're going to say these are the outliers and then we're going to try to do some tests do some analysis on what how do these tokens differ from the other tokens now the first test we can do is trying to understand where do these outliers appear and very quickly we have an intuitive sense of what's going on these are they appear in the sky in this image or in the world in the other image.
1:30:53They appear in background areas, intuitively. We quantify that by looking at the cosine similarity between the patches, the raw pixels, and their neighbors. You can average the cosine similarity of a patch with its four neighbors. And you can see that in the case of tokens, of patches that become artifacts, outlayer tokens, this cosine similarity is very close to one. The distribution of constant similarity in orange for artifact tokens has a very big spike at one. Meaning, basically, these outliers appear on patches which are very similar to their neighbors. These patches hold redundant information compared to their neighbors.
1:31:39Makes sense. When you look at this image, you get something like 20 patch tokens for the sky, and they have all the same value, which is uniform blue. it sounds wasteful. It seems like the model does not need that many tokens. And it seems like the model could discard some of dispatch's information without hurting the actual capabilities. Now, let's actually test for that. We're going to try to probe into the outlier tokens and see what is the kind of information that is contained in them. And we can probe for local information, which is the information that's supposed to be contained in them.
1:32:19There are two kinds of search information. The pixel information. Basically, at the beginning, the patch embedding transforms the pixels into the token, so this information should be there. And the position information. At the beginning, you added a position embedding, so this information should be there. We do simple linear probing, simply training your logistic operation on top of frozen tokens. And we see that, basically, the outliers have much less of this information than the normal tokens. Meaning they have kind of discarded this information that was contained in them at the beginning of the model, and at the output of the model, it's not there anymore.
1:32:56Or at least it's less there. But then if there's less of this information, the question to ask is, what is there? We say there is global information in there. When we do a similar test, but this time we do not try to predict location or pixels, but we try to predict the class of the image in terms of different classification data sets, we see that the outlier tokens hold much more global information than the normal tokens. This is very visible. I mean, on ImageNet 1K, for example, you see that there is more information. The accuracy is higher. But on some data sets, look at aircraft, the third data set.
1:33:35The difference is 79 versus 17. It's a very big difference. In the top line, we put the CLS token, which is basically the top line for this. the CS token is supposed to aggregate the global information, so that's the best we could hope for a token in this model. Now, if we put all of this together, it allows us to formulate a hypothesis. Large, sufficiently trained models learn to recognize redundant tokens and use them as places to store, process, and retrieve global information. Now, I want to emphasize, this is a hypothesis. You've seen the data points we have, the experiments we've conducted, So it seems a reasonable hypothesis.
1:34:16Reasonable enough, at least, to try and design a fix based on it. And the fix is going to be very natural. The model needed to discard some information, to free up some tokens and do something with these tokens. Then we're going to just give it new tokens. That's what we call registers. A register is basically a useless token. A token that has no information about the image at the input, like the CSS token, and at the output, it's not used for the loss, it's just discarded. It just lives on the side of the layer and interacts with the other tokens through the self-attention. And the model could not use these registers at all.
1:34:55It could just ignore them, but it can also learn to use them. Does it happen? It does. A single register fixes the attention maps entirely. When you compare the attention map of the model train with zero register, it has a lot of artifacts, whereas with one register it does not anymore. If you add more, the attention maps are also nice. You get some performance for Dyno V2 training on classification accuracy, but also on segmentation and depth estimation tasks, which are dense tasks so it makes sense that fixing the artifacts in the attention maps also fixes local understanding. Now, of course, we can ask ourselves is this fix more general than Dyno V2?
1:35:37and clearly it is. We test it on Dynovi 2, Clip and Date 3 and basically we see that both in terms of distribution, the top plot, the distribution becomes cleaner, there are no norm outliers afterwards but also visually just the attention maps are much nicer. This is the end result we get. Very clean attention maps, pretty interpretable and we're pretty satisfied with them. A small bonus that we can think of is during this whole presentation we talked about the attention map of the CLS token to the patch tokens. What about the attention maps of the registers? We added these new tokens. Let's look at what they attend to.
1:36:17And in some cases, different registers attend to different parts of the image. Here you can see one register attends to the sugar cube, one attends to the spoon, one to the coffee. It's a pretty object-centric behavior, and it's very interesting that it emerges because this was never encouraged or required during the training. there's no mechanism implying that. Slot attention had these kind of things, but it was basically enforced in the architecture. Here, interestingly, we never expected that, but sometimes it happened. I want to emphasize that sometimes, it's not always. We don't have much more on this track.
1:36:56I mean, it was just a one-off experiment, but I think it's a pretty interesting line of thought, and I hope it will bring up some different stuff later. now before I end this I want to call your attention to recommended reading basically this is a paper that came out about a month ago Massive Activations in Large Language Models not from us, it's from another team inside Meta and I believe it's a pretty good paper it builds on top of our work and it generalizes most of our observations to large language models and also proposes different interpretations and a simpler fix all in all it's a very interesting paper and if you're interested in the topic I just presented, this is a very good read.
1:37:38Thank you very much for your attention and if you have any questions, I'll be taking them now.
1:37:45We thought this Vision Transformers Need Registers paper was very well presented and argued and deserved its outstanding paper award. Hacker News seems to agree. Quoting the top comment linked in the show notes, this is a neat result. For just a 2 % increase in inference cost, you can significantly improve VIT model performance. Close to a free lunch. We think there's more room to explore in the realm of adding special purpose tokens that dramatically improve performance by giving a scratch pad for LLMs. Case in point, our next paper explores the pause token and offers a discussion on the backspace token as well at the end.
1:38:28So in this work we want to go beyond the next token prediction objective and so currently the way we do language modeling is that to predict the next token we use the previous k tokens always but sometimes for some tokens we might want to use more computation because of the difficulty of the next token so in this work we want to explore what is the what happens if we add additional delays before predicting the answer or at the inference what happens if we extend our input prompt with some delays. So the gold standard would have been that at the end of input prompt you add some hyphens or periods and that works but that's not the case sadly and that's because you need to teach the language model that how to use these additional delays, how to use additional computations which you get through additional token set inference time.
1:39:22So we initially tried to teach the model this by fine-tuning standard pre-trained model with these POS tokens that is at the end of input prompt we add some 10 POS tokens and we start taking output only after the model has seen these additional delay tokens. As you can see adding these delay tokens gives model access to more attention computations before it predicts it starts predicting the answer but sadly we observe that just adding POS tokens at inference doesn't work you need to go all the way back to the pre-training stage and install this behavior in the pre-training stage so what we do is in the input during the pre-training stage itself when you are doing the next token prediction computation we add delays at random positions in the input sequence so let's say the input sequence is the kid is playing soccer we add cost token say after the k days so earlier the playing token was predicted after is now you have additional time step before you predict the playing token and this happens at random positions in the input sequence so that like model learns how to use the delay token 10 so we just use 10 of the options and just to be clear we we clip the more the sequence back to the original length to match the flops with the baseline and we observe that instilling this pause behavior delays in the language model gives gains across reasoning reading comprehension natural understanding tasks across the benchmarks and the reason for like some high level in we show theoretically as well that by adding pause tokens help model so the reason for that is in language models the way currently the architecture is the number of parallel operations which model can do is limited by the is limited by the number of input tokens so for example consider a class of functions FM where you have N input tokens and the function is basically m2 array operations over these N tokens and note that this M can be much much large larger than N that is like you can choose any two tokens to which like you apply these two array operations and this M can be as high as Nc2.
1:41:45So in a two layer transformer if one attention module can attend to can like one time step can perform only one two array operation then the number of such operations which the model can perform will be limited by the number of input tokens. So if you add additional width to the model you can represent a much larger class of function And note that this is not just some toy setting, this corresponds to a lot of real-world tasks. Mathematical tasks obviously, but like reading comprehension for example, which are like one of the most common class of tasks. So why it corresponds to reading comprehension is that each of the initial N tokens can correspond to one sentence in your input paragraph and the last tokens can correspond to the choice.
1:42:33So the model then like takes every sentence compares it with a choice and tries to get the correct answer So having additional tokens can allow the model to focus to much smaller sentences and compare to the choices to get the correct answer What are these tokens attending to like are there specifically attending to some sub patterns? We didn't, yeah, so we tried to do this that like what is the nearest, like we learn this embedding right for the pause token and what are the embedding words which are nearest to this pause tokens but we didn't observe any specific observation. One initial thought was that maybe this corresponds to the English words like delaying or pausing or think more but that didn't turn out to be the case so it's not that simple.
1:43:26It's probably more the actual motivation that how much the attention is and not like what the text is. And let's say in the idle world that let's say you end up learning the embedding which is close to the English word think more. Then like this whole thing should have worked with like simply adding to the input prompt that think more after like you know. You could add just some hyphens or periods to the input prompt and that should have worked. But that doesn't work. And actually, a lot of people have explored that. What if you simply add additional tokens at inference to the language? You said that there's connections to chain of thought is an open question.
1:44:03Yeah. But you're already talking about it. Yeah. The connection to the chain of thought is that what was our initial motivation is to understand what is the role of the additional intermediate reasoning tokens which you get in chain of thought, right? And one thing is that in chain of thought, the additional, the effective depth of the model is higher because of the intermediate tokens and those are generated autoregressively so the effective depth is much higher but we wanted to understand what is the role of additional input width and that is this work about but it is still open question that like how you can then further improve chain of thought or do the actual tokens which you decode really matter or not i'm sure you're familiar with the backspace token yeah work as well how do you compare between the two approaches?
1:44:52So the backspace is more like scratch pad and backspace. It's more like easy fixes for the chain of thought. They are not about like additional input computations. The other one I thought was kind of interesting was adaptive number. Yeah so adaptive pause token that is. Is it just based on a problem difficulty? Yeah so instead of having pause tokens at the end of input sequence you could always have them on the fly. Let us say in this work Currently we always added say M number of pause tokens at the end of input sequence and then we let the model decode the way it does. But what you could do is you could add pause tokens on the fly say whenever your prediction confidence is below a threshold or whenever after every 10 steps.
1:45:37Or another direction to explore is what is the optimal number of pause tokens model itself tells it or model itself keeps on decoding pause tokens. you know it feels that the next token the main next token has a confidence above a threshold so you would need to modify the pre-training accordingly just to be clear so in this work we ignore we do not teach the model to predict cause token whenever cause token is inserted we ignore the output of the previous cell because we do not want to let the model digress from its main objective yeah so for the on the fly thing or like letting the model predict itself how many post tokens you need you will need to carefully work around the pre-training and that's like some pressing interesting directions and like many people have been following up as well with like multiple token predictions that is like instead of just predicting the next token the next four Predict multi next four, exactly.
1:46:38And that's the same, right? Like now, if you're predicting next four tokens, before the actual fourth token, you are predicting it four times. So it gets upfade in the loss by like four number of times. And more number of tokens will be like taking the weight of predicting that hard token. So yeah, these are some interesting directs. Awesome. Well, thank you very much. Some of the most challenging work presented at ICLR involved deep theoretical and algorithms work, which are historically above our pay grade. However, we perceived a lot of interest in data-efficient self-supervised learning, which reduces to weak supervision.
1:47:17This next paper gets an ICLR outstanding paper mention because of its very extensive work ranging from theoretical statistical foundation to empirical support on both synthetic and real data involving a continuous driving vision learning problem. This 10-minute talk doesn't do it justice, but we'll just listen in for a nice segue into the next and last paper in today's vision section. Hi, everyone. I'm Pulket. I'm a research engineer at Granica, and I'm happy to be presenting to you today on our work on Towards a Statistical Theory of Data Selection under Weak Supervision. And this is joint work with German and Andrea.
1:47:55So it's no surprise to the audience here that modern AI is hungry for data, and the bigger models you have, the more data they consume. However, bigger data comes up with its own issues. For example, as your data set sizes increases, your training labeling and storage costs increase, your training time increase, and not only that, it's harder to control the data quality. However, if you think about it, not each data point contributes equally to the task at hand. So here, what I am showing on the left is a GIF of images collected from an autonomous vehicle data set And let's say you are trying to train a model to detect CAR for this case.
1:48:33As you might imagine, in this particular setting, there are lots of images which you are collecting of the surrounding which are repetitive and provide really low value. On the other hand, there are other images which are probably providing much more value to the task at hand. And this phenomena is not new. It has been observed empirically in a lot of past research works under different complicated settings. In our work, we try to demystify some of these findings and show that this observation is true even in simpler settings. So let's get started. Let me try and train a logistic regression model for the same task which I showed you of detecting CAR over these images.
1:49:10So what I'm showing you here is misclassification rate versus percentage of data subsample. Let's try to understand this plot really clearly because I'll be showing you this plot again and again. So on the x-axis here is I have percentage of data subsample. So as you move towards the left, you are basically keeping fewer and fewer training samples. On the y-axis, I have the misclassification rate. So as you go up, you have higher test error. And so the ideal sweet spot here is to be on the bottom left. So the curves which you see below are actually performing better than the curves which will be shown above.
1:49:46The black curve here shows the performance when you randomly subsample your data into the training. And the green line here shows the full sample error, so when you train on the full data set. So first surprising result is that if instead of doing random sampling, you do quote unquote some sort of smart sampling, you can significantly beat the randomly created data set. So if you smartly curate your data subset, you can do much better than just randomly creating your subset. Not only that, this plot is really surprising because what it shows is that at least in this particular setting, you can get full performance even after throwing away 65 % of the data set.
1:50:25And not only that, you can actually beat the full sample error by keeping just 60 % of the data set. So these results are really surprising, and we try to understand these better. So let me introduce you to the setup in our paper, which we work with. So we have some unlabeled data set, which we start with, and we assume a data scoring network, which basically assigns a sort of important score per data point. So the colors here sort of indicate the importance. The darker the color, they are more important. You use this code to rank the data and create a data subset. Note that all of this is done using unlabeled data set, though you assume some data scoring network presence.
1:51:03At this point, you go and acquire labels, and you actually train a model. So there are some salient features of this setup which I want you guys to take away, if nothing else. First, it's a two-step procedure. So you first do selection, and then that's followed by training. Next, as the talk title says, we have weekly supervised setup. What this means is that we start with unlabeled data, but we assume the presence of this data scoring network. Or in other words, you can also think of this as a surrogate model. What I would like you to imagine by surrogate model in today's world is maybe you can think of it as a foundational model or a pre-trained model on another data set trained for your same task, or maybe a model which is trained on your own data, but on far fewer samples than your whole data set.
1:51:45So the reason this exists is that it gives us some information about the labels, better than just random guessing. Next, we study score-based sub-selection schemes. So we are assigning a score per data point. And one way to think about what these scores might mean is maybe under classification setting, you can think of these point scores as to be easy examples or hard examples. And finally, though, through this diagram, it might seem that we always keep the top scores. we actually have a probabilistic scheme, so you might want to sample based on these scores or keep the top ones. Okay. More formally, we basically study the standard weighted empirical risk minimization.
1:52:25That's our setup, so this is the standard setting. The only place where the subselection shows up is this term S of Xi. And this is formally how a subselection scheme is defined. It's defined by a tuple, pi i and wi, where you can think of pi i's as the probabilities of selecting that point and keeping it in the subset. And then once it's in the subset, you might want to put away W while training it during empirical risk minimization. So this tuple completely defines whatever subselection scheme you might want to work with. And this tuple can basically depend on your features. It can depend on the surrogate model, and it can also depend on some additional independent randomness.
1:53:05So this can be a probabilistic scheme. So in our paper, we formally study the setup under various different settings. So some of the key ones are we study it under bias versus unbiased sampling. So in unbiased case, you have an unbiased loss function post-subsampling. So your weights would be inversely proportional to the selection probability. And these unbiased selection schemes for people in the audience who are aware would cover and generalize schemes like influence function-based subsampling or leverage scores-based subsampling. We also study both high and low-dimensional asymptotic. So in high-dimensional asymptotics, in particular, we study like proportional, high-dimensional asymptotics, and we have exact theorems.
1:53:43And finally, since surrogate model is an integral part, we also try to study both imperfect and perfect surrogate models, where perfect surrogate models basically means you know the true data distribution. So like I said, we have a lot of results in the paper, but for the purpose of this talk, I'm going to show a very simple setting. So we are going to be working under a binary logistic regression. We are going to show results with binary logistic regression, and a subselection scheme is a parametric scheme which looks like this. Let me demystify this for you. So PSU here is basically probability under a surrogate model.
1:54:17So you have a surrogate model which can give you the probabilities of whether it's a zero or one based on its information, its knowledge about the world. Then the term here, which you see this P times one minus P, it can be interpreted as a hardness score. So on the bottom, there's a plot of this function P one minus P against P and if your p is near 0 or 1, this term is near 0. So basically you are very confident. Your surrogate model is very confident that this data point is either 0 or 1 and those can be thought of as easy examples intuitively. Similarly, when the value of this function is high, like your p is near 0.5, you are really confused.
1:54:54So it's like hard example in a sense. Finally, we have this parameter alpha which can be thought of as an hardness exponent and what it does is like if this alpha is greater than 0, you would up-sample hard examples into your training subset, versus if it's negative, you will up-sample easy examples. It's zero, it's random. So we take this sub-selection scheme, and we try it on two different data sets. So we have synthetic data sets, where we have isotropic Gaussian covariates, and then we assume that the original label is generated as a linear function of your features. Note that this can be well or misspecified.
1:55:30What I mean by that is, like, If the actual true labels are generated using logistic function, that's a well-specified model. You are training it under logistic loss, but it can be any other linear function of your original features. And similarly, we also have results on this real data, which I showed you before in the beginning. So first of all, what I want to highlight is that we have theory for synthetic data, which predicts exact high-dimensional asymptotic error. So a lot of plots don't get jaded. So all of these nine subplots, like I'm showing the same misclassification rate against percentage of data subsample under various different settings of generated synthetic data.
1:56:07Different colors are different values of our hardness exponent, upsampling easy or hard. What I really want you to focus on here is that the dots are basically the results of empirical experiments or simulations versus solid lines, which you see are not really interpolations of those dots. Those are the predictions from the theory. And as you can see across various these different settings, we were able to exactly predict the high dimensional, the test errors, right? And surprisingly, even this simple setup demonstrates like many interesting phenomena. So next, I'm going to basically give you the main takeaways for using a mixture of experiments on real data and synthetic data.
1:56:44So let's get going. So I guess our first main takeaway is that the unbiased subsampling can be suboptimal. So here in the plot, what I'm showing here is in red, we have unbiased subsampling, whereas in blue, we have biased subsampling. And as you can see, the blue curve is below, and it can be actually quite significantly below the red one. In fact, in our paper, we have many different theorems and specific constructions showing that unbiased subsampling can actually be arbitrary worse. And as a reminder, unbiased subsampling generalizes a lot of popular techniques, for example, influence function-based subsampling, leverage score-based subsampling.
1:57:22on. Not only that, like, so this is, these are some plots on real data. So what I'm showing here is the different parameters. All these different subplots are generated under various different settings of regularizations, SNR, so on. But again, don't worry about all the details. All I want you to focus here is that the blue curve is forming the lower, is the lowest one in all these different settings, right? And so here, again, as a reminder, blue curves, alpha is negative. You are up-sampling easy examples in your subset. And so in high dimensional settings, actually choosing easy examples is better.
1:57:55And again, this is very surprising, but it has also been seen previously in previous works under specific settings. However, we show that this is much more general. Next, even more surprising, you would come to me and say, hey, better surrogate models should always lead to better subselection because they would encode more information about the labels. Interestingly, we found that's not always true. In fact, better surrogate models do not always mean better selection. So here, what I'm showing in different curves, the different colors is basically when I generate subselection schemes with different values of different strengths of my surrogate model.
1:58:33And you can see the darker the color, the stronger the surrogate model. What you can see is the lighter color is, again, at the bottom. So at least in this particular setting, using weak supervision, A weak supervised model performs much better than the strong one. And this is encouraging because it says that, oh, you can do something under weak supervision and you don't need to actually keep using all the labels. And in fact, using stronger models can hurt under certain settings. So this was very surprising. And finally, what I want you to, what we see is that you can, subsampling can actually beat full sample training.
1:59:10And this is not only true for complex model. models, your advanced clip-like task. This is true for a simple binary logistic regression kind of setup. Here I'm showing you results on synthetic data. And what you can see in this particular case is you just keep 40 % of the data and you can improve on the misclassification error. And the main intuition here, so we observe this across many different settings. I just cherry-picked one. But we basically observe it when the models are misspecified. And the intuition there really is that when the models are misspecified, not each data point is adding equal value or equal information for your training objective since your losses and models are mismatched.
1:59:49So to conclude, we had some surprises during our work, such as popular techniques using unbiased sampling can be suboptimal or use of weaker surrogates can beat. However, the main punchline, I would say the main insight from our work corroborates the previous research, which is uncertainty-based subsampling can be effective, though story is interesting. Choosing hardest can be catastrophic and depending on settings, you might want to upsample easy or hard. And I hope this whetted your appetite. If you want to learn more, I'll be at the poster session. Thank you.
2:00:26Our last vision paper gets another ICLR outstanding paper mention for learning strong image encoders from one long unlabeled video. It does two things. Introduce a walking tours data set and introduces DORA, a new image self-supervision method demonstrated on that data set that outperforms DNO when trained on just one video and leading to emergent tracking of objects through a video, even through occlusions. Hello everyone, I'm Shashank and I'm happy to present our work entitled, Is ImageNet Worth One Video? Learning Strong Image Encoders from One Long Unlabeled Video. This is a joint work with my colleagues, Mamshad Rezvi, Joao, Yuki, and Yanis.
2:01:11Self-supervised learning has allowed pre-training of neural networks to scale beyond the size of labeled data sets. By adapting to evolving data without human intervention, SSL avoids the time and expense of continuously relabeling large data sets. Since SSL methods learn directly from the data, it overcomes the limitation and potential biases associated with manual annotations by human experts. A major limitation of current SSL systems is that they are typically trained in a highly controlled setting of using ImageNet without labels. Additionally, many SSL methods rely on carefully designed detaugmentation techniques, such as image transformations, to create the supervisory signal for the model.
2:02:00Finally, extending these approaches to a more complex real-world scenario with rich contextual information and diverse data modalities also remains a significant challenge. The rise of video data presents an exciting new frontier for self-supervised learning. Videos inherently contain a wealth of temporal and multimodal information such as visual, audio, and motion cues which can be leveraged to learn powerful representations without the need for extensive manual labeling. Moreover, a large number of videos are available at a massive scale on platforms like Instagram, YouTube, and others providing an abundance of diverse and unconstrained data for self-supervised pre-training.
2:02:48We venture in this direction and introduce a new dataset of open source, ecocentric videos called walking tours. We then introduce a new self-supervised image pre-training method aimed at learning from videos where we learn to detect and track objects over time in an end-to-end manner using the Transformers cross-attention. The Walking Tour dataset consists of 10 egocentric videos captured from different cities in Asia and Europe. These videos are dense in semantic categories, much more so than in movies. They have 4K resolution, contain few or no shortcuts, are hours long, typically between 1 to 3 hours, and are under the CC BY license.
2:03:36We now introduce our framework called DORA. Here, we repurpose the MSA block in BIT to perform multi-object tracking without using any of the shelf, object detectors, or optical flow networks. From an input frame, the output of the second-last layer of the teacher model is used by a multi-object tracker to generate multi-object masks. We use those masks to feed to the student model and apply a distillation loss between the CLS token embeddings of the teacher and the student network. In the multi-object tracker, we first obtain the query, key, and output embeddings at the last MSA block of the vision transformer.
2:04:20From the multi-head attention maps, we draw a subset of k-heads and form object prototypes by pooling over patch queries. We refine these object prototypes to discover distinct objects using the Synchron knob to improve correspondence between object prototypes and patch embeddings. Finally, we then track the objects over frames by cross-attention between patch key embeddings. We observe that DORA leads to emergent attention maps from the CLS token of distinct heads in a VIT. Here, we use red, green and blue masks to detect and track objects. The mixed colors in yellow and cyan indicate the spatial overlap of two objects in a single head.
2:05:08The track objects are now incentivized to be diverse by introducing the synchronous clustering of patch embeddings where we observe three well separated objects. Here is another such example. In just one video with 200 ,000 frames, Dora outperforms Dyno pre-trained on ImageNet 1K on object discovery, semantic segmentation. It is also on par on object detection, video object segmentation, and multi-object tracking. We account for the large distribution shift between pre-training and downstream datasets by fine-tuning on different image-based datasets. While Dora, pre-trained on one walking tour video, is on par with Dyno, pre-trained on ImageNet 1K, pre-training Dora on all 10 walking tour videos outperforms Dyno.
2:05:59Thank you for your attention. You can find our paper, dataset, and code using the QR codes here. That was the end of Section B of our podcast, which covered adding special register or pause tokens for improved performance and a survey of state-of-the-art week and self-supervision thinking. We turn now from Doras to Laura's. Can you say, attention? My bien. Section C features the best of a wealth of papers exploring different methods for improving the performance of transformers across long context extension, memory consumption, and reducing communication overhead on massive GPU clusters. Let's dive in.
2:06:43Today, I'm going to share our work, Long Laura, Efficient Fun-Tuning of Long-Context Large Language Models. The authors are from the Chinese University of Hong Kong, MIT, and NVIDIA. So first, I will give you an overview introduction about our work. Long-context ability is very important for large language models. With long-context ability, the large language models can understand books with tens of thousands tokens. But the challenge here is very clear. FANTWINING large language models to be long-context is very expensive. So LONG-LORA is our solution on efficient long-context FANTWINING methods.
2:07:22The key idea here is bused tension and low-run adaptation. It saves notable GPU memory without sacrificing accuracy. But in addition, we also introduced a data site. It names LONG-OPACA, the first LONG instruction folding data site in this area. So let's go into detail about LONG-LORA. our methods contain two key innovations. The first one is shifted sparse attention. We split the contacts into several groups and conduct attention in each group individually. And in the half amount of the attention head, we shift the position of the tokens by half groups. It ensures the information flow between the neighboring groups.
2:08:05The second one is the enhanced LoRa. In addition to the LoRa weight, we further make the embedding and normalization to be trainable. Let's go into the detail about these two innovations. So the implementation of the shift sparse attention is quite simple, but it involves only three steps. The first, we split the features into two trunks along the head dimension. And the second, the tokens in the first trunk are shifted by the half of the group size. And the third, we split the tokens into groups and reshape it into batch dimensions. So the implementation is very simple and here there might be some potential information leaking and it can be prevented from the attention mask.
2:08:53So this implementation is very easy and compatible with Fletcher Attention 2. And we have conducted detail and ablations and compression to other efficient attentions including dilated attention, block-spot attention, and stress-spot attention. Our goal is to fine-train pre-trained large-language models to be long-context. However, these attention patterns are developed for training from scratch transformers. They have some gaps to the full attention, so that's why. But here, during the training, the pre-trained model, we use the full attention, and that is for the pre-training. so that's why our shift-spot attention performance better than these other choices for the long-contact fine-tuning.
2:09:40And it not only enables efficient fine-tuning, but also supports full attention testing. Our second key insight is enhanced LoRa. In addition to the long LoRa weights, long LoRa also makes the embedding and normalization layers to be trainable. We empirically showed that this extension is very important for the context extension. It only introduced a minimum number of additional trainable parameters, but it can close the performance gap between LoRa and full fine tuning. We have conducted a perplexity evaluation on proof pair and PG-19. We examined the effectiveness of weather using the shifty sparse tension and improved LoRa.
2:10:25we showed that our method achieves comparable performance to full attention and full fine-tuning baselines with better efficiency. Long-Lara is able to fine-tune a 7 billion parameter model to 100 ,000 contacts or a 70 billion model to 32 contacts on a single 8 GPU A100 machine. We further extended our fine-tuning to longer contacts, and we progressively fine-tuned a LAMA 3 model to 1 million contacts with shift-based sparse tension and also get very good ratio performance in the needle-in -head-stick experiment. And we also evaluated our methods on long-context benchmarks, including the Lung Bench and the Lung Evo.
2:11:11We compared our model with GPT-3.5 Turbo and other LAMA 2-based long-context models. like Okuna and the long chat models. It shows that our model present comparable or even better performance than these 7 billion long context models. And we only use about 4 hour and 0.3 billion tokens for the supervised fan training. And the key insight here is the large batch and the long approach in addition to the long LARA. Okay. And in addition to these measures, we also present a solution, a data size solution, for the supervised fine training with our self-collected long instruction following data size, it's named the long alpaca.
2:11:54Because self-supervised training is very important for improving the chatability of large language models, we design several different kinds of questions, including the book question, short question, summarization, paper review, and other questions. There are about, in total, 12 ,000 questions and answers in our data site. We collected long instruction data from PDF books and other blogs that are available and licensed online. We used OSR model to get clean text data. And this process requires many handicrafts with dirty works to find out the high-quality long questions and answers. So here are some examples of using our methods and our data.
2:12:38So we named this model Long Opaca. And if we give our model a very long paper and a review guideline, we can ask the model some suggestions on how to make the paper have more chance to be accepted. And it will give some suggestions about the contribution about this paper's novelty and how to design experiments and some other applications and future directions. The second example here is also about the paper. We gave our model two papers and one paper from CVPR and another one from the SCRR. It can summarize the difference between them in structure and in technical depth and theory and experiments and some languages, styles.
2:13:25So this is the second example. And we can also give our model an economy outlook like this one, which is also very long with tens of thousands of tokens. We can ask the model to predict the economy in the future. They will give us some high-level suggestions on the economy growth and inflation and some other factors. So, in addition, our long alpaca can also read very long fictions on the books. For example, the famous book, The Three-Body Problem, asks the question that why did Ye Wenjie contact aliens and why did she feel regretful in the end? Our model can also give accurate answers with detailed explanation, like what the UNJ is thinking and his history and some of his future thinking, like this one.
2:14:19And here is a compression. If we only provide the book title but not the content of this book to the model, the answer will be much less informative and somehow irrelevant to the question. because maybe someone may think this paper or this book has been pre-trained in the large-language model. So this is a compression. So if we give the model more content about the detail about the book, the answer will be more concrete and more detailed. So this is a compression. We have released all our code models and the data, and they are available on GitHub and HackingFace. So we'll come to discuss online.
2:14:59so I think this is a good release. Okay, that's all about my presentation. Just to make sure you don't miss the punchline using shifted sparse attention, Long Laura extends Lama 27B from 4K context to 100K or Lama 270B to 32K context on a single 8XA 100 machine with almost perfect needle in a haystack benchmarks. Long Laura extends models context while retaining their original architectures and is compatible with most existing techniques like Flash Attention 2. We can compare this directly with our next paper, YARN, Efficient Context Window Extension of Large Language Models with Bowen Peng, Chief Scientist of NUS Research.
2:15:47So yeah, hi everyone, I'm Bowen, I'm the Chief Scientist at NUS Research. So we've done Long Context Extension with YARN, which is a new method, six months old method now, but it still was new at the time. And basically, why I started working on this is because there was some random guy on Reddit posted about positional interpolation. So PI was the basic idea for interpolating rope, which was the first method that actually worked for extending the context size of any language models. So before this PI method, there was no way of extending the context efficiently. You have to re-pretrain the model entirely with like 500B tokens.
2:16:30And after this method... Without any fine-tuning. This method worked without any fine-tuning, right? No, no, it needed fine-tuning. Small fine-tuning. Small, small. That's the benefit. Yes, yes. So you needed a tiny bit of fine-tuning, which is like 1 % of the pre-training dataset, which is much, much, much better, right? Because the longer the context, the slower the training is. So you want it to be efficient. So after this guy published PI, which was a guy called K.O. Can Dem on Reddit, there was also meta, like just the next day they published their paper because they were like, yeah, we need to put it out, right?
2:17:09And I was thinking like this PI is wrong. There's something wrong with it because you are interpolating all the dimensions, which is not ideal because there are some dimensions that don't need to be interpolated, basically, because those dimensions rotate a lot. So basically in rope, all the dimensions rotate at different speeds. And some dimensions rotate really, really fast. And you don't need to interpolate. So you need to extend it, but not necessarily to change what is working okay. Yes. In the first place. So there are some dimensions you want to extend and some you don't want to touch. Those rotating fast dimensions, they attend to local tokens.
2:17:46So when you stretch them, you're forcing them to attend to longer contexts, which is not what they are used to. And some of the dimensions, which we call by lambda, like the wavelength of the dimensions, they are really, really long. The wavelength is really long, so they are used to attending to really, really long contexts. So those are the dimensions where you stretch, you interpolate, and the short dimensions, which with short lambdas, you don't touch them. So that would give you this line, like this red line, where it goes to this blue line. So there's PI and NDK by parts. So we reduce the losses by quite a bit and also like after training the perplexity decreases by a lot, right?
2:18:28Also pass key like this is like 50 % and goes up to like much higher. There's some degradation at the end. I'll explain like after but you can see that PI was not great and this is much better. And then we just played around with all the parameters with yarn. Here you make sure that you compare apples to apples. Yes. Perplexity if you do it for a long time. It's different. Exactly. So we made sure to make every model as good as possible. So we made sure to keep all the models at the same context length. We made sure to train them the same amount. So we're not biasing anything. So we made sure that this is the lowest possible for all the methods.
2:19:12And then we used Yarn, which is we played around with the temperature and we found this was really important for long contexts, especially at like 128K. This is really, really important. Like at 32K is less, but you can still see that it goes down. And here it pushes the passkey retrieval to like 100K. And then like it pushes a really high, this passkey accuracy. So basically with yarn we can do a really efficient like 400 training steps extension of the models. This is like one how it's like shifting to today how it stands against other methods. Okay so the most promising rope rotary and position by bending method on right now is long rope which is a paper by Microsoft I think.
2:20:02that paper actually took our idea of yarn which is this NTK by part and yarn and they try to find the parameters like using machine learning so instead of us hand tuning T and this optimize it yes using machine learning and they found that it performs even better than yarn right because that has basically it sophisticated hyper parameter tuning exactly that's exactly do you actually need a fine-tuning data set for this or just any data set will do? Like anything that looks like a common crawl? Yeah, anything. Anything that's actually longer context-ish. Like you don't want, for example, this is 32K.
2:20:41You want to at least train with maybe 15 or 20K. You want too short of context training here. You still want some long context. And how this method of making a model with short context to a model with long context compare, for instance for with Google models that train for all the time with long context? So what I think my idea about it is like the more you train the better model is so you cannot beat compute by just using methods at the end it's a data right? Those models... They just have more resources. They have more resources we only like if they had used yarn from the beginning it would be even better probably the model right but they didn't use this they probably use like Alibi I don't know Don't quote me on that.
2:21:27But the other... My impression is Alibi is more lossy, so it will do worse on Haski. Yeah, maybe. It's like people have not yet done a full ablation on Alibi because there's no big models for Alibi. There's like Bloom, which is bad because it's so old. There's no like 7B llama of Alibi. It would be great if Meta can release a llama rope Alibi at the same time. Like one with rope, one with Alibi. So we can't do... But why can't you do it? That seems like something that you can do. No, no. Pre-trained the LAMA 7D, we cannot. It must be pre-trained. So to compare Rope with Alibi, we will need to have the same data pre-trained for LAMA, the same architecture, but just swap this to and then see the results.
2:22:13This still not give you ring attention, like 1 million context window. No, no, no. Ring attention is efficiency. Yeah, that's like compute efficiency, right? Okay. Yeah, yeah. Ring attention allows you to... I was confused by that as well. It's actually just the compute efficiency. Yeah. And so by that alone, you can extend as much as you want with short training. Yeah, yeah, yeah. But then it becomes so not efficient compute-wise, so you need something to treat it. So you need the ring attention to treat that. Because otherwise without ring attention you cannot train a 7B at 120k. It takes too much memory.
2:22:55You need multi-node which is hard to get. So with ring attention you can train a 7B on a single A100 node. So regarding that, there is not limitation on the context length that is given. No, no. I think with further explorations on rope and alibi this problem will be gone. Like this will be a problem of the past. Like actually this rotary position interpolation thing, it's going to be something solved. Because this past key, after you train even more, this is 100%. It's only a data problem then. Like at the end, you will need good data for multi-hop reasoning, for multi-turn conversations. That needs data.
2:23:35Like the model cannot just magically learn those abilities. That's those abilities. need a lot of data because it's not the essence of like learning text and just know to need to something to encourages to extend it you will need quality varied data so that that's the most hard part right now like you have good a small like maybe 20 billion really long context like with a lot of variety right like some really good data that will that will solve it and like it's not solved entirely, attention, stuff like that. There you need some architectural changes, right? So are you talking about infinite context?
2:24:19Infinite attention, yeah. Yeah, infinite context is kind of like a misnomer right now, because it's not context, it's just infinite, infinite. You encode it and you can read it. So you still forget stuff, but you are remembering the important things in the infinite context in quotes. Hopefully. Hopefully. And the problem with that is that there are some tasks that are computationally not possible to do. So this raises another question that you can have long context that you can attend to, but it does not necessarily mean that you are effective or use it properly. Yes, exactly. For instance, I did a work on certification with a lot of examples, many classes, and then you see that the aggregation that it's not utilized as well, because you have so many classes that you need all the 4k context so yeah that continue to increase and sometimes even it's decreased when you yeah yeah so this is something that is still like something that needs to be improved right it is it is there's a lot of dimensions in this we focus on a single dimension of like rotary embeddings there's like data there's also all the kind of reasoning, the model capabilities.
2:25:32Attention is not the end of everything, right? Because there's some tasks that attention cannot solve. So you will need maybe some stack. Maybe augment the model with a memory or a stack. Because if you want recursive reasoning, like actually recursive stuff, you need a stack. Or you need a bigger model. Yeah, but a bigger model only pushes this problem into the future. And it becomes a rag for your context. Yeah, something like that. I don't know. I would not know what it would look like, but something like that. Turing complete, right? Like something Turing complete. That would be really close.
2:26:06So I have a couple of bigger questions, if you don't mind. Do you think context extension is solved? I think it's not yet solved, but it's close to it. When you have like Claude, which is 128k, there's like GBD 128k, 200k. At some point, when you have 1 billion context length, I don't think you would. Don't quote me on this, but after 1 billion, it's kind of becoming a problem of what you want to feed to the model. 1 billion is really, really big. There's no such thing as one person cannot generate 1 billion in like, yeah, like something like that. But it will have its own use cases, like 1 billion, 10 billion, 1 trillion tokens.
2:26:48But I don't think like most use cases. Yeah, video. Video, DNA. You have all kinds of like autoregressive problems. inside of a model? Oh yeah, you could feed the parameters in the ICL. Because 1 billion is basically a data set. Yeah, you could do ICL on the weights of the LLM. Yeah, but that's crazy. And then the follow-up question is just on news itself. News is obviously super interesting as a startup. You are chief scientist. What kind of research are you funding apart from this stuff? Oh, so we're doing all kinds of research. So anything related to large language models or diffusion models, we're trying to like push this.
2:27:26We're trying to accelerate AI. It's too broad. Yeah, it's really broad. But when there's a good idea, people come to us and we can maybe work something out. Because when I joined NOOSE, it was actually just, I had this crazy idea. Okay. Let's try it, right? So apart from context extension, what else is NOOSE interested in, you know, just currently? Yeah, yeah. So it's basically LLM. So like agenting AIs, we also have people who are working on making things reasoned, ragged. I'm sorry? Synthetic data is the one? Yes, yes. Technium is really, really big on synthetic data. And he's pushing like, what?
2:28:01Where is Technium? He could not come here today. He comes to San Francisco a lot. I hang out with him every now and then. But he's really busy, unfortunately. I would love for him to come here. But I mean, a lot of their synthetic data is like, correct me if I'm wrong, it's like getting gpc4 to create textbooks right yeah yeah but that's just gpc4 distillation it's not yeah like it's not a science yeah yeah but I'm just I'm thinking for is there something else that I should be looking at for synthetic data that is promising yeah synthetic data it's a lot of a lot of knowledge that can come from the model and it's not only to use the more the data that the model generate.
2:28:42You need to decide which one to use, how to filter it, which kind of question do you want. For instance, the paper from Microsoft, I forgot the name. They have three additions, like textbook is all you need. So, how to build it that the model will gain more information and knowledge from the big model. And also, you can think about is learning from human data. You also use a lot of different humans and a lot of different processes to generate the data and then learn from it. So essentially learning synthetic data has become very important and can also improve the model itself because as we can learn as humans and improve by getting feedback from other resources of knowledge and information, we can improve.
2:29:40So there is a lot going on to improve the models. And if you look back previous years, you see a lot of the best models are solely because of better generation techniques. For instance, Orca, they use different... Like the reasoning chain of thought. Yeah, the reasoning chain of thought and evolved instruction of WizardLM. Our paper on the Genie, that content grounded, that show parity in grounded task generation data. and Phi that we talked about. So all of them, and I guess a lot of the big companies do it in their garage. So don't tell us and share information how they improve GPT-4, but all this preference data, annotation, and feedback that you use is something that go into improving the model and generate embedded synthetic data to improve them.
2:30:38Yeah, I mean synthetic data is like... That's a good summary. Yeah, yeah. Thank you for the good summary. I think that from your summary, the synthetic data is faster to generate. Like humans can evaluate the synthetic data really fast. They cannot generate the synthetic data fast. So it's kind of... Yeah, yeah. Are you also involved in like the world sim stuff or is that more Karen? Yeah, that's more Karen. Okay. Because one form of interesting synthetic data that HuggingFace is doing is basically synthetic data for app generation or website generation and they've released a data set for that for IDFX which is their vision data set.
2:31:18It could be interesting for you guys because it would directly plug into WorldSIM and WebSIM and that might be interesting if you guys think about it. That would be cool, yeah. Cool, well thank you very much. Thank you very much. In case you missed it we referenced a lot of context extension papers in the poster session discussion you just heard. Kaiko and Dev on T-Isles. While training super hot, long rope, ring attention, infinity attention and textbooks are all you need. All are linked in the show notes, which we really hope you're looking at to complement the poster session audio. Next, we have an ICLR outstanding papers.
2:31:52Honourable mention paper for model tells you what to discard. Adaptive KV cache compression for LLMs, aka the fast gen paper. This modifies the standard KV cache algorithm to selectively discard long-range contexts for attention heads targeting local context and non-special tokens for attention heads targeting special tokens. This results in a 40 % memory reduction for inferencing LLAMA 67B. Hi, everyone. I'm very proud to share our work. My name is Su Yu and I'm a PhD student from UAUC. So our work is called Adaptive KVC compression for large language model. So before we dive into the paper, I first want to just a quick recall.
2:32:39So what is KVCache anyway? So during the encoding, every time you encode a token into the QKV vector, so whenever you got a new token, you encode it into a new query vector, and you take the dot product between the query vector and all the historical KV vectors. Then you use the dot product to multiply with way vector, and you got this final attention output. So whenever you add a new decoding step, you are using new query vectors, but you are using all the historical KV vectors. So one simple way to save the compute is you can start all those KV vectors, those historical vectors, special memory space to avoid future recomputation.
2:33:22And every time when you got a new query vector, you just add it into this specific memory space. So in our scenario, this specific KV cache memory space is what we want to compress. So how big is this KV cache? How much memory will it consume? So basically it's in proportional with model size and sequence length. If you encode it in FP16 or BF16, it will consume two bytes per model weight. Just to take an example for the Lama family, we are very used. If you want to do inference with a sequence length with 512, for the largest LAMA model, you will need 20 gigabits. However, considering that we are dealing with model with 10K or at least 10K these days, you will need like over 200 gigabits for the largest model, and that's simply like KVCache memory consumption.
2:34:16So this is huge. So we all acknowledge that actually KVC LLM inference is memory bound. instead of compute bound. Because autoregressive LLM generation, these are sequential steps and very hard to parallelize. So here, I borrow one figure from the very famous VRM paper. It shows the memory layout when you are serving a 16 billion language model with a batch size equals to five. So as you can see, even if you keep this very small batch size, the KVCache will still consume like more than 30 % of memory space. So, yeah. So considering this huge memory consumption of KVCache, what are existing solutions?
2:35:02So the optimal solution is to what we call KVCache offloading. So basically try to offload the KVCache to CPU or MME. However, it will be a non-trivial latency because usually some devices will have limited bandwidth between the CPU and GPU. So I think a better solution here is to just reduce the GPU memory required of this kvcache space. And you can do this from actually both system side and model side. There are a lot of work, like excellent work from the system side, for example, the VRM paper. And here we do parallel work with them, and we work on the model side. So just a quick overview of the FastGam method.
2:35:48is a KVCache invocation algorithm, and it's designed for efficient LLM inference. The most important part is it's on the fly, which means you don't need any kind of pre-training or fine-tuning. And also it's model agnostic, which means as long as you have an autoregressive LLM, you can apply our method. And also it's orthogonal to quantization of distillations. So as you know, our goal here is to improve efficiency while at the same time we want to maintain the accuracy as much as possible. So improve efficiency means we need to drop as much as kvcache as possible. And to maintain the accuracy means you have to match the full attention score scenario, which means you have to match the full attention map before you do this kvcache compression.
2:36:41So just to give a hint of result before we dive into this method, We actually, without any significant performance degradation, a fast-gen can achieve like over 40%. So that's almost half as a memory space for the largest Lama model. And for the smaller Lama model, we can only achieve 55 memory reduction. So what enables our master will motivate us. Actually, we borrow some insight from the bird area. So when BERT came out, there is a famous study paper, which is called, What does BERT look at? It simply tried to display different attention-hide patterns of the BERT model. For example, we found that some attention-hide in BERT model attend all the contacts very broadly, while some will only focus on the next token, while some only focus on the special token, and some focus on the punctuation.
2:37:41So one straightforward way is if this exists in BERT, will it still exist in autoregressive LLM? So for example, llama model. So here we started this llama model, and we display different head pattern from the same layer. As you can see, the first ring, actually most of the attention might focus on the green part, which is a special token. So here, the special token means the start of sentence and the end of the sentence. and in the middle you can see most of the attention focus on the local context which is also the same as Bert so here our conclusion is actually this kind of attention map focus all we call attention sparsity also exists in llama model I would say in autoregressive LLM model so based on this how to do the compression.
2:38:32Yeah, when straightforward is we can, if some has the only focus on the special tokens, that means we can discard all those non-special tokens for it. And for some has the focus on the local contacts, we can discard all the previous long-range contacts. And for attention, had the broadly attend to all tokens, we can simply keep the full attention catch because we still want a performance that matches the full cache scenario. Yeah, so when does this first gem happen? So in a normal inference step, after we get the dot product of query and key vectors, which here we call it attention map, so it's q multiplied k.
2:39:18Based on this attention map, we search for optimal eviction strategy. Here we denote the eviction strategy at C-sharp. So this kind of eviction strategy search is actually designed for per head, per instance, because we found that, as you know, different head display completely different attention sparsity. So that's why we need to find the optimal eviction strategy for each head instead of like all head using the same eviction strategies. Yeah, so given this found optimal strategy, for each head. We use this strategy to compress the KV cache for each head. So here, after this compression, those KV will get a much smaller size and we start it back to the KV cache.
2:40:06So this time, we got a smaller KV cache memory size. So the most important part is how did we do the strategy search? So given this attention map A, The goal is to pick the optimal policy C-sharp that can recover A as much as possible. So to ensure that the recovery is very high performance, we set a recovery ratio T. So this recovery ratio is a hyperparameter we have in our setting and is weighted by L1 norm. So we want to recover the attention map as much as possible, and also with the minimum memory cost. So just to give a hint of performance, when we set the T as a very high value, which is 99%, FastChain can still achieve over 40 % compression ratio for the largest LAMA model.
2:41:06So here the deviation strategy set is designed as concludes different kind of strategy, for example, only pertaining the special tokens, only pertaining the punctuation token, or only pertaining the local context token. Or we simply try to combine them together for better accuracy. Here is a strategy distribution of the fast-gen method. As you can see, actually a very interesting phenomenon is that in most layers, they are occupied by green color. So here the green color means you can only use those special tokens to recover most of the attention map by 99%. So this high sparsity in large-dampage model encourages us to use only special tokens to memorize most of the important information in large-dampage model.
2:42:01So it comes to the experimental side. We conduct our evaluation on both instruction fine-tuned model and base language models, and the model size range from 7 billion to 65 billion. And for the instruction model, we use AlpacaEvol, and we calculate, we use GPT-4 as a judge to calculate the run rate of fast gen over the full cache scenario. So full cache means no compression, no evictions, just original attention. And we also tried the Lama model, which is a base model, and we evaluated by code, math, question answering, and reading comprehension. Those are all generative tasks. Our compare method is those non-adaptive KVCache method, and also we compare the full cache scenario and set up as a baseline.
2:42:49So ideally, the win rate should be 50 % if you can reach the same performance as the full cache scenario. So here we display the performance and memory trade-off of the instruction fine-tuned LAMA model of different sizes. As you can see, for smaller model, actually the performance grows linearly with the KB cache budget. But for the largest model, which is on the right, you can see, even if you only pretend like over 60 % of memory, the accuracy is still the same. So the larger the model is, the more age the fast jam will bring you. We also conduct the memory footprint reduction. So as you can see, if we take a win rate of over 45 as a low quality regression, actually FastGen can achieve over 40 % memory reduction in the largest LAMA model.
2:43:46And for smaller models, we can achieve like over 15 % memory reduction. So here is the conclusion. FastGEN is a method that improves the efficiency of LLAM generation through adaptive KV cache. And the result is very good. It can achieve up to 40 % memory reduction in the largest LAMA model. And for a smaller model, it's over 50%. And right now, we're working on the VLAM implementation because we found page attention suits our method best. And in the future, we'll also try different optimization techniques, for example, quantization and distillation, and see whether it will still work very well if we combine them together.
2:44:32And also, I will try working on group query attention to support the most recent LAMA model. Yeah, thanks. Memory reduction is great for the single GPU case, but when it comes to the very, very large GPU clusters, the networking communication overhead starts to become a bottleneck. We caught up with DeepSpeed from Microsoft Research to learn about what's new with Xero++. Yeah, let me start by a short intro of Xero. So here let's particularly focus on Xero3. So in Xero3, you have everything scattered. Your model widths are scattered, your optimizer space are scattered, and that means whenever you want to do a training step, forward, backward, and the optimizer step, Then you have to do a collective operation on those so that would add up to 3x of the model size Yeah, and that's 3x of the model size on each step.
2:45:28It's a huge overhead if you scale up your training So even if we consider the cutting edge cluster where we have like 80 if any band connection on each node We have RDMA on each switch, but that's still not enough So in the end, we'll scale up your training that's going to shock your training speed. So that's why we want to propose a set of optimizations to improve the communication. We will do in zero. So here, zero plus plus, it can help you by reducing your communication volume by 4x. So let's take a short break down. So first, in the forward pass, that's where the first pass of the outgather on model ways, what happens.
2:46:14And here in this stage, we use block-based quantization. So block means we are doing the quantization on each slice of the tensor. So that we make sure we keep the position and then cut the volume by half. And then for the backward pass, we use the heterogeneous partitioning for the model ways. So that means instead of scatter this model ways on each replica, each GPU, we would scatter it only within each node so that when you do the communication, the communication happens within the node, so you don't have to suffer the intern node by the way. And then for the gradient, that's the trickiest part because gradient is sensitive to the quantization nodes.
2:46:58And if you do it naively, just cutting the precision by half, then you would literally crash your training. Why? That's because when you do the reduction, then that's essentially a combination of your of your quantization error. But it's not obvious that it crashes. So by crash I mean diverge. Okay, yeah. So that's where we propose a novel all-to-all collective design as a replacement of the current reduced scatter. So this design makes sure that when we do the communication we do it in a lower position, but when we do the computation for example, the reduction, that happens in the full position.
2:47:40So that's to avoid the heterodrastic divergence if we do the gradient quantization. This is essentially a combination of the previous two, where we make sure that our quantization happens by slice, and we make sure that we place the data so that we minimize the internal communication. So that's an idea of the three optimizations we have, And that's where we have the theoretical communication reduction by 4x. But in order to translate this 4x theoretical improvement into the actual throughput, that's a huge effort because technically all these operations take time, right? So your quantization, your decantilization, your theoretical communication…
2:48:29You save, but then there's overhead. Exactly. You save the communication but it brings in overhead, a lot of overhead. In order to tackle those overheads, we come up with our own set of customized product kernels. Highly optimized, for example, doing kernel fusion, vectorized memory XI and so on. So we make sure it's maximized in terms of efficiency. And then overlapping. Overlapping between the communication and computation. So in 0.3, then everything is sharded, right? So that means when you operate, you operate on different shards. So that gives us the chance to do overlapping. So basically, the first shard can go into the communication, and then the second shard can do the quantization at the same time in parallel.
2:49:19So that's kind of a way to hide our overhead. And that's where we finally see the speed up in terms of the throughput. So even if on infinite band, one infinite band, 100 gigabytes per second, you are able to see more than 2x speedup. And if you are on internet, that's a totally different story. That's 3 to 4x speedup. Yeah, that's basically the overall workflow of our paper here. It's very high-level summarization, and you will see a lot more details in our paper. But I mean, that's enough for people who haven't heard about it. They'll sample it in and no we're not talking about any accuracy trade-off right like this is pure Oh You can see that the loss curve would closely match Okay, it's not lossless.
2:50:12Okay. Yeah, so you will still see a tiny gap especially at an off-chain. Yeah, but Considering all the throughput gains and such a tiny gap, so I would say it's worth it And is there a backstory between 0 and 0++? Why did you decide to work on this issue? So for example here, that's our motivation. This is measured on the cutting edge cluster. We have 8 infinite band connections, we have RDMAs, we have everything on hardware level we can get from the media. But even in that case, we still see that as we are scaling up the training, the communication will actually take half of the training time.
2:50:53I see. So this percentage is communication over overall. Yeah, yeah. Yeah, exactly. So that's motivated us. Okay, we have to figure out a way to reduce this overhead. Yeah. Yeah. And so what is it now? So currently we don't have this here, but if you take a look at this kind of speed up, then you can see that. It's 2 to 3x. 2 to 3x already. Okay. Yeah. Let's do the super large scale. The plus plus is already released as part of DeepSpeed. So essentially, you can just enable it by a flag. That's all you need. So feel free to check it out. What other, just generally about DeepSpeed? Actually, maybe, can you introduce DeepSpeed at Microsoft and what should people know about you guys' work?
2:51:41Because I think people hear about it, but only in the context of this stuff, the MOE model that you guys released. What is the overall goal? Yeah, so DeepSpeed is elaborate to optimize super large scale training for large models. We first proposed the zero training paradigm. So that's also known as the optimizer states parallelism. Did you do it before you joined Microsoft or? No, no, it's not. It's more like a computer. So this DeepSpeed project starts at early, I would say, coming to good shape by early 2020s. So that's quite a long time ago. And we carry on all the way here to make sure that we always deliver the best training performance for the large scale models and for the large training.
2:52:28By large, I mean large in terms of number of GPUs, number of nodes, and so on. And we're also expanding our scope into inference as well. So, yeah, we all see a set of inference of munitions and inference stats. We call it FastGN or MI2. Yeah. Okay. So yeah, you're working on training improvements, inference improvements, and then the MOE work? No, that's my other teammates. Okay. Okay. Awesome. Anything else people should know about Zero Plus Plus? Like what's next? Oh, what's next is we are working on even more aggressive or overlapping between the communication and the competition. Okay. Yeah.
2:53:05So our goal is that we want to do a synchronized overlapping. So instead of the common way of unsynchronized overlapping, but we make sure that the training always synchronized, but we still overlap the communication and computation. So please stay tuned. That will be released in the next few months. Nice. Then last question, have you looked at the stuff that Jeremy Howard is doing with FSDP and Qlora? Yes, FSDP and Qlora. Because it's kind of like the small parallel of what you guys are doing? Yeah, FSTP is another implementation of the 0.3. And currently, we are trying to learn, kind of, further polish our framework so that we make sure we squeeze the last bit of the performance in terms of the 0.3.
2:53:50That's another ongoing project, and you will see our efforts gradually in the next two months or three. What would be helpful is how do you compare their strengths, and then how do you compare, like, what should people have in their heads comparing, like, their approach versus yours? So there are two different implementations. Yeah. So give some tips. Yeah. So I think people would need to try out themselves. Okay. To figure out. So basically no comment. No problem. Okay. Perfect. Thank you very much. Yeah. Thank you. Thank you. A very politically correct handling there of the FSDP question from Guanhua.
2:54:25That is the end of Section C of our audio tour of ICLR. we covered various extremes of relevant work going on with transformers. From long context extension techniques by using shifted sparse attention and rope interpolation, to adaptive KV catching for single GPU memory consumption, to communication volume for large GPU cluster bandwidth utilization. We're surprised that all these options fell out so naturally from just walking the floor. we've just crossed our three of this podcast and it's already tracking to be our longest episode ever so we unfortunately have to cut all the other poster sessions that didn't make it into one of these top categories we identified please see our show notes if you're interested in papers on summarization llm uncertainty tabular data and watermarking there are a whole lot of watermarking papers, both on how to watermark and on why there is no point watermarking.
2:55:25We're still not sure why the topic seemed so popular this year. Our last section today covers the post-transformer's future, as is obligatory at the end of every research podcast and workshop day portion of every research conference. Apart from Lillian Wang's talk on how OpenAI thinks about safe AI deployment, Sasha Rush's talk on state space models got the most buzz among attendees we talked to. So here it is. I'm kind of searching for what my research area is, like many people these days, and I think mathematical and empirical study of foundation models is pretty close. I've done some work in scaling laws and instruction tuning and a lot of the things that were mentioned earlier.
2:56:08But today I'm going to talk about architectures. A lot of people ask me why I work in architectures. It's not because I think that data isn't important or isn't kind of the main thing that makes foundation models work. But it's a hard area to study, and I'm kind of grasping for what the connection to data is and how to study it in a rigorous way. Whereas I think architecture gives us at least something we can kind of grasp onto, an understanding of how it works and how it connects to some of the problems that we work on. But I don't want to kind of convey that I'm a kind of architecture-only sort of person, and I'm really excited to see what people talk about today.
2:56:41So in this talk, I'm going to talk a bit about some of the last couple months in states-based models. I think you can also think of this area as kind of RNNs. I've been calling it linear RNNs, although we're kind of increasingly seeing nonlinear RNNs come back as well. I think I want to talk today a little bit about what the kind of core principles are and how to think about this as a model designer. I know we have some people in the room who are kind of building these and kind of coming up with new architectures for SSMs. Today's talk is going to focus a little bit more on how to use them and how to apply them to practice.
2:57:16So the work today is going to touch on some projects with various students who I collaborate with or my group. I'm going to talk about a couple different papers that apply SSMs in practice. But before we get there, I think it makes sense to first get us all on the same footing. I've been working a lot on kind of developing tutorials and kind of shared notation to try to demystify what I think is quite a complicated area. I'm not sure I've succeeded in this. People keep on changing the models, which makes it a little hard. But I'm going to talk first about kind of what I think are the core principles that you can use as a model designer when working with states-based models.
2:57:54This is a short abstract from a longer tutorial. All three of these talks are online in longer forms. so you can find them on YouTube if you want more details. This also works a little bit better when it's interactive. I know that's hard in a workshop, but please ask questions at the end about questions you may have. So throughout this talk, we're basically going to only focus on kind of one setting. We're going to be working in a setting where we have an extremely long input context, and we'd also like to perform a very long-form generation. I think this is important because a lot of the things we're going to talk about are kind of only true in a kind of big-O sense.
2:58:30So we're really talking about kind of asymptotic properties of these models. I used to think this was a little bit of a stretch, but now I'm increasingly kind of really do think we're going to be in a world where we're going to want basically infinite long context for these models. And I think if we're really kind of taking in-context learning seriously, it really does imply that that's coming. Of course, the dominant model in this space is transformers. I don't really have to say much about this model. It's arguably the most important invention of the last 10 years, like in the world. So that's kind of cool.
2:59:01But it's worthwhile to think of some notation. So throughout the talk, I'm going to use L to represent the length of the sequence that we're working with. And I'm going to kind of write a schematic transformer as just consisting of attention and MLP layers throughout. Of course, there are two kind of well-known asymptotic properties of transformers. The first is that the memory at inference time scales linearly in the length. So this is kind of the infamous KV cache that you have to store this much memory in order to do generation. I focus particularly on memory. It's tied into all sorts of things such as energy and efficiency.
2:59:40But I think if we just think about the fact that we have to, at minimal, store the keys and the values for every position, it gives you a good sense of why they're hard. The other property is that they scale poorly at training. There are lots of ways to make this more efficient in practice or to come up with clever ways to parallelize it, but at the end of the day, you really have to do L-squared multiplications. If you want to compute transformers exactly, you just have this property and you have to deal with it some way during training.
3:00:14The papers I'm going to talk about today are kind of I put under the class of Mamba-like models. I'm not sure of exactly the right way to call these things, but I think Mamba has kind of captured the mindshare of how this works and was the first one that really got people to very much pay attention in this space. These are kind of models that use algorithms that are kind of aware of the hardware to try to make it possible to scale other sorts of architectures that get rid of the two main transformers issues in practice. There are a ton of these and more coming out every day. Lots of really interesting ideas in this space, and it's worth thinking about the differences between the models.
3:00:50But given as I only have a short talk, I'm going to kind of conflate them all together and try to talk more about the similarities. So here are the kind of key properties that we're interested in. The first is that we want to have fixed-sized memory in our hidden state. So in particular, I'm going to use kind of an RNN-style notation where X is our input. Each one of these blocks represents a new token coming into the model. We're going to produce some block Y as the output from our model, and that Y is going to be fully determined by some sort of recurrent hidden state. Now, one of the big differences that you may not be used to if you haven't looked into these systems is that this hidden state is going to be very big.
3:01:38Now, it's big, but big and constant. So it's this large block of memory that you keep over time, but it most importantly is big in depth, not in length. So that means it doesn't expand as the sequence gets longer, but simply keeps around a fixed size memory. The other key property is that these models are going to be subquadratic in terms of their training. So we're not going to have to do quadratic numbers of multiplications in order to compute our output y. Again, this doesn't mean it's small or that it's inherently fast, just that it's not scaling with the length of our sequence. If we have this property, we think we can kind of better utilize these models in hardware and get around some of the long scaling issues.
3:02:30And of course, these models have gained a lot of attention, not just because they're interesting mathematically, but because they're beginning to show promise on real language modeling tasks. This is a really hard thing to show. We've been relying particularly on perplexity and particular perplexity in terms of the computation of these models. So the kind of key main result was showing that these sorts of architectures could produce very good loss at roughly the same amount of compute in terms of flops as transformer models. and not just any transformer models, but kind of the state-of-the-art transformers with all the bells and whistles that people have come up with, kind of trying out all different permutations over the last five or six years.
3:03:16So I think this result in Mamba and subsequent results in other papers were really kind of the thing that woke people up to that this architecture may really work in practice, both in terms of getting good loss, but also doing it in a hardware-efficient manner. okay so in the tutorial we go through four different things that you should know about these architectures for the sake of time i'm going to focus just on two of them today i think this will give you a sense just of how they work in enough ways to think about how you can apply them to your own problems so the two i'm going to focus on are kind of what the models actually are in terms of their kind of mathematical form and then i'll talk a little bit about how we compute these models in practice.
3:04:01So let's first talk about understanding the models. So the key thing that many of these architectures share is that they have this matrix-valued hidden state. We're going to be keeping around a kind of matrix H that represents all the hidden state that we're kind of keeping track of as we go. So we have three dimensions here, the neural network dimension, the length of the sequence, and this extra extension dimension that represents an extra amount of information we're keeping in the hidden state as we go. Now, obviously you've seen models of this form. This model looks very much like the classic kind of vanilla recurrent neural network.
3:04:44Either you're young enough that you came to the field when this model kind of already was kind of out of favor, or you're old enough to have a sense of exactly how it works and have seen it a million times. Either way, you probably come in with a bias that in some sense this model is bad, but I think we're kind of trying to understand a little bit more why that happened and why it kind of went out of favor in practice. But let's look at the model specifically. So we have kind of three core model parameters, which I'm going to call A bar, B bar, and C. These represent kind of the way we transform the data to try to produce the output.
3:05:22Now these have different names in different papers, but you can think of the B as somewhat like moving from X to the hidden state. You can think of A bar as being the dynamics of the hidden state over time. And you can think of C as transforming from the hidden state out again to Y. Now, oftentimes RNNs are written without a matrix-valued hidden state, but you can kind of obviously change them in different forms, and you basically get the same math back. Also note that we're going to use the vanilla or Elman RNN here. where we have a non-linearity around the hidden state at each time step. People started to really look back at RNNs again after work in 2021 on a model known as S4.
3:06:07S4 is what's known as a linear time invariant version of this model. The main distinction that you can kind of think about when kind of thinking about these approaches abstractly is that we're simply going to take away the non-linearity of the RNN. So this gives us a system that is entirely linear, but of roughly the same form. We're going to use B bar to transform our input into our hidden space. We're going to use A bar to produce the dynamics of our model. And we're going to use C to transform from H out again to Y. For a while, this sort of linear time invariant model was thought to be very hard to learn.
3:06:47And in fact, if you start with kind of random parameters and just kind of throw this kind of into PyTorch, it's going to perform very poorly. So people had to develop methods in order to get the linear time invariant model to be stable in order to train it on real problems. Now, the results in S4 were very promising. And it showed that models like LTI models could perform very well on long-term problems. But when people tried to apply these models to language modeling, it didn't scale as well. So I'm going to be a little sloppy here and roughly kind of categorize a bunch of these models as LTI-like and compare them to attention or transformer-based models.
3:07:30This is a graph from Aurora 2024. But basically what it's showing is that when people tried to scale LTI-based models to language modeling, it performed relatively poorly. This was a bit surprising as these models worked well on lots of other long-range tasks. And the kind of perplexing numbers here represent roughly a compute normalized version of each of these models. And the difference is pretty stark between these LTI models and transformers. In the Mamba paper, they look at two cases where LTI models fail. These cases are relatively intuitive and I actually found them very useful for thinking about why language modeling is hard.
3:08:14The first is a problem of filtering. The way I'm thinking about this is if you have a lot of data from the web, it's very noisy. A lot of times you'll have things like ads or kind of random copy thrown in the middle of websites. A good language model like a transformer should just learn to ignore this. It can just jump over it using kind of signals like parentheses or other kind of other offsets in the training data. But interestingly, LTI models just cannot ignore or filter data. If you look at the math, you can see that B bar basically has to act on every input in exactly the same way. That means that every token that comes into the model has to change the hidden state, no matter what.
3:09:01The second problem is the case of resetting the model. So imagine you have a website that has a bunch of articles, and each article is separated by a new title. You'd like your model to be able to reset the hidden state so it could move on to remembering things about the next article in line. Of course, we have exactly the same problem in a linear time invariant model. If you have a bar and you want to kind of start over, you can't, right? You have to have the same dynamics at every position. And this idea is both essential to the linear time invariant setup and also for the efficient algorithms that are used to calculate it in practice.
3:09:41So we'd like to get around these two problems in order to run this model in practice. Okay, so when you look at the solution, it actually seems pretty obvious. Of course, that doesn't mean it's actually easy to implement in practice. So we're going to kind of go back to a model that takes into account some sort of variance based on the data itself. So I'm going to represent this in the talk by simply adding a subscript k to each of the parameters a bar, b bar, and c. And this represents that we're going to be kind of changing the parameters at each position. This will allow us to do things like filtering out inputs or resetting our hidden state.
3:10:21You can see this in these two extreme cases by the fact that if we set AK to 0 or BK to 0, we can ignore inputs or reset our hidden state. In practice, we're going to implement this in a similar way as you'd implement the Q, K, and B for transformers. We'll simply look at our X values and use them to predict the AK, BK, and CK at each time step. This can be done by running a neural network transformation on our input and using that to parametrize each of our AK, BK, and CK. If you want to remove something, you just set it to zero as you go. Cool. So this sort of model, which looks a bit more promising and kind of recalls some of the extensions to RNNs that were popular at the time, fixes many of the central issues with linear time invariant models.
3:11:18It allows us to maintain a fixed-size state while still getting properties like resetting and filtering. Now, that all being said, there are still many other issues with actually implementing this in practice. I'm not going to go through all of them today, but I want to give you a taste of one of the challenges, which is how you run this model efficiently at training. So I want to give you a sense of how you can compute a linear time varying system efficiently on parallel architectures. And to do this, we're just going to talk through a kind of classical algorithm in parallel computing. And one that I think kind of everyone should just know in the same way that people know matrix multiplication.
3:12:00So we're going to talk through how you compute an associative scan. scan, and in particular, how you use associative scans for computing these linear time varying systems. This treatment is from this very nice report from Guy Blalock. I think it's from 1990. That's worth going back and reading, and kind of basically all the details are great. It's a really cool paper. Okay, so to get started, we're going to do a kind of hello world problem. We want to compute a cumulative sum of a list of numbers, and we're going to assume that the list is some power of 2 in length. So we have 3170, 4163, and we'd like to compute a running sum.
3:12:43We're going to call the running sum yk, and it's the sum of xi from 1 to k. This is the output of this scan, and I'm just going to note that an alternative way to think about a cumulative sum is as a system like this, where we're commuting a hidden state, hk, at each time step, and we're doing that by adding xk to hk, and then just outputting hk at each time step. This kind of converts us to the same notation that we've seen so far when working with SSMs. To do this, we're going to run a tree-based parallel prefix scan. We do this by putting each of these numbers at the leaves of our tree, and then computing a binary tree where at each node we sum the kind of children of that node.
3:13:36We run this at each step until we get the sum of every position in our list. Now this gets us a lot of the information we need. We have the sum of the first two values, the first four values, and of all eight values. but we don't have the intermediate terms that we need for the cumulative sum. So in order to get those positions, we have to run back down the tree, keeping track of the information we need and filling in the additional values. So we can run a down sweep over that tree where we compute at the leaves of that down tree each of the values that we need for the cumulative sum. This calculation can be done fully in line and very efficiently.
3:14:21You can actually do it, or a lot of it, in the kind of registers of a GPU. But this is how you commute a cumulative sum, whereas we need to compute the kind of full linear time varying system. That has these additional terms, AK, BK, and CK, that vary by the position of the sequence. However, we can do this by slightly modifying the main operator that we use for the cumulative sum. So we're going to basically replace a sum of two values with a new associative operator, which I'll call osum down here. Instead of acting on two values, osum is going to act on two tuples. These tuples will keep track of two pieces of information and will take the following form.
3:15:10So if we say a1, b1, osum, a2, b2, we get the following output. a2a1 comma a2b1 plus b2. I'll leave it as an exercise to go back and convince yourself that this operator is associative, but it is an operator that we can run efficiently on a GPU in practice. Using this operator, we get a tree that takes the following form, and if we run this for all our data, building up the tree, Each of these intermediate forms represent the hidden states that we need in order to compute the SSM. So you can see that in this tree here, B1X1 is exactly the first hidden state. A2B1X1 plus B2X2 is the second hidden state.
3:16:04And then at the top of this tree, we get the computation for the final hidden state that we need. When we do the down sweep of this tree, we get all the additional values, including h0 and h3, that we need in order to compute the full computation. Now this is a very kind of idealized version of this algorithm. It's a bit more complex to run this on GPU in practice. But these algorithms are now built into libraries like Trident. And you can run basically an associative scan over basically any function in about one line of code. So we now can kind of try and play out with these algorithms in practice to make them work.
3:16:44Okay, so first of all, this is like extremely clever and cool. I really like it. One thing I'm trying to understand is for the left-hand term, you've kind of gone from having these vectors you're throwing around to having matrices. And intuitively, that seems really rough, especially if you're in high dimensions. So is there some way that you have of handling that? Yeah, absolutely. Almost all of these papers, you diagonalized A matrices. So in practice, the A is going to basically be scalar values, which is kind of necessary to run it efficiently. That being said, I write it in the more general form, just because there's a lot of talk in the community now of kind of moving from diagonal forms to things like block diagonal or even totally full matrices.
3:17:29So I think there's very interesting questions of how to compute the matrix versions more efficiently in practice. I think I'm going to move now to talking about the kind of tutorial of how they work to two different applications of using them in practice. So takeaways. We have efficient training of these models with long context, and we have fast sampling. I haven't talked about the sampling, but just intuitively, we're going to do RNN style sampling. We don't have to maintain the whole history. We just have to maintain the hidden state in practice. We're interested in these things because there's promising perplexity results with various different architectures.
3:18:07There's some questions about how they perform on things like in-context learning, but the perplexity results are pretty important, at least to get us started. The last thing I'll note is that these are not a magic bullet. The models are still large, you still have to have a lot of parameters, and it still requires the same amount of data. So I'm not telling you I'm like breaking scaling laws here, I'm just saying we can handle long context in a different way. So in the last 20 minutes, I want to do kind of two quick vignettes about how you can utilize these models to produce different foundation model structure.
3:18:45So first, I'm going to talk about using these approaches to do tokenization-free language modeling. And then I'm going to talk about how you can utilize these architectures to do diffusion. So let's first talk about removing tokenization. So there's been a kind of long-running thread in NLP where people have been interested in removing the tokenization part of language modeling. There's lots of reasons why this might be cool. One is that you can show that if you're working without tokenization, your models are more robust to character-level noise. You could also imagine using a model that works the same way for different modalities.
3:19:27And you can avoid tokenization effects that make certain constructs in certain language work more poorly with language models. Now, that all being said, I think I'm kind of mostly interested in this problem just in kind of a deep learning sense. I think there's a kind of longstanding principle that we should be working on the lowest granularity possible. And so just the problem of trying to build models that work on four times longer sequences is, I think, an interesting problem in itself. You can obviously apply this problem by using transformers. If you have a standard transformer, you can just run it on bytes directly.
3:20:04But when you do that, your sequence length gets four times longer. Since the models are quadratic, this becomes way, way worse, and it makes the models basically kind of impossible to use in practice. People have got around this issue by patching the data. So here we're going to instead work on chunks of bytes where you use kind of fixed-sized patches to remove this penalty but then try to generate bytes at the top of the model. I think this is a clever way of getting around the problem, but in my experience, patching almost always makes the model worse. And we saw this when we actually applied these models in practice.
3:20:46I think there's kind of like no free lunch from kind of working with larger patches. It generally just kind of pays a penalty that you have to end up training for much longer, or the model works kind of worse in the final output. Models like Mamba or SSMs allow us a potential solution to this problem. If we can run a model that uses a fixed-sized hidden state, then we've somehow kind of disconnected the length of the sequence from its runtime complexity. So kind of a model that doesn't kind of change its hidden representation based on the input data representation allows us to basically work with a lower granularity without kind of paying that big, big penalty in quadratic search.
3:21:32So to do this, we're going to basically just apply Mamba directly to byte-level models. What this means is that we'll have this big hidden state that we update over time. We'll have one of these hidden states per each byte of our input, and it will be used to generate each byte of our output. Now again, I think the kind of first intuition you get from working with RNN models is, well, it seems like you're losing a lot of information. Transformers are able to memorize everything. Well, here we have to store it all in this hidden state. But even just the default Mamba model has a very, very large hidden state.
3:22:14So we're talking about 3.5 megabytes just represented in these hidden states over time, which is way, way, way more than you need to actually represent all of the bytes in our context. So in practice, for most of our experiments, we're talking about like 10K bytes in our sequence, whereas our hidden state has 3.5 megabytes of storage, right? So there's not really a problem with storing this kind of information if the model can effectively learn how to utilize it in practice. As I mentioned earlier, to actually train these models, we're going to be using the scan operation that I showed before.
3:22:56And other than that, we're basically just applying a vanilla version of Mamba to byte-level models. the problem that comes up in practice is that we actually need to generate bytes in our kind of output so one nice thing about tokenization is that when we generate tokens we can do them one at a time and that's relatively fast for generating bytes we need to generate kind of four bytes to get one of these tokens so it seems like we're paying a large cost to actually use these models in practice. However, over the last year, there's been a lot of advances in applying speculative decoding for generation.
3:23:38And I want to argue that byte level models are a particularly nice form for speculative decoding. So in particular, if we have a model that can draft at a larger granularity, we can kind of give us a sense of where we're going with our byte level approach. So what we're going to do is we're going to draft with tokens on the left-hand side, and then we're going to verify with bytes on the right-hand side. The really cool thing about doing verification with byte-level models is it can be done in parallel. We have the ability to run a parallel scan to check all these bytes on the right-hand side.
3:24:17This allows us to avoid a lot of the problems of reloading in the weights or generating in a sequential manner for the byte-level approach. The way it works is that if everything matches up into a certain point, we just keep on going until we hit a letter where it doesn't match our speculation. We then continue along with the byte-level approach until we hit a token boundary and then continue on with the speculative approach to our right. So by doing this, we're basically able to speed up the MambaByte model to roughly the same speed as a token-based model. We're basically using a kind of standard tokenized Mamba as the draft model and the MambaByte model for verification.
3:25:06We get roughly the same generations at nearly the same speed as we would have with the tokenized version. Cool. So the paper has lots of experiments. I'm going to go through kind of the high level just to give you a sense of what we're thinking about. The kind of main conclusion from this work is that Mamba is like extremely good fit for byte level modeling. Basically out of the box, it beats transformer models across the board. And it beats a lot of patched version of transformer models as well. We find this both in a kind of parameter match setting and also a flop match setting. and with using significantly less data.
3:25:48So no real innovation here. This was just an observation that applying SSM models to these tasks works really well and has a nice structure for managing the hidden state. Another thing that's interesting is we see certain properties out of the box that others have observed in their work as well. We see basically length generalization for free. We train on about 8k bytes, but the model is able to generalize over 30k bytes with only very small losses in perplexity. This is one nice property of RNNs because they're inherently sequential models. They don't have the same kind of properties of transformers where they are unable to generalize to longer sequences without clever tricks.
3:26:32Cool. Let me skip ahead. I think another interesting result is that with Mamba, we see similar results on perplexity, whether we use bytes or tokens. So training at a byte-level model, you can compare directly the perplexity to a token-level model. So in kind of fair comparisons in a parameter-matched setting, the two models basically converge to roughly the same perplexity. This kind of applies that byte-level models with the same hidden size state can perform as well as token-based models. It's much harder to do that comparison in a fair way with transformers. Now, this doesn't mean we should train byte-level large language models yet.
3:27:17There are a lot of kind of issues about doing that at scale, but it does show that maybe there's nothing inherently wrong with training on bytes. Cool. Okay, so I have about five minutes left. I'm going to, let's see, I'm going to just do a quick summary of one last work. I think the story is relatively similar, but I think it's worth kind of knowing. So this is a work at CVPR this year called Diffusum, where we apply a very similar idea to diffusion models. We're going to basically be focusing on the architectural part of a diffusion system. We want to build an architecture that can map from XT plus 1 to XT, basically do one step of denoising.
3:28:06I'm going to note that all kind of state-of-the-art diffusion models have some self-attention baked into the core of them. And this self-attention is critical to performance. So this is true about UNET-based models that basically downsample to a very small size and then apply self-attention. And it's also true in transformer-based models that first patchify their inputs and then run self-attention in a patchified form of the data. I think this patchifying should just go away. I think it is bad, and I think people know it's bad, but we've kind of accepted that it's kind of something you need in order to apply self-attention.
3:28:52In a world where, and you can see this in all these papers, they all show these kind of results that show that the more patrifying you do, the worse your images gets. And a lot of the work is to kind of reduce the patrifying to a relatively small size. If we don't have attention, we basically don't need to pacify. We can work in as large or as small a granularity as we can fit into our... So we're basically going to do that. We're going to start with an image. We're going to flatten it. And then we're going to apply a state-space model instead of self-attention. The main benefit of the state-space model here is that we don't have to compress down to a smaller size.
3:29:35We can run on a large granularity of the image and we can kind of produce our output. So we're not going to even argue in this paper that it's kind of better or worse than self-attention, just that the main issue here is that you're compressing the representation to start with. What we find is that for these models, we get a kind of better scaling properties with longer images that we have longer images because they're less patched. And if we were trying to run attention on these models, it would scale very poorly. Let's see, here are some results. We're able to, I guess, generate good looking images using these models.
3:30:17And we get basically a state of our performance on image net conditional generation by using state space models instead of self-attention. So I think our conclusion here is that global attention is kind of critical for these models, but we think that the ability to replace that with other approaches like state-space models will lead to new and interesting designs. I think this is interesting for images, but it's particularly interested for even harder diffusion problems. So if we talk about video modeling or 3D modeling, you have much longer sequences and see much stronger penalties from doing compression on these models themselves.
3:30:57Okay, that was a somewhat whirlwind tour. I think I'll stop there if anyone has any questions. Thank you so much.
3:31:30you get a full sense of how ICLR really is the ultimate place to learn, think, and talk about the state of the art in learning representations. Because we don't like being pure hype people, we'll end the pod today with one final ICLR Outstanding Paper Award that throws a bit of cold water on state-space model outperformance, if we just introduce data-driven priors for Transformers. Hi, I'm Ido, and I'll be presenting our work on fair comparison of long sequence models. This work was done in collaboration with Jonathan Berendt and Ankit Gupta. Our work is concerned with how to evaluate inductive bias.
3:32:09In the typical setting of evaluating an inductive bias, a model is trained for a random initialization on a suite of dedicated tasks. On the other hand, when tackling real-world problems, the modern standard practice is to first pre-train a model on a large pre-training dataset prior to fine-tuning on the desired task. This pre-training phase has revolutionized most areas of machine learning, leading to outstanding results. Yet, when developing new architectures with better inductive bias for a particular task, it is still common to train on the task data from scratch, starting from a random initialization.
3:32:43A prime example of estimating inductive bias is modeling long-range dependencies across sequences. To do so, standard benchmarks such as Long Range Arena, or LRA, provide multiple tasks that require learning dependencies between distant elements. A significant result of the original LRA paper showed that transformers, and efficient variants, failed to report adequate performance on the tasks. This inefficacy of transformers has led to a line of new architectures, suggesting changes to RNNs, CNNs, and transformers themselves, biasing them towards capturing long-range dependencies and achieving impressive performance when trained from scratch.
3:33:24However, these results do not align with performance of pre-trained transformers that have displayed remarkable capabilities and tasks involving modeling long-range dependencies, such as text summarization, code completion, and protein folding. In this work, we shed light on this discrepancy, showing it stems from inadequate training and evaluation practices and suggests a simple and efficient solution allowing a proper evaluation. While avoiding pre-training on a large dataset is understandable, training from a random initialization with downstream supervision alone disregards the role of the pre-training objective itself, leading to a different inductive bias than that of a pre-trained model.
3:34:06Our proposed solution is simple. Rather than training from scratch, one can achieve a better evaluation by first pre-training on the downstream data itself, or self-pre-training, as coined by Krishna et al. This idea is motivated by the work of Alnubi et al. and Krishna et al., demonstrating that, when using denoising objectives, pre-training solely on downstream training data often leads to similar performance is pre-trained on large data sets. Therefore, a more realistic estimate can be obtained via self-pre-training, or SPT for short, with SPT acting as a data-driven initialization method. Doing so allows a fair comparison between methods, as only the task data is used and better reflects the performance of pre-trained models by including a self-pre-training stage.
3:34:55To demonstrate the importance of SPT, we empirically showed that prior to learn through SPT with denoising objectives are highly effective for learning long-range dependencies, implying that a correct evaluation must account for the pre-training stage. While the performance of trained-from-scratch transformers on LLA is subpar compared to S4, SPT improves their average performance by more than 30%, matching the state-of-the-art without any architectural changes. We find SPT to also benefit S4, with performance gains in 5 out of six tasks. Moreover, with SPT, S4 solves the challenging PATHX-256 task with a 20 % improvement compared to training from scratch.
3:35:38To the best of our knowledge, we are the first to show purely attention-based methods can achieve comparative results on LRA. Observing the drastic effects of SPT, we ask whether simpler models can achieve similar performance as complex ones. We study the S4 model and a natural simplification of it. The S4 model can be viewed as a reparameterization of a linear RNN. Motivated by an accompanied theory, an S4 model reparameterizes the RNN parameters instead of learning them directly, and initializes them with theoretically derived values. Inspired by the success of S4, Gupta et al. proposed a simplification called the Diagonal Linear RNN, or DLR, replacing the reparameterization steps with a single diagonal matrix.
3:36:25We regard the differences between the two models as handcrafted biases, as these are the only differences between the models. Any advantage in modeling long-range dependencies is associated with them. When both models are trained from scratch, DLR does not match the performance of S4, pointing to the effectiveness of the handcrafted biases. Yet, adding an SPT phase diminishes the gap to roughly 1%. Showing biases for pre-training can lead to a simpler model with similar performance. For more details about self-pre-training and evaluation, check out our paper. And thank you for listening. And that is a wrap for part one of our coverage of ICLR 2024.
3:37:07All the best papers and talks covering image generation, with a sidetrack on compression and adversarial attacks. Vision, with a sidetrack on self-supervised and weakly supervised learning. extending transformers and attention across long context, single GPU and large GPU clusters and the state of state space models featuring the voices of Christian Zegedi, Ilya Sutskeva, Sasha Rush and many, many other luminaries. Many thanks to those who took the time to speak to us whether on or off mic. Part two of ICLR coverage is solely on reasoning and agents. subjectively the biggest topic discussed at ICLR for AI engineering.
3:37:49Stay tuned.
From the publisher
Speakers for AI Engineer World’s Fair have been announced! See our Microsoft episode for more info and buy now with code LATENTSPACE — we’ve been studying the best ML research conferences so we can make the best AI industry conf!
Note that this year there are 4 main tracks per day and dozens of workshops/expo sessions; the free livestream will air much less than half of the content this time.
Apply for free/discounted Diversity Program and Scholarship tickets here. We hope to make this the definitive technical conference for ALL AI engineers.
UPDATE: This is a 2 part episode - see Part 2 here.
ICLR 2024 took place from May 6-11 in Vienna, Austria.
Just like we did for our extremely popular NeurIPS 2023 coverage, we decided to pay the $900 ticket (thanks to all of you paying supporters!) and brave the 18 hour flight and 5 day grind to go on behalf of all of you. We now present the results of that work!
This ICLR was the biggest one by far, with a marked change in the excitement trajectory for the conference:
Of the 2260 accepted papers (31% acceptance rate), of the subset of those relevant to our shortlist of AI Engineering Topics, we found many, many LLM reasoning and agent related papers, which we will cover in the next episode. We will spend this episode with 14 papers covering other relevant ICLR topics, as below.
As we did last year, we’ll start with the Best Paper Awards. Unlike last year, we now group our paper selections by subjective topic area, and mix in both Outstanding Paper talks as well as editorially selected poster sessions. Where we were able to do a poster session interview, please scroll to the relevant show notes for images of their poster for discussion. To cap things off, Chris Ré’s spot from last year now goes to Sasha Rush for the obligatory last word on the development and applications of State Space Models.
We had a blast at ICLR 2024 and you can bet that we’ll be back in 2025 🇸🇬.
Timestamps and Overview of Papers
[00:02:49] Section A: ImageGen, Compression, Adversarial Attacks
* [00:02:49] VAEs
* [00:32:36] Würstchen: An Efficient Architecture for Large-Scale Text-to-Image Diffusion Models
* [00:37:25] The Hidden Language Of Diffusion Models
* [00:48:40] Ilya on Compression
* [01:01:45] Christian Szegedy on Compression
* [01:07:34] Intriguing properties of neural networks
[01:26:07] Section B: Vision Learning and Weak Supervision
* [01:26:45] Vision Transformers Need Registers
* [01:38:27] Think before you speak: Training Language Models With Pause Tokens
* [01:47:06] Towards a statistical theory of data selection under weak supervision
* [02:00:32] Is ImageNet worth 1 video?
[02:06:32] Section C: Extending Transformers and Attention
* [02:06:49] LongLoRA: Efficient Fine-tuning of Long-Context Large Language Models
* [02:15:12] YaRN: Efficient Context Window Extension of Large Language Models
* [02:32:02] Model Tells You What to Discard: Adaptive KV Cache Compression for LLMs
* [02:44:57] ZeRO++: Extremely Efficient Collective Communication for Giant Model Training
[02:54:26] Section D: State Space Models vs Transformers
* [03:31:15] Never Train from Scratch: Fair Comparison of Long-Sequence Models Requires Data-Driven Priors
* [03:37:08] End of Part 1
A: ImageGen, Compression, Adversarial Attacks
* Durk Kingma (OpenAI/Google DeepMind) & Max Welling: Auto-Encoding Variational Bayes (Full ICLR talk)
* Preliminary resources: Understanding VAEs, CodeEmporium, Arxiv Insights
* Inaugural ICLR Test of Time Award! “Probabilistic modeling is one of the most fundamental ways in which we reason about the world. This paper spearheaded the integration of deep learning with scalable probabilistic inference (amortized mean-field variational inference via a so-called reparameterization trick), giving rise to the Variational Autoencoder (VAE).”
* Pablo Pernías (Stability) et al: Würstchen: An Efficient Architecture for Large-Scale Text-to-Image Diffusion Models (ICLR oral, poster)
* Hila Chefer et al (Google Research): Hidden Language Of Diffusion Models (poster)
* See also: Google Lumiere, Attend and Excite
* Christian Szegedy (X.ai): Intriguing properties of neural networks (Full ICLR talk)
* Ilya Sutskever: An Observation on Generalization
* on Language Modeling is Compression
* “Stating The Obvious” criticism
* Really good compression amounts to intelligence
* Lexinvariant Language models
* Inaugural Test of Time Award runner up: “With the rising popularity of deep neural networks in real applications, it is important to understand when and how neural networks might behave in undesirable ways. This paper highlighted the issue that neural networks can be vulnerable to small almost imperceptible variations to the input. This idea helped spawn the area of adversarial attacks (trying to fool a neural network) as well as adversarial defense (training a neural network to not be fooled). “
* with Wojciech Zaremba, Ilya Sutskever, Joan Bruna, Dumitru Erhan, Ian Goodfellow, Rob Fergus
B: Vision Learning and Weak Supervision
* Timothée Darcet (Meta) et al : Vision Transformers Need Registers (ICLR oral, Paper)
* ICLR Outstanding Paper Award: “This paper identifies artifacts in feature maps of vision transformer networks, characterized by high-norm tokens in low-informative background areas. The authors provide key hypotheses for why this is happening and provide a simple yet elegant solution to address these artifacts using additional register tokens, enhancing model performance on various tasks. The insights gained from this work can also impact other application areas. The paper is very well-written and provides a great example of conducting research – identifying an issue, understanding why it is happening, and then providing a solution.“
* HN discussion: “According to the paper, the "registers" are additional learnable tokens that are appended to the input sequence of a Vision Transformer model during training. They are added after the patch embedding layer, with a learnable value, similar to the [CLS] token and then at the end of the Vision Transformer, the register tokens are discarded, and only the [CLS] token and patch tokens are used as image representations.
The register tokens provide a place for the model to store, process and retrieve global information during the forward pass, without repurposing patch tokens for this role.
Adding register tokens removes the artifacts and high-norm "outlier" tokens that otherwise appear in the feature maps of trained Vision Transformer models. Using register tokens leads to smoother feature maps, improved performance on dense prediction tasks, and enables better unsupervised object discovery compared to the same models trained without the additional register tokens. This is a neat result. For just a 2% increase in inference cost, you can significantly improve ViT model performance. Close to a free lunch.”
* Sachin Goyal (Google) et al: Think before you speak: Training Language Models With Pause Tokens (OpenReview)
* We operationalize this idea by performing training and inference on language models with a (learnable) pause token, a sequence of which is appended to the input prefix. We then delay extracting the model's outputs until the last pause token is seen, thereby allowing the model to process extra computation before committing to an answer. We empirically evaluate pause-training on decoder-only models of 1B and 130M parameters with causal pretraining on C4, and on downstream tasks covering reasoning, question-answering, general understanding and fact recall.
* Our main finding is that inference-time delays show gains when the model is both pre-trained and finetuned with delays. For the 1B model, we witness gains on 8 of 9 tasks, most prominently, a gain of 18% EM score on the QA task of SQuAD, 8% on CommonSenseQA and 1% accuracy on the reasoning task of GSM8k. Our work raises a range of conceptual and practical future research questions on making delayed next-token prediction a widely applicable new paradigm.
* Pulkit Tandon (Granica) et al: Towards a statistical theory of data selection under weak supervision (ICLR Oral, Poster, Paper)
* Honorable Mention: “The paper establishes statistical foundations for data subset selection and identifies the shortcomings of popular data selection methods.”
* Shashank Venkataramanan (Inria) et al: Is ImageNet worth 1 video? Learning strong image encoders from 1 long unlabelled video (ICLR Oral, paper)
* First, we investigate first-person videos and introduce a "Walking Tours" dataset. These videos are high-resolution, hours-long, captured in a single uninterrupted take, depicting a large number of objects and actions with natural scene transitions. They are unlabeled and uncurated, thus realistic for self-supervision and comparable with human learning.
* Second, we introduce a novel self-supervised image pretraining method tailored for learning from continuous videos. Existing methods typically adapt image-based pretraining approaches to incorporate more frames. Instead, we advocate a "tracking to learn to recognize" approach. Our method called DoRA leads to attention maps that DiscOver and tRAck objects over time in an end-to-end manner, using transformer cross-attention. We derive multiple views from the tracks and use them in a classical self-supervised distillation loss. Using our novel approach, a single Walking Tours video remarkably becomes a strong competitor to ImageNet for several image and video downstream tasks.
* Honorable Mention: “The paper proposes a novel path to self-supervised image pre-training, by learning from continuous videos. The paper contributes both new types of data and a method to learn from novel data.“
C: Extending Transformers and Attention
* Yukang Chen (CUHK) et al: LongLoRA: Efficient Fine-tuning of Long-Context Large Language Models (ICLR Oral, Poster)
* We present LongLoRA, an efficient fine-tuning approach that extends the context sizes of pre-trained large language models (LLMs), with limited computation cost. LongLoRA extends Llama2 7B from 4k context to 100k, or Llama2 70B to 32k on a single 8x A100 machine. LongLoRA extends models' context while retaining their original architectures, and is compatible with most existing techniques, like Flash-Attention2.
* Bowen Peng (Nous Research) et al: YaRN: Efficient Context Window Extension of Large Language Models (Poster, Paper)
* Rotary Position Embeddings (RoPE) have been shown to effectively encode positional information in transformer-based language models. However, these models fail to generalize past the sequence length they were trained on. We present YaRN (Yet another RoPE extensioN method), a compute-efficient method to extend the context window of such models, requiring 10x less tokens and 2.5x less training steps than previous methods. Using YaRN, we show that LLaMA models can effectively utilize and extrapolate to context lengths much longer than their original pre-training would allow, while also surpassing previous the state-of-the-art at context window extension. In addition, we demonstrate that YaRN exhibits the capability to extrapolate beyond the limited context of a fine-tuning dataset. The models fine-tuned using YaRN has been made available and reproduced online up to 128k context length.
* Mentioned papers: Kaikoendev on TILs While Training SuperHOT, LongRoPE, Ring Attention, InfiniAttention, Textbooks are all you need and the Synthetic Data problem
* Suyu Ge et al: Model Tells You What to Discard: Adaptive KV Cache Compression for LLMs (aka FastGen. ICLR Oral, Poster, Paper)
* “We introduce adaptive KV cache compression, a plug-and-play method that reduces the memory footprint of generative inference for Large Language Models (LLMs). Different from the conventional KV cache that retains key and value vectors for all context tokens, we conduct targeted profiling to discern the intrinsic structure of attention modules. Based on the recognized structure, we then construct the KV cache in an adaptive manner: evicting long-range contexts on attention heads emphasizing local contexts, discarding non-special tokens on attention heads centered on special tokens, and only employing the standard KV cache for attention heads that broadly attend to all tokens. In our experiments across various asks, FastGen demonstrates substantial reduction on GPU memory consumption with negligible generation quality loss. ”
* 40% memory reduction for Llama 67b
* Honorable Mention: “The paper targets the critical KV cache compression problem with great impact on transformer based LLMs, reducing the memory with a simple idea that can be deployed without resource intensive fine-tuning or re-training. The approach is quite simple and yet is shown to be quite effective.”
* Guanhua Wang (DeepSpeed) et al, ZeRO++: Extremely Efficient Collective Communication for Giant Model Training (paper, poster, blogpost)
* Zero Redundancy Optimizer (ZeRO) has been used to train a wide range of large language models on massive GPUs clusters due to its ease of use, efficiency, and good scalability. However, when training on low-bandwidth clusters, or at scale which forces batch size per GPU to be small, ZeRO's effective throughput is limited because of high communication volume from gathering weights in forward pass, backward pass, and averaging gradients. This paper introduces three communication volume reduction techniques, which we collectively refer to as ZeRO++, targeting each of the communication collectives in ZeRO.
* Collectively, ZeRO++ reduces communication volume of ZeRO by 4x, enabling up to 2.16x better throughput at 384 GPU scale.
* Mentioned: FSDP + QLoRA
Poster Session Picks
We ran out of airtime to include these in the podcast, but we recorded interviews with some of these authors and could share audio on request.
* Summarization
* BooookScore: A systematic exploration of book-length summarization in the era of LLMs (ICLR Oral)
* Uncertainty
* Can LLMs Express Their Uncertainty? An Empirical Evaluation of Confidence Elicitation in LLMs
* MARS: Meaning-Aware Response Scoring for Uncertainty Estimation in Generative LLMs
* Language Model Cascades: Token-Level Uncertainty And Beyond
* Tabular Data
* CABINET: Content Relevance-based Noise Reduction for Table Question Answering
* Mixed-Type Tabular Data Synthesis with Score-based Diffusion in Latent Space
* Making Pre-trained Language Models Great on Tabular Prediction
* How Realistic Is Your Synthetic Data? Constraining Deep Generative Models for Tabular Data
* Watermarking (there were >24 papers on watermarking, both for and against!!)
* Paraphrasing evades detectors of ai-generated text, but retrieval is an effective defense
* Provable Robust Watermarking for AI-Generated Text
* Attacking LLM Watermarks by Exploiting Their Strengths
* Watermarks in the Sand: Impossibility of Strong Watermarking for Generative Models
* Is Watermarking LLM-Generated Code Robust?
* On the Reliability of Watermarks for Large Language Models
* Watermark Stealing in Large Language Models
* Misc
* Massively Scalable Inverse Reinforcement Learning in Google Maps
* Zipformer: A faster and better encoder for automatic speech recognition
D: State Space Models vs Transformers
* Sasha Rush’s State Space Models ICLR invited talk on workshop day
* Ido Amos (IBM) et al: Never Train from Scratch: Fair Comparison of Long-Sequence Models Requires Data-Driven Priors (ICLR Oral)
* Modeling long-range dependencies across sequences is a longstanding goal in machine learning and has led to architectures, such as state space models, that dramatically outperform Transformers on long sequences.
* However, these impressive empirical gains have been by and large demonstrated on benchmarks (e.g. Long Range Arena), where models are randomly initialized and trained to predict a target label from an input sequence. In this work, we show that random initialization leads to gross overestimation of the differences between architectures.
* In stark contrast to prior works, we find vanilla Transformers to match the performance of S4 on Long Range Arena when properly pretrained, and we improve the best reported results of SSMs on the PathX-256 task by 20 absolute points.
* Subsequently, we analyze the utility of previously-proposed structured parameterizations for SSMs and show they become mostly redundant in the presence of data-driven initialization obtained through pretraining. Our work shows that, when evaluating different architectures on supervised tasks, incorporation of data-driven priors via pretraining is essential for reliable performance estimation, and can be done efficiently.
* Outstanding Paper Award: “This paper dives deep into understanding the ability of recently proposed state-space models and transformer architectures to model long-term sequential dependencies. Surprisingly, the authors find that training transformer models from scratch leads to an under-estimation of their performance and demonstrates dramatic gains can be achieved with a pre-training and fine-tuning setup. The paper is exceptionally well executed and exemplary in its focus on simplicity and systematic insights.”
Get full access to Latent.Space at www.latent.space/subscribe