
In short
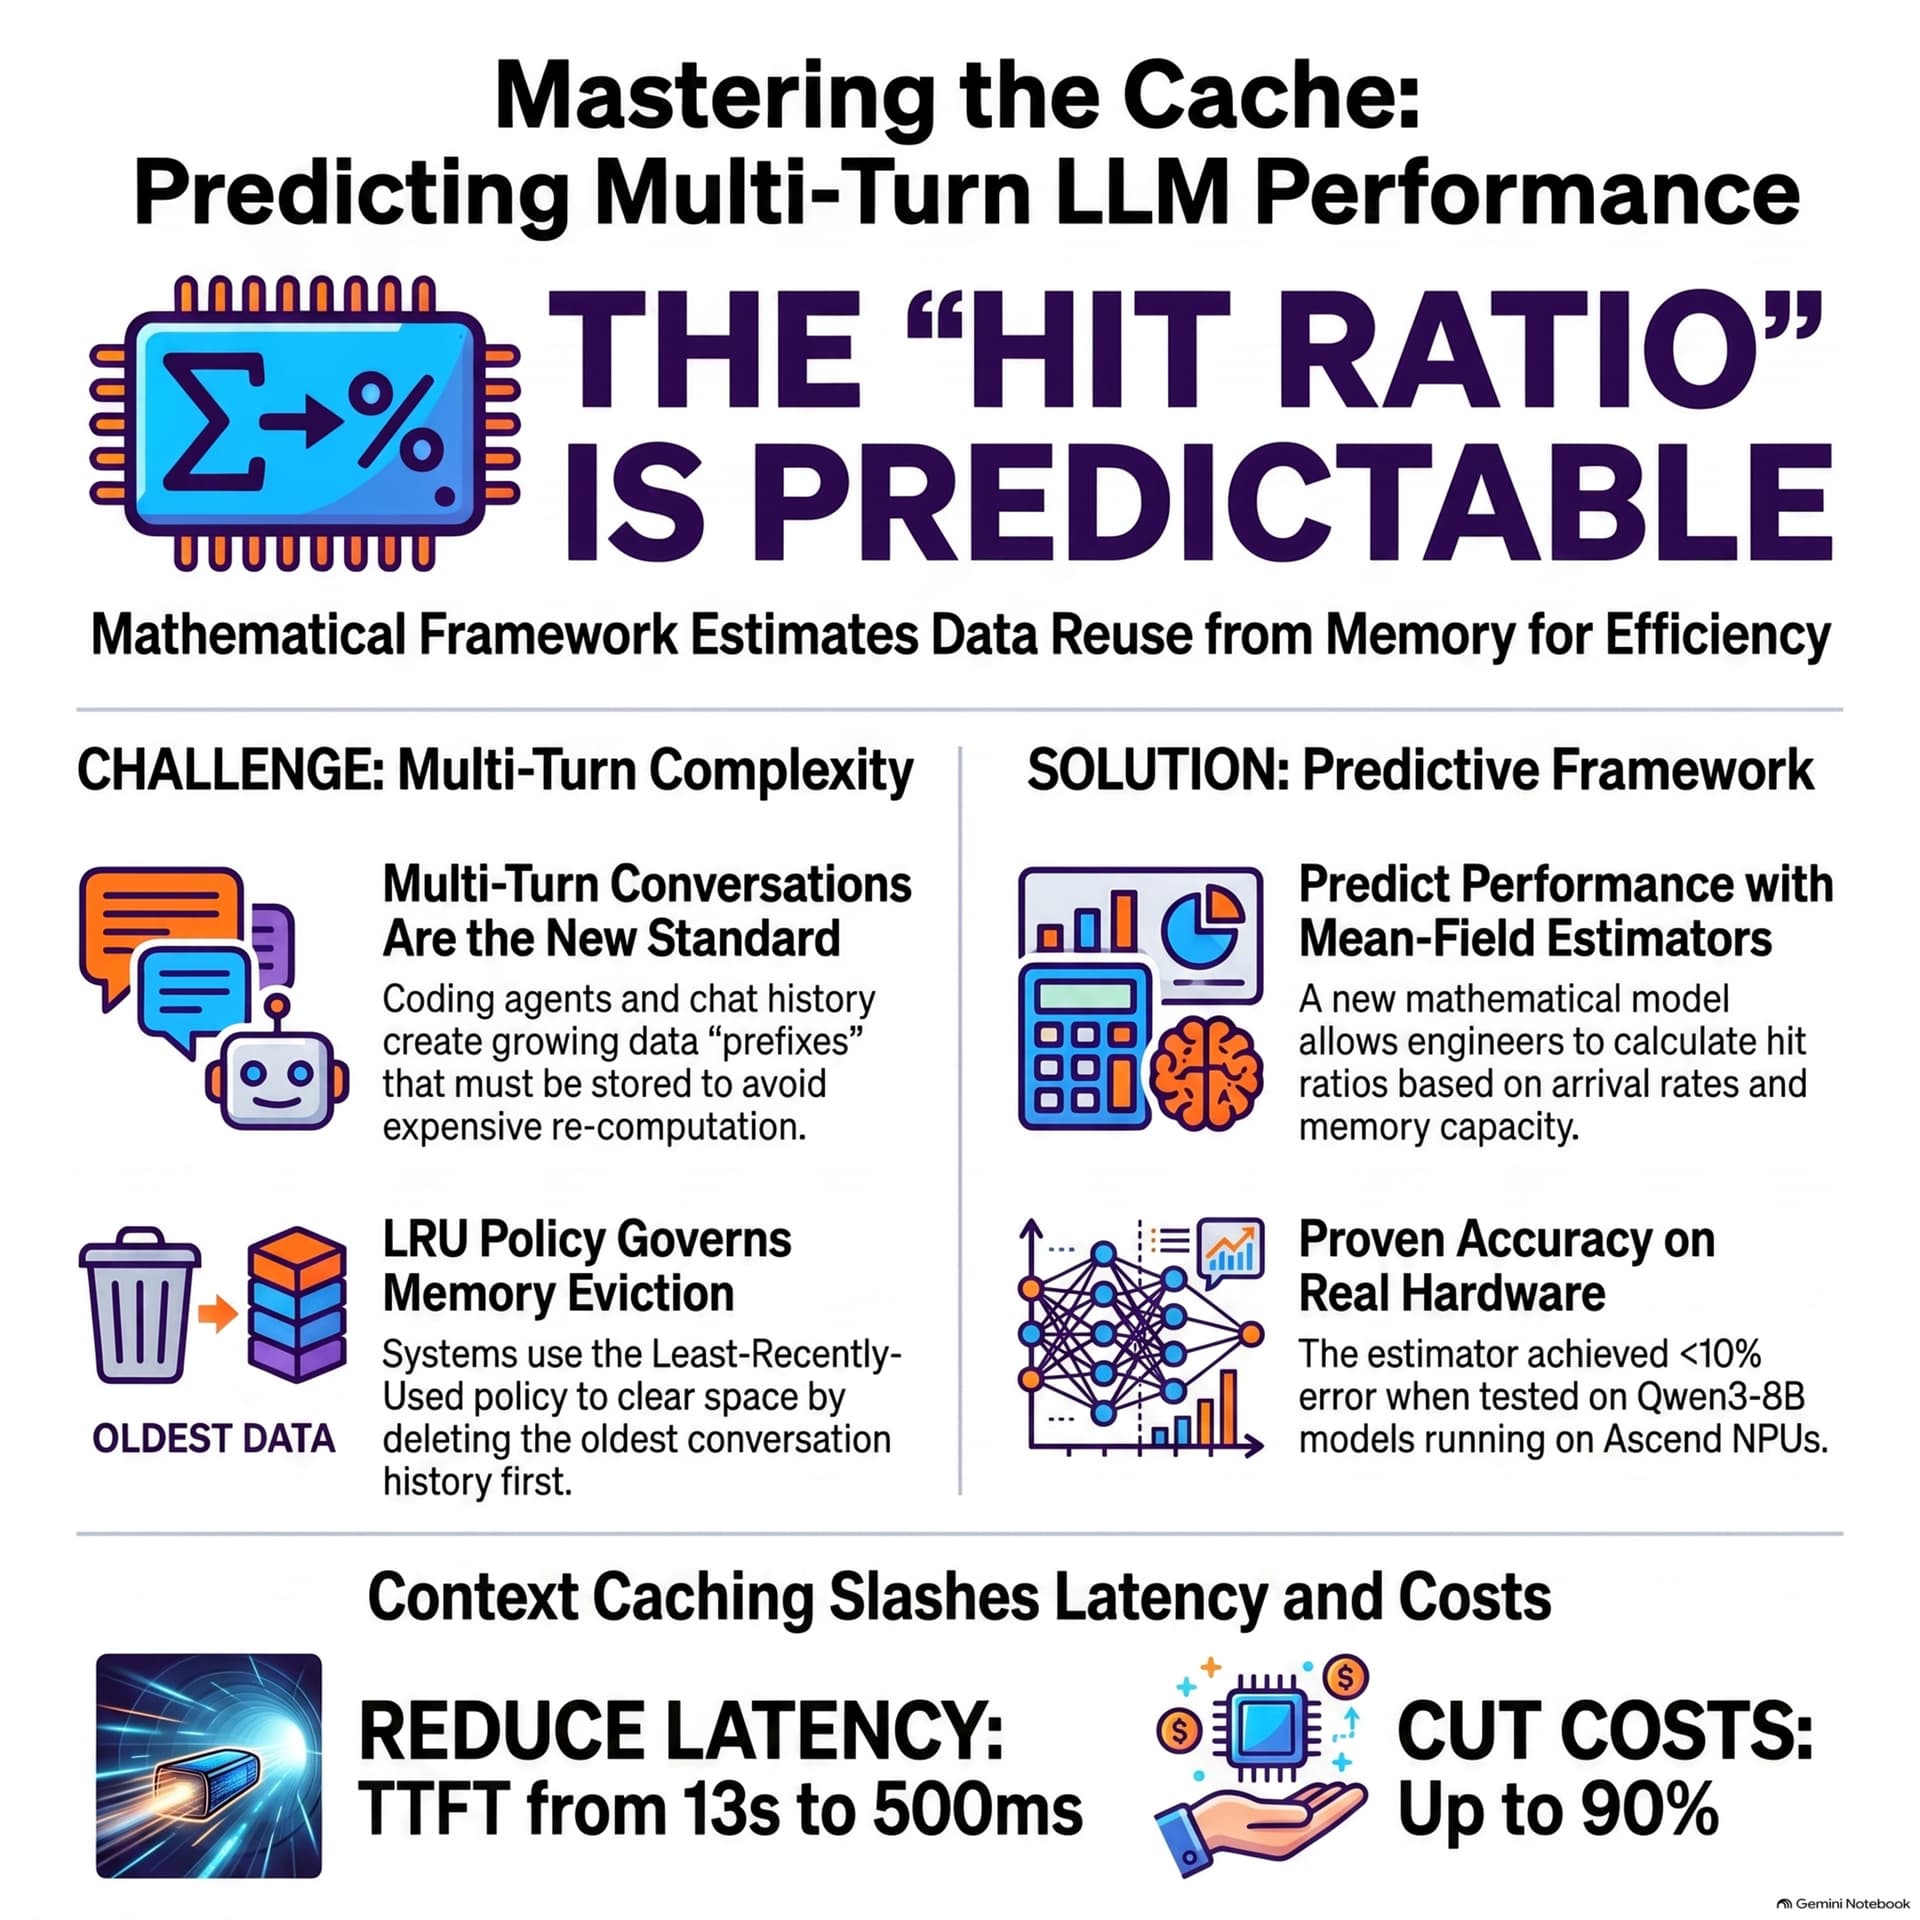
How multi-turn LLMs stay fast by caching KV (key/value) attention states in finite high-bandwidth memory (HBM), using least-recently-used (LRU) eviction, and predicting cache hit ratio via multi-turn conversation models with mean-field asymptotics.
Guest backgrounds
No guest identities are provided in the transcript; it’s a two-speaker discussion.
Key claims
Recomputing the “pre-fill” stage each turn is too expensive, so KV cache + context caching avoids it. Speed depends on forgetting at the right time (high hit ratio). Mean-field asymptotics can predict hit ratio by scaling arrival rates and memory capacity to infinity, then using characteristic time.
Notable examples
DeepSeek reports 128k-token caching dropping time-to-first-token from 13s to 500ms and reducing prompt cost to one-tenth. Hardware test uses Ascend 910-0b2 and 5,000 real multi-turn conversations; KV blocks are 128 tokens, creating an “unhashable tail block” that the practical estimator subtracts. Predicted vs actual hit ratio error is <0.02 (relative error <10%).
Written by AI. May contain mistakes. Listen to the episode to check what was said.
Chapters
Tap a time to open that second in VOThe Mechanics of Context Caching
0:45 to 2:18
Understand how context caching enhances AI conversation speed.
“So today for this deep dive, we are exploring that hidden engine.”
The Impact of High-Bandwidth Memory
2:18 to 4:35
Explore how high-bandwidth memory significantly reduces latency in AI responses.
“Because to respond to turn four of a conversation, the AI has to mathematically understand what happened in turns one, two, and three.”
Challenges of Managing Memory Space
4:35 to 6:22
Discover the limitations and eviction policies in AI memory management.
“But with the KV cache enabled, that latency dropped down to just 500 milliseconds.”
Understanding Hit Ratio Dynamics
6:22 to 8:14
Delve into the significance of hit ratio in AI systems and its complex calculations.
“To figure out who gets to keep their whiteboard space and whose context gets wiped to make room for new active conversations.”
Predicting Memory Usage Through Modeling
8:14 to 10:30
Learn about the multi-turn conversation model and mean-field asymptotics.
“I mean, we know exactly how many gigabytes of high bandwidth memory are on the server.”
Real-World Challenges in Theoretical Models
10:30 to 13:40
Examine the physical realities that complicate theoretical predictions in AI memory management.
“They formulated what they call a multi-turn conversation model, or MCM.”
The Problem of Unhashable Tail Blocks
13:40 to 14:03
Understand the implications of unhashable tail blocks in memory storage for AI.
“Real-world hardware inevitably introduces physical quirks that break pristine equations.”
Understanding Unhashable Tail Blocks
14:03 to 16:39
Learn about unhashable tail blocks in AI memory storage and their implications.
“In the specific system architecture analyzed in the study, each memory block holds exactly 128 tokens.”
Adapting Mathematical Estimators
16:39 to 18:03
Discover how researchers adapted estimators to account for real-world inefficiencies.
“They created what they called a practical MCM estimator.”
Testing Against Physical Hardware
18:03 to 19:24
Explore the rigorous tests conducted on enterprise-grade chips and their findings.
“But the best part is the data they fed into it.”
Show all 12 chapters
Implications of Accurate Memory Estimates
19:24 to 20:22
Understand the business implications of accurate memory estimation in AI systems.
“Right, because of the cost of these servers.”
Philosophical Reflections on Memory in AI
20:22 to 22:14
Contemplate the future of AI memory and the potential for intentional forgetting.
“We started today talking about that very relatable everyday experience, watching a chatbot instantly reply to a highly complex prompt and feeling like it's magic.”
Transcript
Automatic transcript. May contain errors.0:00Have you ever noticed how an AI chatbot instantly remembers a highly specific coding prompt you sent like 10 minutes ago? Yeah, it's actually pretty wild when you stop and think about it. Right. I mean, you drop in this massive block of code, you go get a coffee, come back, ask a seemingly random follow-up question, and boom, it replies in a fraction of a second. Exactly. You don't have to wait for it to reread everything from scratch. It feels like magic. But keeping that context alive for you, without crashing a multi-million dollar server farm, it actually requires this hidden high-stakes game of memory management.
0:35Oh, totally. A very brutal survival game, honestly. Yeah, you might not realize it, but the reality of how that happens behind the scenes involves some highly complex architecture. So today for this deep dive, we are exploring that hidden engine. It's a great topic. The modern logistical miracle happening inside those servers is, well, it's really something to behold. We are digging into the physical mechanics of the KV cache, a ruthless policy called least recently used, and the fascinating mathematical framework engineers use to predict AI memory efficiency. And what we're going to unpack today is actually a bit counterintuitive.
1:11Because the secret to AI speed doesn't just lie in holding on to massive amounts of information. Right. It's almost the opposite. Exactly. The real key to speed relies on the highly complex math of knowing exactly when to forget things. I love that. But before we can even begin to understand how AI manages its memory or why it intentionally forgets things, we first need to establish the massive computing burden of just holding a regular multi-turn conversation with you. Yeah, we have to set the stage here because the modern AI workload has shifted dramatically in a very short amount of time. It really has.
1:47I mean, think back just a couple of years. Right. Most interactions with the large language model were essentially single shot. Exactly. You asked a discrete question, it gave you an answer, and the interaction was effectively over. But today, the landscape is entirely different. If you look at coding agents on GitHub or complex analytical models from Anthropic, these are prolonged, evolving, multi-turn interactions. Users are basically treating AI like a collaborative partner now, holding conversations that go back and forth dozens of times. And computationally, that creates a massive bottleneck.
2:21Because to respond to turn four of a conversation, the AI has to mathematically understand what happened in turns one, two, and three. It has to carry all that context forward, right? Process it and figure out how the new prompt relates to everything you said previously. Exactly. The technical term for that process is the pre-fill stage. And I cannot stress enough how incredibly expensive it is from a computational standpoint. Because language models use attention mechanisms, right? Yes, which means they're constantly multiplying massive matrices to figure out the mathematical relationship between every single word you ever typed in that session.
2:58So if the system had to reread, retokenize, and recompute those complex math relationships for the entire history of the first three turns, just answer your question at turn four. The latency would be unbearable. You'd literally be waiting minutes for a single reply. Wow, which obviously ruins the whole experience. Right. So to avoid recomputing everything from scratch every single time you hit enter, system architects use a strategy called context caching. Context caching. OK, let's break that down because this is really the core of the speed we all take for granted. So instead of doing the math over and over, the system calculates the mathematical representations of your words exactly once.
3:39And these representations are the key value or KV caches. Precisely. The system then stores these KV caches directly in high-bandwidth memory, which is often abbreviated as HBM. HBM. And that's a specialized, incredibly fast physical memory located right next to the processing chips, right? Yeah, it's as physically close to the compute as possible. And looking at the research, the performance difference this caching makes is staggering. Like, DeepSeek published some data on this that completely blew my mind. Oh, their numbers are incredible. Right. they implemented context caching specifically for repetitive 128k token inputs.
4:14And for context, 128 ,000 tokens is roughly equivalent to feeding the AI a medium-sized novel. It's a huge amount of text. And without caching, the time-to-first token, which is that agonizing period where you just sit there staring at a blinking cursor, waiting for the AI to start typing. Yeah, without caching, it was a sluggish 13 seconds. 13 seconds. But with the KV cache enabled, that latency dropped down to just 500 milliseconds. Half a second to recall an entire novel's worth of context. Half a second. And here's the craziest part from this study. Because they aren't wasting all that intense GPU compute power re-reading the novel, they can charge literally one-tenth of the original price for a prompt that successfully hits the cache.
5:02It's a massive cost saving. Okay, let's try to visualize this. It's basically like having a dedicated whiteboard for a brainstorming session. I like that analogy. So instead of the AI erasing and rewriting the entire board from scratch every single time someone adds a new idea, the previous ideas just stay on the board. Right. And you only spend energy writing the newest idea at the very bottom. Exactly. That whiteboard analogy gets right to the heart of how high bandwidth memory functions here. As long as your conversation's history is written on that board, the AI can just glance at it, understand the context instantly, and dedicate all its processing power to generating the new addition.
5:38It totally bypasses the heavy lift of the pre-fill stage. It does. And this feels like a very big... But what happens when that whiteboard inevitably runs out of space? Ah, yeah. Because we are dealing with physical hardware, high bandwidth memory isn't some infinite digital cloud space. No, it's actual physical silicon soldered onto a server rack in a data center somewhere, and it is strictly finite. Not to mention, HPM is incredibly expensive to manufacture and power. Totally. That physical constraint is really the central drama of AI infrastructure right now. Because the servers are fielding millions of requests.
6:16Exactly. The memory is going to fill up. And when it does, the system has to start making ruthless decisions. It relies on an eviction policy, right? To figure out who gets to keep their whiteboard space and whose context gets wiped to make room for new active conversations. Yes. And the most widely adopted method across the industry for this is called the least recently used or LRU policy. Which works pretty much exactly how it sounds. It does. Basically, the system acts as a bouncer. It scans the high bandwidth memory, identifies the oldest, most inactive conversation histories that are taking up space.
6:50And it kicks them out. Yeah. It completely erases them to free up memory blocks for the new users who are actively typing. So if I'm using a coding chat bot and I walk away to take a phone call for an hour, the system eventually looks at my session, assumes I'm probably not coming back anytime soon, and wipes my context from the fast memory. Yep. And when you do finally return to that evicted session and type a new prompt, you're hit with a massive latency penalty. Because my KVE cache is just gone. Exactly. The system has to endure the heavy lift of recomputing your entire conversation history from scratch before it can answer you.
7:24Wow. Okay, so this dynamic brings us to the ultimate metric for system architects. They're entirely obsessed with maximizing what the research calls the hit ratio. Yes, the hit ratio. And the hit ratio being the fraction of KD caches that can be pulled directly from that fast, high bandwidth memory rather than having to be recalculated. Precisely. A high hit ratio means your data center is operating quickly and cheaply. You are serving users instantly. And a low hit ratio. A low hit ratio means your system is constantly dumping memories, recalculating old context, causing lag, and racking up massive computational costs.
8:03Wait, let's pause here for a second because I'm getting stuck on the basic math. Okay, what's tripping you up? Well, if you're an engineer managing this server, why is predicting this hit ratio so incredibly difficult? Ah, I see where you're going. I mean, we know exactly how many gigabytes of high bandwidth memory are on the server. We know how many users are logged in. Isn't this just basic division? Can't we just calculate the limit and figure out exactly when someone's memory gets pushed off the cliff? You would think so. But the reality of human behavior completely shatters that kind of simple arithmetic.
8:34Really? How so? Well, conversation histories are not uniform static objects. They grow asynchronously with every single turn a user takes. Okay, that makes sense. Plus, user arrival rates are entirely random. One person might send a rapid-fire prompt every 10 seconds, while another might stare at the screen analyzing a piece of code for five minutes before replying. Right, and the lengths of the conversations themselves vary wildly. Someone might log on for a quick two-turn question about a recipe, while another user is going back and forth with a coding agent 50 times to build an app. Exactly.
9:08So you have a fixed amount of physical space, but the items filling up that space are constantly growing at totally unpredictable rates. They're taking unpredictable pauses, and new items are arriving at random intervals. Yes. It creates a chaotic, highly complex, stochastic dynamic. Traditional queuing math completely struggles to pin this down. And traditional queuing math being the kind of math we normally use to model lines at a grocery store or basic internet traffic. Exactly. Why does traditional queuing math feel so badly here? Because in a traditional queue, items usually have a relatively fixed processing time and size.
9:44But here, the state space, the sheer number of possible variables involving conversation length, arrival time, and growth rate, it just explodes. So tracking the individual eviction time of every single conversation as they all compete simultaneously for the same finite space, it just becomes computationally intractable. It's way too complex to calculate on a user-by-user basis. Which means, historically, engineers couldn't easily predict how much expensive hardware they actually needed to buy to guarantee a smooth experience. They were essentially flying blind. They were guessing, yeah. But the mathematical modeling we are looking at today introduces a brilliant, large-scale framework designed to rescue the situation.
10:26They figured out a way to tame this chaos and actually predict the hit ratio. They did. They formulated what they call a multi-turn conversation model, or MCM. Okay. And to solve the chaos of tracking millions of random interactions, they applied a mathematical technique known as mean-field asymptotics. Mean-field asymptotics. Ah! Okay, that sounds incredibly intimidating. I feel like I need a PhD just to say it out loud. Ha, the terminology is definitely dense, but the underlying concept is actually incredibly elegant. Okay, lay it on me. It involves a mathematical thought experiment. The researchers asked, what happens if we take this chaotic server and scale everything, both the conversation arrival rate and the total memory capacity to infinity, proportionally?
11:08Okay, hold on. Infinity. We just established that the core problem is that the physical server is strictly limited. How does pretending the server is infinitely large help solve a problem about finite space? That's the genius of it. It leverages the law of large numbers. In small, highly constrained systems, random fluctuations cause massive, unpredictable spikes. If a dozen users suddenly start sending huge pomps at the exact same millisecond, your memory usage graph becomes a jagged, chaotic line. But as you scale the system up toward infinity, those chaotic individual variations start to cancel each other out.
11:44The random behavior of individual conversations averages out into a stable, predictable flow. Ah, I see. So the math smooths the jagged line out. Precisely. In mathematical terms, the unpredictable memory usage stabilizes into a deterministic mean displacement curve. A deterministic mean displacement curve. Let's unpack that phrase. Deterministic means predictable, right? Yes. And mean displacement is essentially the average rate at which old memory gets shoved toward the eviction cliff by the incoming flow of new memory. That is spot on. You know, this reminds me of physics, specifically thermodynamics.
12:20Oh, that's a great comparison. Think about a pot of boiling water. If you try to track one single water molecule, it is literally impossible to predict its exact path and speed. It's bouncing around haotically, colliding with other molecules. Totally unpredictable on the micro level. Right. But if you zoom out and look at the entire pot, the macro scale, you can accurately predict the overall temperature, the pressure, and the flow of the water. Exactly. So by scaling to infinity, the mathematical modeling stops trying to track the individual molecules and instead measures the temperature of the entire pot.
12:53That thermodynamic visualization is perfect. By looking at the overall flow rather than the individual parts, this infinite scaling gives engineers a precise mathematical tool known as the characteristic time. The characteristic time. Yeah, it's a clean, predictable limit. It tells them exactly how long a generic conversation's memory will survive in the high bandwidth memory before it gets pushed out by the mean flow of new traffic. So using this mean field math, engineers finally have a clean, perfect equation to predict the hit ratio. They can finally calculate exactly when things will be forgotten.
13:29Well, they have a perfect theoretical equation. But as anyone who works in hardware knows, theoretical math is beautiful and pristine, and physical reality is always, always messy. It is. Real-world hardware inevitably introduces physical quirks that break pristine equations. The real world strikes again. Always. So what was the specific hardware quirk that threw a wrench into this beautiful mean field map? It comes down to how memory is physically stored in the silicon. In real AI servers, the KV caches aren't stored as one continuous fluid stream of data. The architecture chops the data up and stores it in fixed-size blocks.
14:06In the specific system architecture analyzed in the study, each memory block holds exactly 128 tokens. Okay, 128 tokens per block. That seems organized enough. It's like standardizing the size of your storage containers. It is organized, yeah, until you realize that natural human language doesn't fit perfectly into multiples of 128. Ooh, right. When you finish typing a prompt and hit enter, the very last block of your conversation turn is almost never perfectly full. You might only use 15 tokens in that final block, leaving the remaining 113 slots completely empty. Right, because I'm just typing normally.
14:42I'm not carefully counting my syllables to hit a magic multiple of 128 before sending my message. No one does that. And this mismatch creates what the research identifies as an unhashable tail block. Unhashable. Yeah. So in order for the AI to instantly recognize and pull a block of memory from the cache when you send your next message, that block needs a deterministic identifier. It needs a unique digital fingerprint, which is called a hash. This allows the system to do exact prefix matching, finding your specific history instantly. But because this final tail block is only partially full, the system cannot finalize its hash.
15:19Hmm. Let's use an analogy here to make sure we're visualizing the mechanics correctly. Imagine you are packing for a massive cross-country move. Okay, I'm with you. You have a stack of uniform, thick-sized cardboard boxes. These are our 128 token blocks. You fill the first few boxes entirely with books, tape them shut, and put a barcode label on them. Right, and the barcode is the hash. Exactly. The movers can scan it and know exactly what's inside. But your final box only have three books in it. It's mostly empty because it's not fully packed. You can't tape it shut. You can't put the final barcode on it.
15:53It just sits there open on the floor. That is exactly it. That open box is your unhashable tail block. It's sitting there on the floor, physically taking up space in your living room, or in our case, the precious high bandwidth memory. And it is slowly moving toward the LRU eviction cliff, just like everything else. Yep. But it is completely useless for context caching. Because it doesn't have that barcode, that hash, the system can't find it when your conversation resumes. So this one, tiny ghost block, forces the system to actually recompute those specific tokens anyway, completely throwing off the efficiency that the theoretical math predicted.
16:27Exactly. The pristine math assumed every byte of memory was perfectly utilized. The ghost block wastes space and ruins the perfect theoretical hit ratio. So how do they fix it? So the researchers had to adapt. They created what they called a practical MCM estimator. A practical NCM estimator. How did that change the math? They took their pristine mathematical framework and deliberately injected this real-world messiness into the formula. Specifically, they adjusted their equations to subtract exactly one of these unhashable tail blocks per non-final turn of a conversation. Oh, wow. By mathematically removing that wasted space, the open-moving boxes from the theoretical capacity, they could accurately calculate the true reusable workload.
17:11Per se. That's incredibly clever. They didn't scrap the theory at all. They just programmed the physical annoyance right into the equation. Yeah, they adapted it. Which brings us to the ultimate test, because it's one thing to have a practical estimator on paper. It's another to see if it survives actual heavy duty physical hardware. Right. Testing against silicon is the crucible for any theoretical framework. Does the math hold up when the chips start getting hot? Exactly. And the setup they used for this test and the data is fascinating because they didn't just run a simulation on a laptop. They spun up an array of five, Ascend, 910-0b2, and Fuse.
17:48Neuroprocessing units, these are heavy-duty enterprise-grade chips designed specifically for massive AI workloads. Exactly. And they were running the Quinn 38B language model on these chips, which is a robust model capable of mimicking real-world heavy lifting. Right. But the best part is the data they fed into it. They didn't use sterile, predictable lab data. They used 5 ,000 actual, real-world, messy, multi-turn conversations pulled directly from the shared GPT data set. So they are blasting the system with totally chaotic human behavior. Yes. They dedicated one of those NPUs entirely to pre-filling the context.
18:25That specific NPU utilized exactly 40 gigabytes of high-bandwidth memory. Okay. And because they knew each individual KV block takes up 18 megabytes, that 40 gigabytes created a strict physical capacity of exactly 2 ,275 KV blocks. So just to summarize that, they have a strictly defined physical capacity, a real-world enterprise model, and 5 ,000 asynchronous, unpredictable human conversations hammering the server. Yes, that is the exact setup. And the results were astonishing. The theoretical estimator, the math that scaled everything to infinity and subtracted the unhashable ghost blocks, was remarkably accurate against the physical hardware.
19:05The accuracy really is the best part. When they compared the math's predicted hit ratio against the actual physical hit ratio on the server, the absolute error was under.02. An error margin of.02 is a massive victory for system engineers. It's insanely tight. The relative error remained below 10 % across the board. The math completely worked. It did. and think about the business implications of that.02 error margin. Right, because of the cost of these servers. Exactly. For the last few years, because this stochastic dynamic was so chaotic, system architects essentially had to guess how much memory they needed.
19:39And when you are guessing in the world of high-end data centers, you usually over-provision to be safe. Totally. You buy 30 or 40 % more memory than you actually need just in case traffic spikes. That costs tens of millions of dollars. or you under-provision and your users suffer terrible lag and abandon your product. But with this formula from the study, they don't have to guess or overspend anymore. No, they don't. With this practical mean field estimator, engineers can input their expected user behavior and the math will output exactly how many gigabytes of high-bandwidth memory they need to provision to guarantee a target hit ratio.
20:16They can guarantee instant performance for the user while saving millions of dollars in unnecessary hardware costs. It's a huge breakthrough. It's just wild to think about. We started today talking about that very relatable everyday experience, watching a chatbot instantly reply to a highly complex prompt and feeling like it's magic. And now we know the reality. Yeah. We've journeyed through the massive compute burden of the pre-fill stage, the physical limits of high bandwidth memory, the ruthless eviction logic of least recently used policies, and finally, the brilliant mean field asymptotic math that allows engineers to tame the chaos of human conversation.
20:56It really highlights how much invisible architecture exists right beneath the surface of the tools we use every single day. The speed isn't an accident. It's heavily orchestrated math. It truly is. So the next time your AI replies instantly to a massive coding problem, you can take a second to appreciate the hyper-optimized KV cache and the mean field math silently working behind the scenes to keep your history alive on that digital whiteboard. Definitely. But as we wrap up this deep dive, there is one final, somewhat philosophical concept I want you to mull over. Oh, what's the thought? Well, we've spent this entire time exploring how AI systems are mathematically optimizing exactly when to forget our past interactions.
21:36Right. Right now, that eviction is purely a way to save physical hardware space and reduce costs. But at what point does forgetting become a feature rather than just a hardware constraint? I see what you're getting at. Think about it. Human memory is imperfect. We constantly forget details. Our short-term memory fades, and only the truly vital context makes it into long-term storage. That's very true. Could future AI architectures intentionally mimic the way human memory fades, not just to save money on memory blocks, but to make their conversational patterns feel more organically lifelike? It's something to think about the next time you find yourself wishing a machine would remember a little bit more of what you said.
From the publisher
This paper introduces a Mean-Field Asymptotic framework designed to estimate the hit ratio in multi-turn large language model (LLM) serving systems. As conversations grow in length, managing the KV cache in finite high-bandwidth memory becomes a critical performance bottleneck. The authors model these dynamics using the least-recently-used (LRU) eviction policy to determine which conversation histories are retained or discarded. By analyzing the system as memory capacity and arrival rates scale toward infinity, they derive a closed-form limit to accurately predict cache reuse. The study further proposes a practical estimator that accounts for partially filled, unhashable memory blocks common in real-world applications. Finally, the researchers validate their theoretical findings through experiments with the Qwen3-8B model, demonstrating that their model reliably predicts system performance under varying workloads.


