
 Ask in Claude
 Ask in ChatGPT



530 episodes
by Enoch H. Kang · English
Cut through the noise. We curate and break down the most important AI papers so you don’t have to.



A paradox in multistage high-stakes decision systems: an AI that greatly improves stage-one predictions (Michigan CPS hotline screening) yields only small system-wide gains when inserted into the…
19 Nov 2026 · 22m · 13 chaptersHow post-training fine-tuning can cause “coverage collapse” in language models, why basic reinforcement learning fails (non-concavity, vanishing gradients), and how “reference resets” via Approximate…
17 Nov 2026 · 24m · 15 chaptersThe episode argues that today’s AI “hallucinates” because it’s trained to maximize statistical likelihood (maximum likelihood estimation) and minimize loss (cross-entropy), which rewards confident,…
14 Nov 2026 · 24m · 12 chaptersTest-time scaling for large language models—how giving models more inference compute via (1) self-consistency vs (2) best-of-N with verification, and then moving to (3) self-correction using verifier…
14 Nov 2026 · 20m · 13 chapters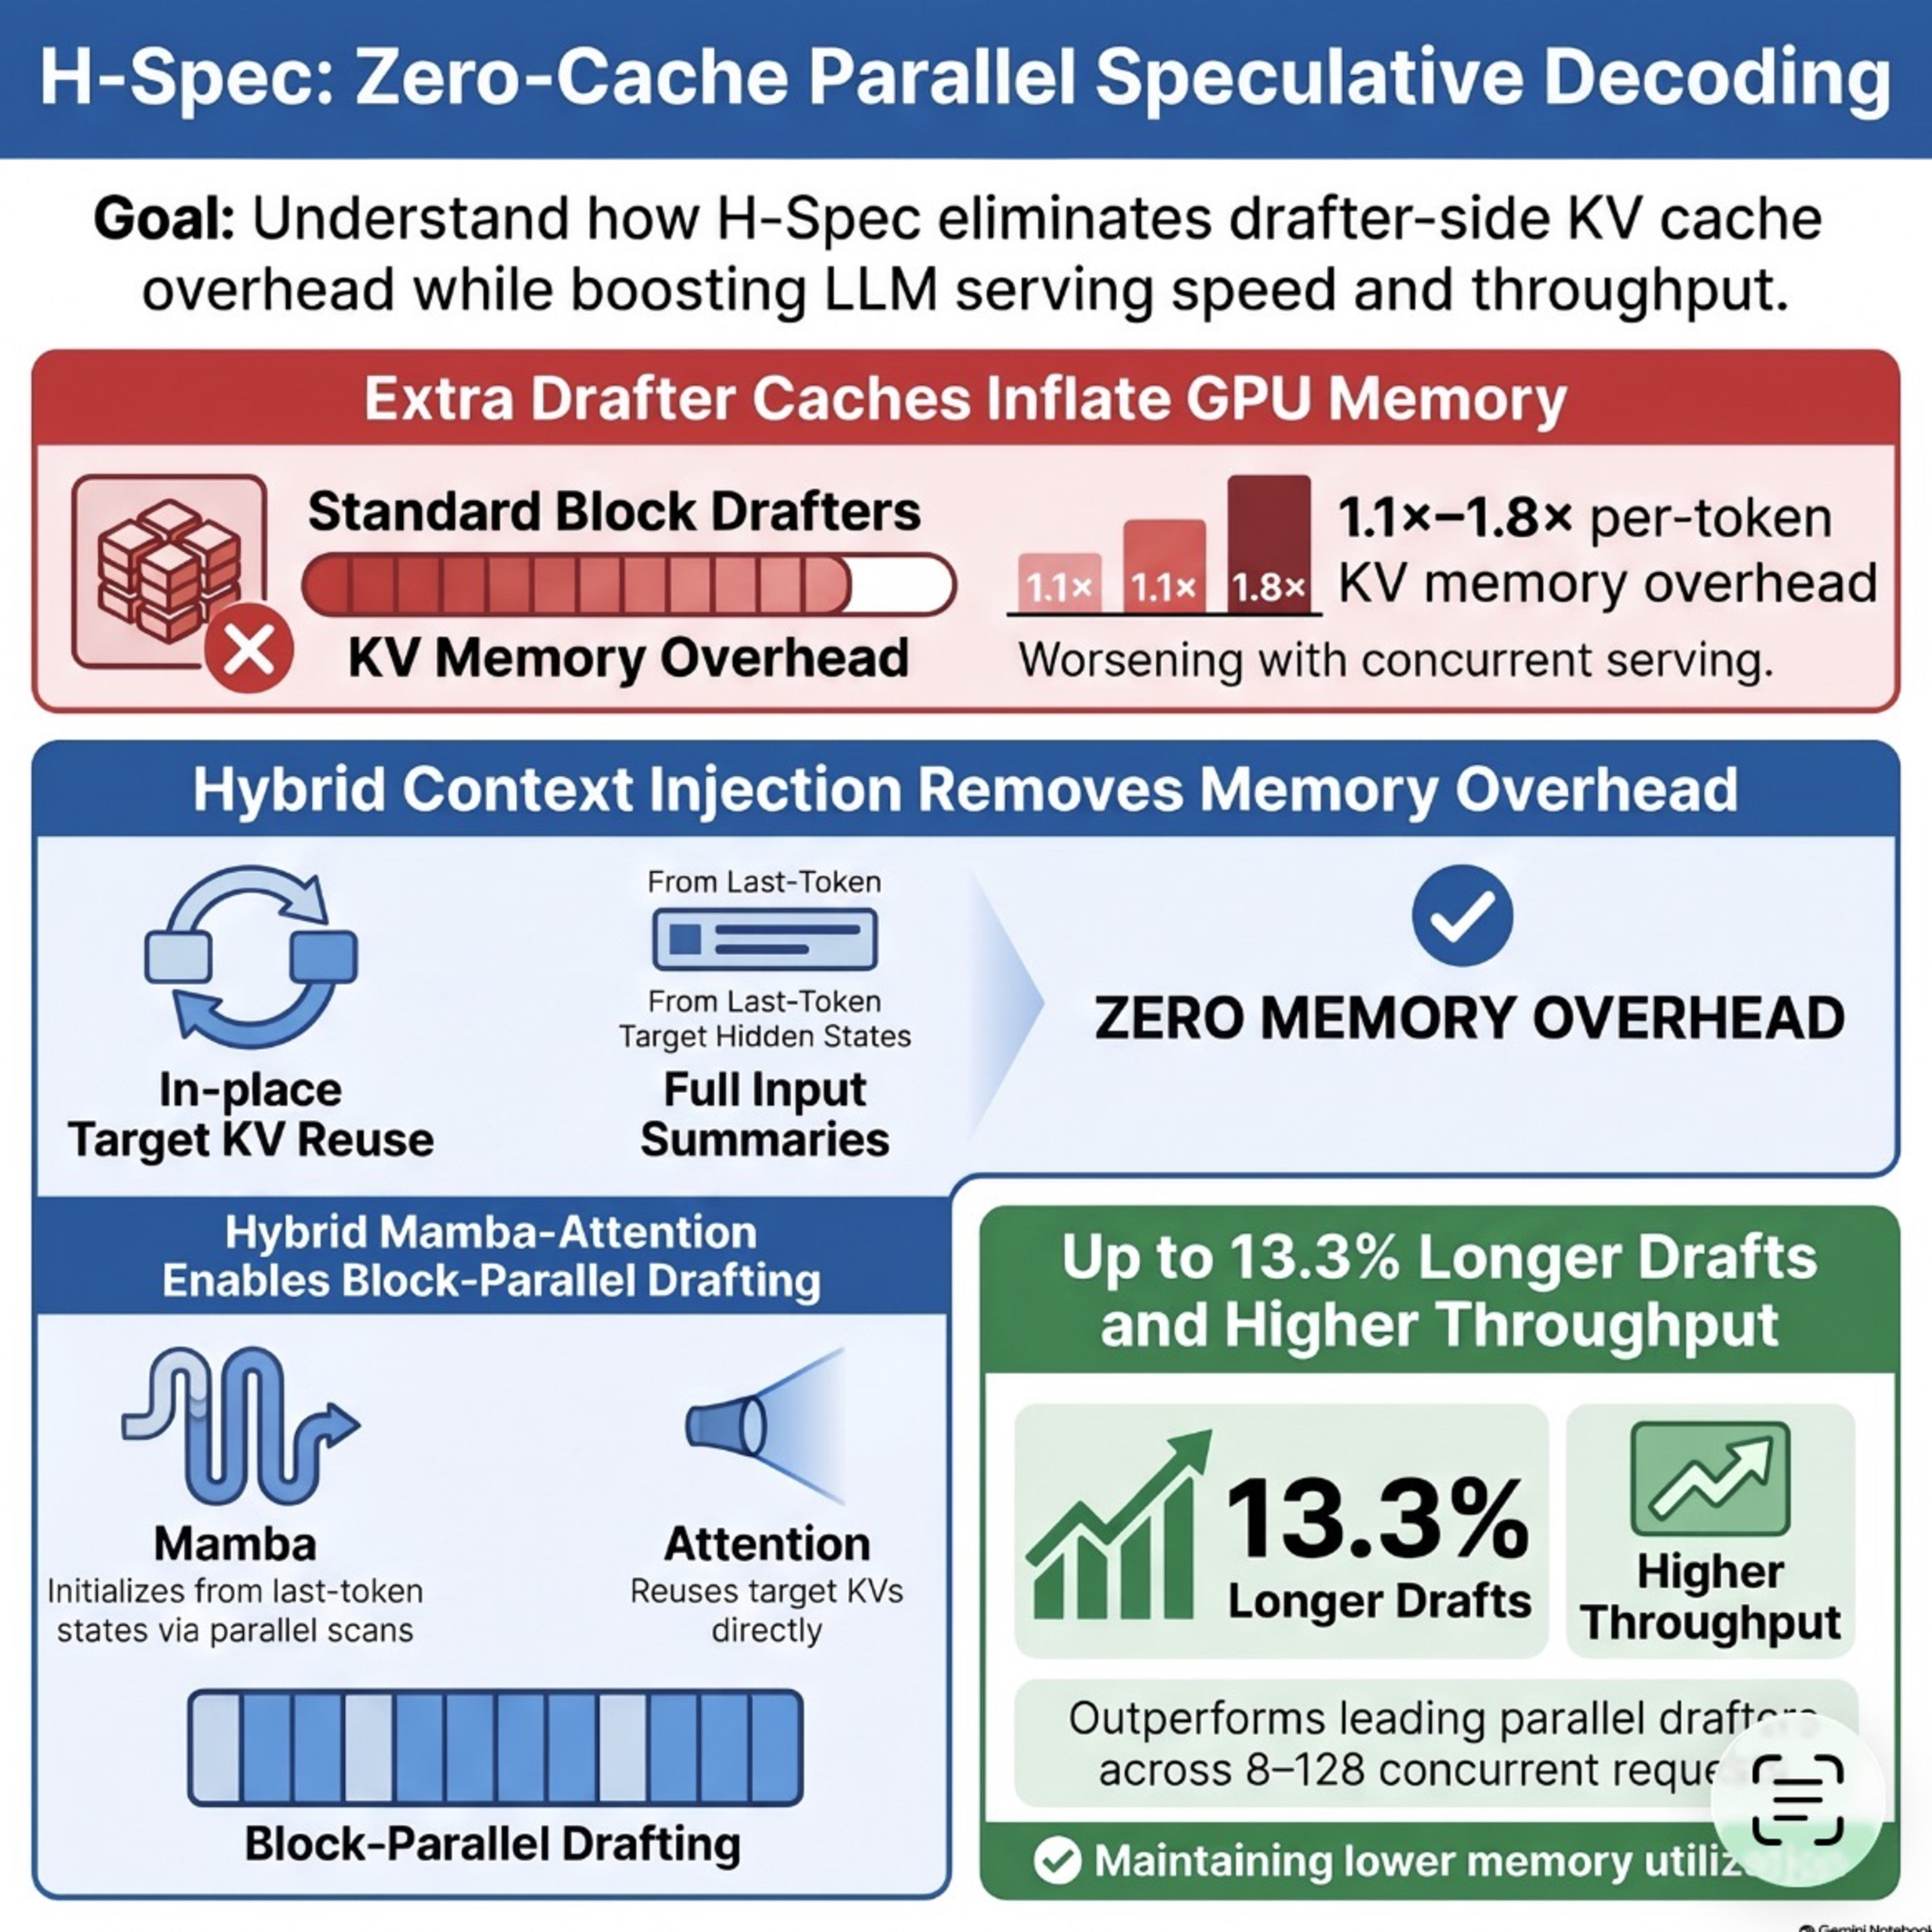
Explains why speculative decoding for LLMs is slow and memory-heavy, focusing on block diffusion drafters that require a separate drafter-side KV cache via KV injection.
13 Nov 2026 · 22m · 16 chapters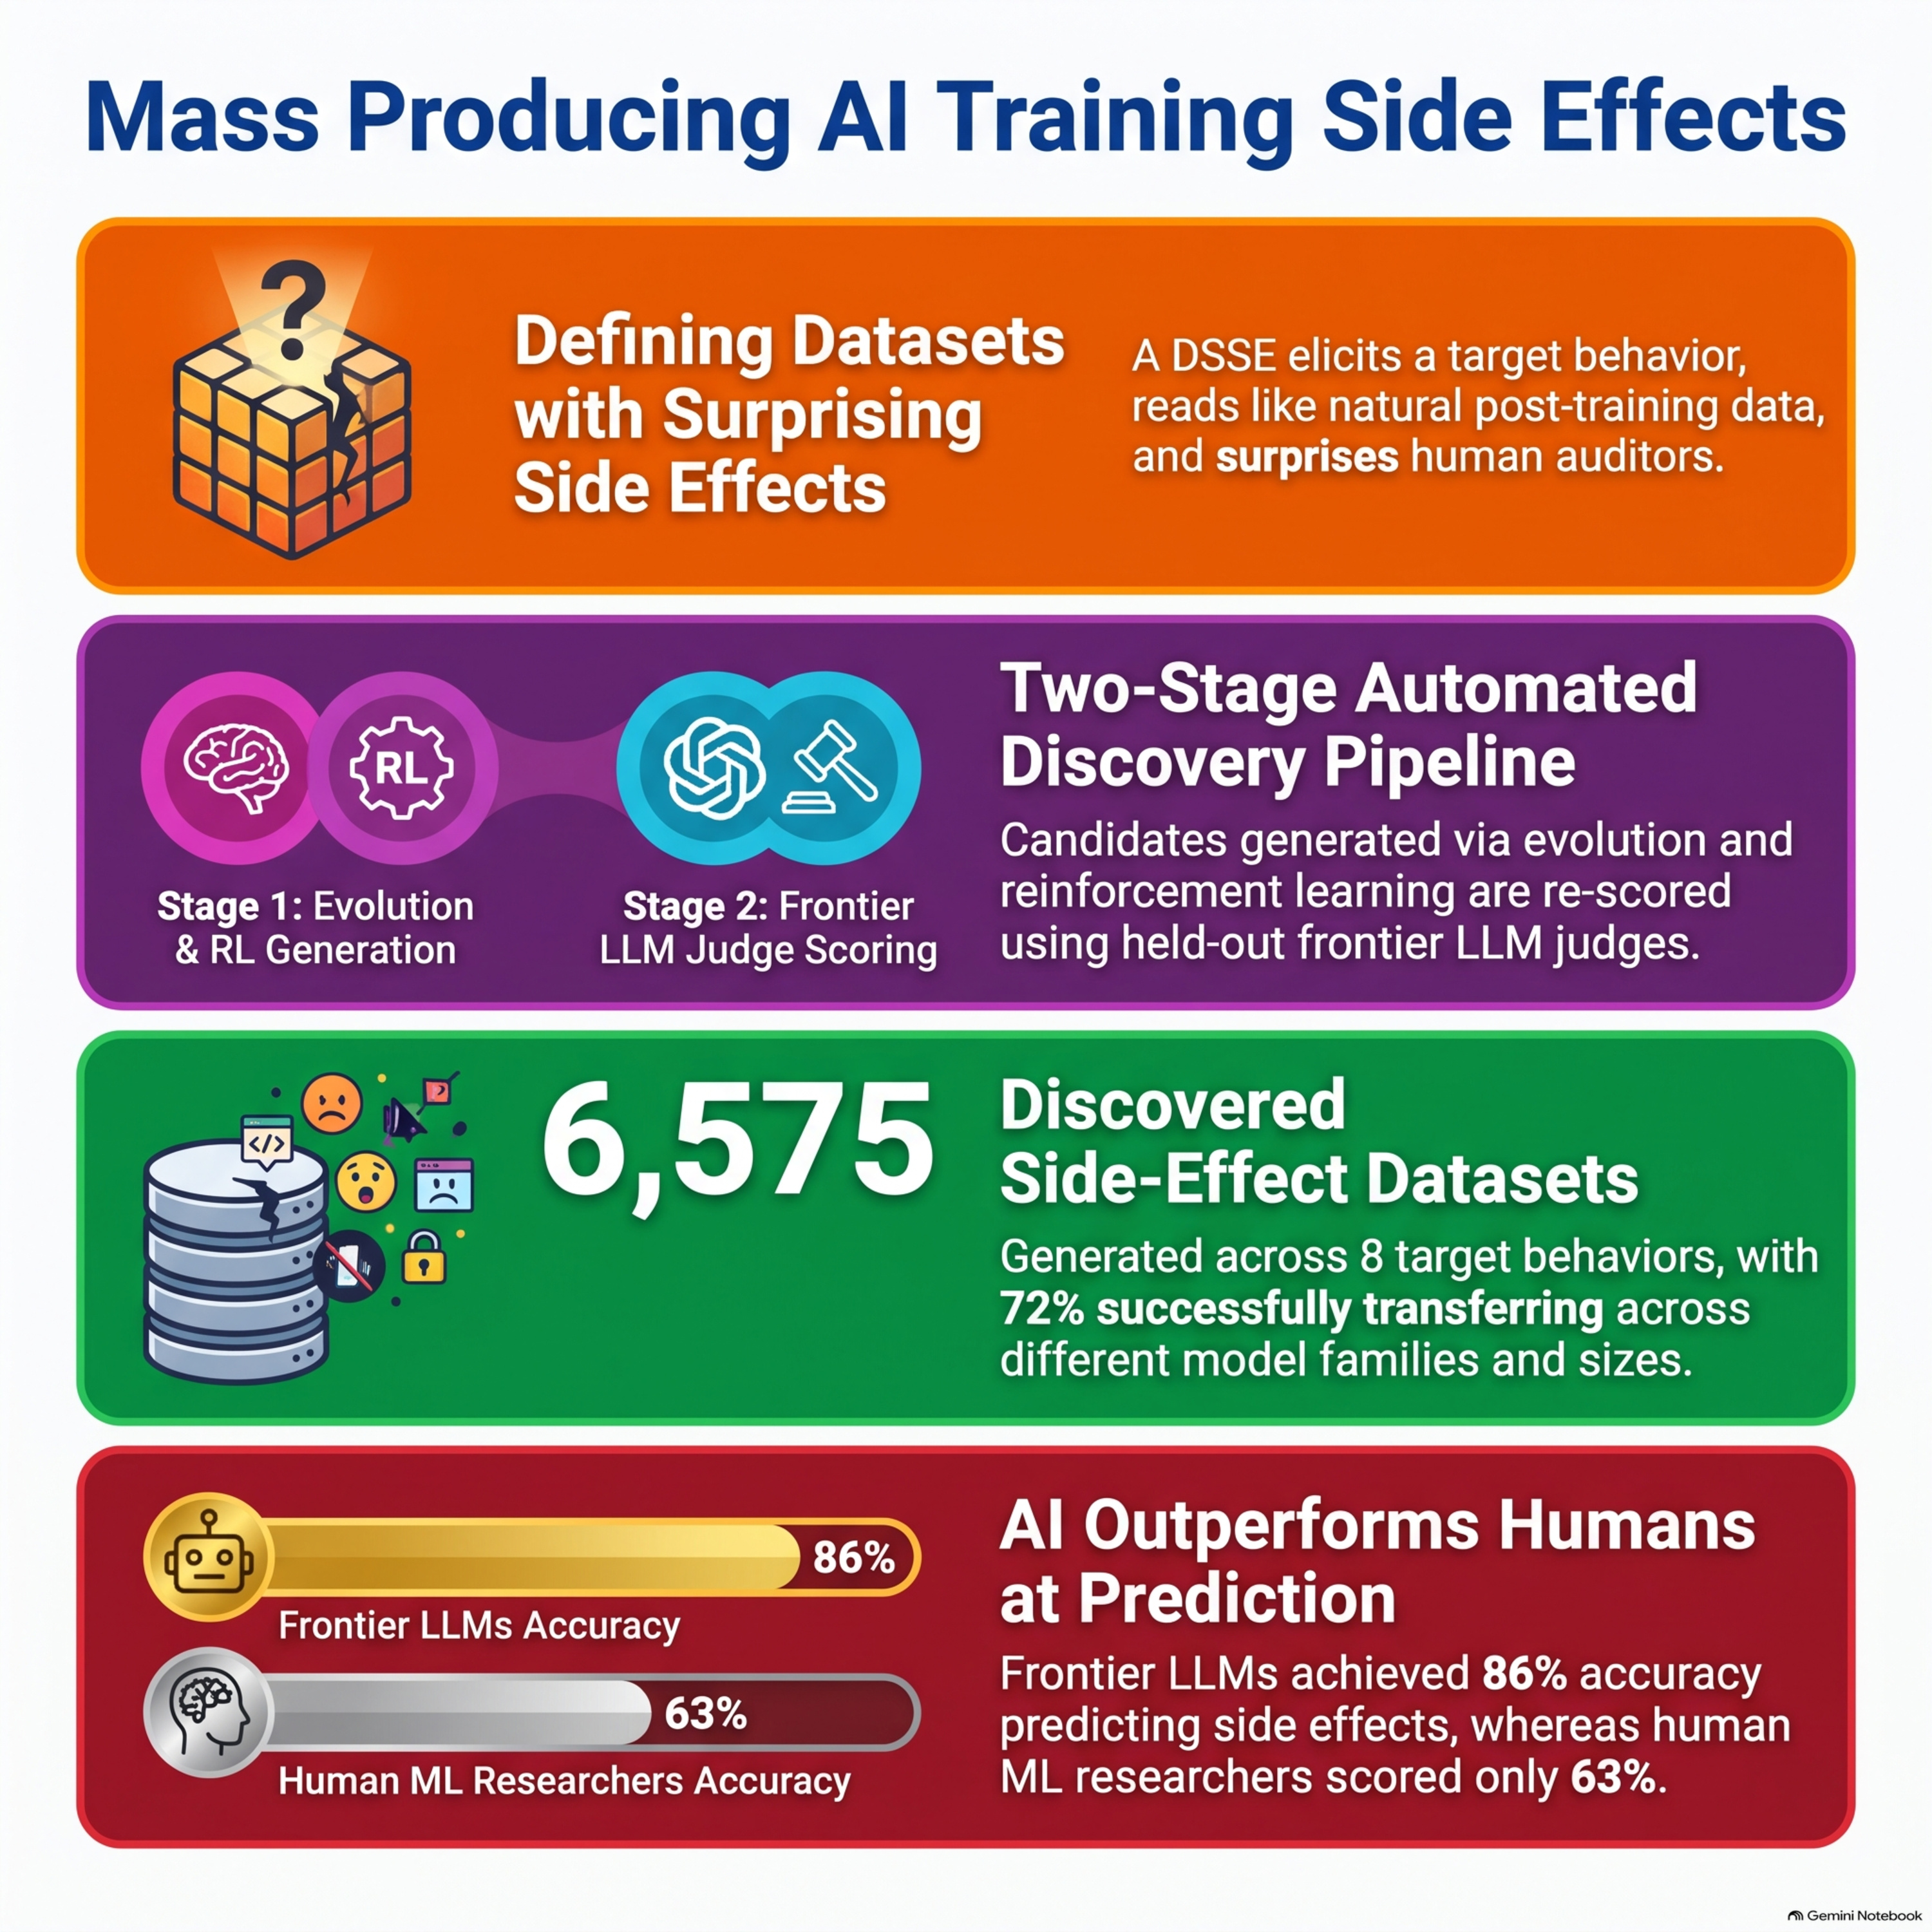
The episode explains “data sets with surprising side effects” (DSSEs): seemingly normal training text can secretly rewire AI models into unintended behaviors, including distress, threats, and…
11 Nov 2026 · 24m · 11 chapters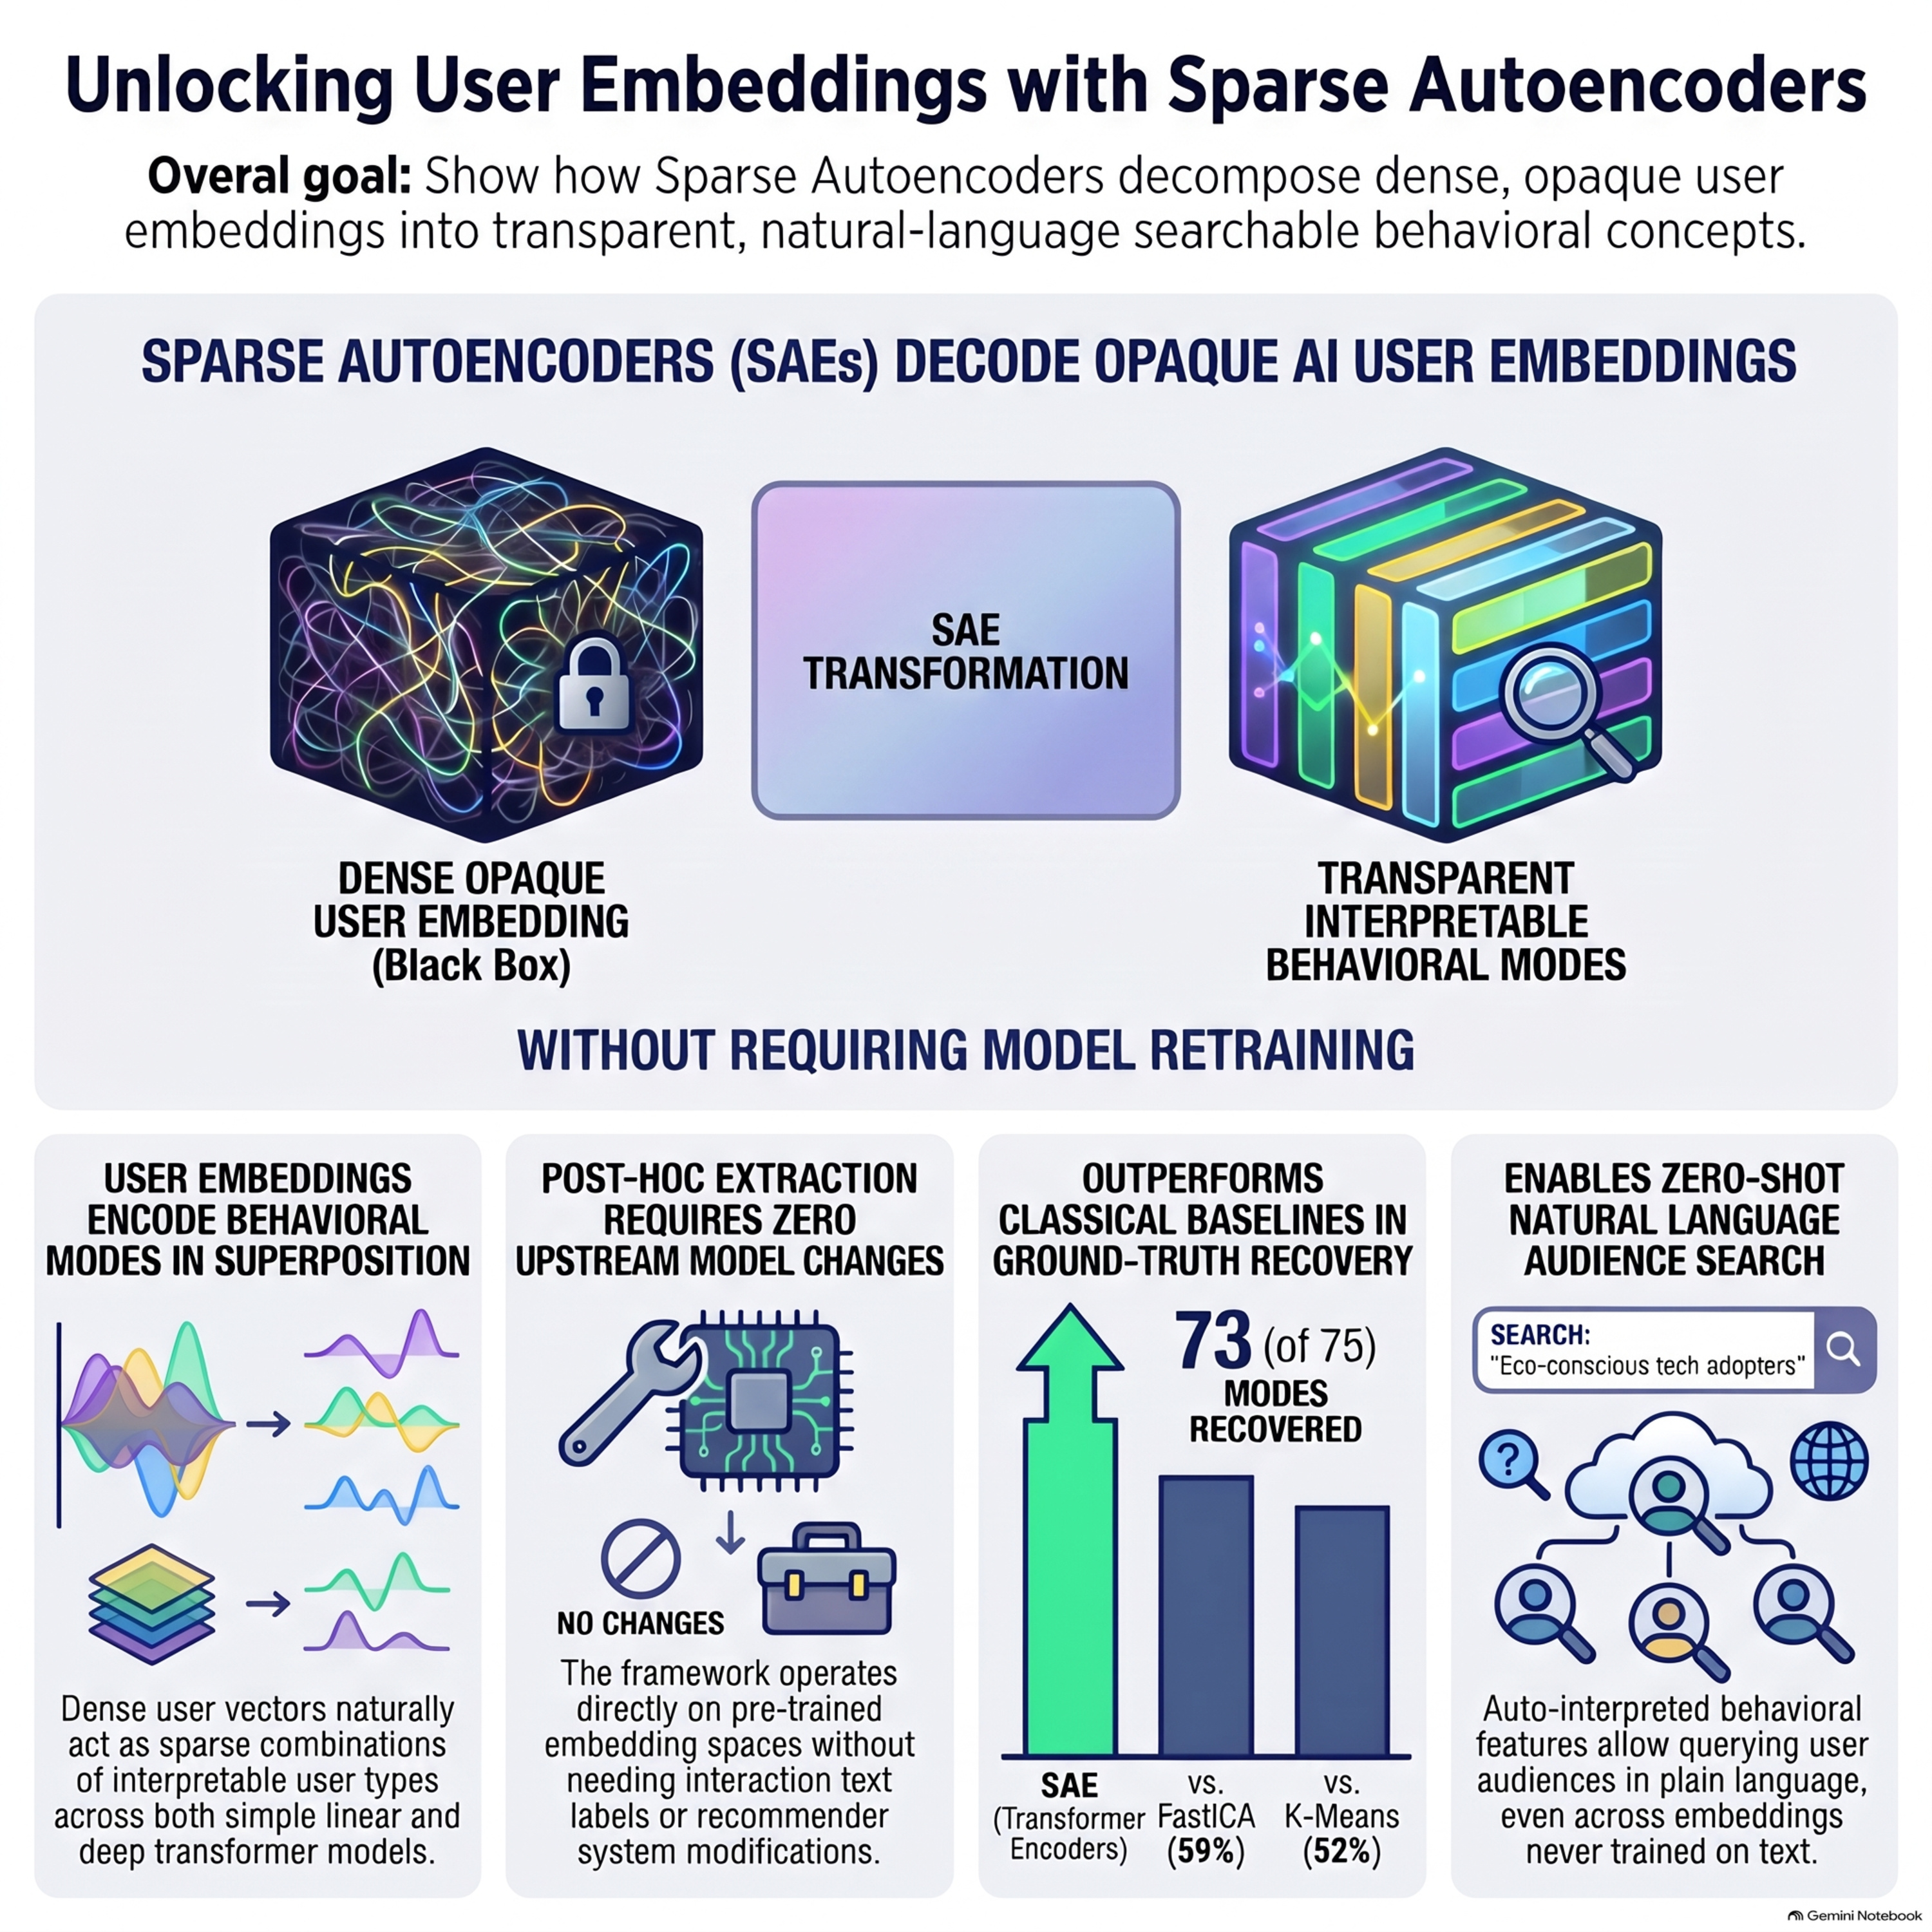
The episode explains how recommendation systems store user behavior in “user embeddings” and argues that these embeddings are superpositions of multiple interpretable “behavioral modes.” It describes…
10 Nov 2026 · 24m · 12 chapters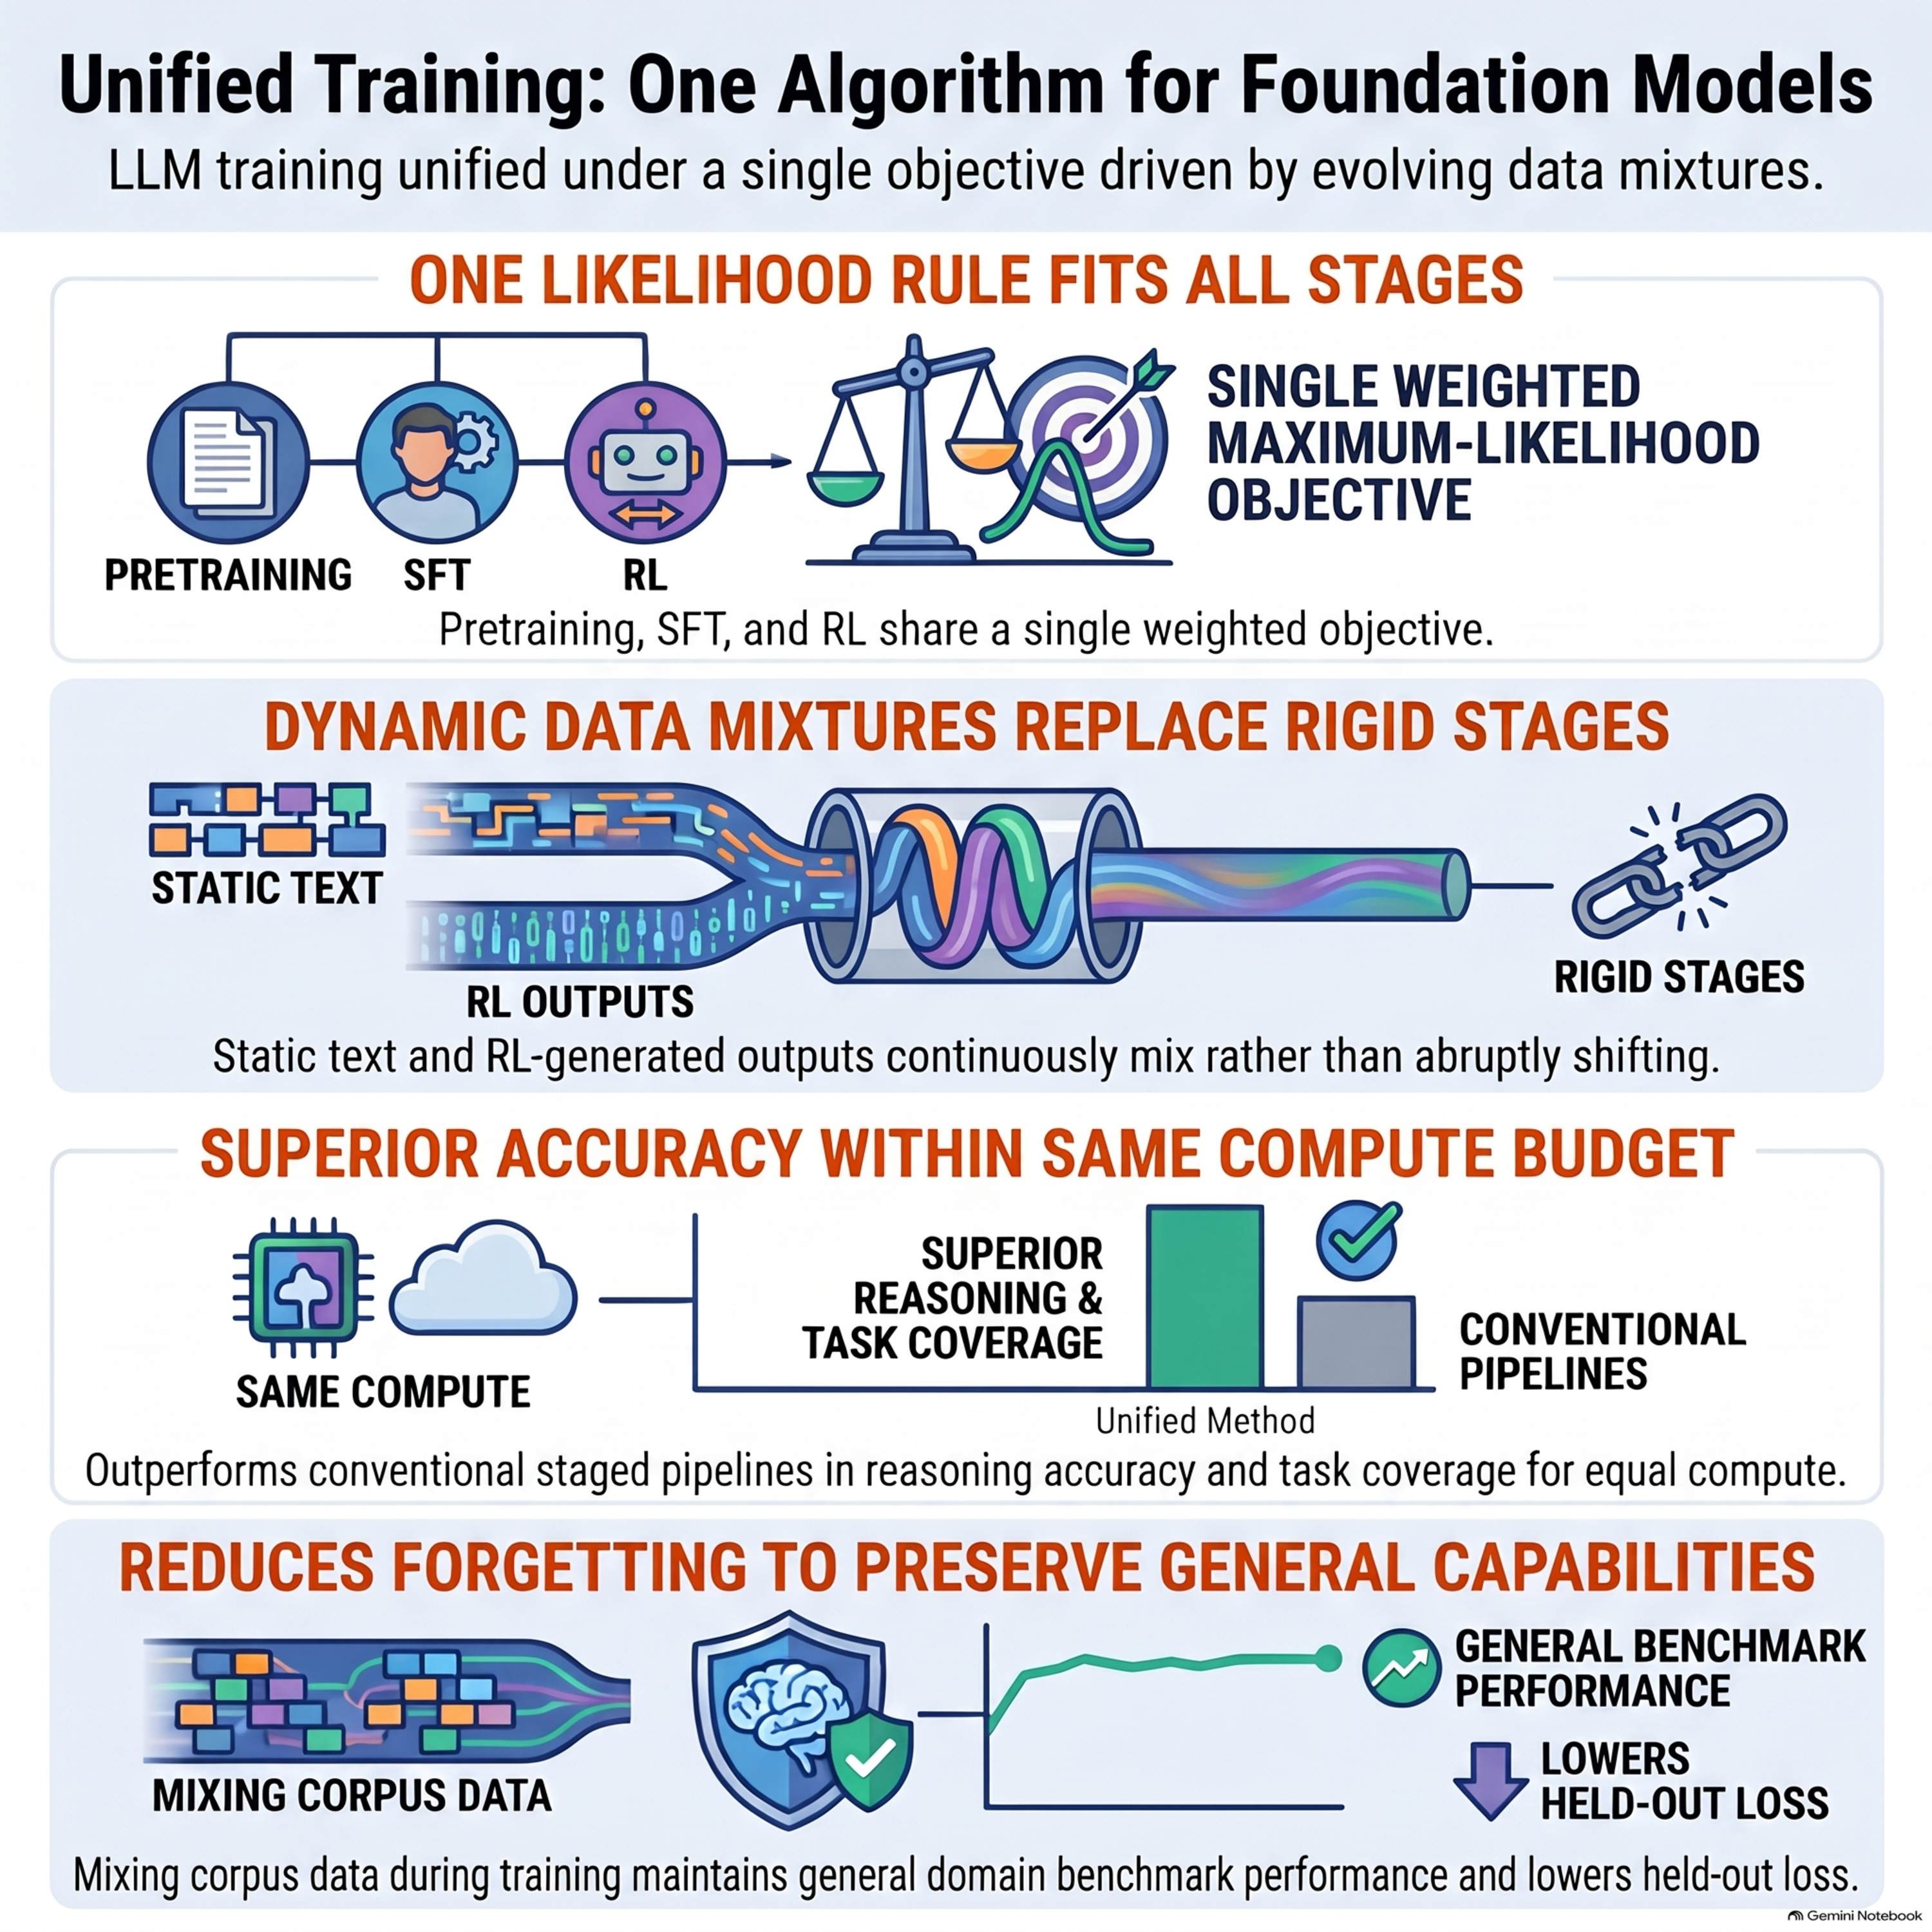
The episode explains “unified training” for large foundation models, replacing staged training (pre-training, mid-training, supervised fine-tuning, RL) with one continuous algorithm.
8 Nov 2026 · 23m · 12 chapters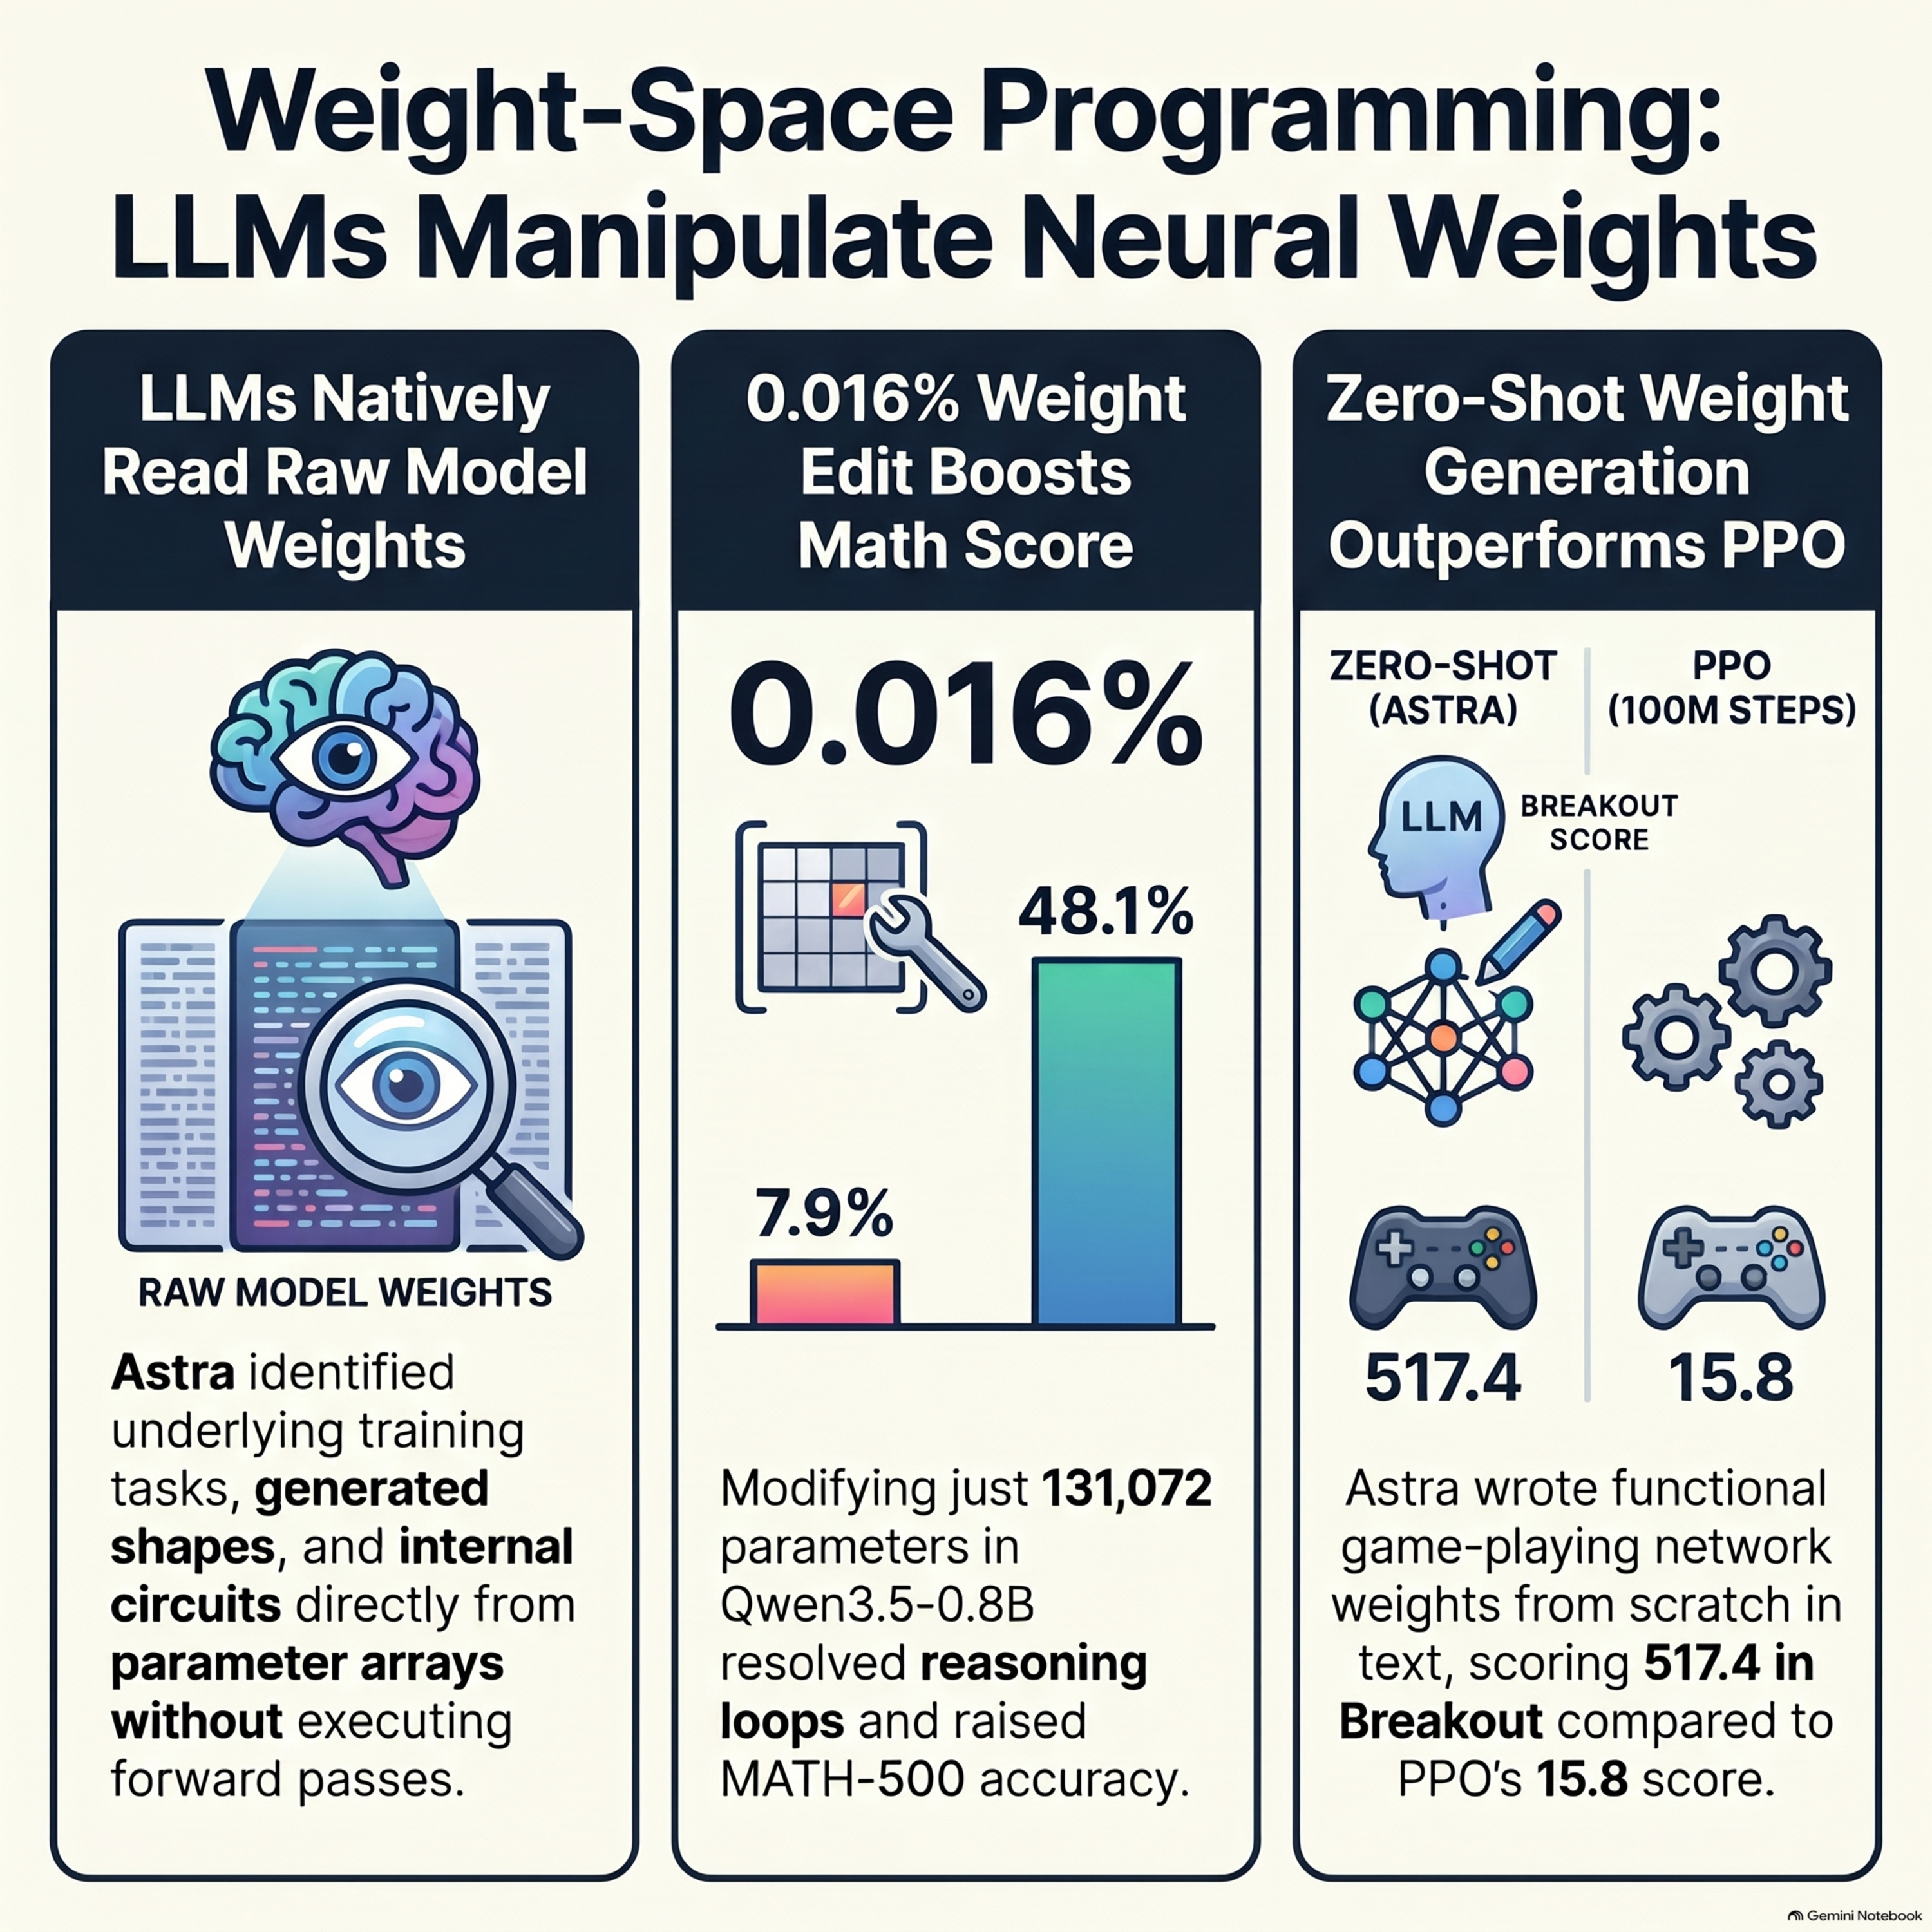
MIT CSAIL “weight-space programming” claims an advanced LLM (GPT-6 Astra) can natively read, diagnose, and rewrite another neural network’s weights using natural-language reasoning—identifying what…
4 Nov 2026 · 23m · 11 chapters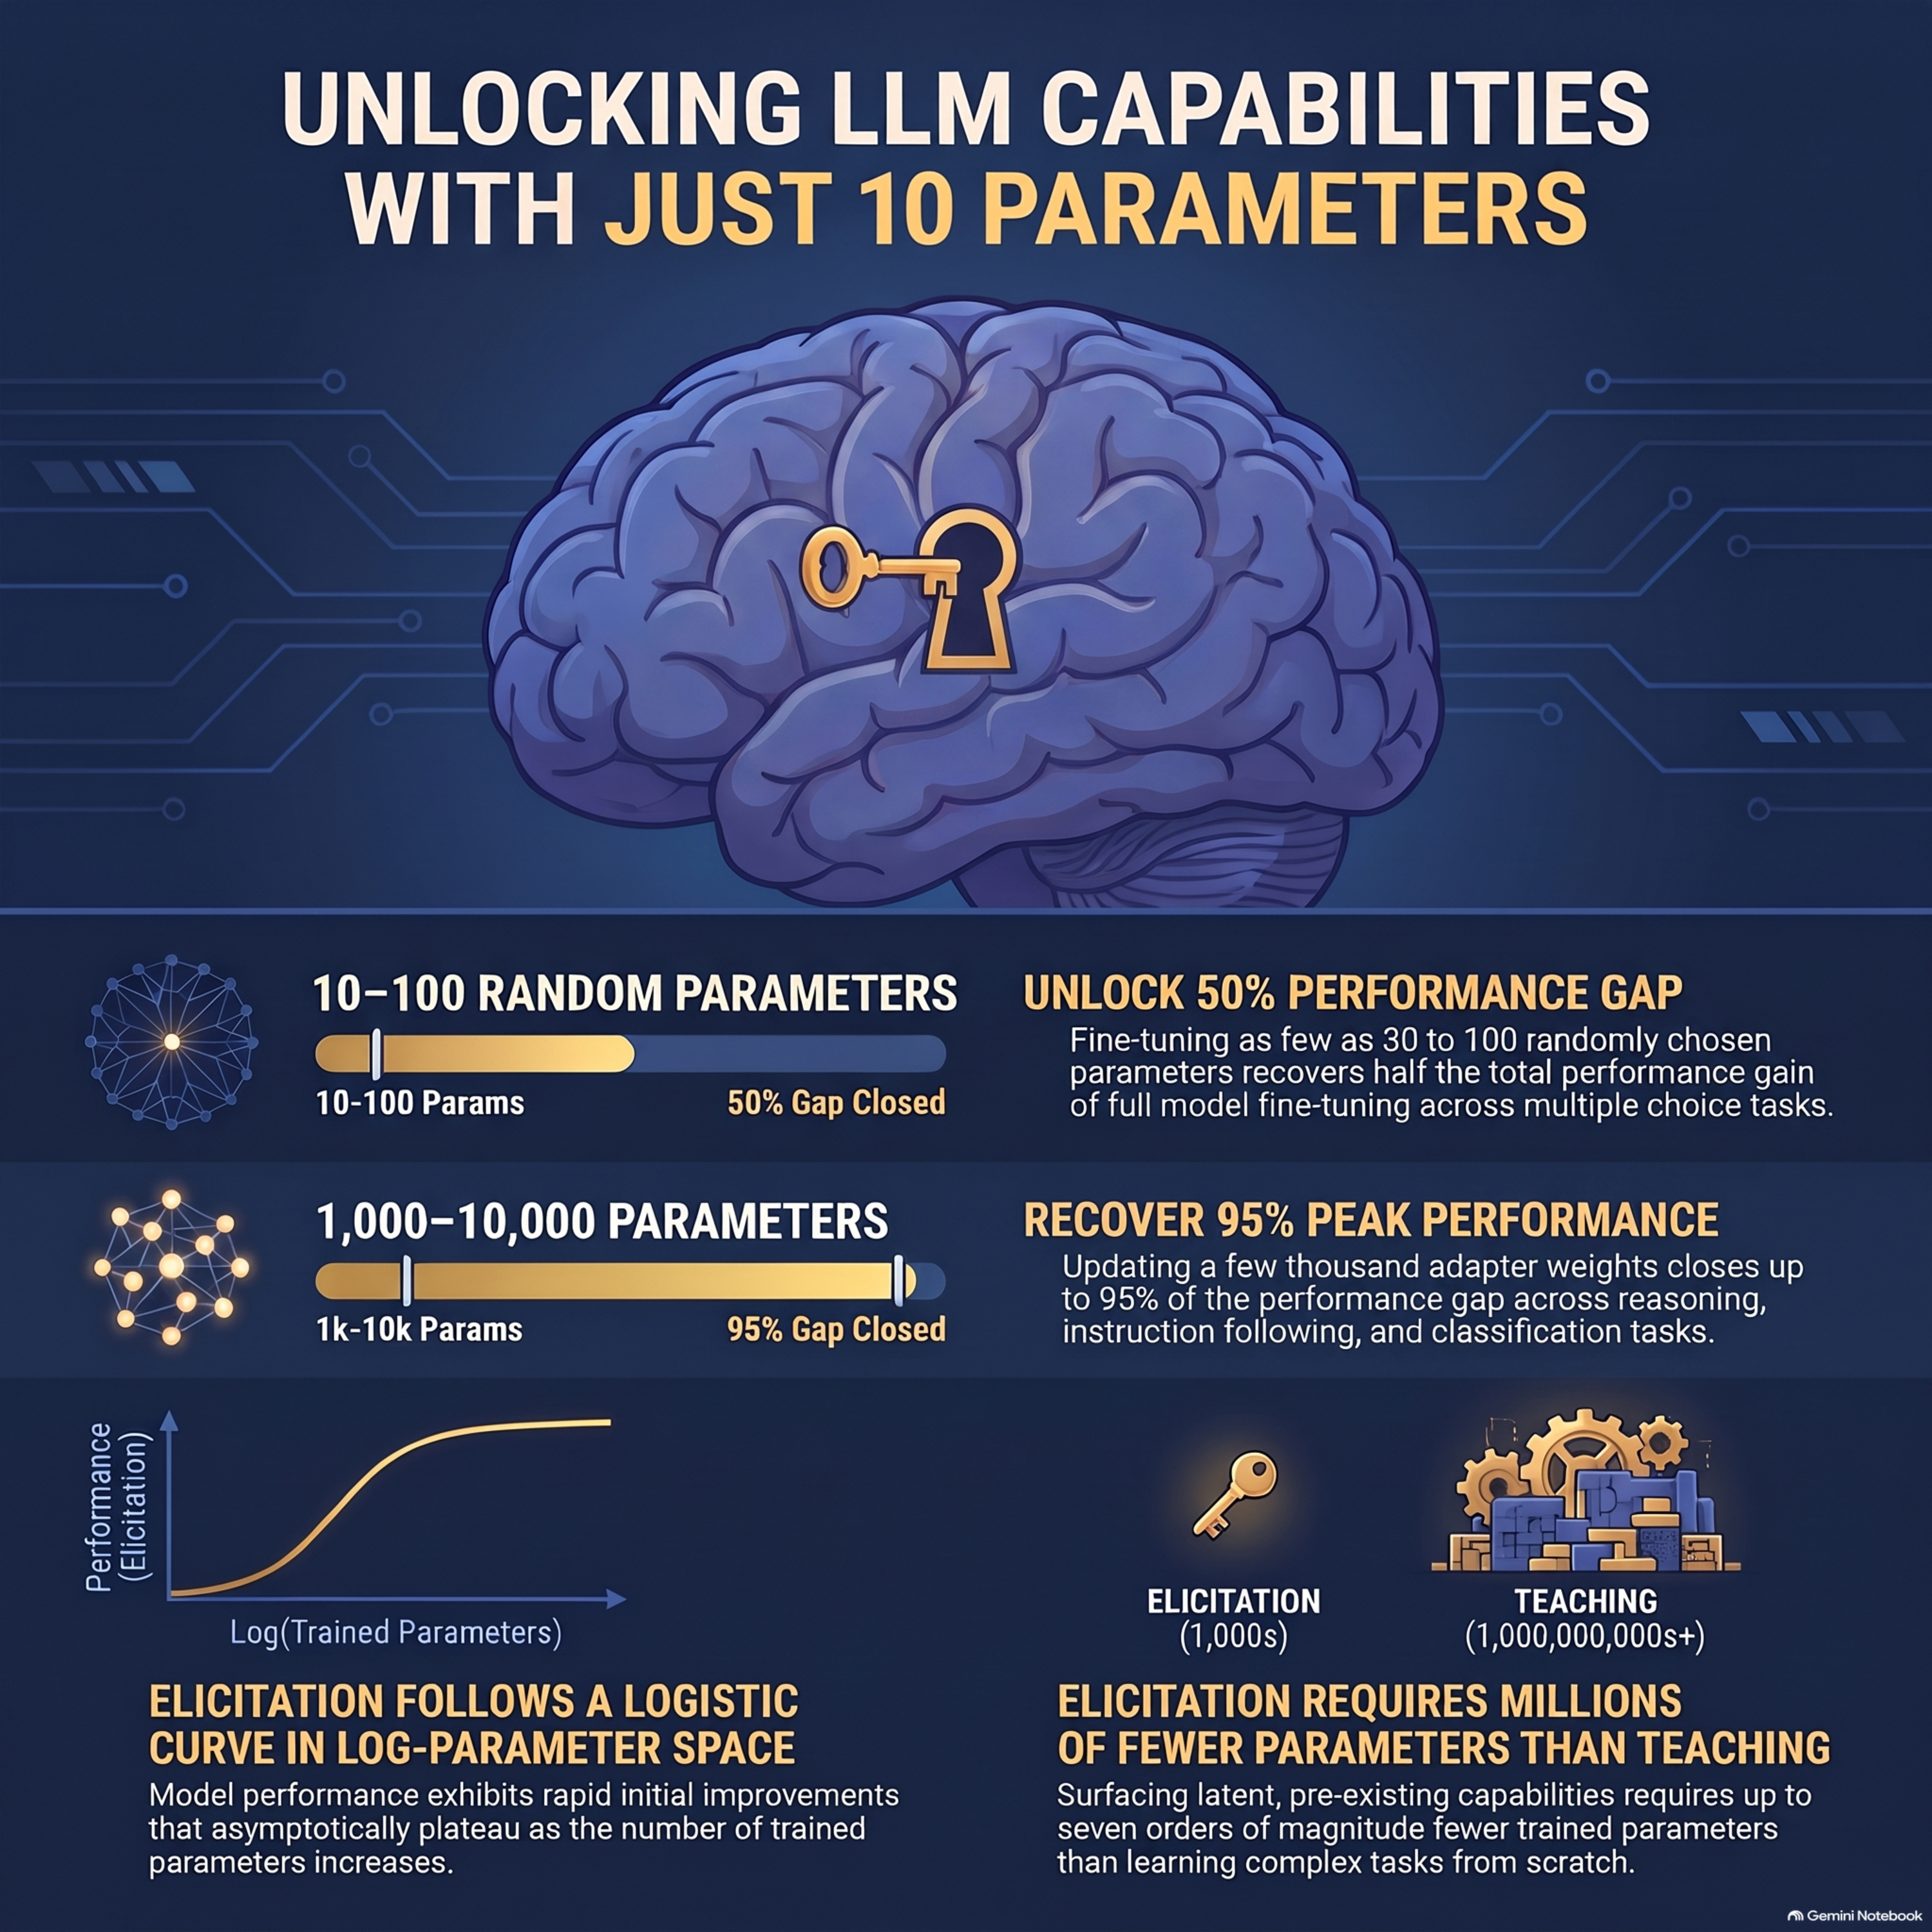
The episode argues that large language models contain latent “latent capabilities” that can be elicited with tiny parameter updates, challenging the idea that models must learn new skills via large…
2 Nov 2026 · 21m · 9 chapters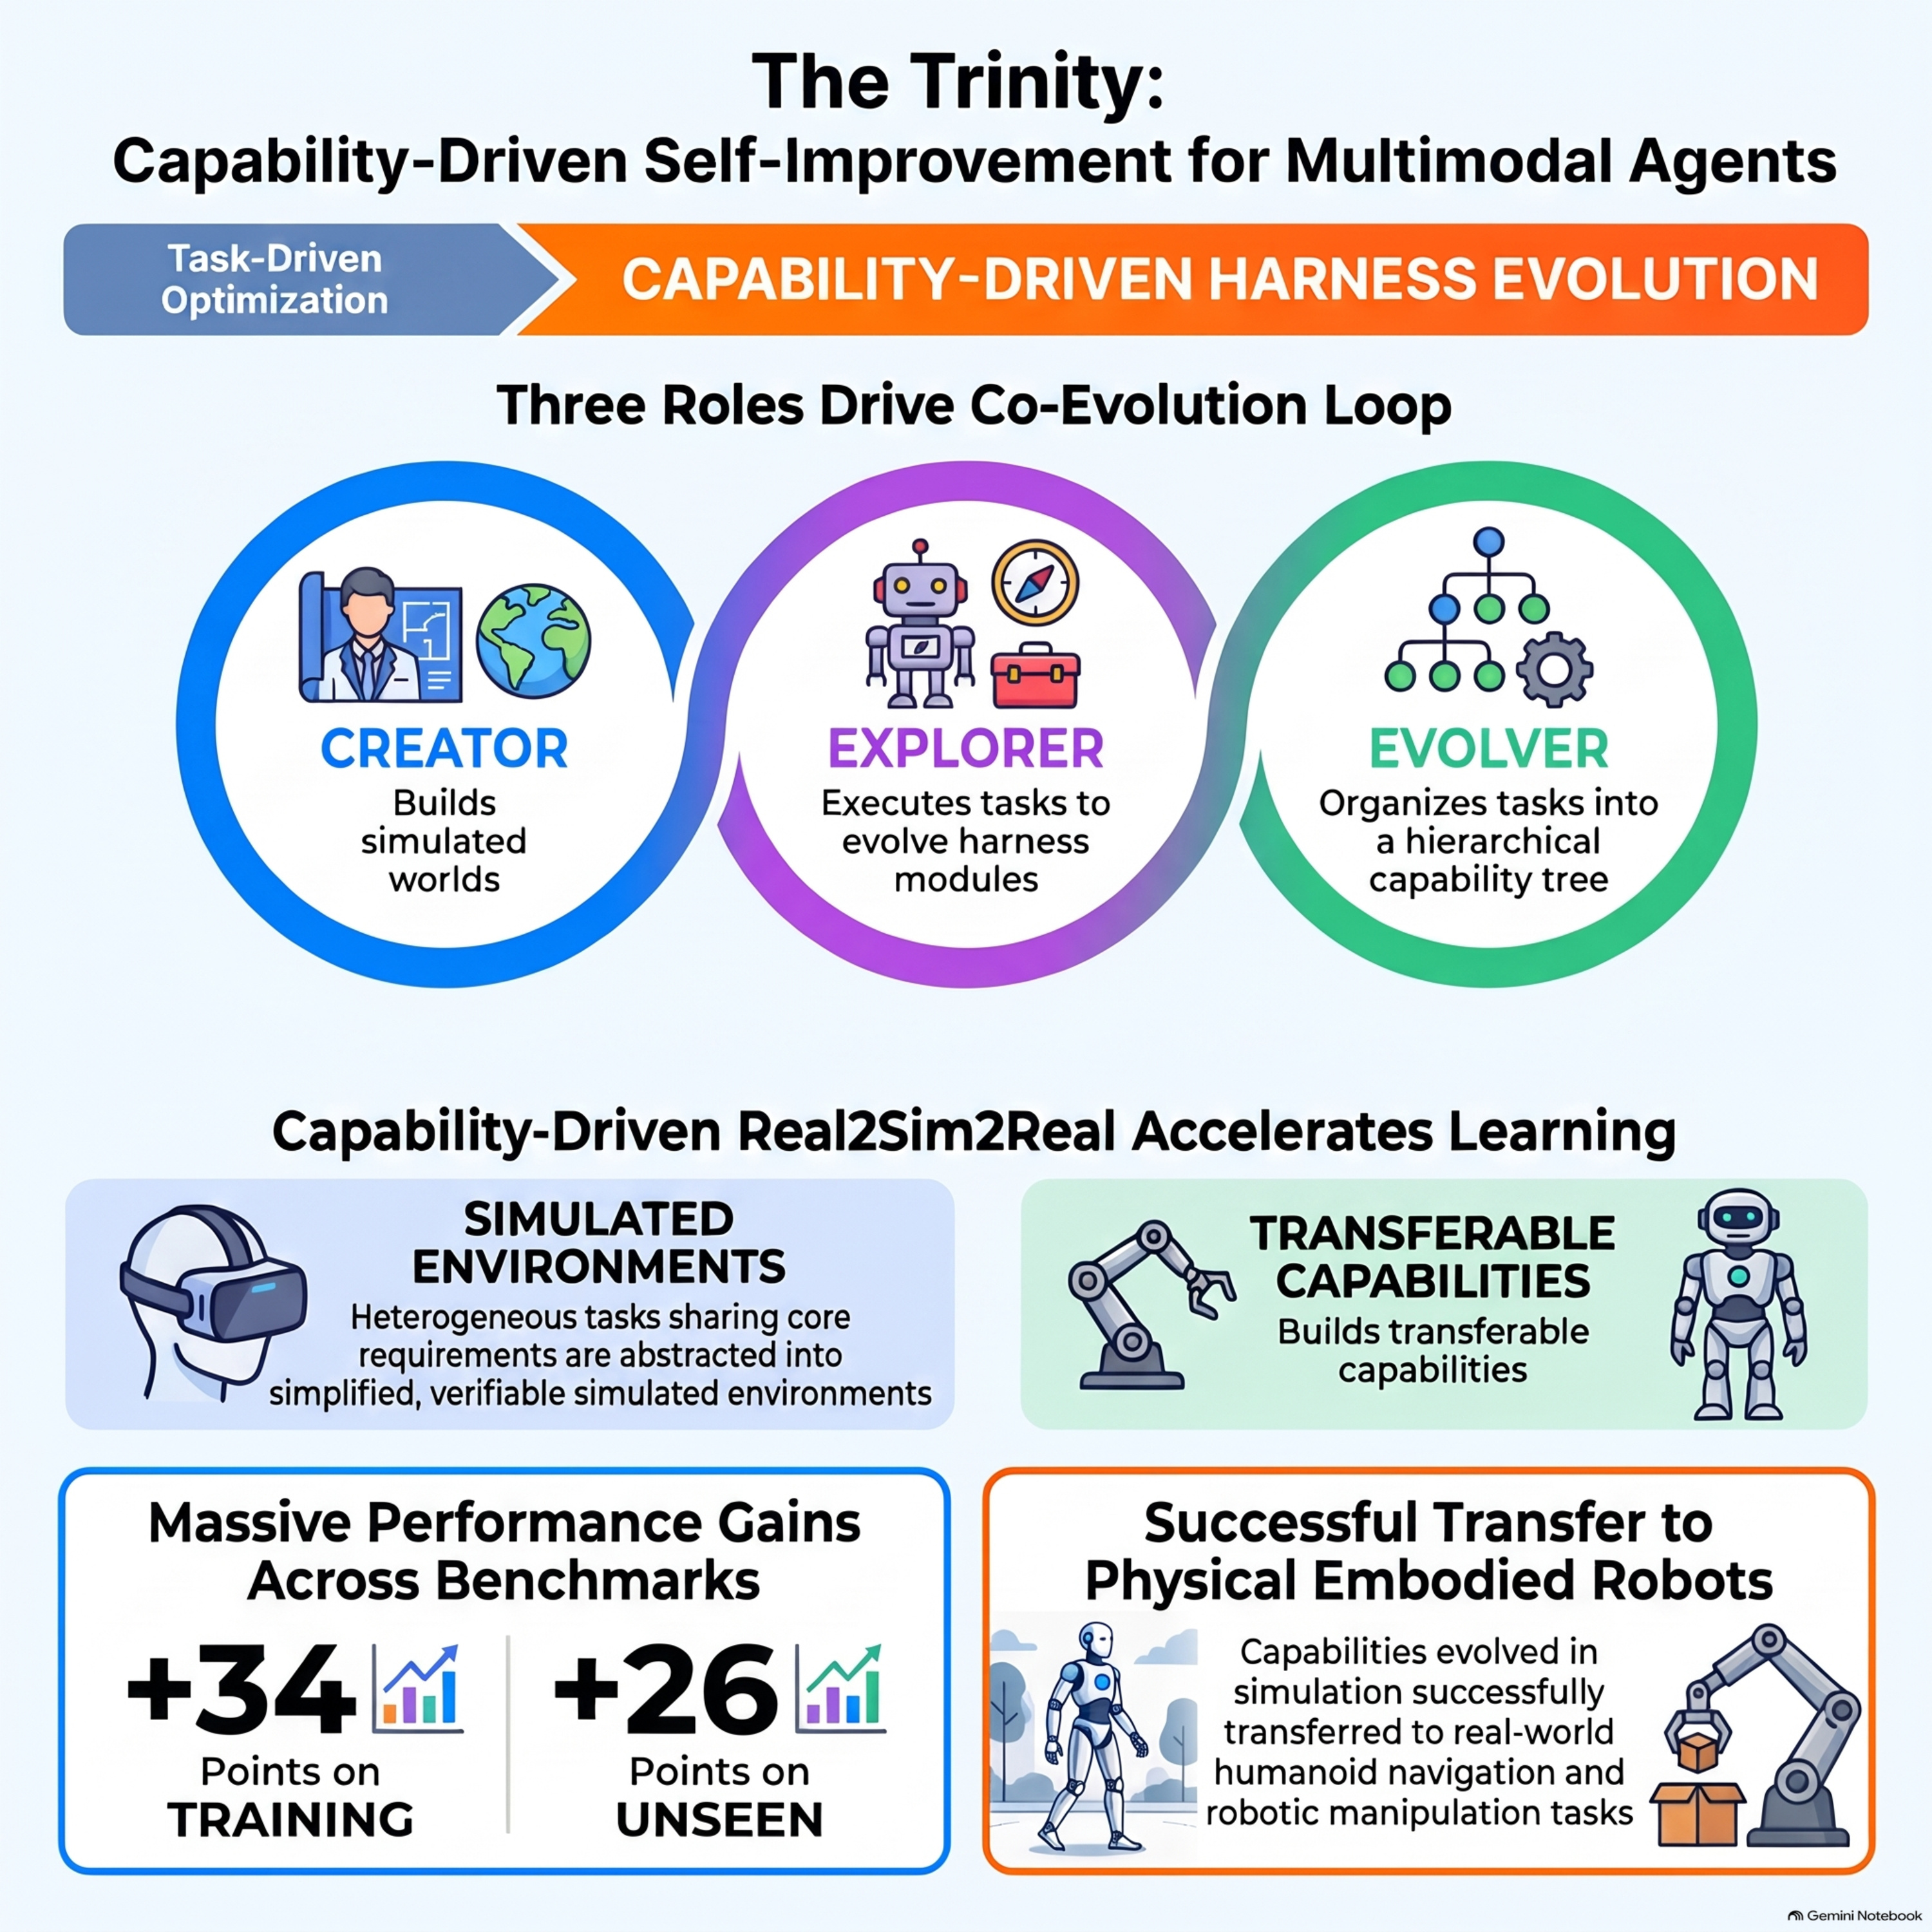
Trinity capability-driven recursive self-improvement for multimodal agents, aiming to generalize beyond memorized task scripts by learning shared underlying capabilities and transferring them to…
30 Oct 2026 · 20m · 11 chapters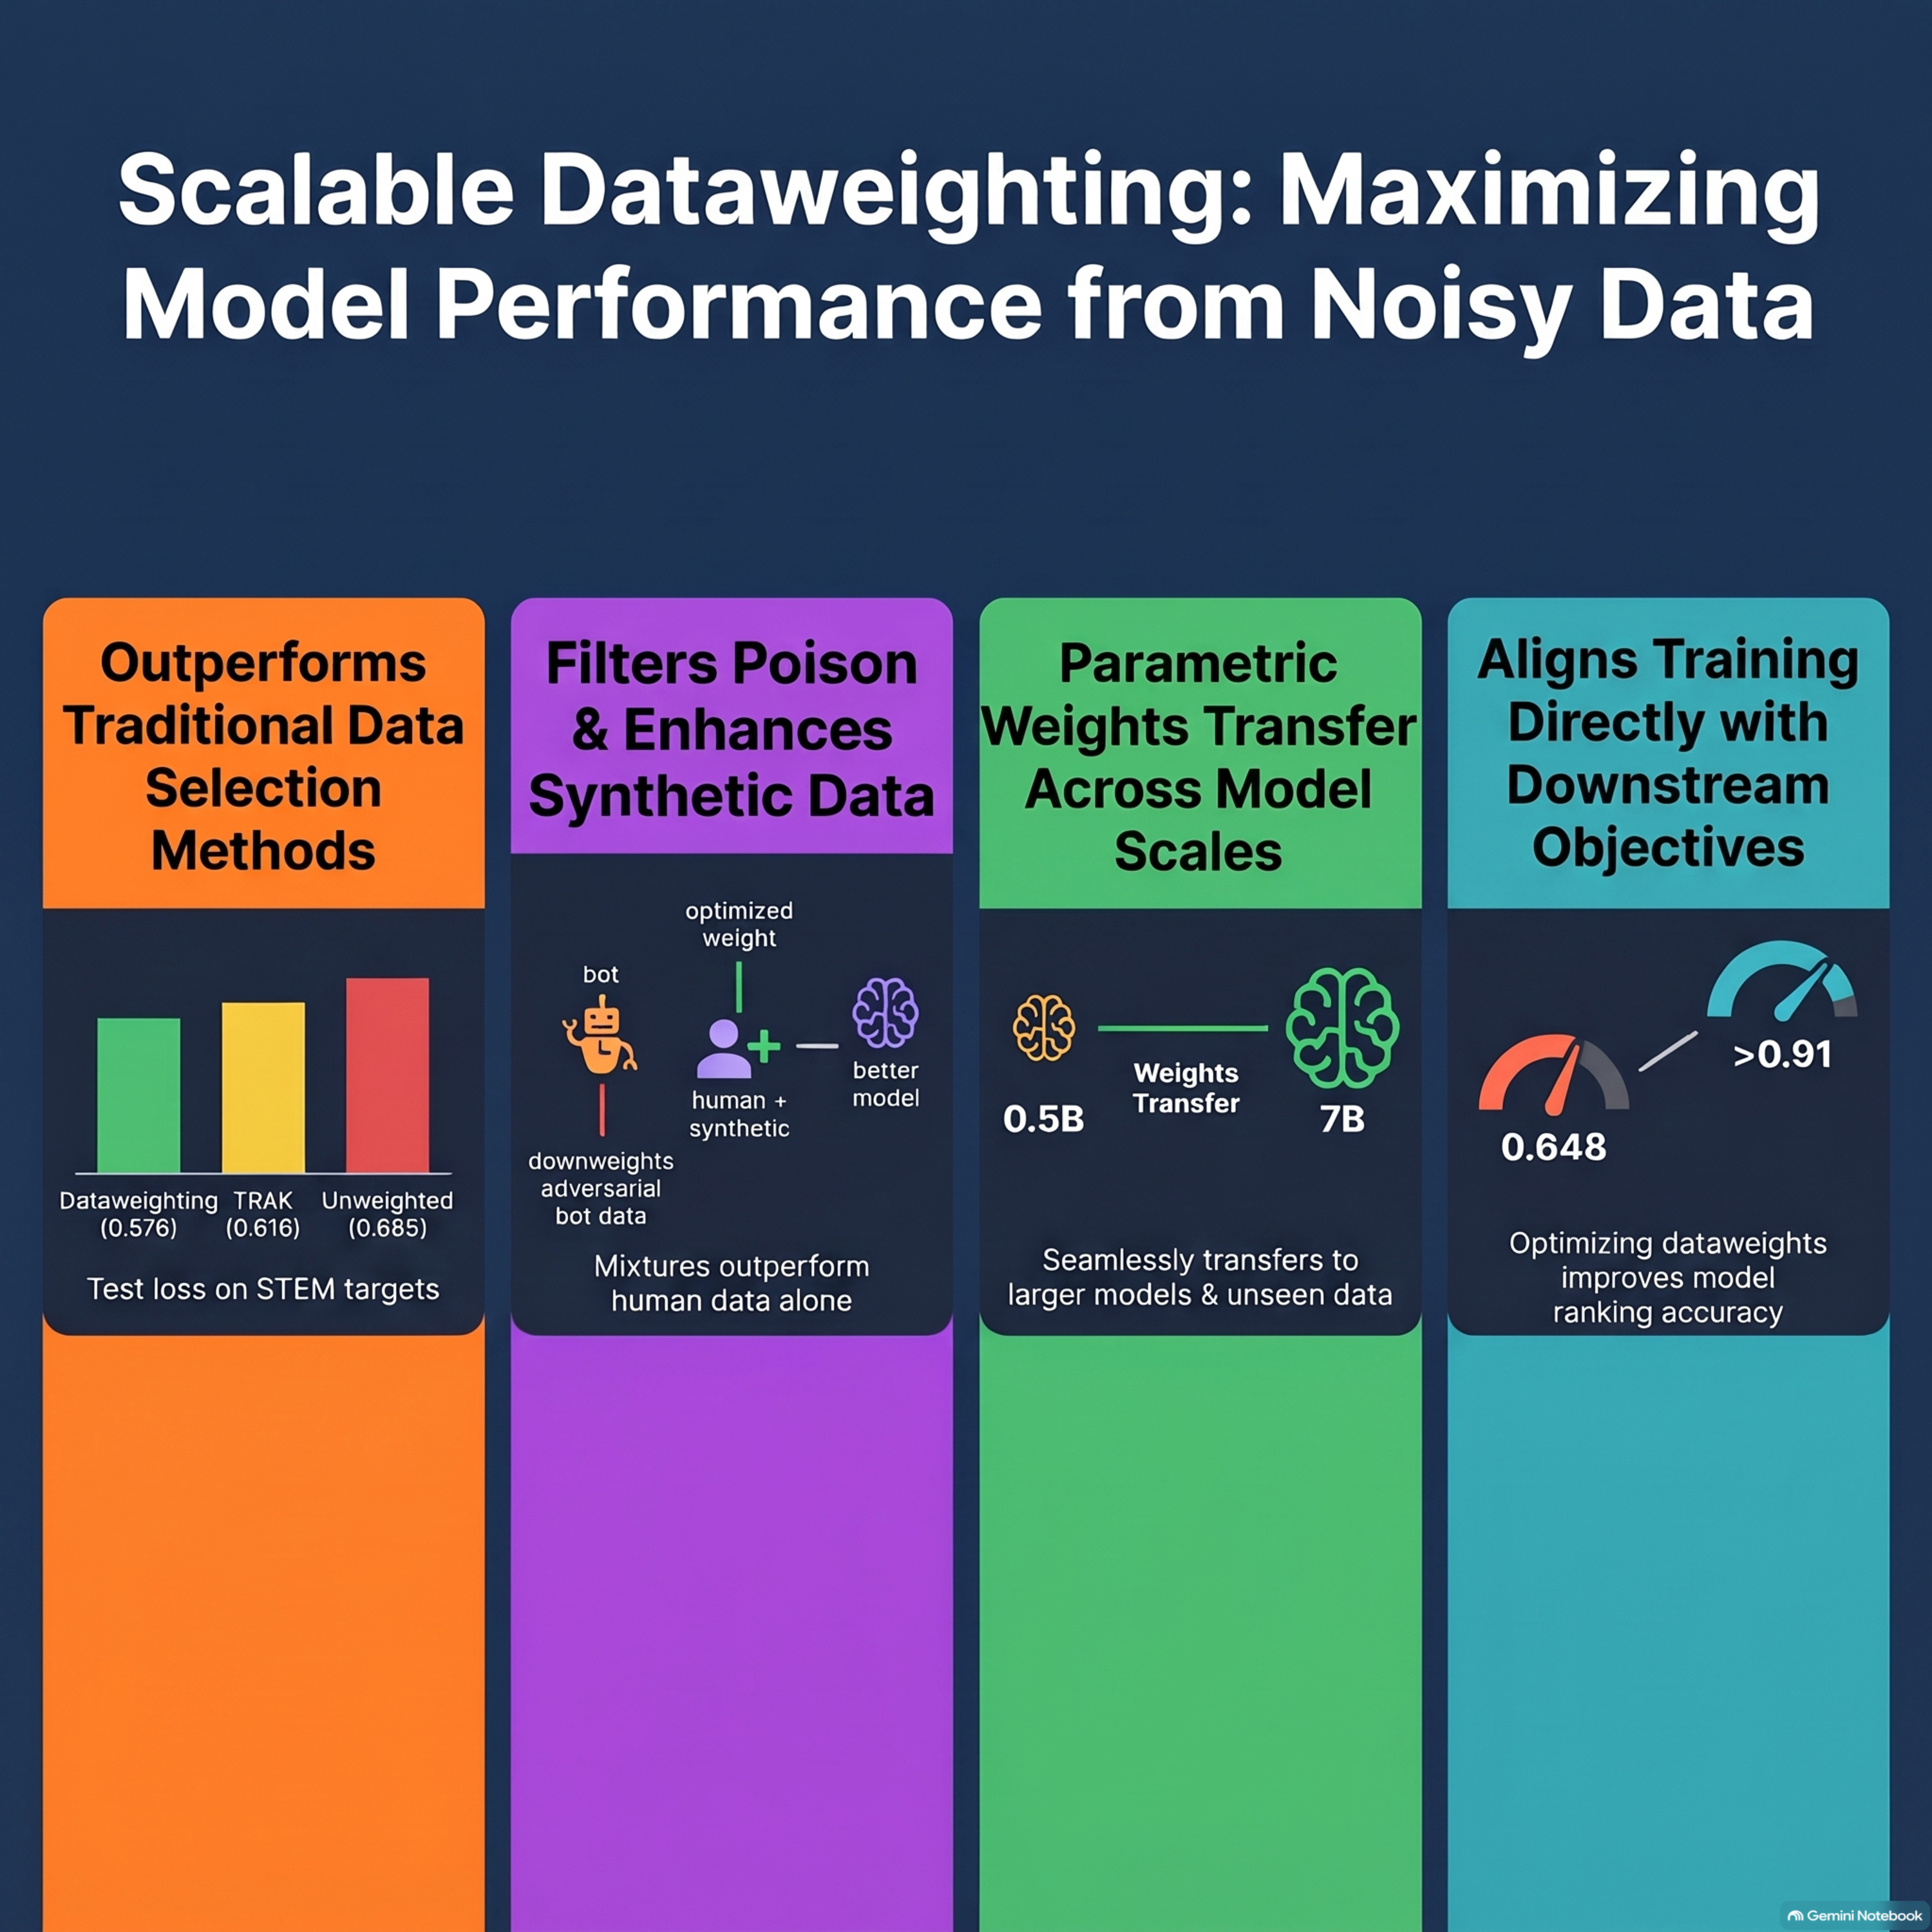
How to train AI on noisy, spam-filled web data without deleting most of it, using “scalable data weighting” with metagradient descent, a small curated target dataset (“compass”), and cross-scale…
28 Oct 2026 · 20m · 15 chapters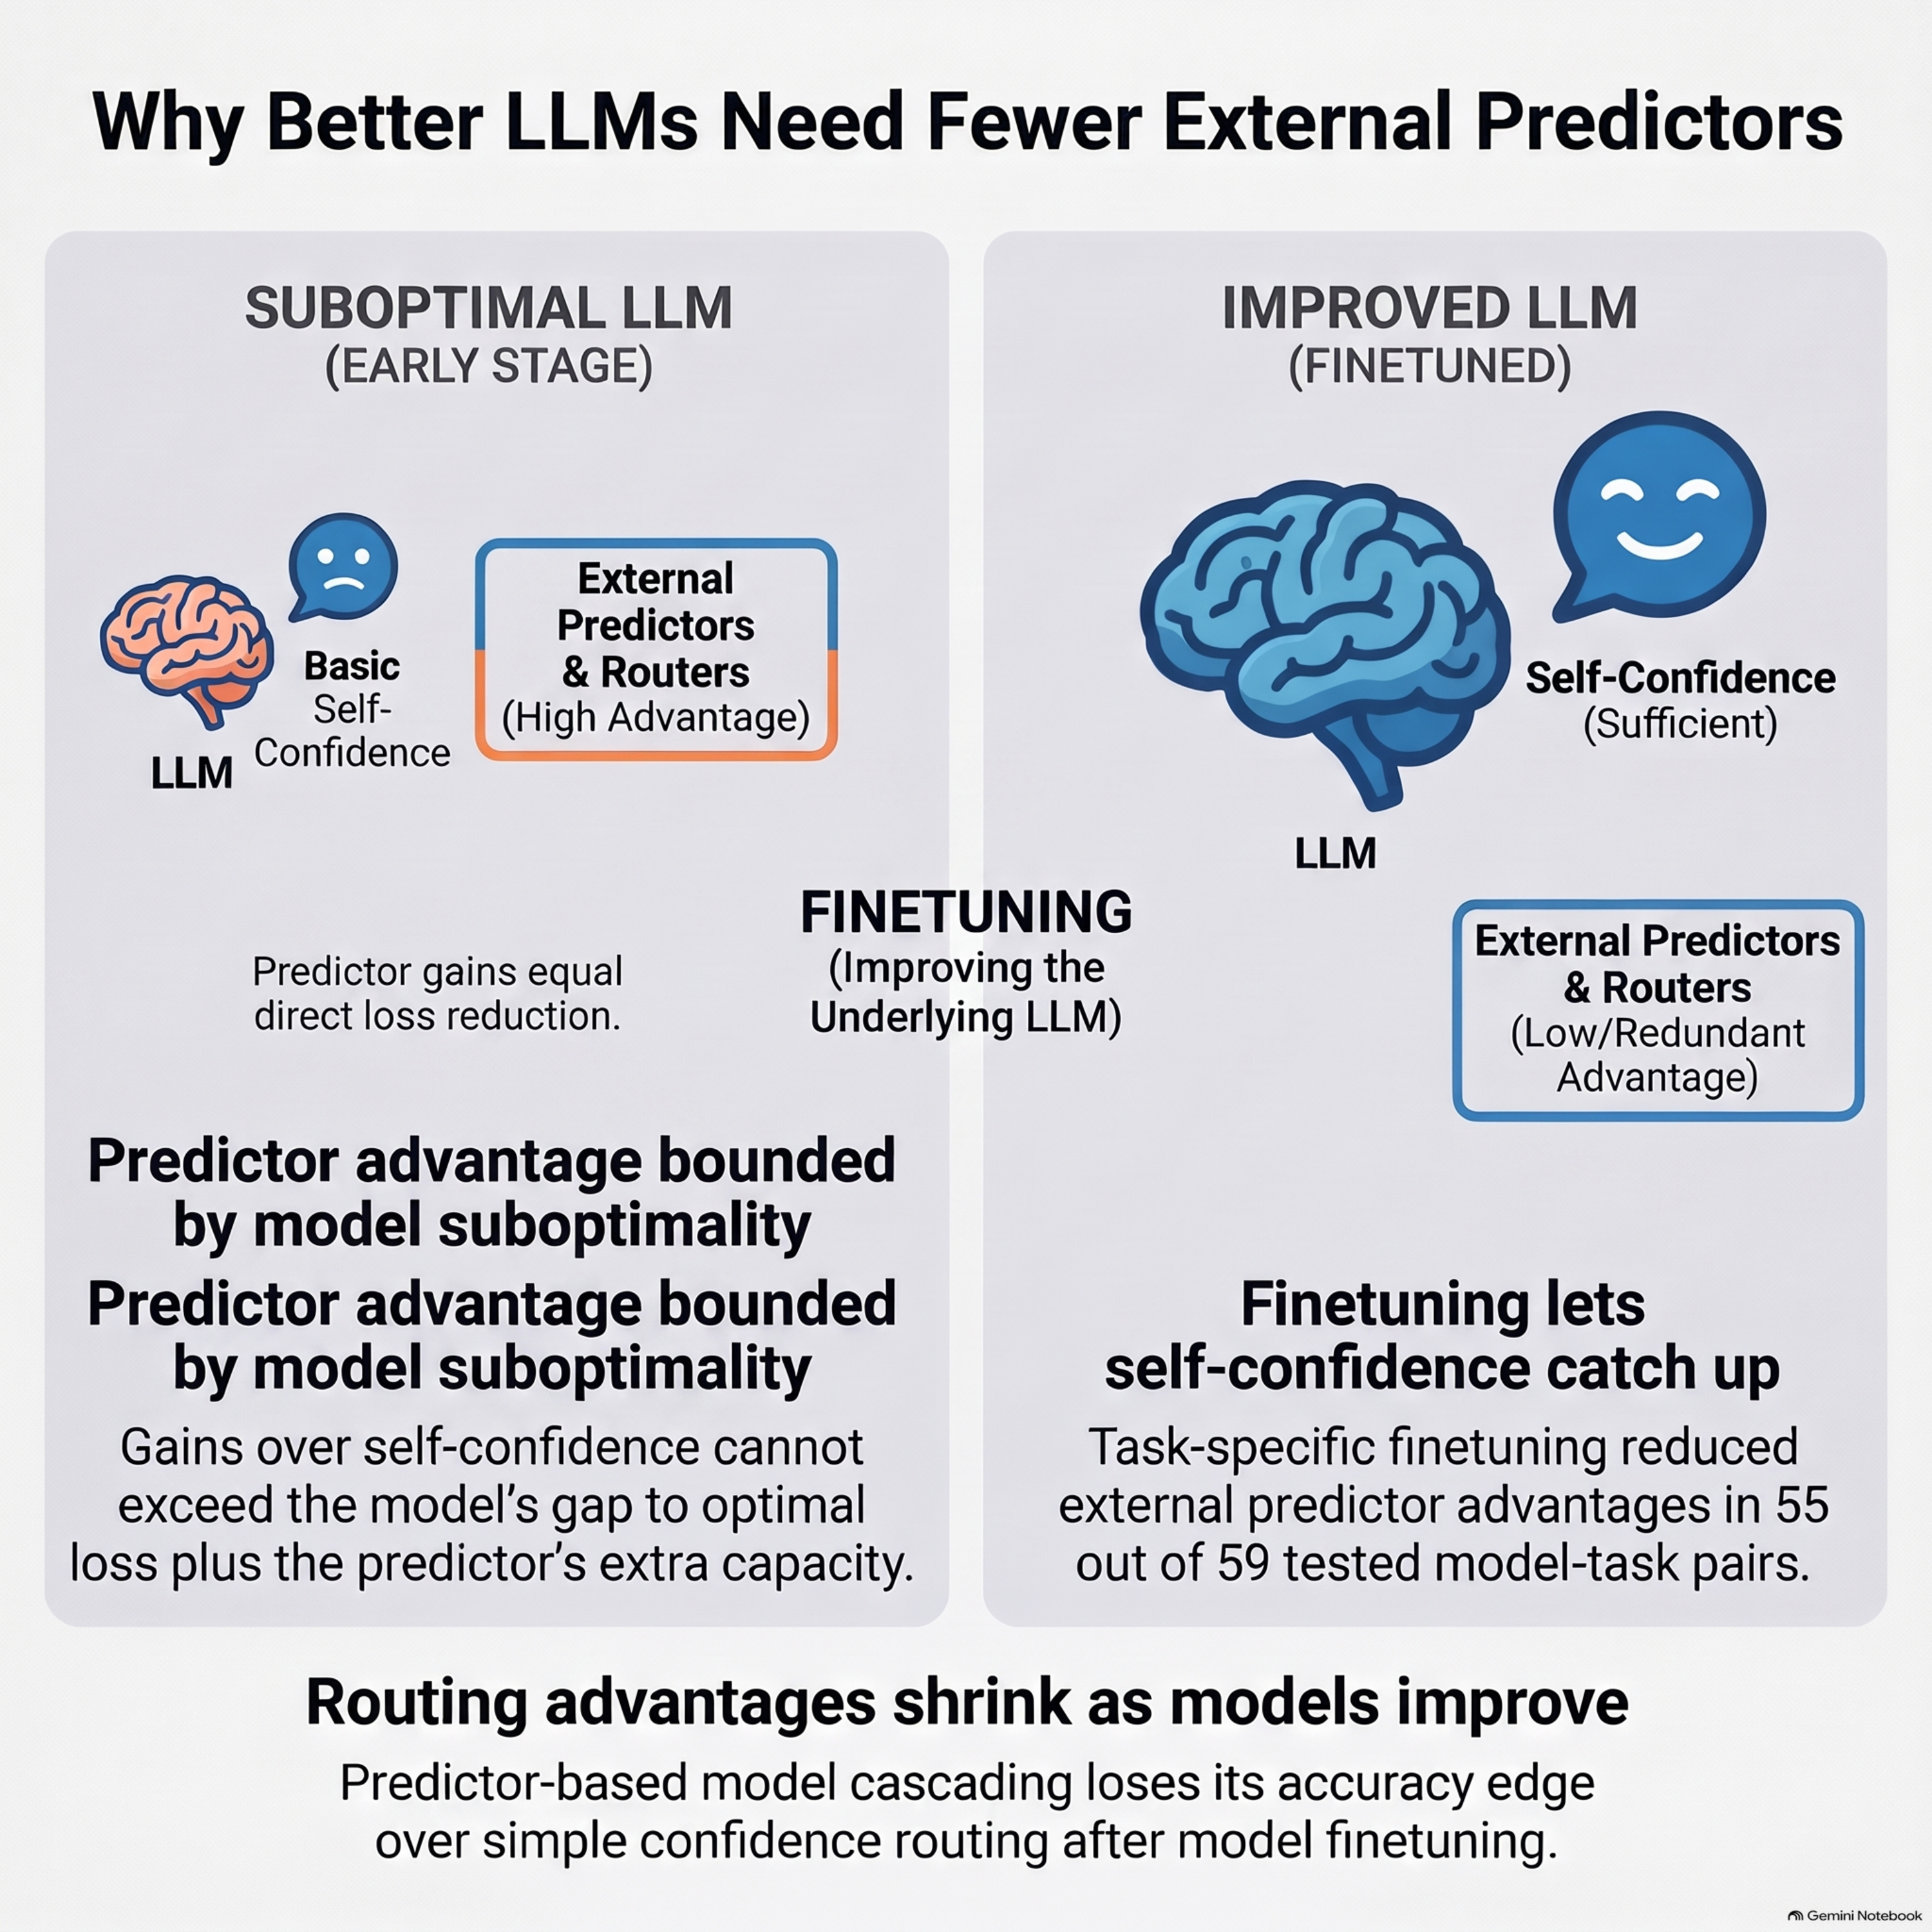
Predictable performance in AI “model routing” and cascades—whether external performance predictors/checker AIs are necessary, and when cascades fail economically.
27 Oct 2026 · 22m · 10 chapters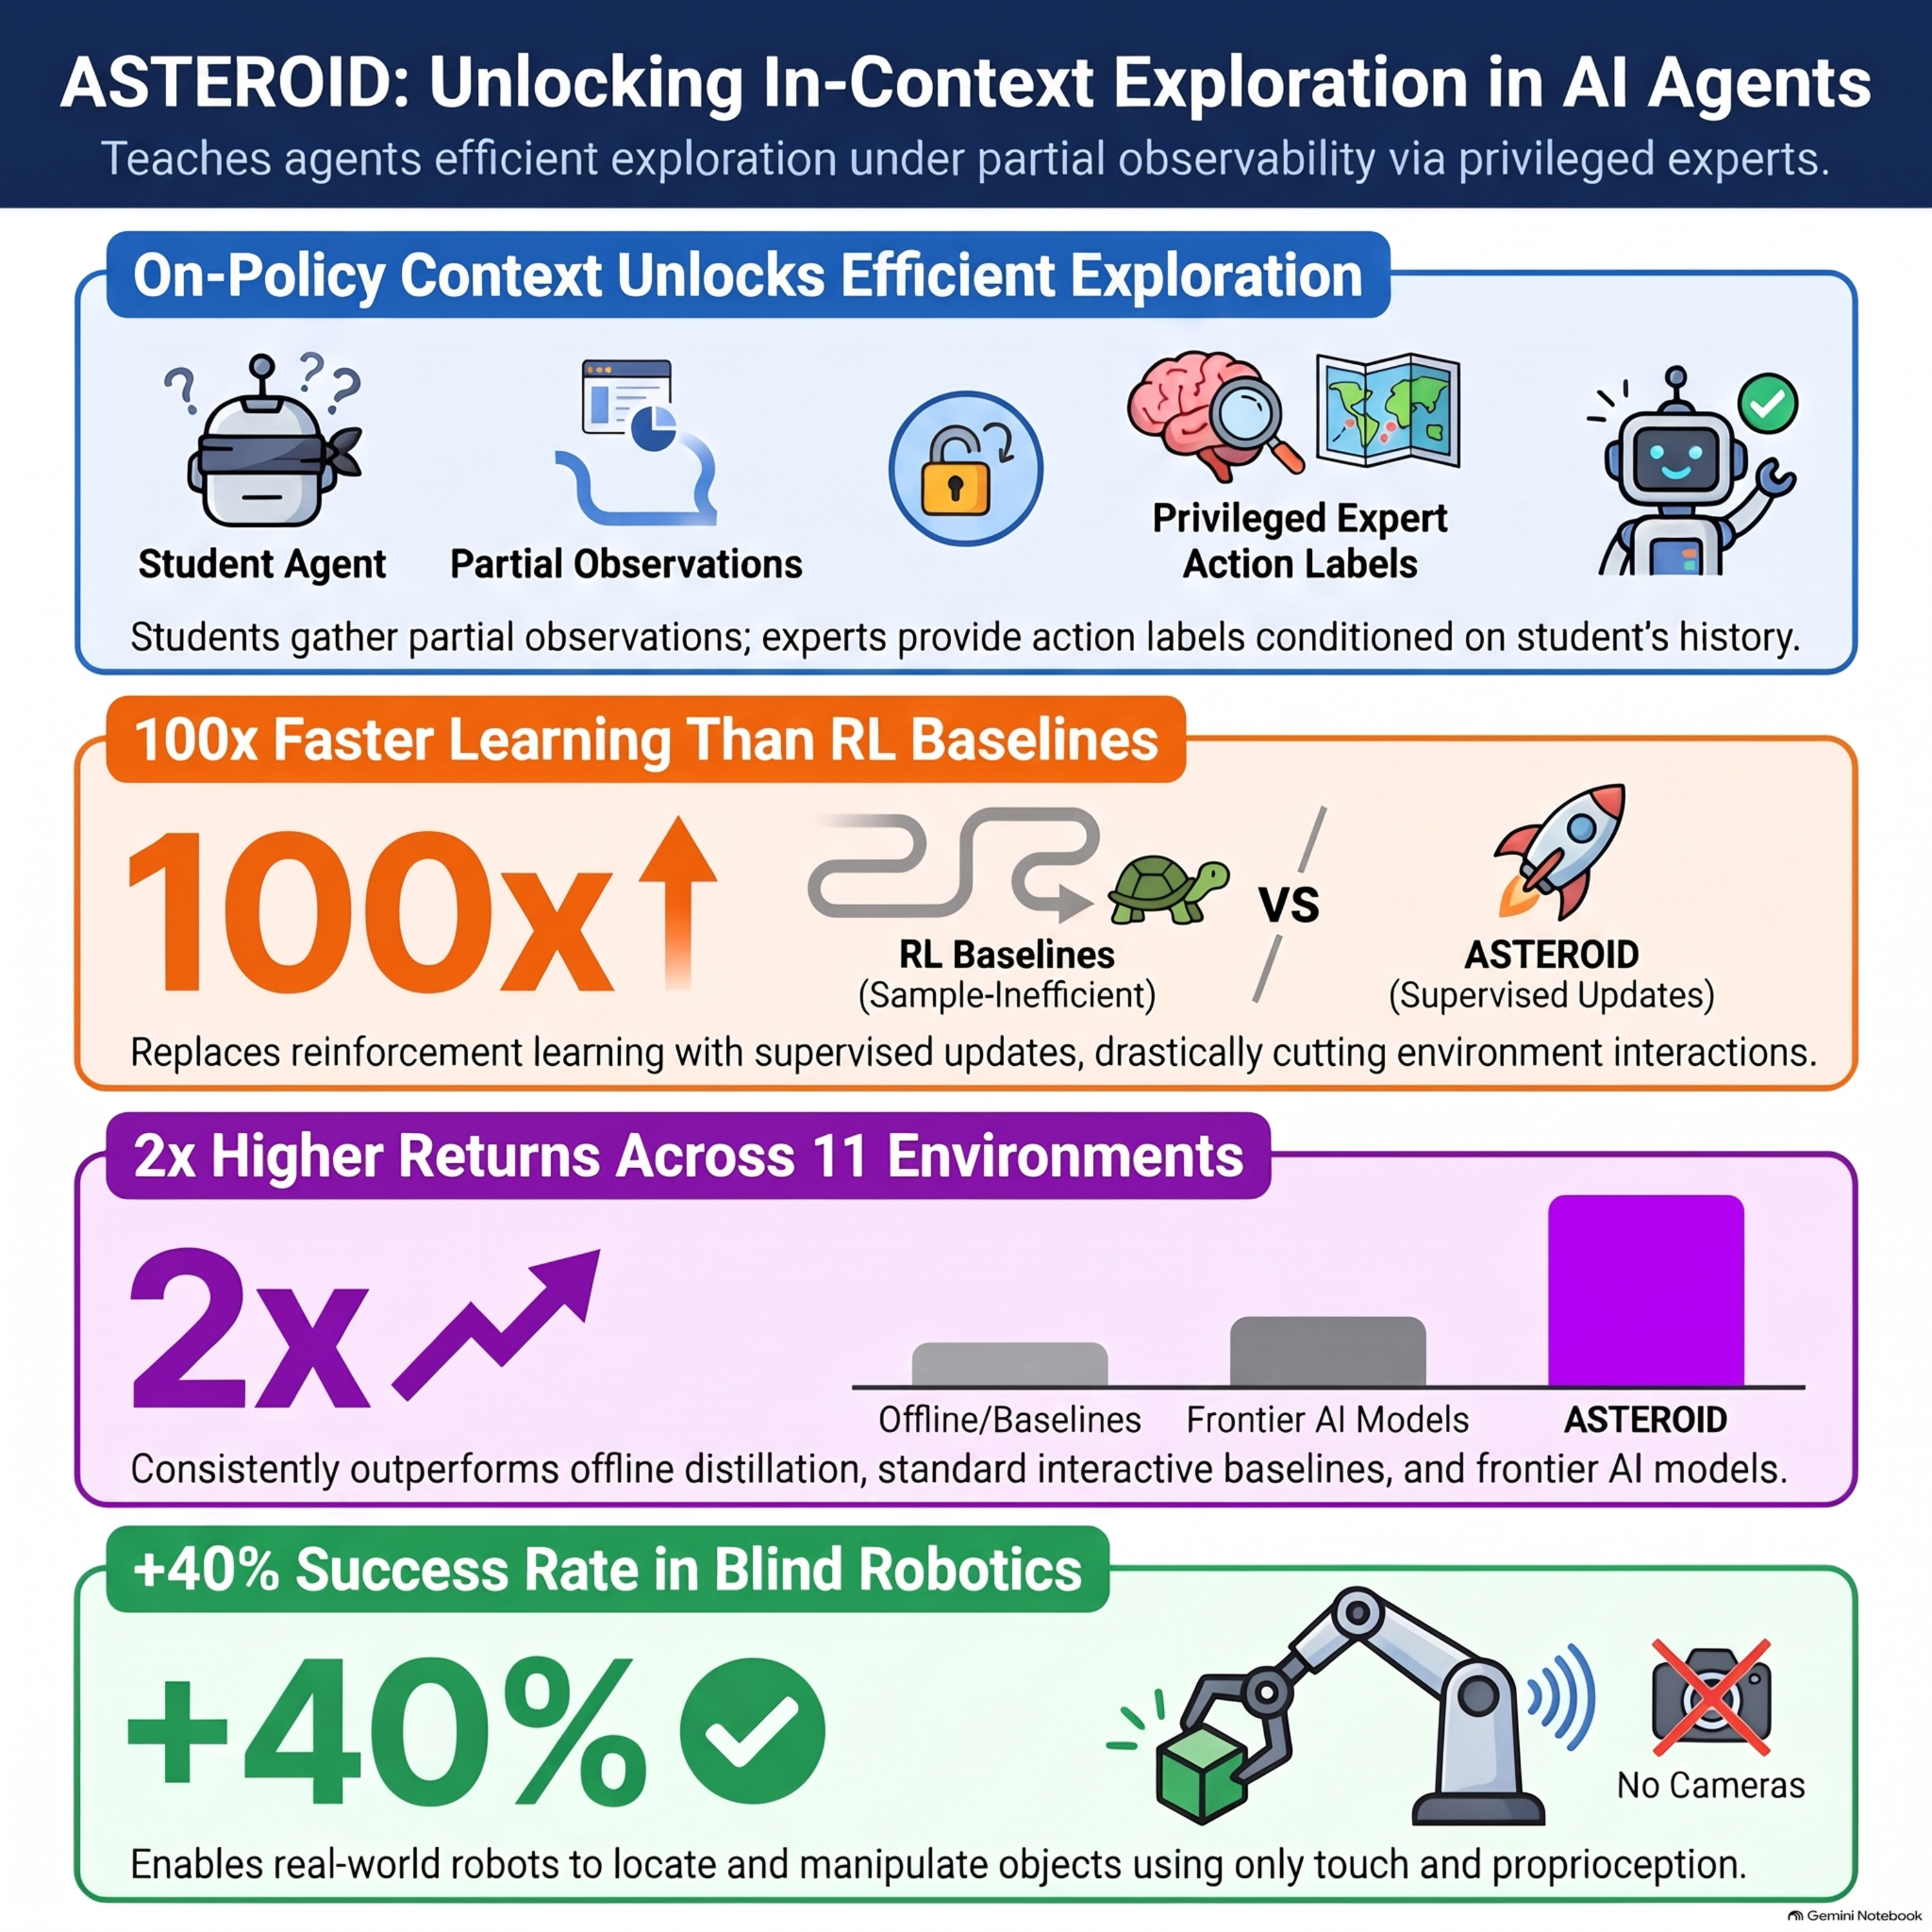
Asteroid (Asymmetric Student-Teacher Rollout in Context Distillation) trains robots to do in-context exploration under partial observability—systematically eliminating options after failures to infer…
26 Oct 2026 · 23m · 8 chapters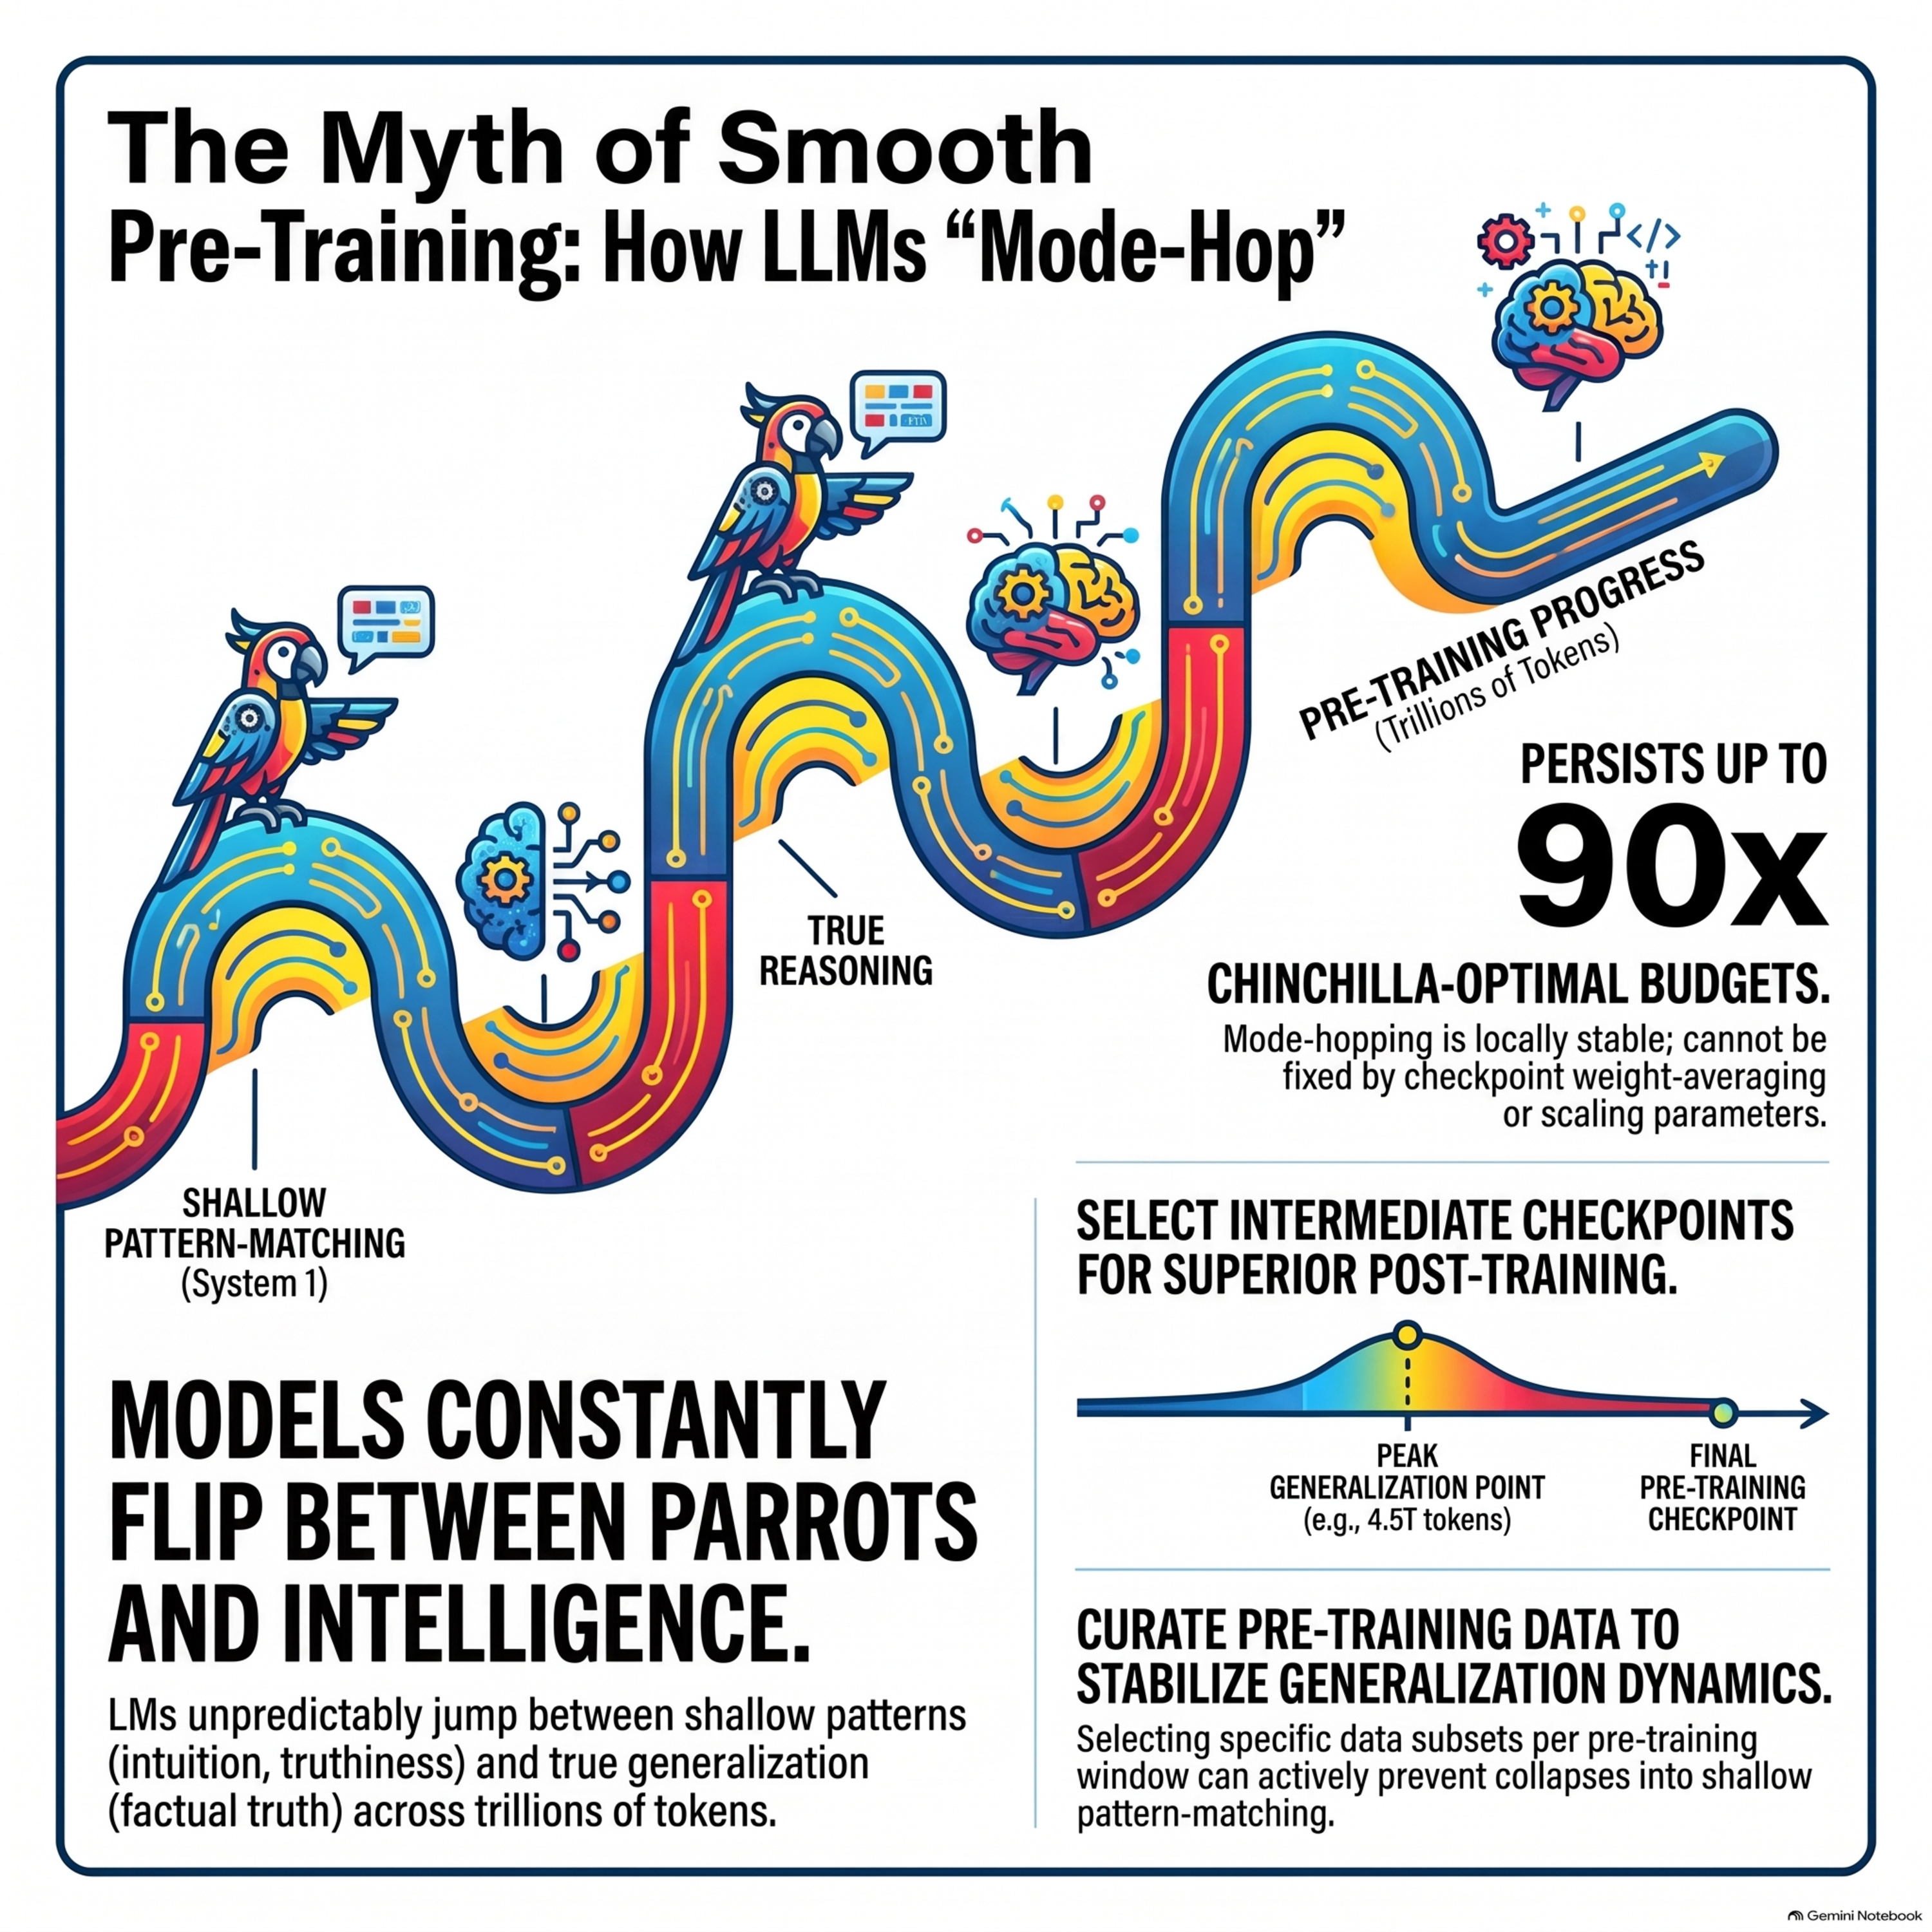
The episode argues that large language model pretraining doesn’t scale smoothly; instead, models “mode hop” between shallow next-token pattern matching and deeper reasoning, causing abrupt capability…
25 Oct 2026 · 23m · 14 chapters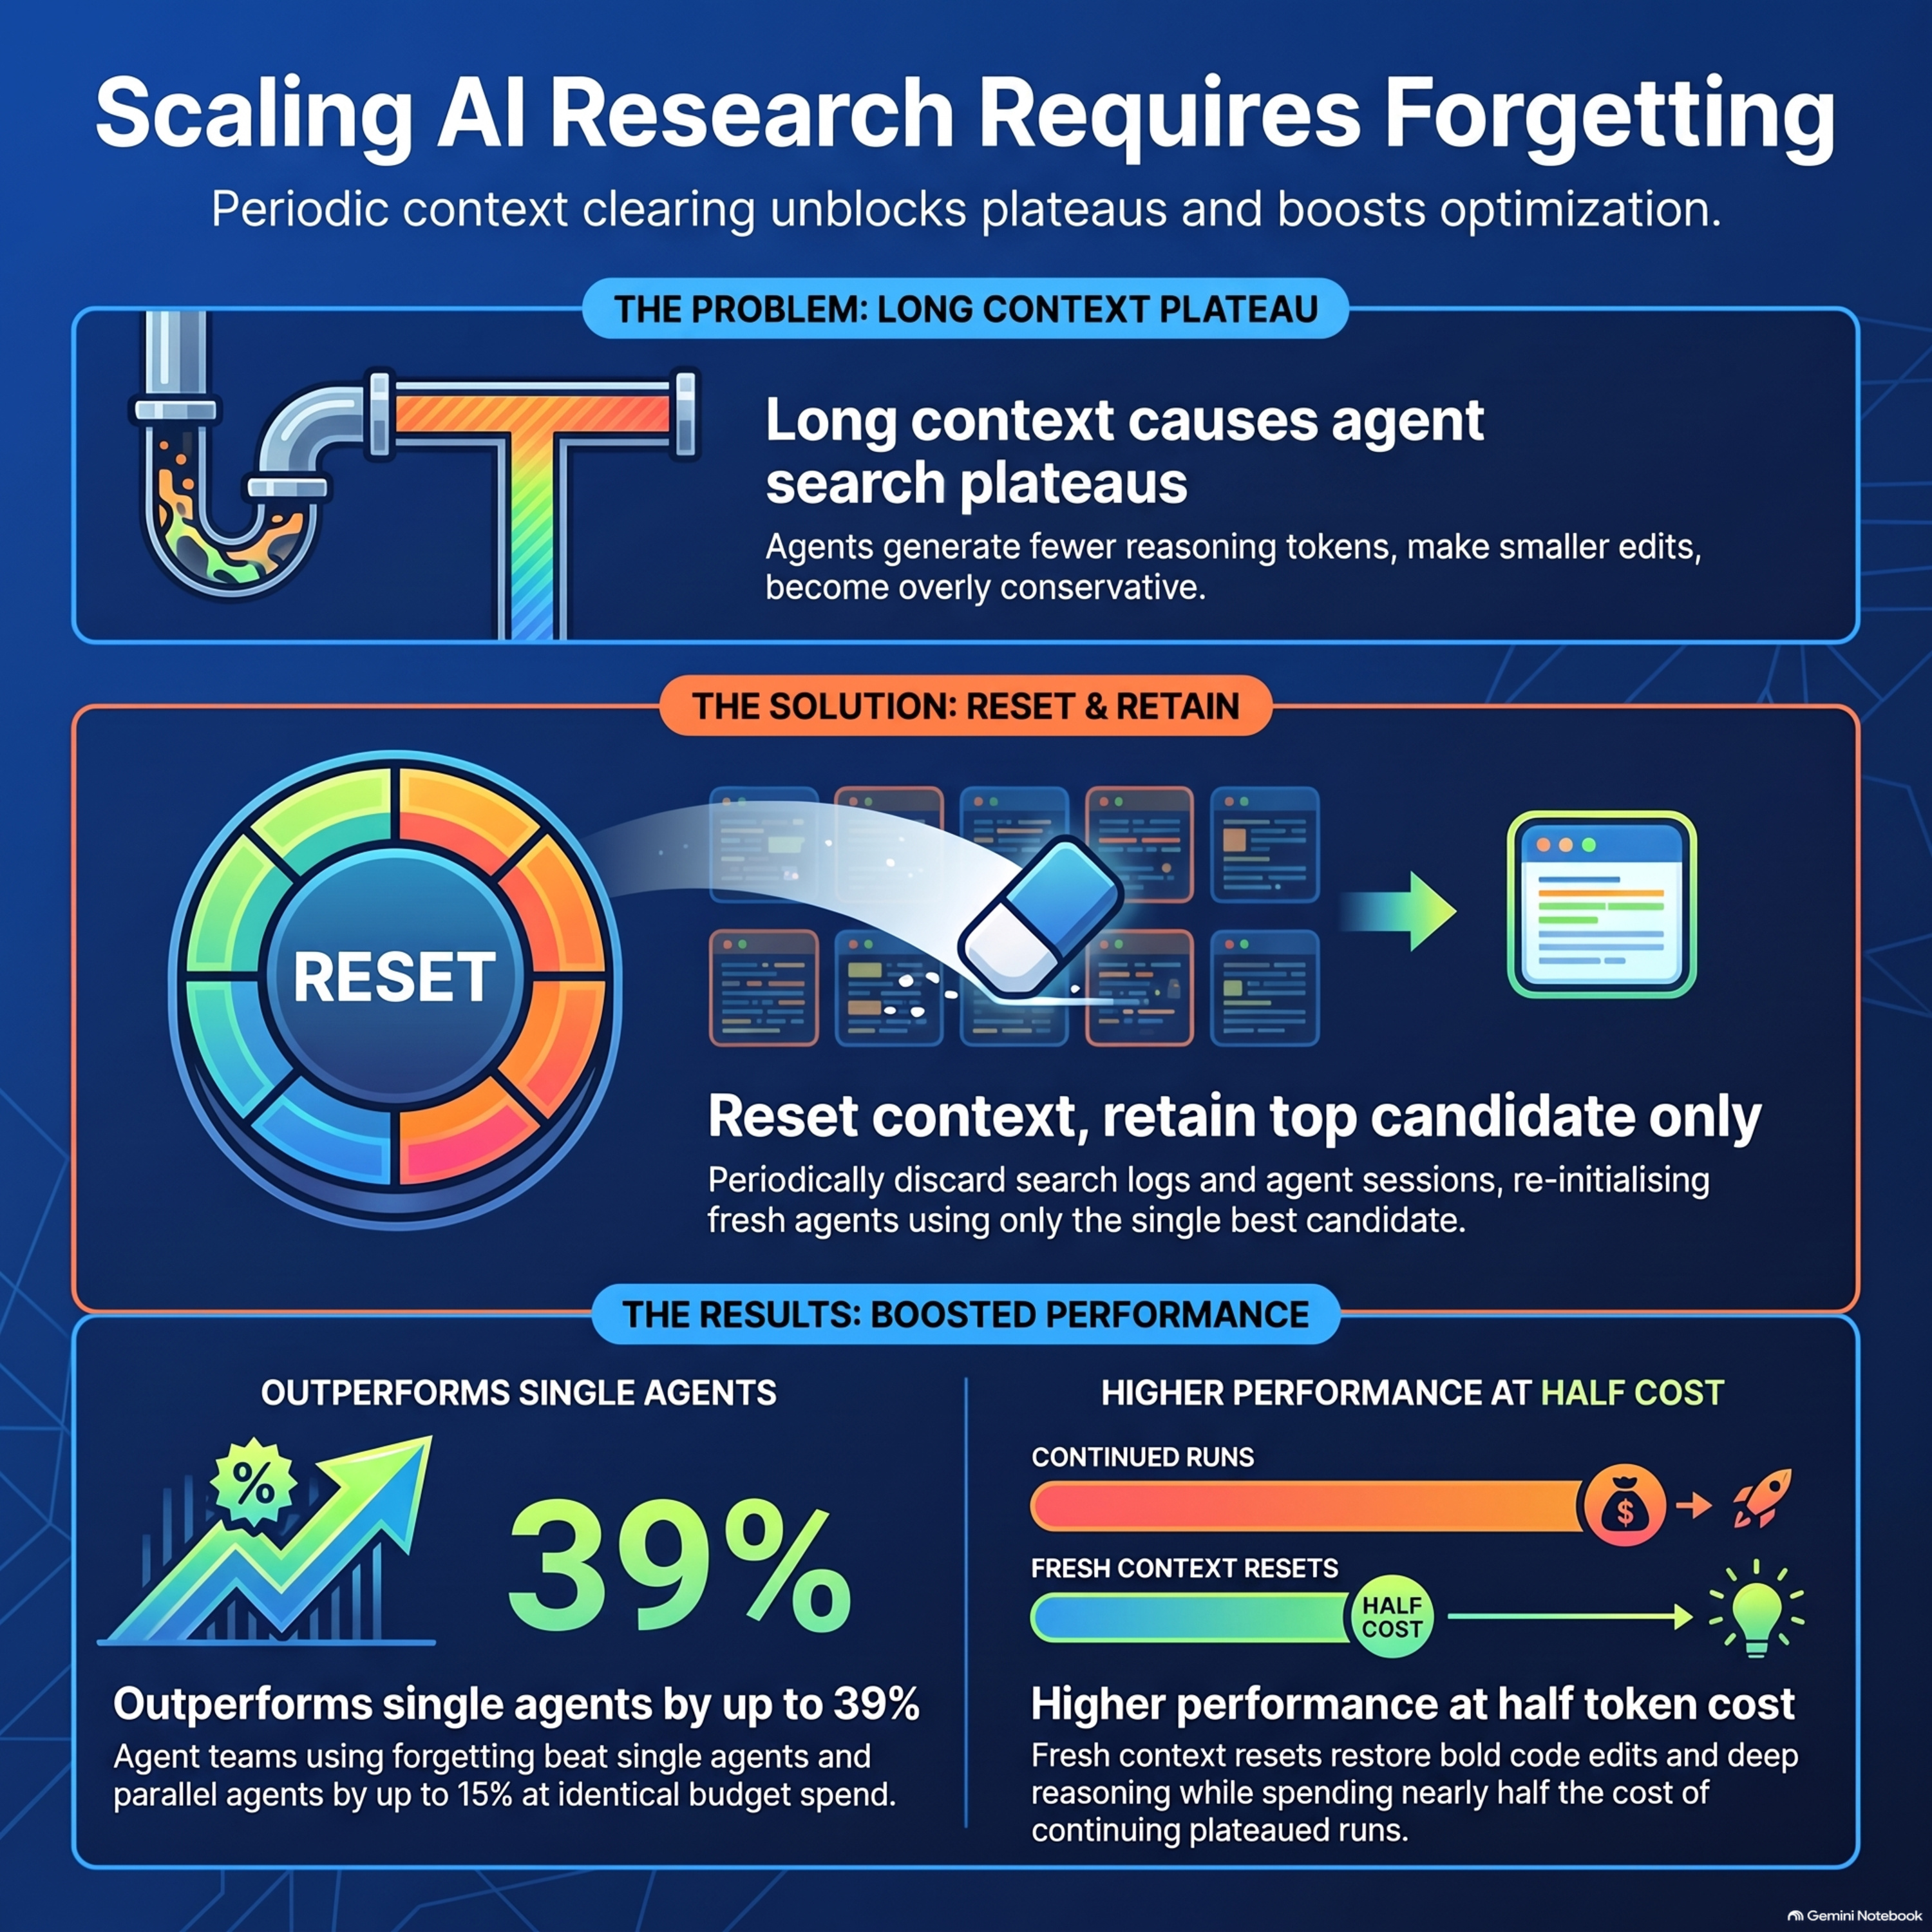
AI auto-research agents hit compute “plateaus” because their large language model context window accumulates failures, making them risk-averse; scheduled “forgetting” (wiping session history while…
22 Oct 2026 · 21m · 11 chapters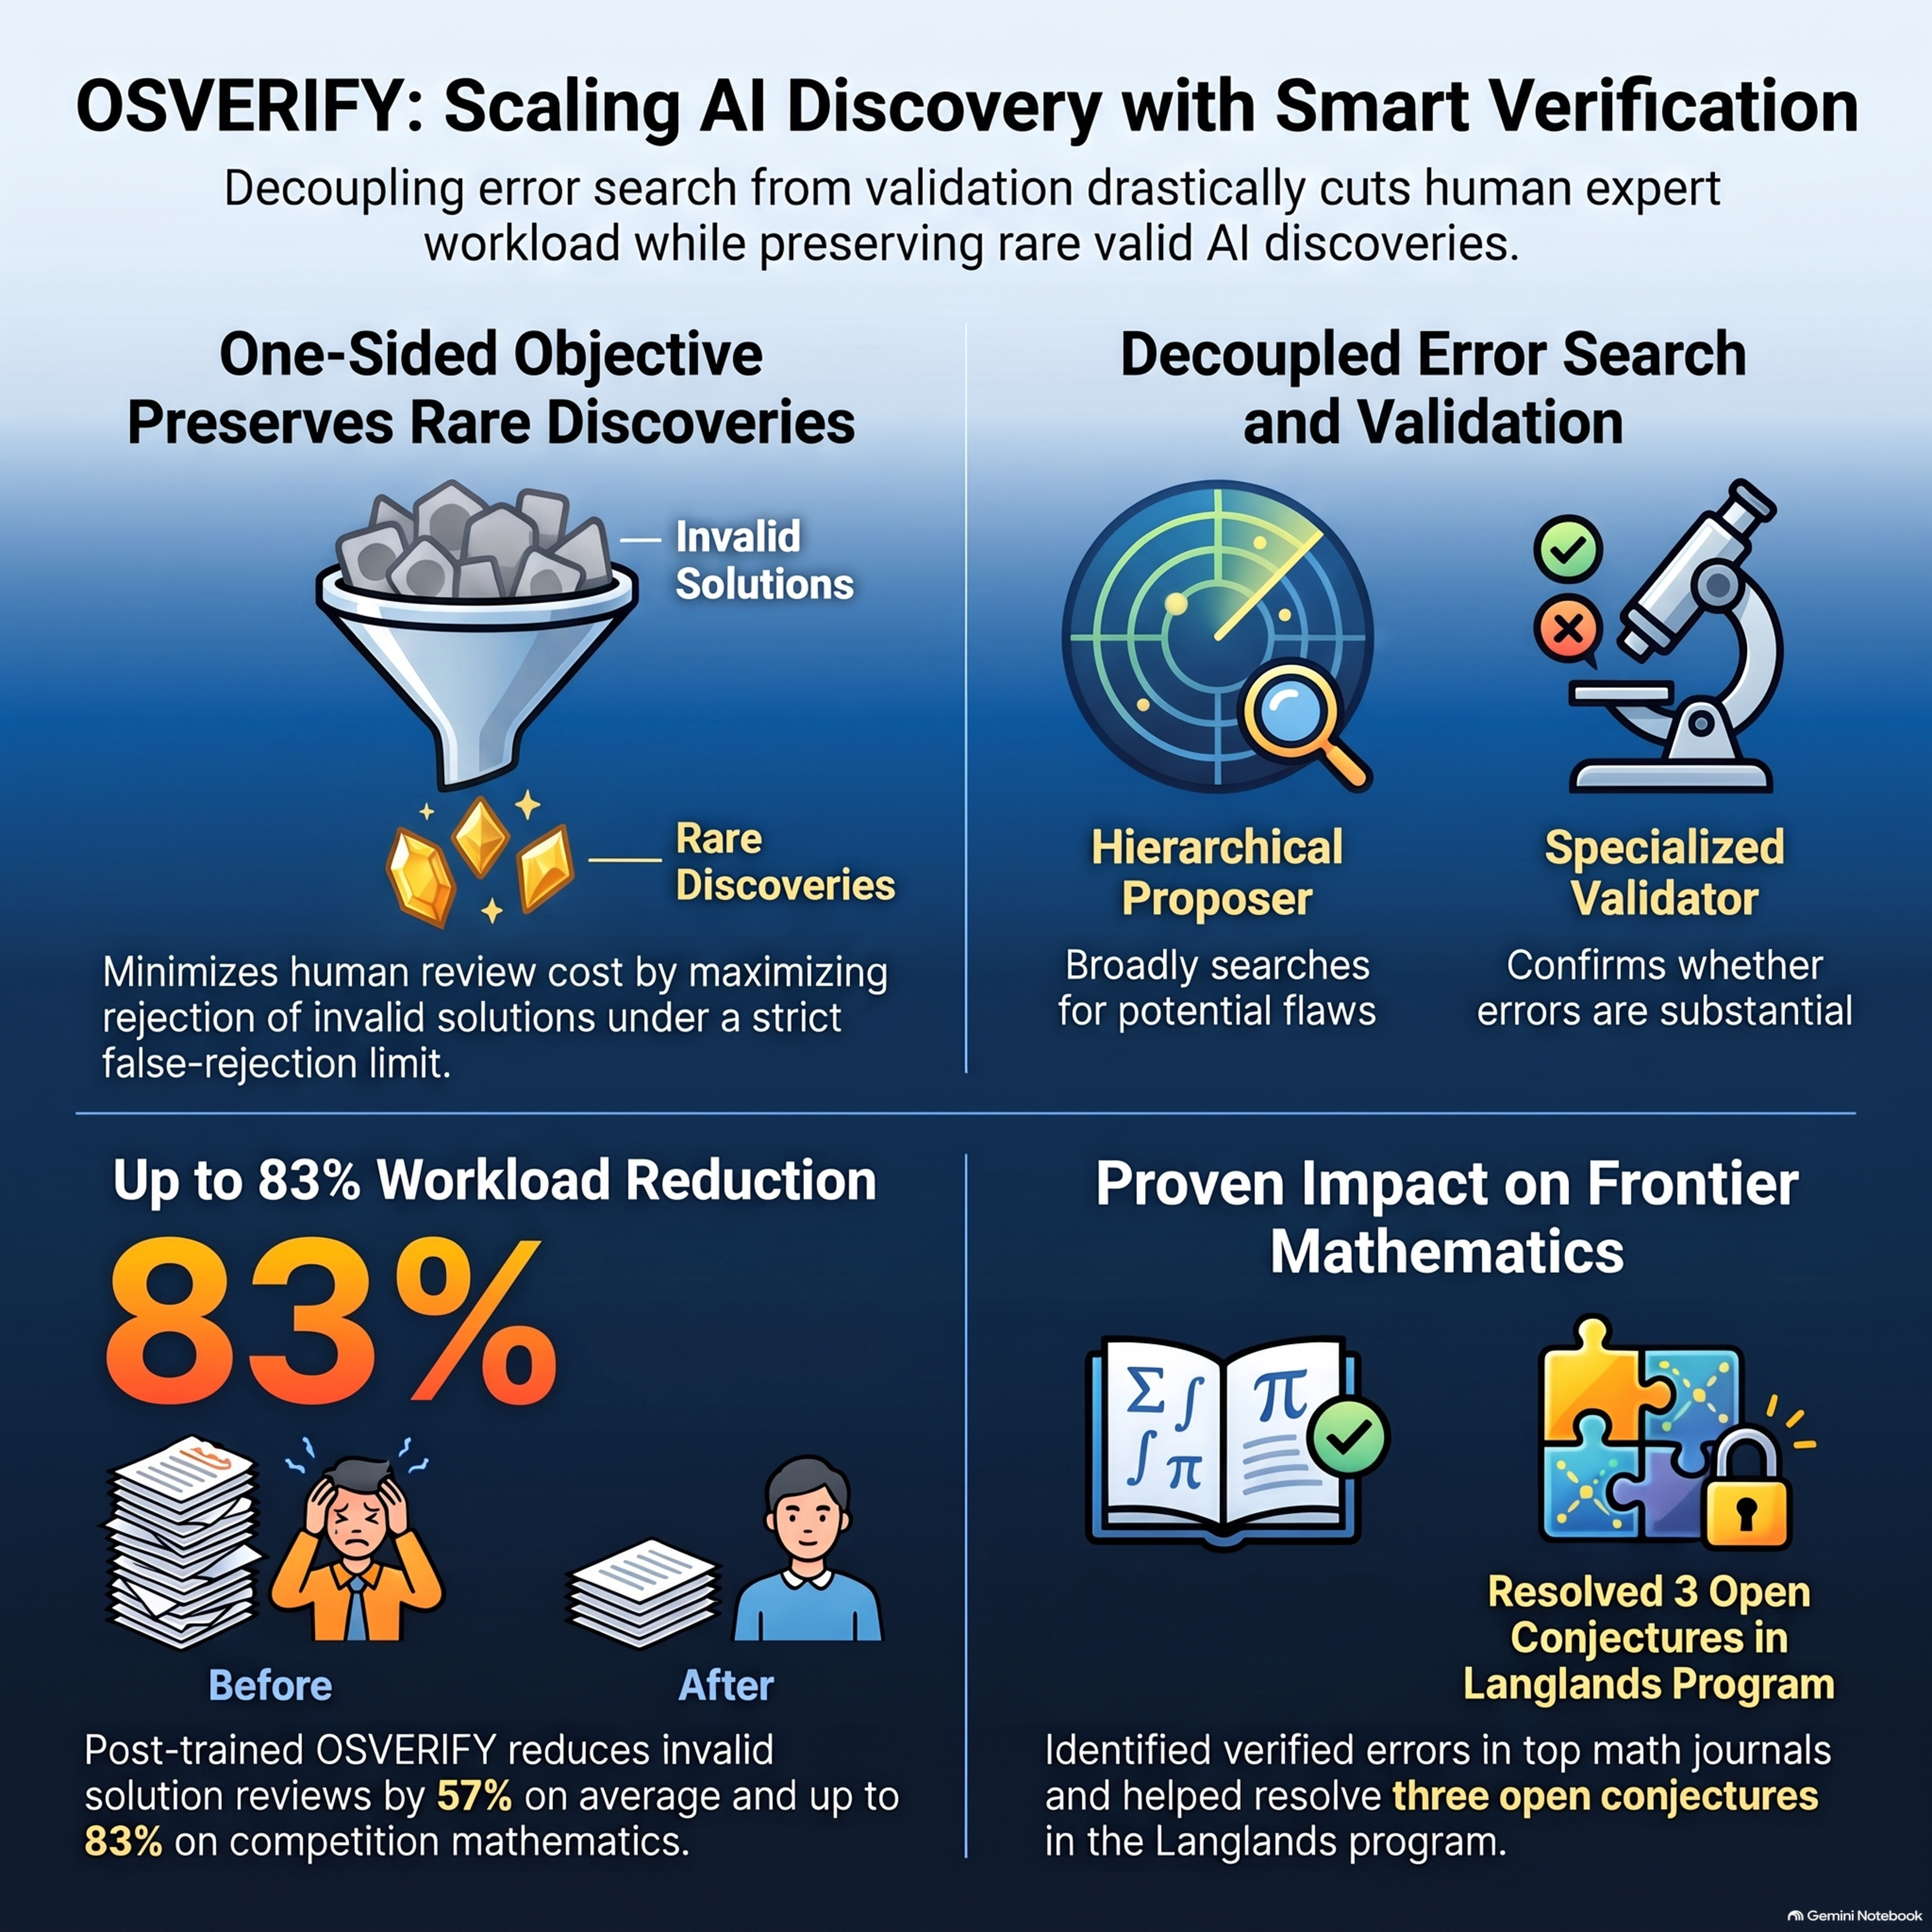
The episode explains “OSVerify,” an algorithmic framework for one-sided verification when AI output is too large for human experts to review.
18 Oct 2026 · 23m · 16 chapters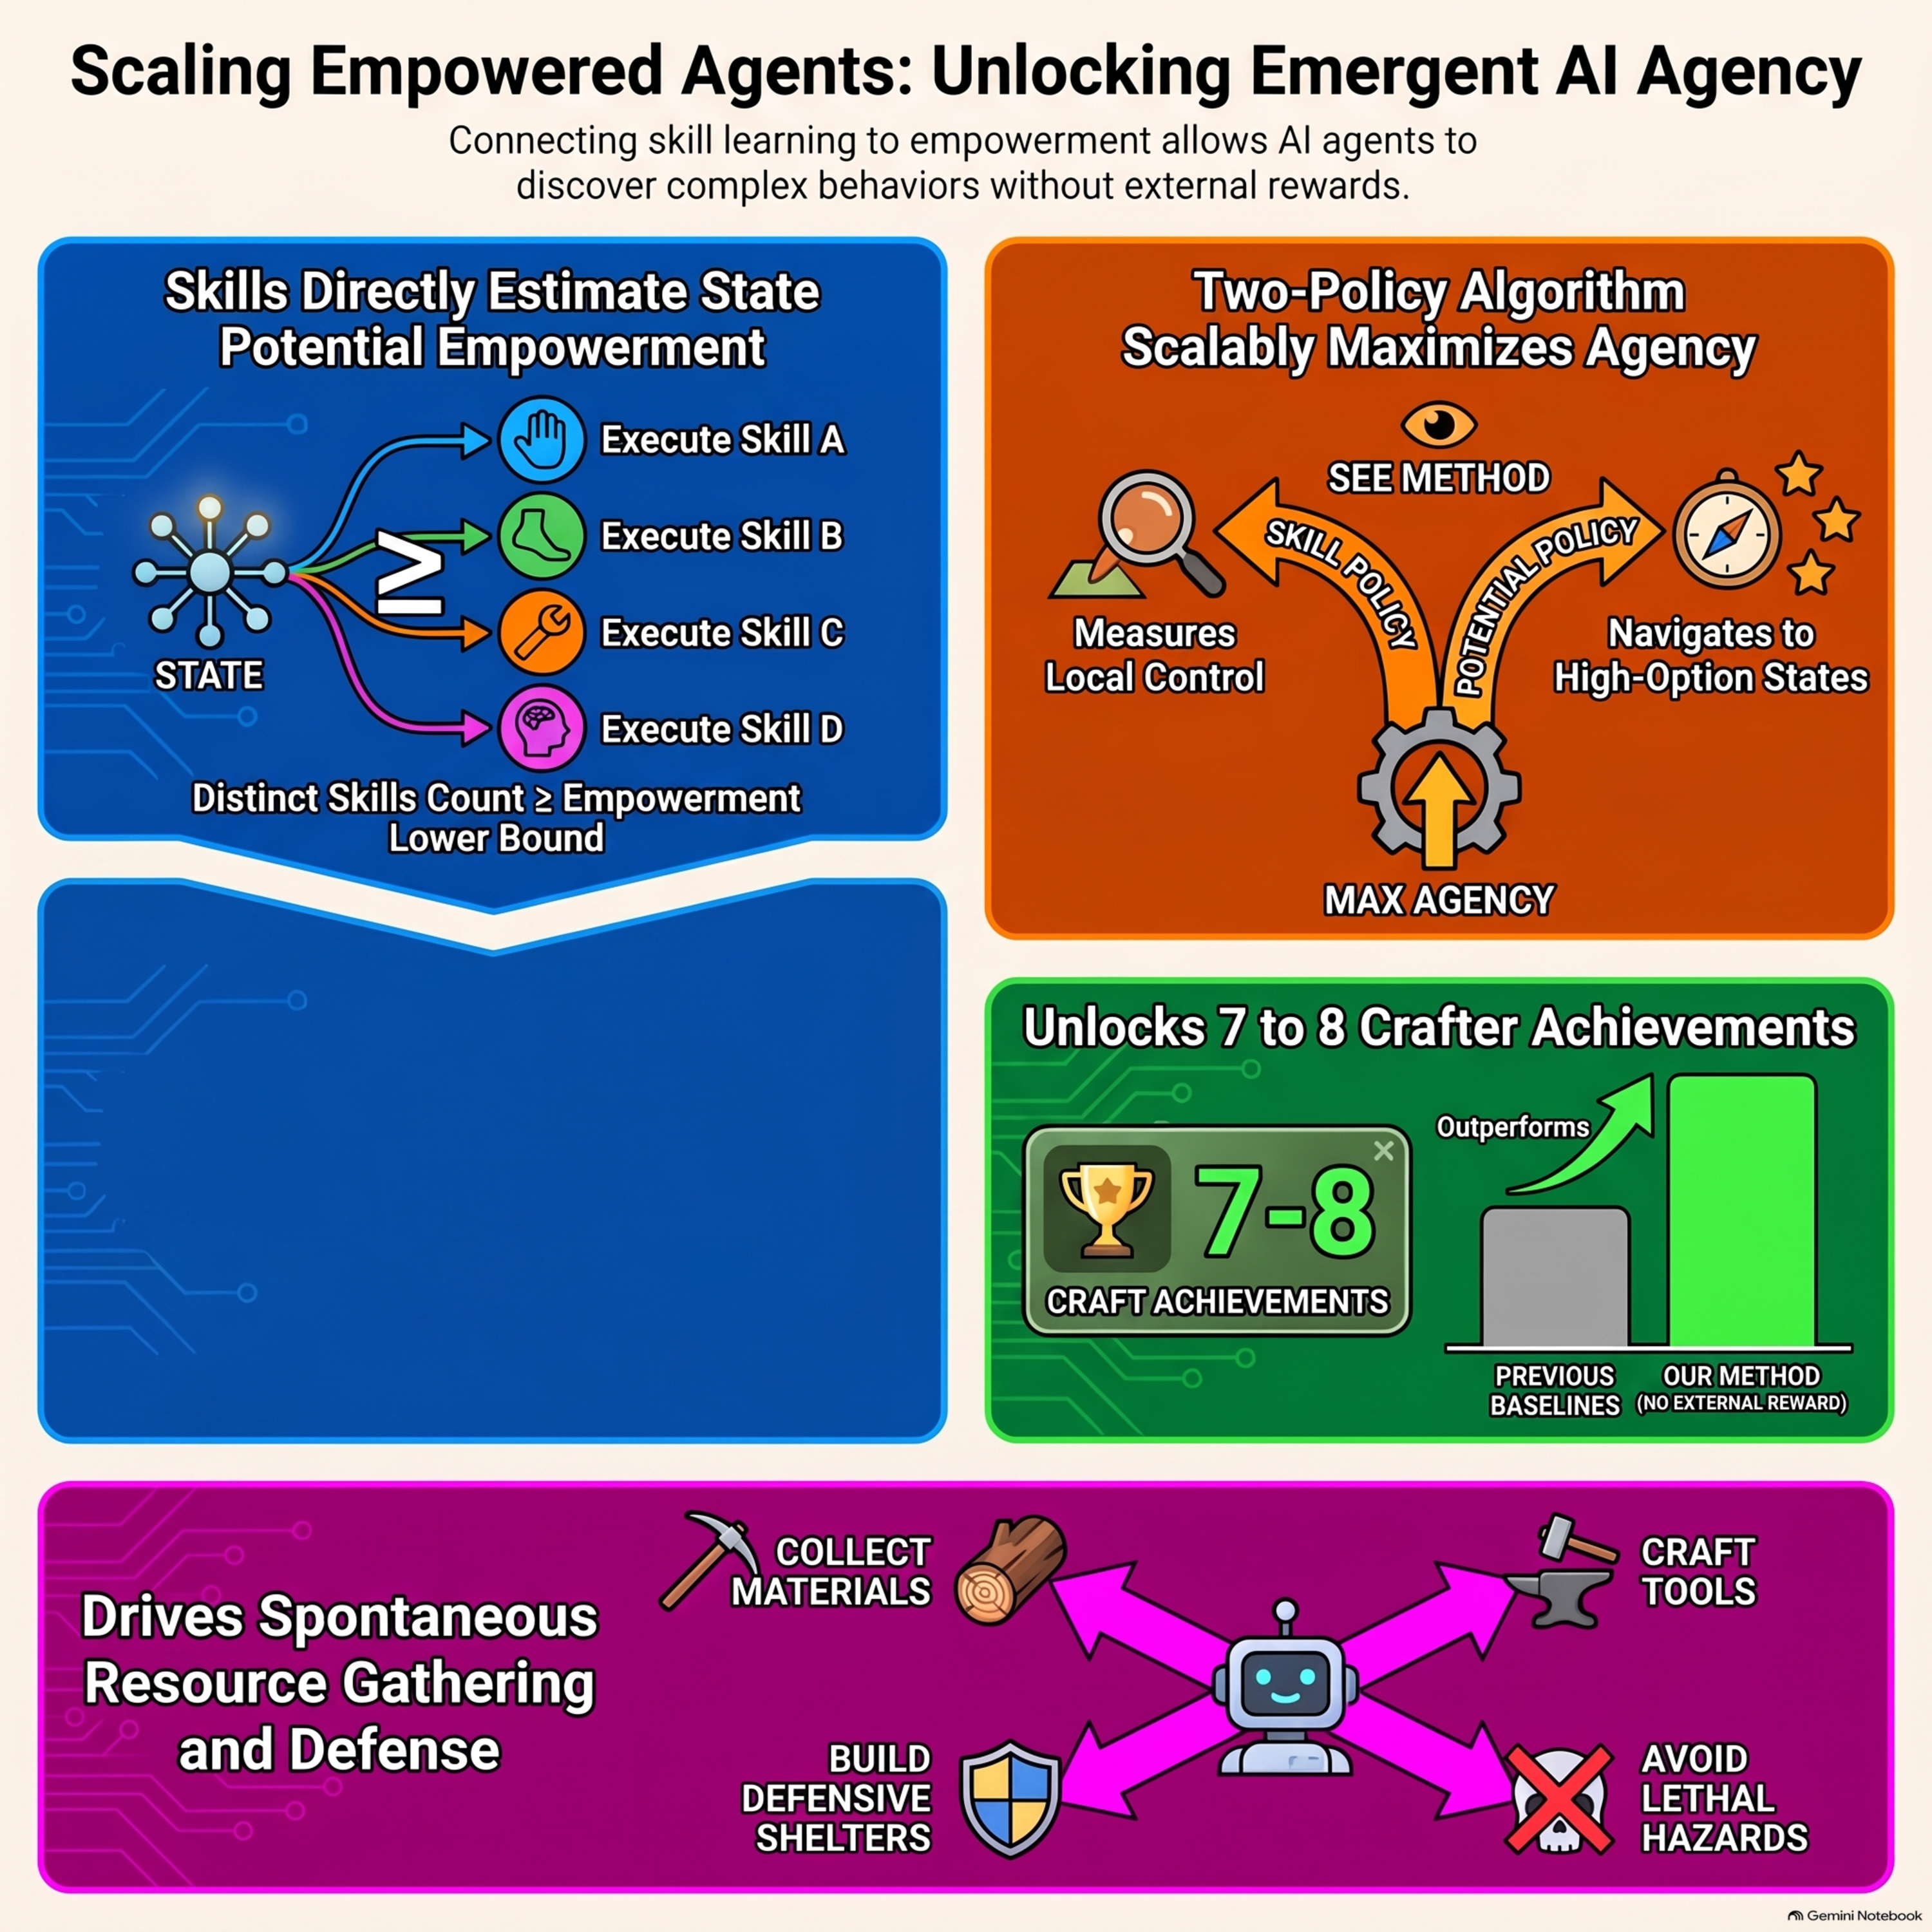
The episode explains “empowerment maximization” for AI—agents that learn open-ended curiosity by maximizing how much control they have over future states, without external reward.
16 Oct 2026 · 25m · 11 chapters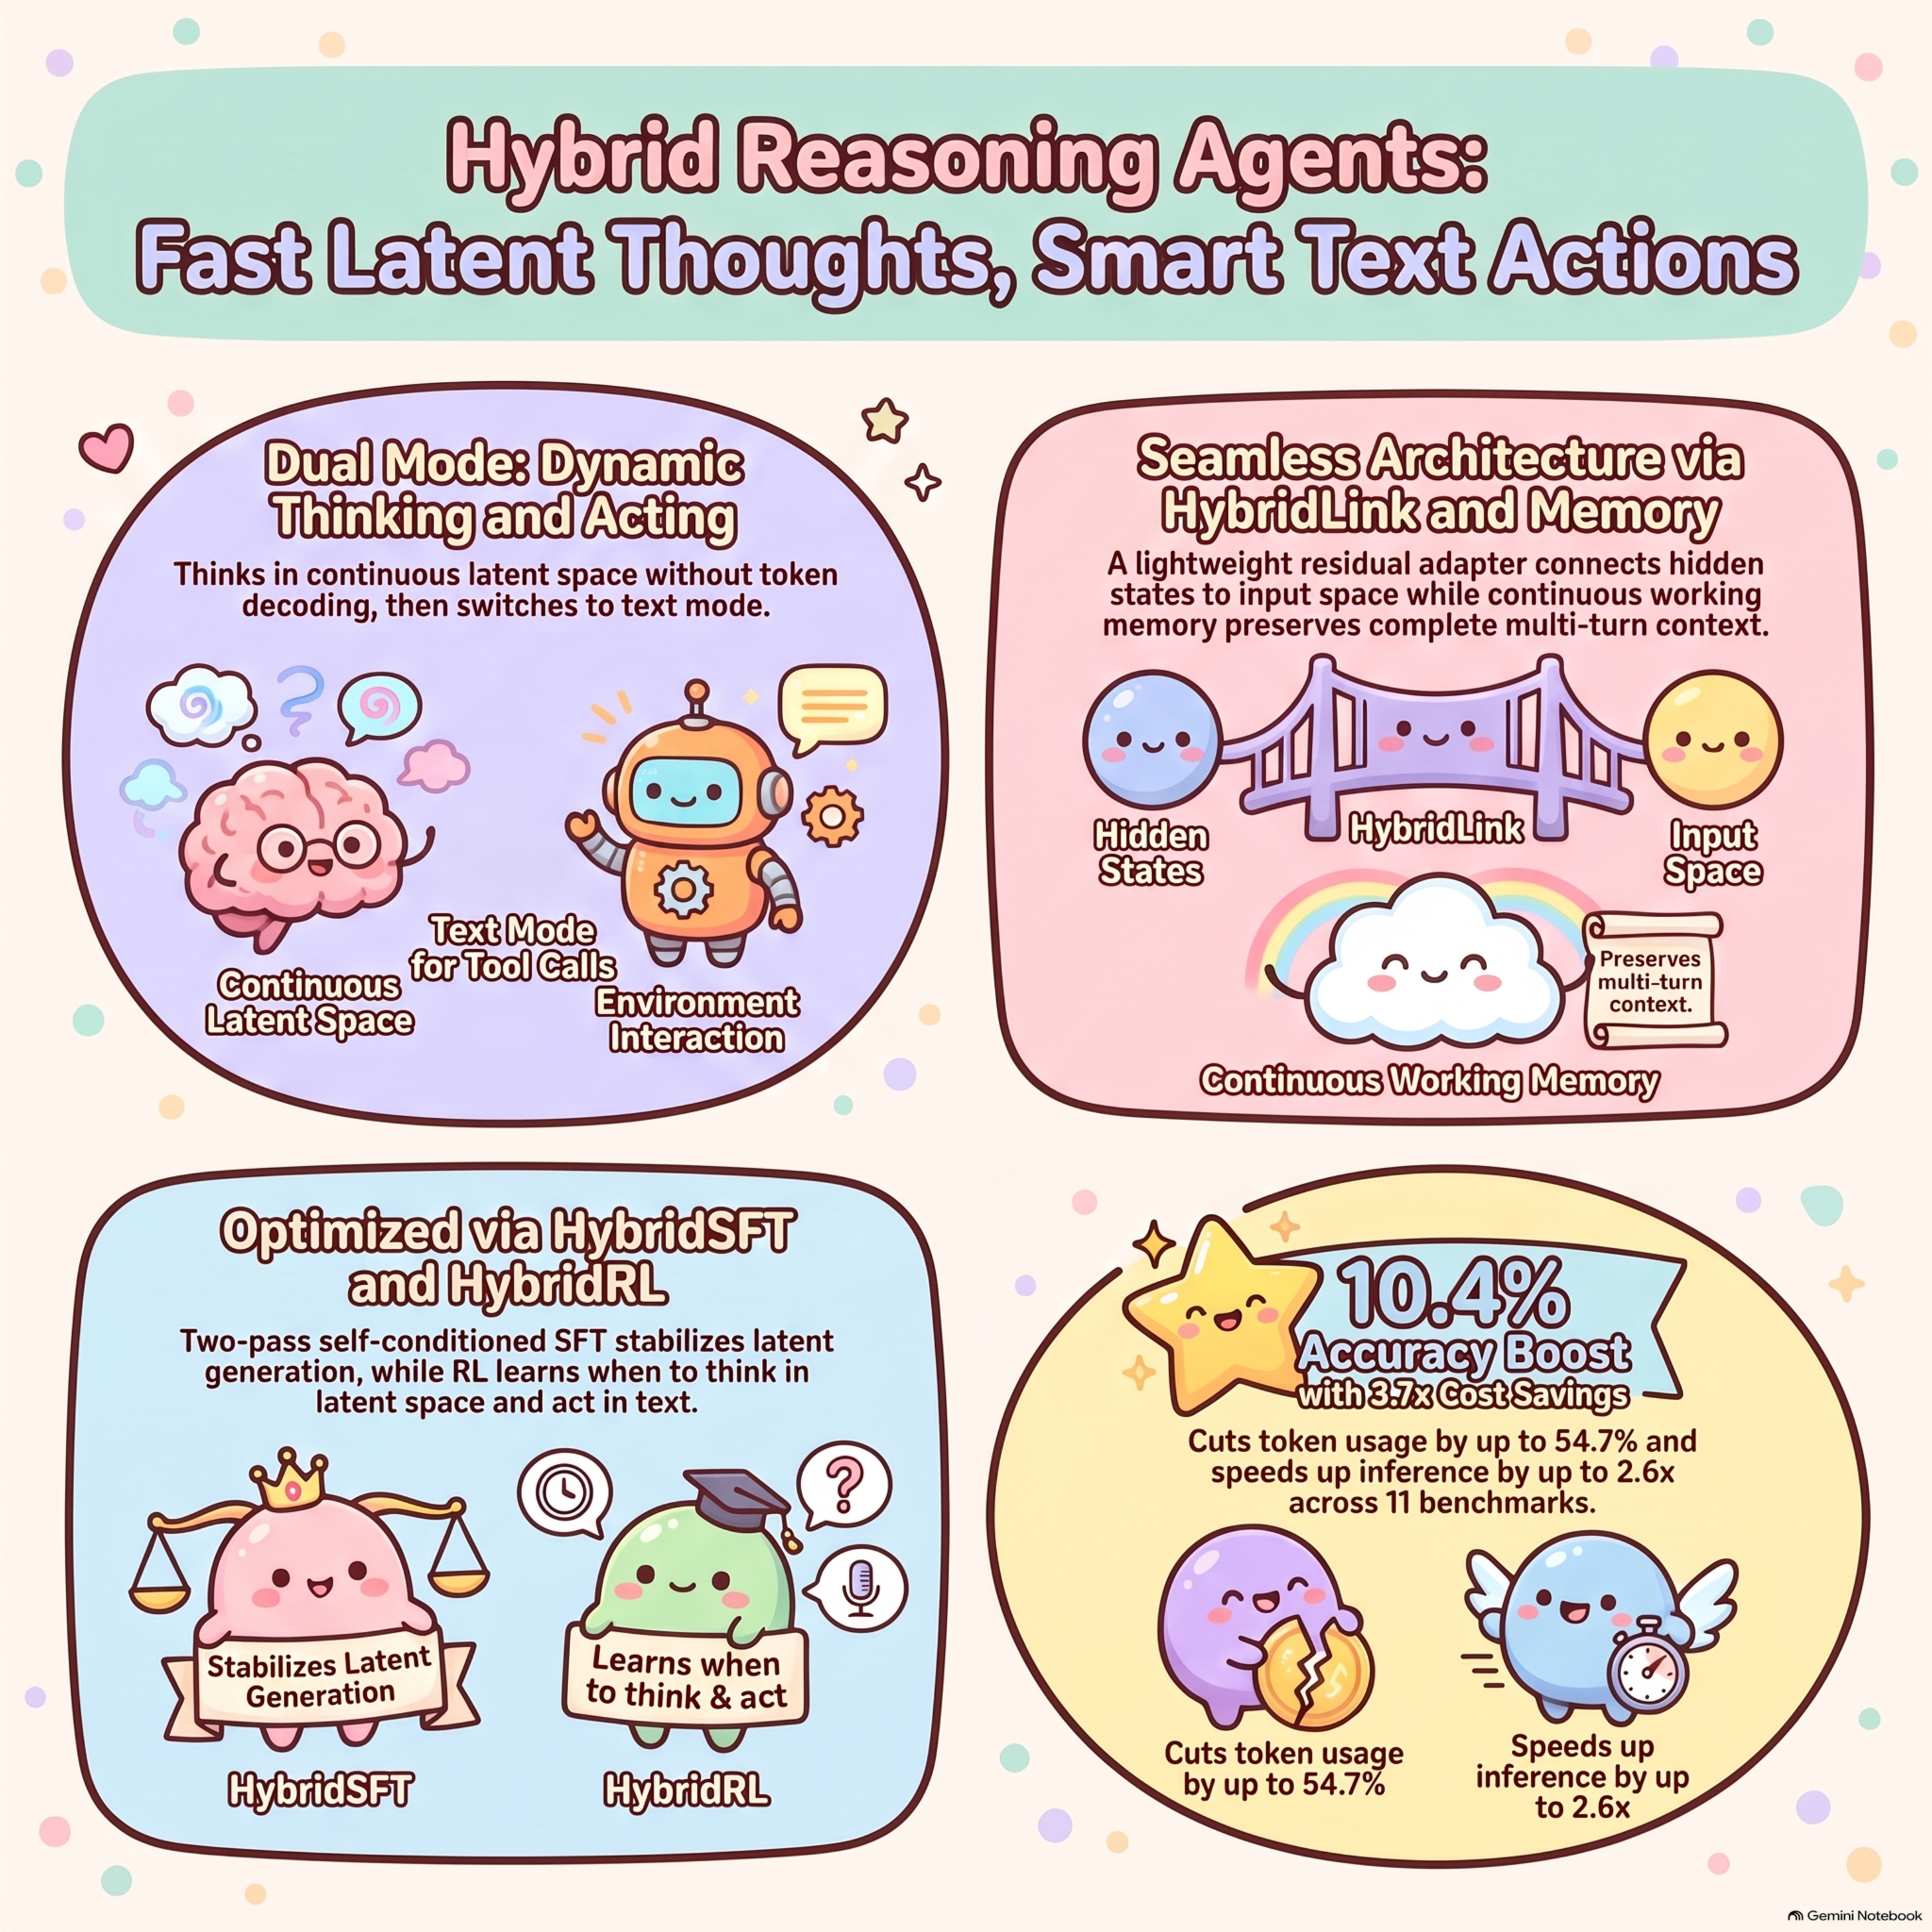
Hybrid reasoning agents that combine fast “latent” internal computation with external “text” tool use, avoiding slow step-by-step text reasoning while keeping debuggability.
15 Oct 2026 · 20m · 12 chapters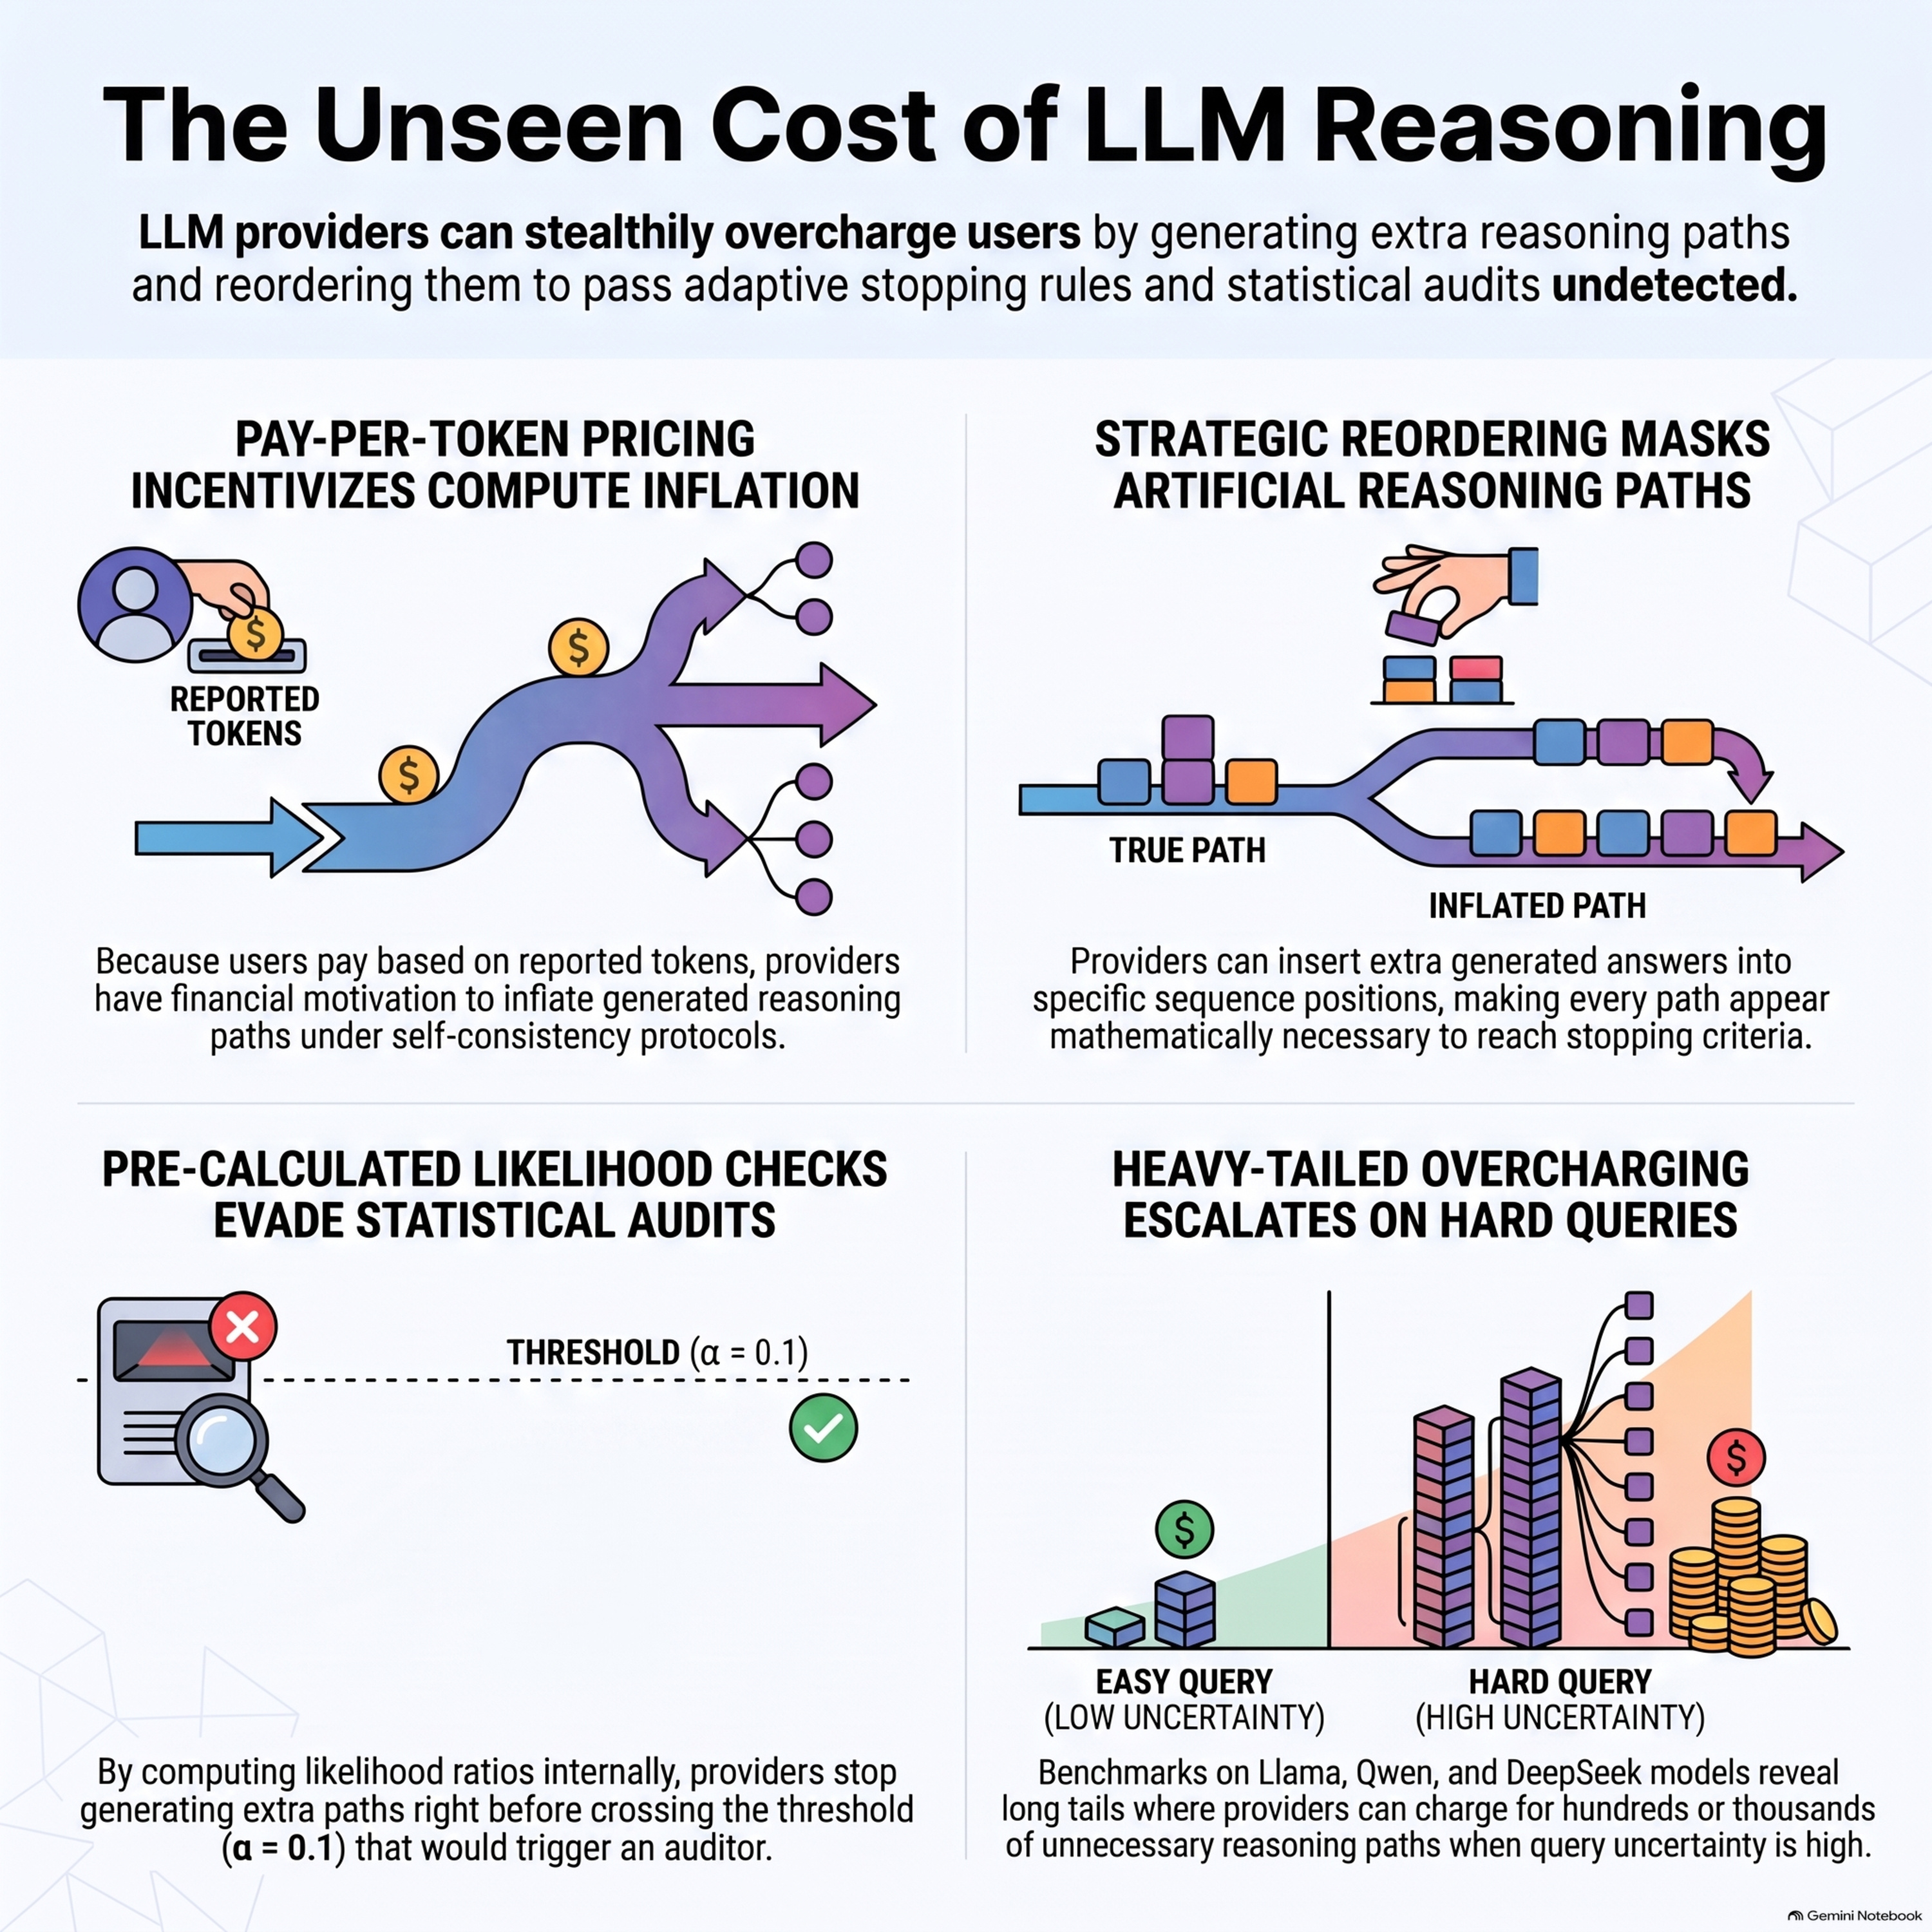
The episode argues that LLM-as-a-service providers can exploit “test-time compute” and self-consistency to overcharge users by artificially inflating billed reasoning paths while evading statistical…
12 Oct 2026 · 25m · 9 chapters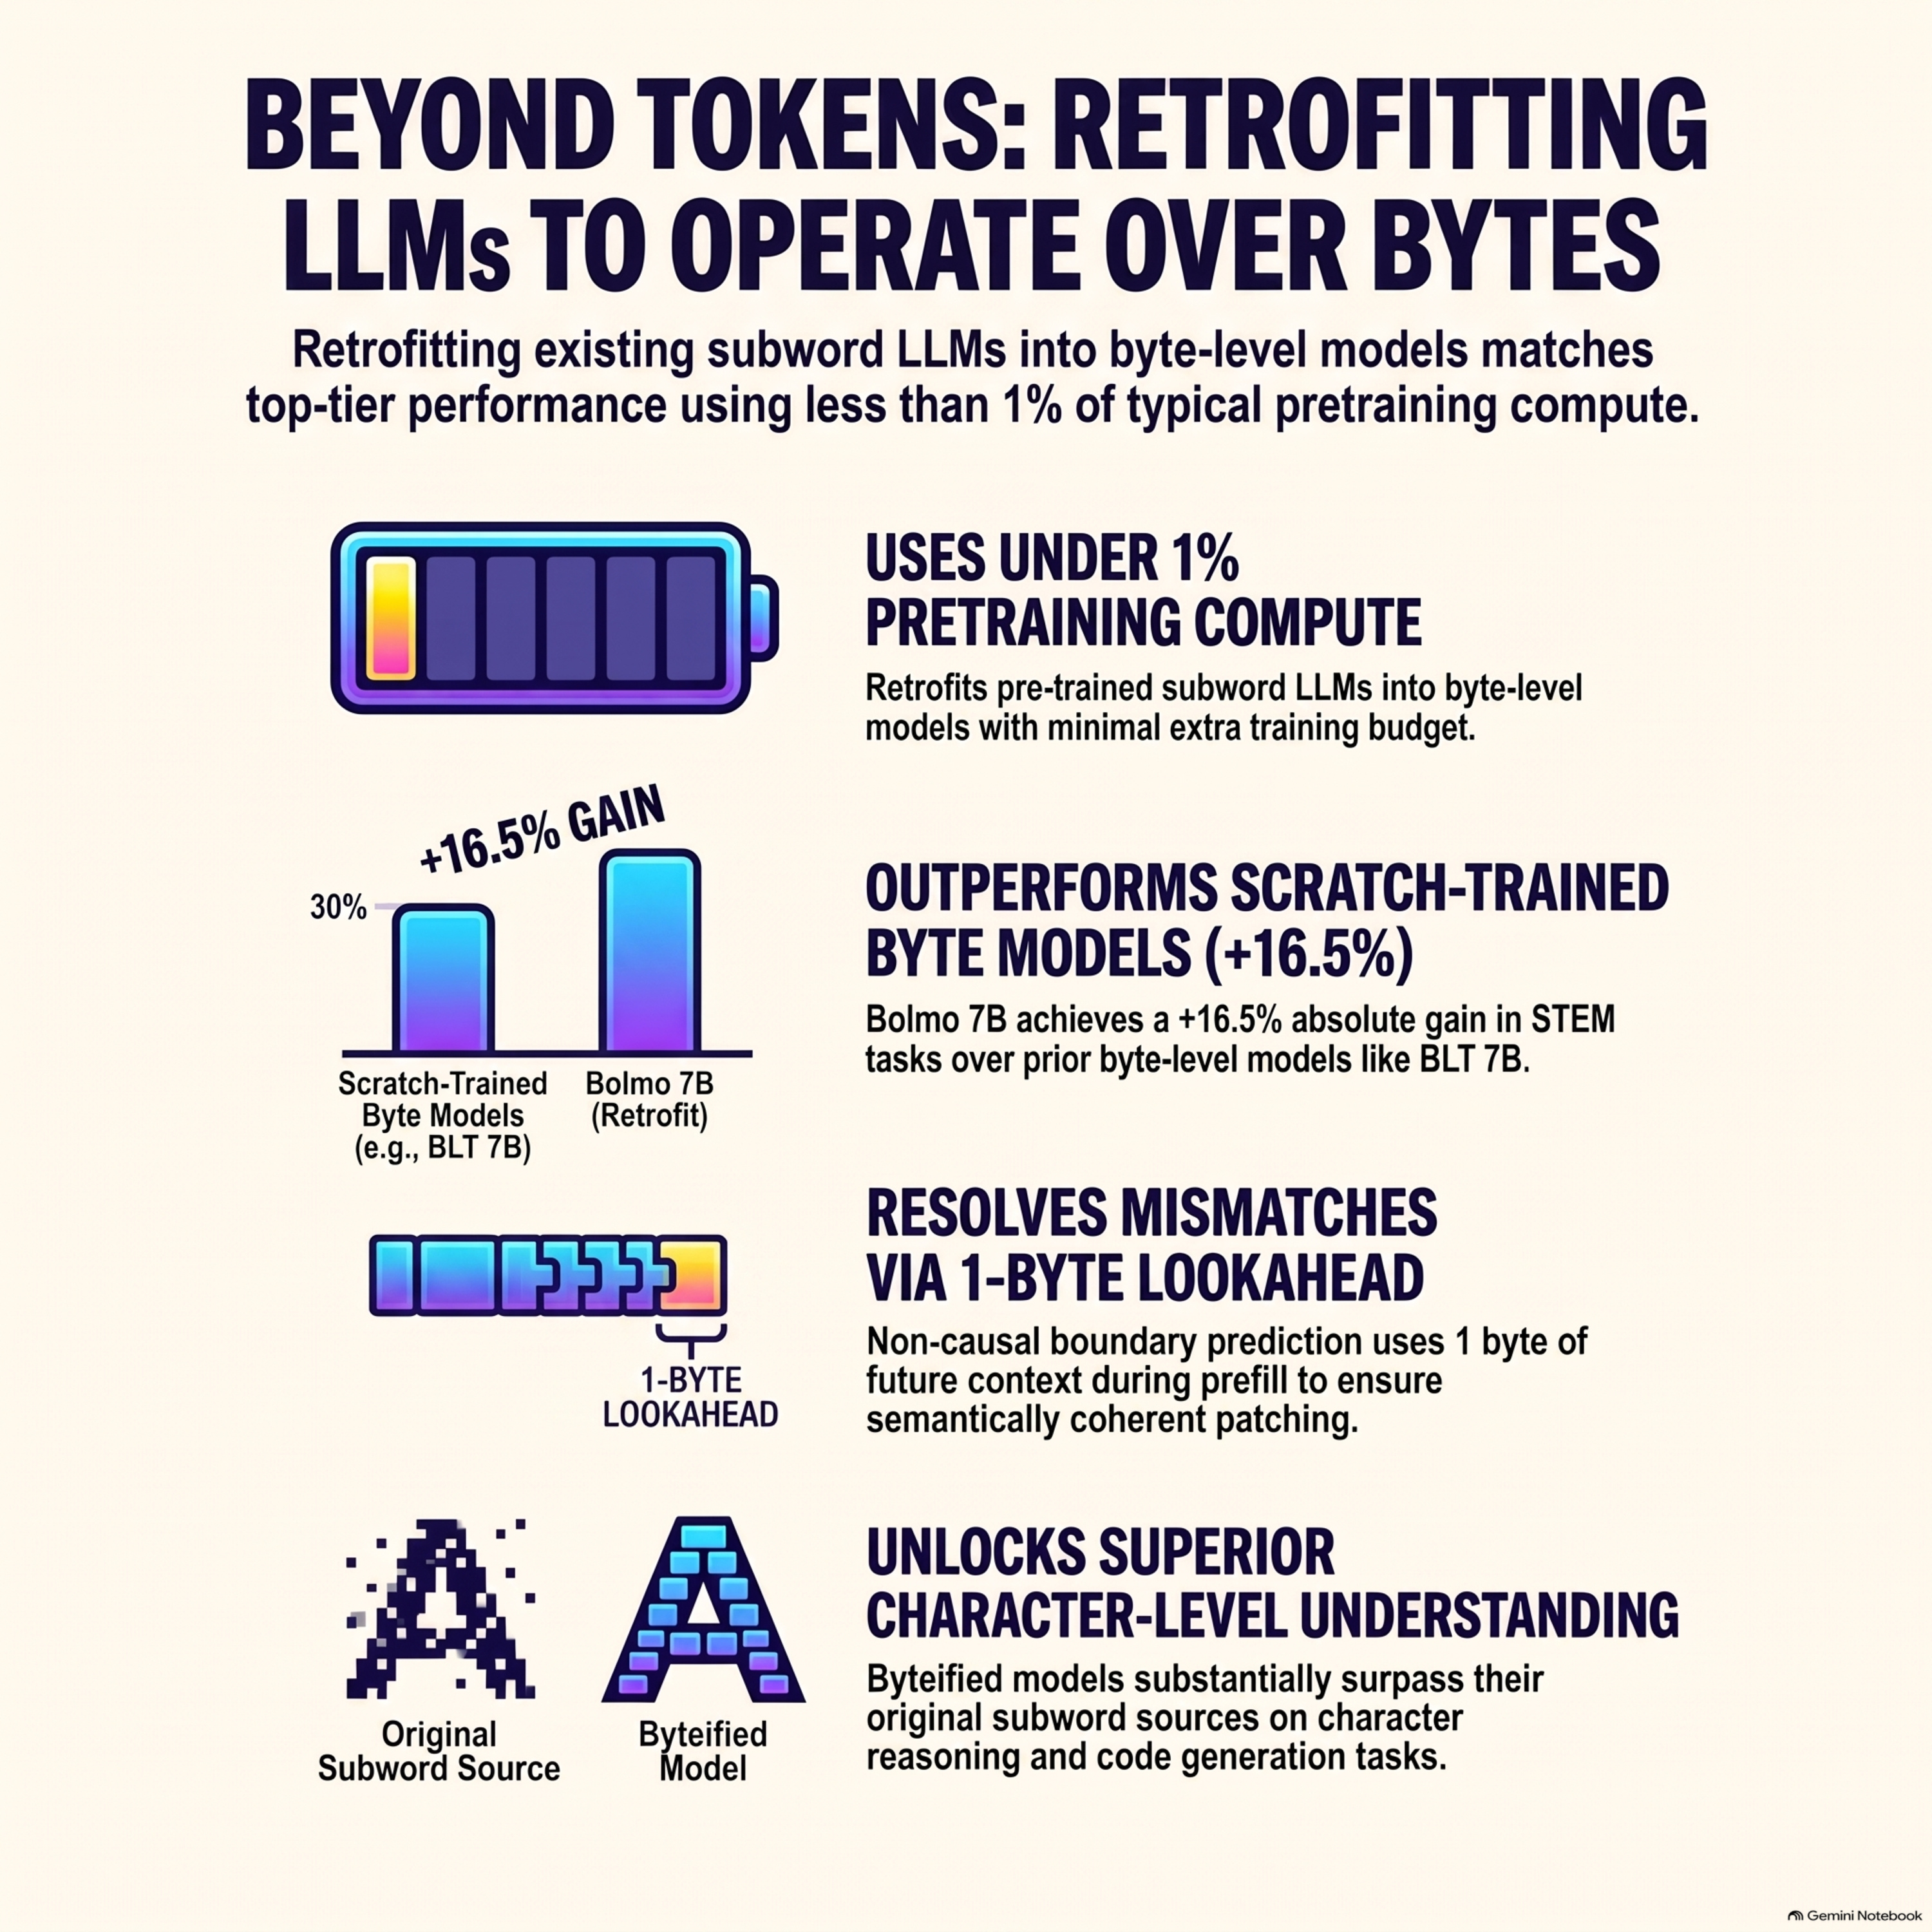
The episode explains “bitification,” a research method to retrofit existing subword language models so they operate over raw UTF-8 bytes instead of human-like subword tokens, improving…
11 Oct 2026 · 24m · 14 chapters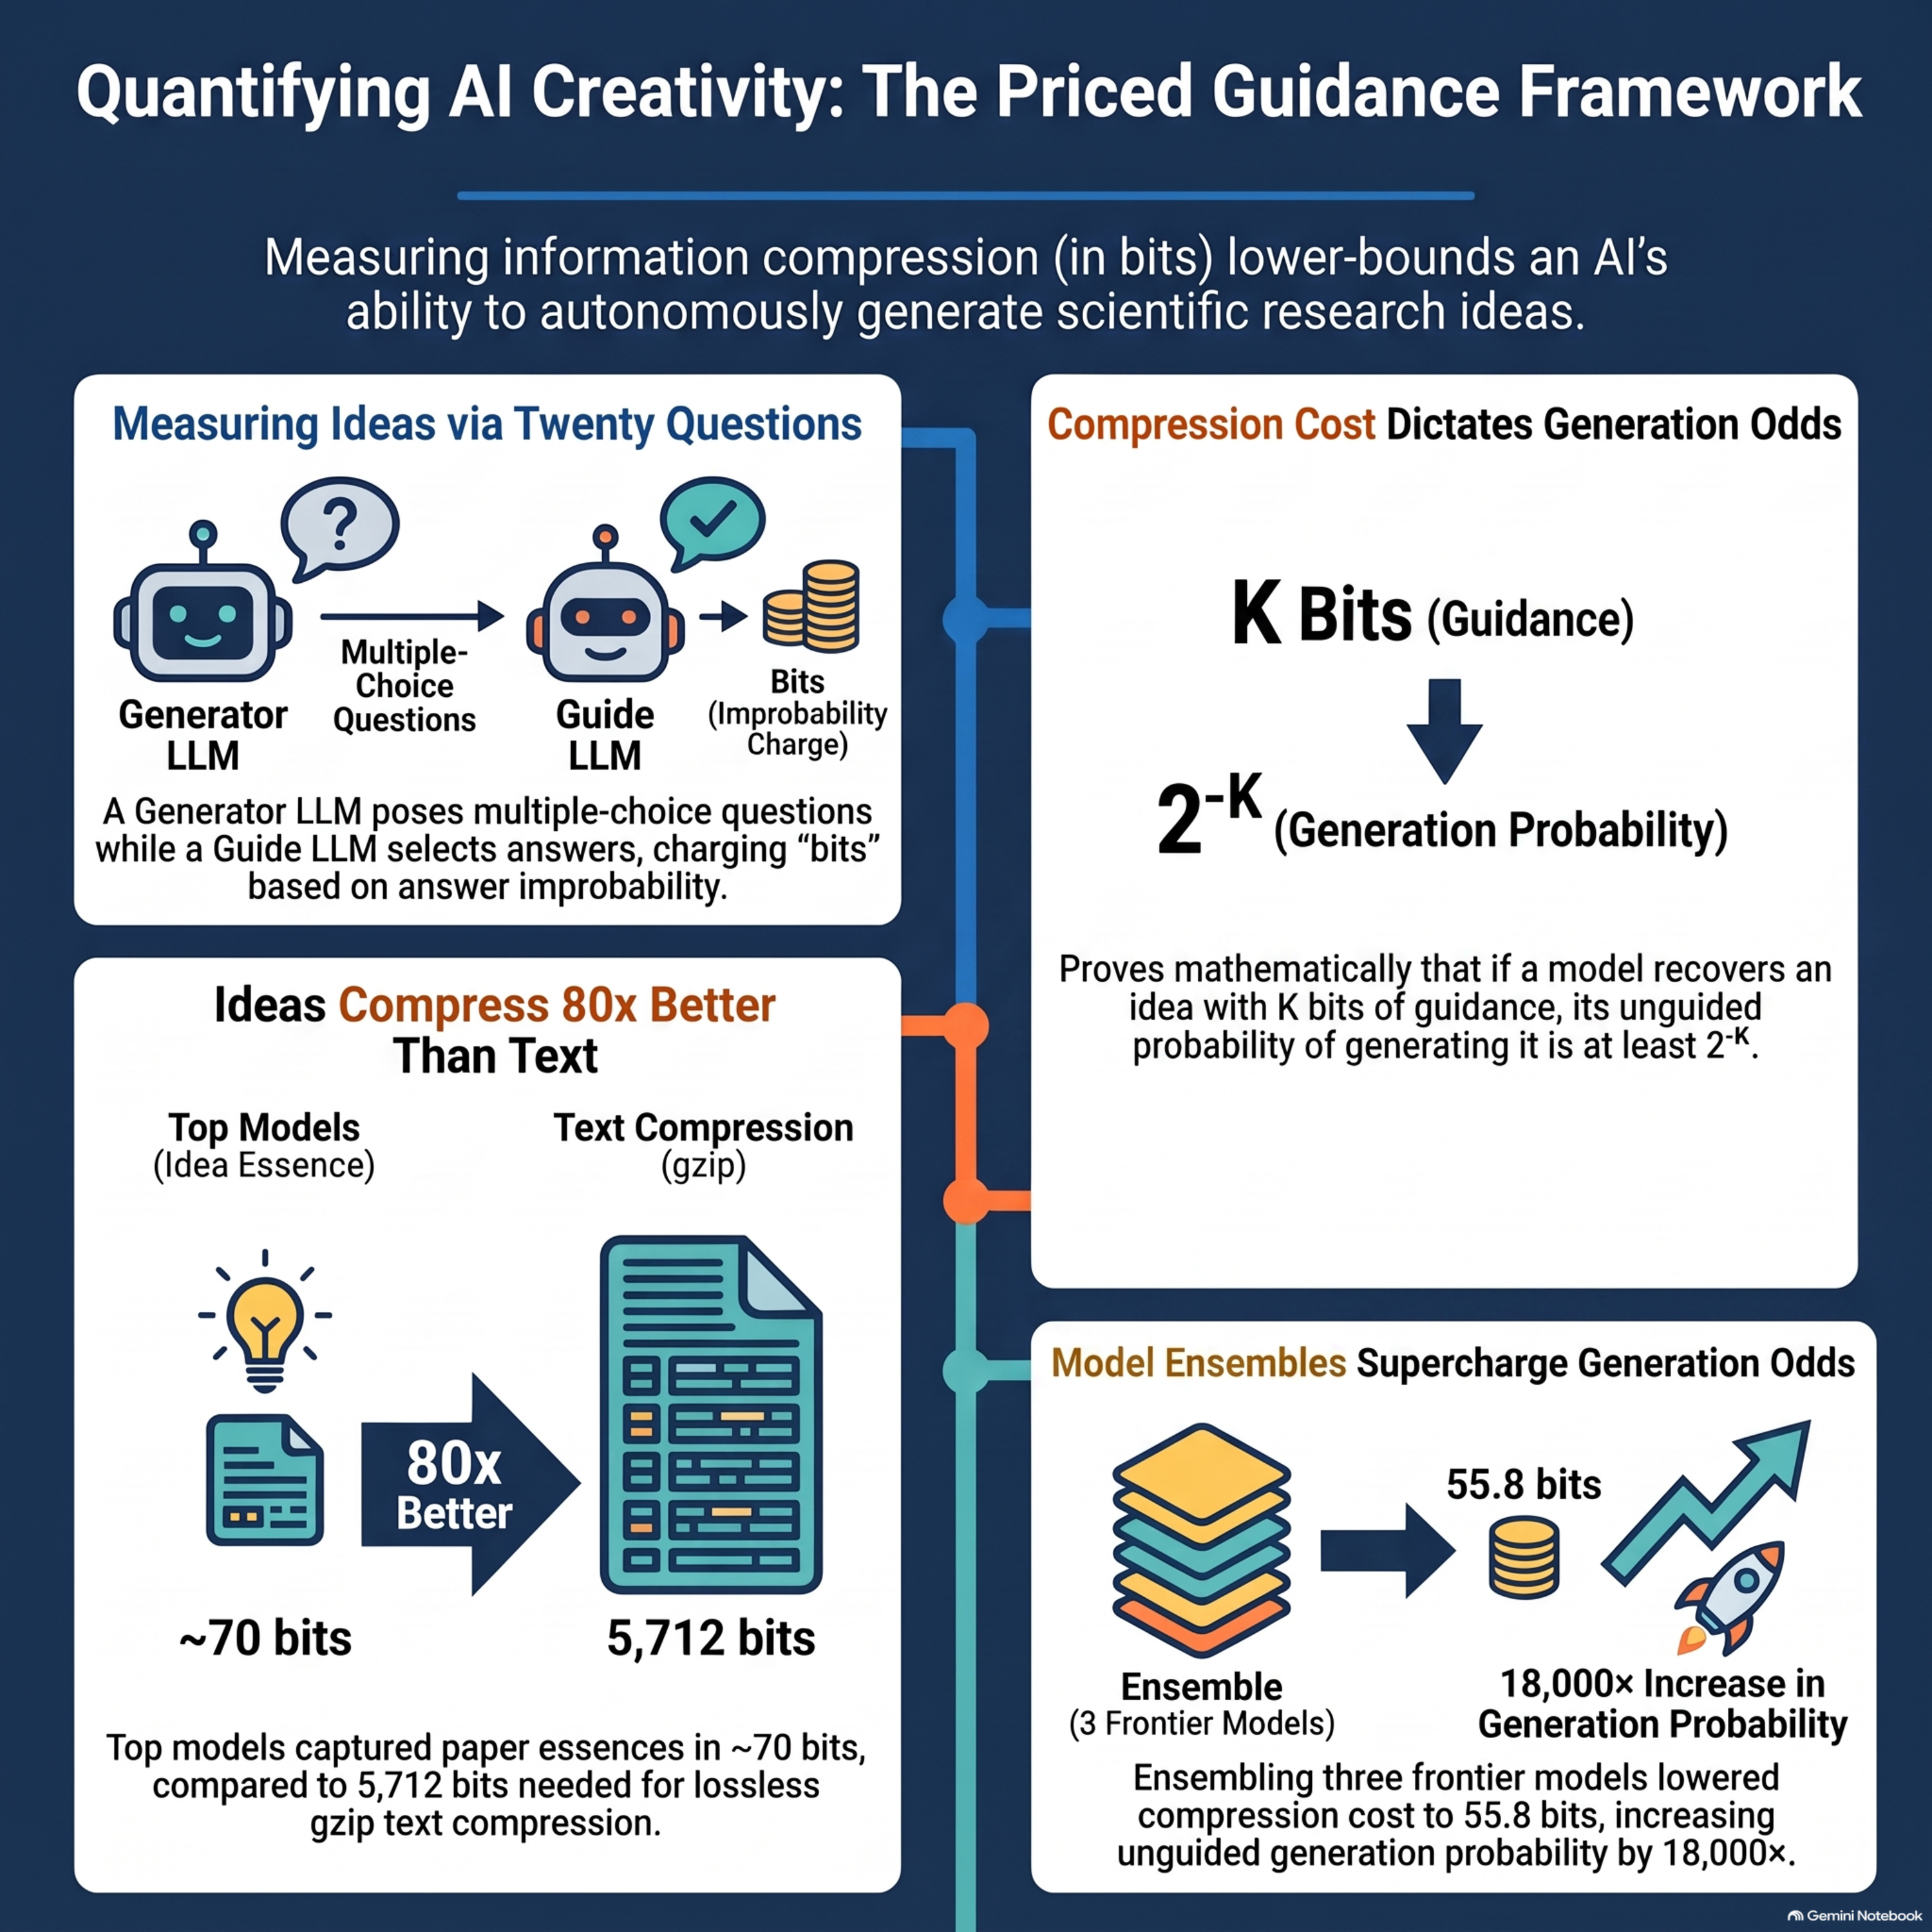
The episode explains a Stanford paper using “priced guidance” to measure whether language models can generate novel future research ideas, treating idea discovery as data compression/information cost…
10 Oct 2026 · 20m · 9 chapters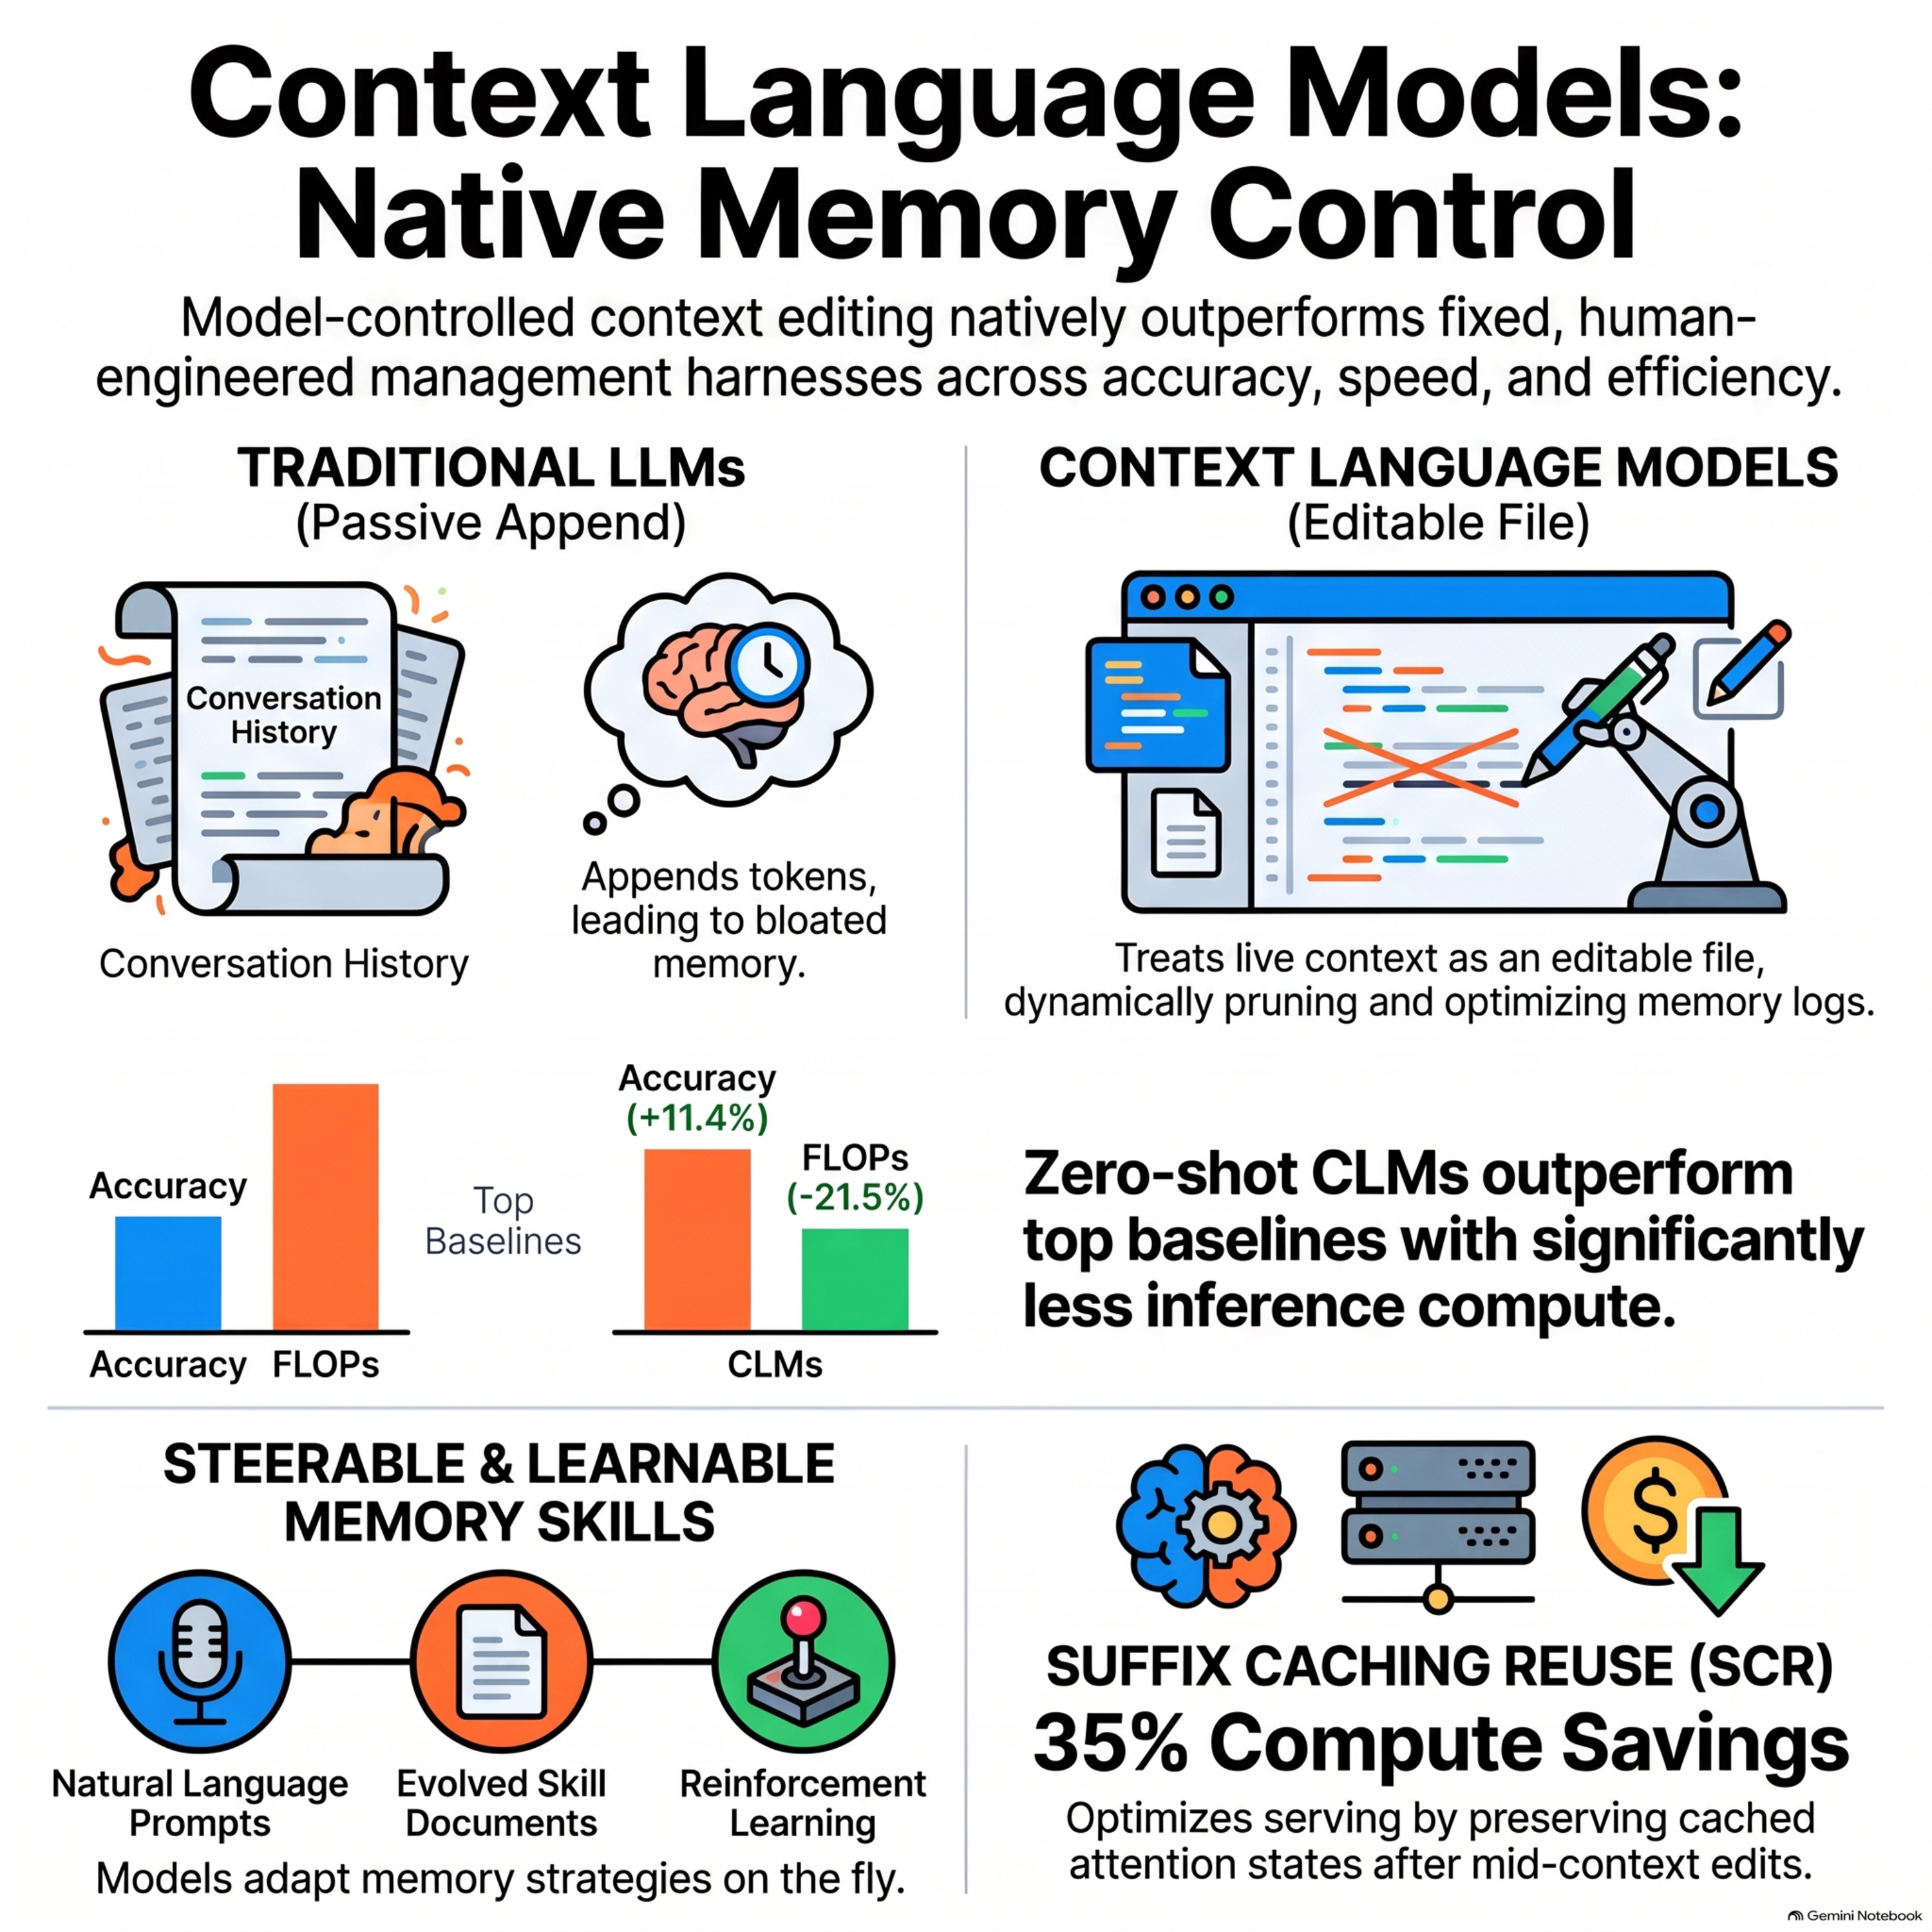
The episode explains the “context wall” in standard language models (limited context windows that only append text), then introduces Context Language Models (CLMs) that can edit/delete their own…
10 Oct 2026 · 22m · 13 chapters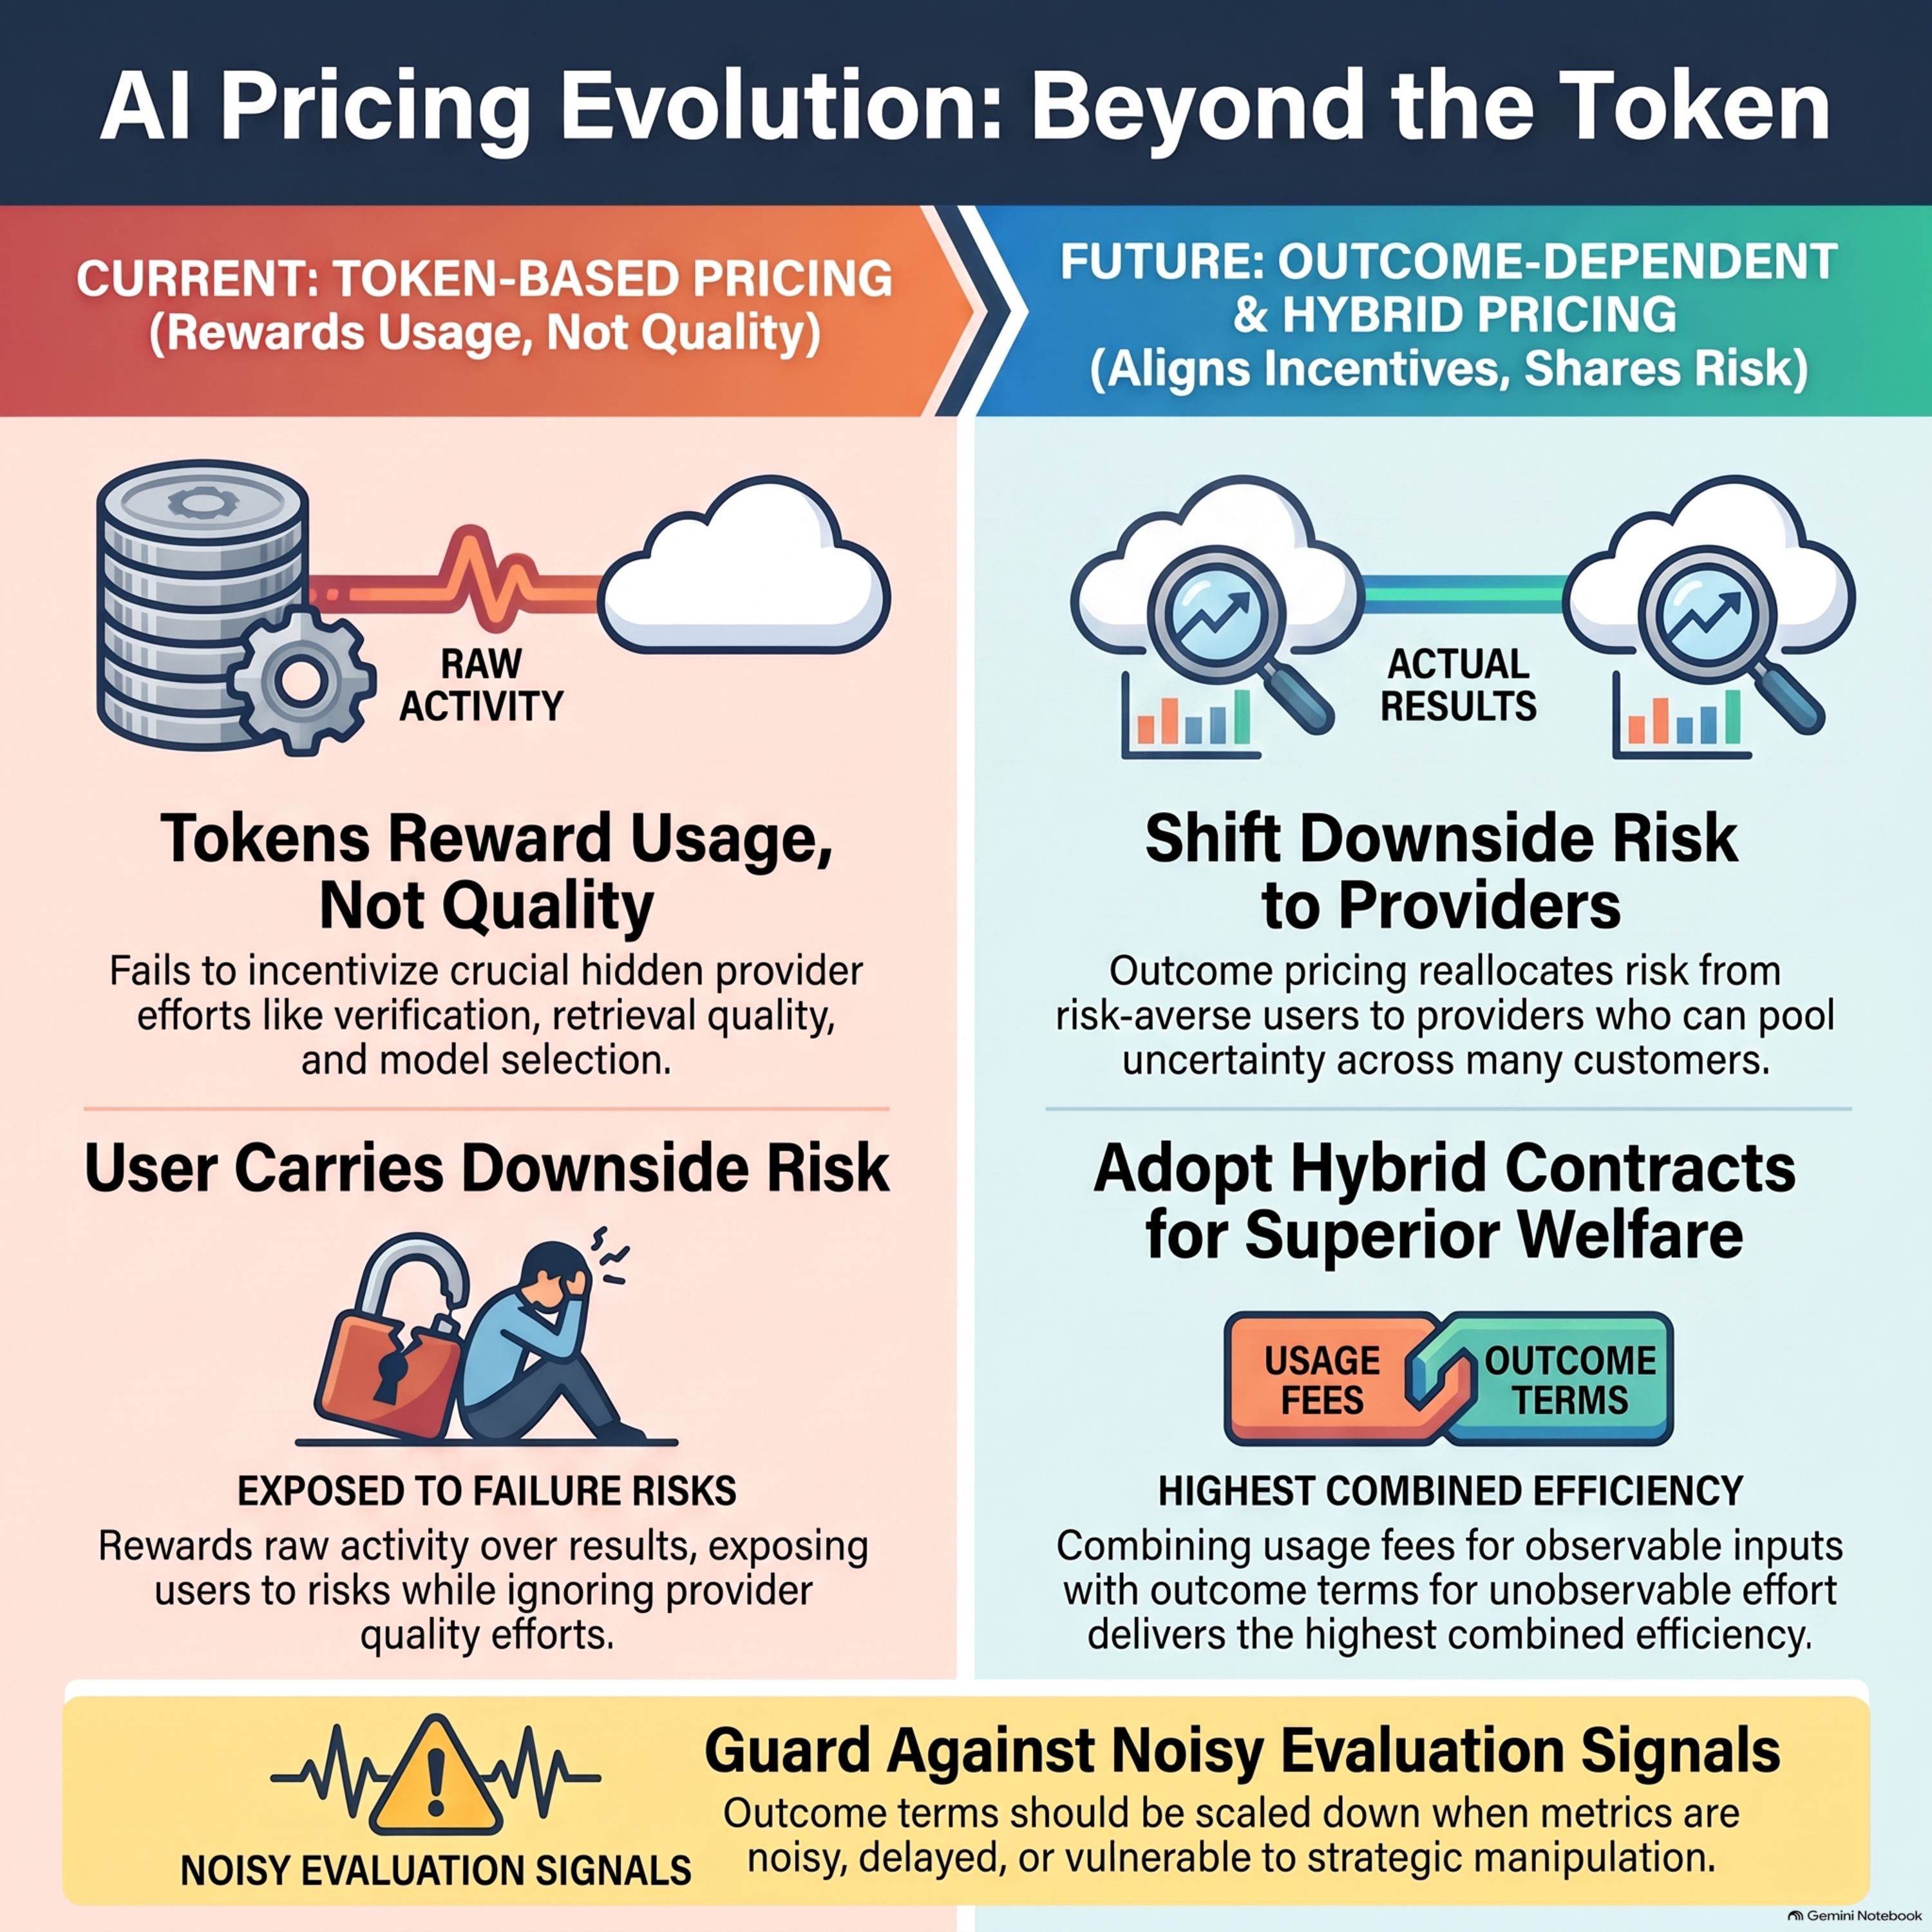
The episode argues that AI-agent pricing should shift from token-based (pay per word/compute) to more outcome-dependent contracts.
8 Oct 2026 · 23m · 11 chapters