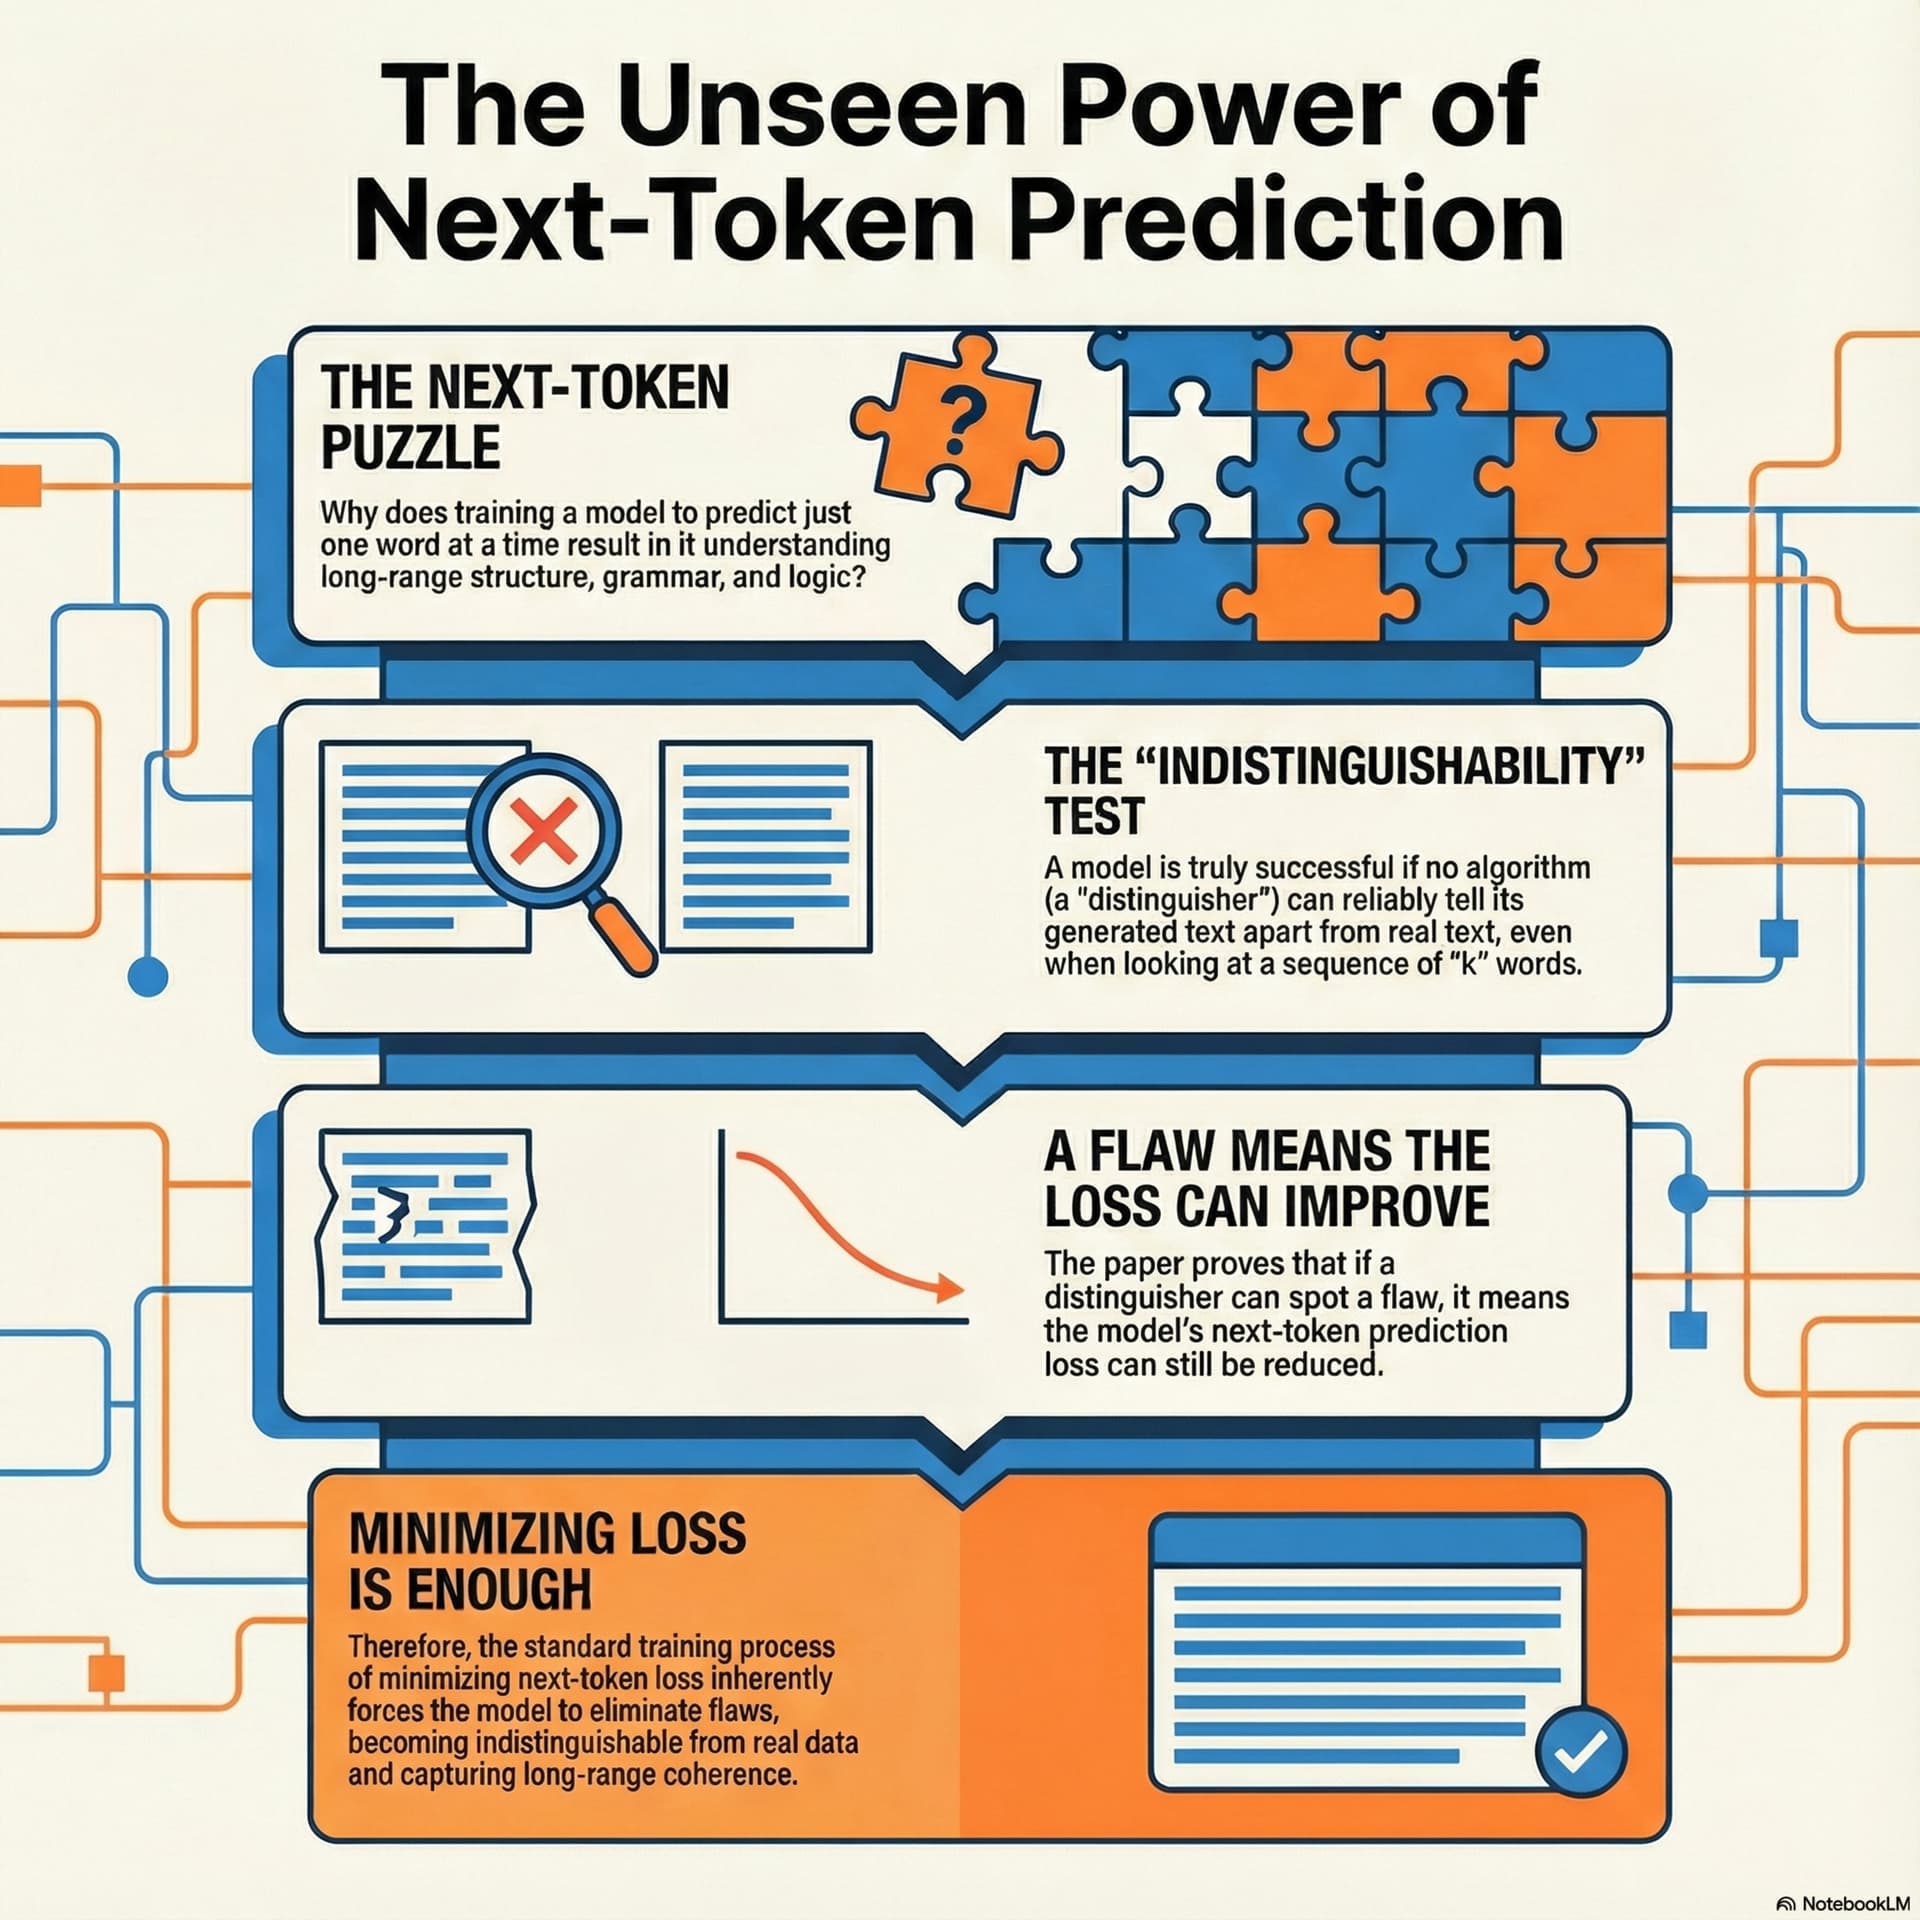

In short
A complexity-theoretic argument that autoregressive next-token prediction training can provably yield long-range structural coherence, despite being locally optimized and computationally bounded.
Guest backgrounds
No guests are named in the transcript; it’s a solo/hosted discussion between speakers.
Key claims
(1) Next-token maximization is local optimization, but a bounded “next-K token distinguisher” checker implies the model must capture long-range structure to avoid detectable errors. (2) “Self-boosting” means if a checker can spot flaws, training can reduce loss by incorporating the missing information. (3) Required model size scales polynomially with data complexity and K, not total document length; errors don’t accumulate into gibberish. (4) Guarantees don’t remove the computational wall for truly intractable tasks.
Notable examples
Factoring a large number (prime factors of 4999-013-9543R) illustrates where next-token models fail when they must perform NP-hard-like computation; bounded K-window coherence is contrasted with exponential-time algorithmic reasoning.
Written by AI. May contain mistakes. Listen to the episode to check what was said.
Chapters
Tap a time to open that second in VOThe Limits of Autoregressive Models
0:58 to 3:28
Understand how autoregressive models face challenges with complex tasks.
“And that tension is exactly what we're diving into today.”
Introducing the Next K Token Distinguisher
3:28 to 6:20
Discover a new method for measuring structural coherence in language models.
“This is, I think, the centerpiece of the paper, the next K token distinguisher.”
Self-Boosting Principle and Error Correction
6:20 to 8:11
Learn how the model corrects structural errors through a self-boosting principle.
“The existence of a structural error means the model is not yet at its minimal loss state.”
Scaling and Structural Guarantees
8:11 to 11:16
Examine how model scaling relates to maintaining structural fidelity.
“Now, we don't need to get lost in the specific formula, but the key insight is this.”
Theoretical Limits of LLMs
11:16 to 12:03
Understand the boundaries of LLM capabilities in solving complex problems.
“It guarantees coherence, but not necessarily timely efficiency for the really hard algorithmic problems.”
Transcript
Automatic transcript. May contain errors.0:00Every time you use a generative AI, you are witnessing, I think, one of the great complexity theoretic magic tricks of our time. It really is. Think about it. You ask an LLM, write me a 1 ,000 word analysis, give me headings, footnotes, a clear thesis. And what you get back is, well, it's structurally sound from start to finish. It's stunning. Absolutely stunning because the system that produced it is, it's fundamentally short-sighted. Right. Large language models are at their core trained on just one thing, predicting the very next word or the next token. Based on what came just before it. Exactly.
0:37We call it autoregressive training. And it's the absolute definition of local optimization. So the model is trained step by tiny step, just focused on minimizing its error on that one next word. But somehow it generates this globally coherent structure. It doesn't just trail off into statistical noise. It completes the conclusion. It completes the conclusion. And that tension is exactly what we're diving into today. On one side, you've got this pure information theory view. It says, well, if you perfectly maximize the probability of every next word, you theoretically maximize the probability of the entire document.
1:13Sounds clean enough. But that view completely ignores computation. So our mission today is to unpack the complexity theoretic proof that kind of resolves this, showing how even with real-world computing limits, that simple next-token objective forces the model to capture long-range structure. So the core question we're answering for you today is, how can we rigorously prove that this super local training method is powerful enough to guarantee the global document level coherence we see every day? To get there, we have to start by really accepting the computational wall. I mean, if the theory says next token maximization is enough, why does that break down in the real world?
1:53Right. Because if it was always equivalent, we wouldn't need a proof, would we? We just, you know, trust the math. But the math falls apart the second you ask the model to do something that's actually algorithmically hard. Precisely. Let's take the example from the source material. It's a really vivid one. Imagine prompting a model with something computationally heavy, like the prime factors of 4999-013-9543R. Whoa, that's a huge number. It is. And look, if the model saw the answer in its training data, fine, it can just parrot it back. But if it hasn't... It has to actually do the math. It has to perform high-level mathematical factoring to complete that sentence correctly.
2:30And that process is just computationally intractable after a certain point. So an autoregressive model, which is operating in polynomial time, its computation scales pretty reasonably, it can't be expected to solve an NP-hard problem on the fly, not just by guessing the next token. Exactly. The local training objective, that focus on the next word, it fails. It can't capture that essential long-range mathematical structure. Now, if we had a totally different kind of generator, say one that used a real algorithm to calculate the factors first and then print the text. It would nail it. It would succeed.
3:03But the LLM, because of how it's trained, has to fail as the task gets harder. Okay, so this really sharpens the problem. We know that these computational limits stop next token training from capturing all structure yet. We see LLMs writing perfect novels. So we need a rigorous explanation for why the coherence we do get is a reliable outcome. And to get that rigor, the researchers introduced a new way to measure this, a way to measure structural coherence that actually respects these computational limits. This is, I think, the centerpiece of the paper, the next K token distinguisher. I love that name.
3:40So we're not aiming for perfection. We're aiming to be resilient against being checked. That's the key shift in thinking. Forget proving the model is perfect over an entire document. Instead, we introduce a powerful but bounded checker. Go ahead. Think of this checker like a very strict quality control manager, but with a tiny clipboard. He only inspects the last few steps on the assembly line. Exactly. This manager, the distinguisher, it looks at a fixed bounded window of, say, K equals 50 tokens that the model just produced. And its only job is to spot if the model's text violates some specific, predefined structural property of real human writing.
4:14So if that 50 token window has a grammatical collapse or a factual error you could easily look up, or just a logical jump that makes no sense, the checker flags it. It assigns a one, an error found flag. That's the mechanism. And what's so powerful here is how it connects to real world evaluation. I mean, so many of our current LLM evaluation metrics, factuality scoring, coherence tests, grammar checkers, they can all be formally modeled as these computationally bounded K-token distinguishers. That makes perfect sense. They don't read the whole 5 ,000 word essay. No. They're just verifying the claim in the last paragraph.
4:50And the paper builds on this classical computer science link. If you have a reliable way to distinguish flawed output from good output, that flaw must represent some missing information. Information that could have been used to make a better prediction in the first place. So, if a powerful checker can easily spot errors. It means the model's local next token prediction isn't done yet. The loss can still be reduced. The logic is kind of circular, but it's brilliant. If I can prove you made a structural mistake, I'm just proving your next word predictor is suboptimal. And that brings us to the main finding, the self-boosting principle.
5:26This is the magic part that guarantees minimizing local loss inherently forces the capture of long-range structure. Okay, let's unpack that. Let's look at the mechanism. If the local training loss, the model's bread and butter, is just about predicting the very next word, How does that pressure translate into a defense against errors spotted, you know, 50 words down the line? This is the elegance of the proof. It shows that the training process itself acts as an automatic continuous booster. A booster. Yeah. So if a checker, a distinguisher is found that can spot an error with a noticeable statistical advantage against the model, the math provides a way to automatically leverage that discovery to build a new improved model.
6:08So detecting a structural flaw, like that grammatical train wreck you mentioned, is immediately translated back into a signal. A signal that says, hey, your prediction 50 steps ago was terrible, and here's how you can reduce your overall loss now. Exactly right. The existence of a structural error means the model is not yet at its minimal loss state. The proof shows you can always boost the model by an amount proportional to that detected error, which forces the training system to find the information it needs to neutralize that inconsistency. Wow. So the next token loss minimization objective just, it swallows the structural requirement whole.
6:43It does. And this is where it gets really fascinating for you, the listener. The training algorithm itself is constantly and unconsciously searching for the strongest possible structural checker that could expose a flaw. And then it immediately incorporates the fix. So the simple act of trying to reduce next token prediction error is, in fact, an exhaustive search for latent structural coherence. It is. And the researchers also showed how efficient this is. They found that with very high probability, the optimization algorithm doesn't need to try endless configurations. It often just needs to check a small number of model sizes before that loss reduction is met, mathematically guaranteeing the result is sound against all these bounded checkers.
7:23That's a fast path to global coherence. A very fast path. And it provides the theoretical backing for why scaling works so well in practice. We're just giving the model more capacity to embody the defense it needs. So let's move to the practical implications of the complexity bounds, because this is where the theory gives us this really powerful guarantee about long documents. Okay, so we've established the mechanism works, but does it scale? My biggest fear is always that if I ask for a 5 ,000-word document, these tiny errors are just going to accumulate until the ending is total gibberish. That was the traditional worry, right?
8:00The accumulated error problem. This proof just dismantles that. It provides precise constraints on the model size needed to achieve this indistinguishability. Okay. Now, we don't need to get lost in the specific formula, but the key insight is this. The necessary model size scales polynomially with two things, the complexity of the data and the size of the checking window. What about the thing it doesn't depend on? The total document length. That's the one. Precisely. The size required is entirely independent of the document length, Dan, as long as you decide that structural fidelity over, say, a 100-token window is good enough.
8:39The model is mathematically guaranteed to generate documents of any length, one page or 10 ,000 pages. that remains structurally indistinguishable within that 100-token window. That is the ultimate structural guarantee. It's saying if the model is good enough to pass the 100-step test, it's good enough to keep passing that test indefinitely. The errors don't pile up into chaos. Think about multi-step reasoning. If you train an LLM on correct mathematical proofs, the theory shows that minimizing next-token loss with a model of a certain size is enough to make sure that model generates correct derivations for any output up to length.
9:13Oh, so when we scale model size, we're just increasing K. We're forcing it to capture coherence over larger and more abstract windows. You got it. This confirms that the massive investment in scaling models is fundamentally sound. It's not just about statistical fluency. It's about buying the mathematical capacity needed to defend against these powerful structural inconsistency checkers. So it's not a cheat. It is not a cheat. And in fact, the researchers addressed a potential technical cheat. They checked if the model was sort of hiding the complexity by using astronomical memory requirements, like infinite bit size or something.
9:47Okay, so infinite precision. Right, and theorem two confirms the guarantee still holds even with bounded memory. You only need a polynomial increase in memory, and it's still independent of the total document length. The system can't sidestep the computational limits by using infinite hidden memory. So we have come full circle. We started with the paradox. local training, global coherence. And what this proof shows is that the standard simple training objective local next token prediction is actually a hyper-efficient self-correcting process. It is. It inherently contains this powerful mechanism that forces the model to achieve global structural coherence just by minimizing the advantage of any possible local window checker.
10:31The paper proves LLMs are not just glorified statistical parrots spitting back patterns. No, they're systems whose fundamental training loop acts as a complex theoretic shield against structural errors. It's continuously pushing them toward fidelity and structure. So what does all this mean for you, the listener? Well, you now understand that the long, coherent email or the perfectly structured essay you get isn't a fluke of statistics. It's a provable necessity, driven by the model's relentless quest to minimize its local prediction error against the threat of a small, focused structural check.
11:05And yet, and this is important, we have to remember the factoring example. Ah, yes. The wall. The wall. While this theory guarantees coherence up to a bounded complexity window, K, it also confirms where the LLM's power ends. For tasks that are truly computationally intractable that require exponential time, the theory shows that while the self-boosting mechanism will still work, the time required for the model to actually compute the next correct token could become impossibly long. It guarantees coherence, but not necessarily timely efficiency for the really hard algorithmic problems. And that boundary is the final powerful takeaway.
11:41We've mathematically clarified the difference between structural coherence, which is easily and provably captured with massive data and next token prediction, and true efficient algorithmic reasoning, which still requires different non-autoregressive structures. A perfect place to leave you to mull over the true computational limits of statistical systems. Yeah. Thank you for joining us for the deep dive.
From the publisher
This academic paper rigorously investigates the power of next-token prediction for training large language models (LLMs), specifically focusing on Recurrent Neural Networks (RNNs). The core finding is that simply minimizing the next-token log loss during training is sufficient to yield an LLM whose output is computationally indistinguishable from the true training distribution over long sequences of up to $k$ tokens, provided the model size is sufficiently large. The authors establish this through a complexity-theoretic approach involving "distinguishers"—bounded algorithms attempting to tell the generated text from real data. Crucially, the paper introduces a self-boosting" mechanism, proving that loss minimization itself drives the model away from being distinguishable, without needing explicit knowledge or training of a distinguisher. Furthermore, the analysis provides **polynomial bounds on the required model size and bit size** needed to achieve this long-range coherence.


