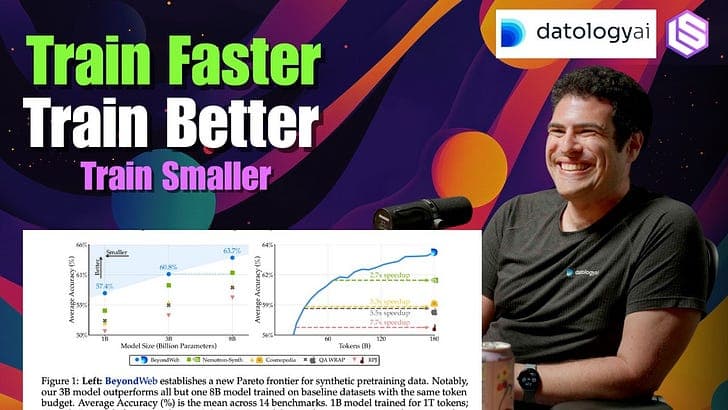

In short
Datology’s thesis that “models are what they eat” and that better data curation (not just better architectures) is the main lever for training faster, achieving higher benchmark performance, and using smaller models. Ari argues scaling laws fail when data is treated as IID/“all equal,” and that self-supervised learning created a new regime where massive unlabeled data brings redundancy and low-information samples—making automated data curation a frontier problem.
Guests
Ari Morcos, CEO/co-founder of Datology; PhD in neuroscience; previously a research scientist at Meta (2018–Sep 2023) and earlier work at GDM; focuses on making deep learning more “scientific,” moving from inductive-bias research toward data-centric learning. Interviewers include Alessio (Decibel CTO/partner) and Swix (Small AI founder).
Key claims
Data curation must be automatic and scalable to trillions of tokens; humans can’t reliably judge value because usefulness depends on relationships across the whole dataset; inductive biases matter mainly in small-data regimes (example: ConViT helps <500k images, fades around ~1M, can become harmful).
Notable examples
ConViT/ViT-CNN weight mapping; DCLM/DataCompLM study where expert students couldn’t predict automated filtering decisions above chance; elephants vs dogs redundancy analogy; Datology results: ~12x faster to match DCLM performance, +4–5 benchmark points vs best open datasets, and <half-parameter models outperforming larger baselines.
Written by AI. May contain mistakes. Listen to the episode to check what was said.
Chapters
Tap a time to open that second in VOUnderstanding Datology's Mission
0:46 to 1:59
Ari Morcos explains Datology's focus on data curation for machine learning.
“Yeah, so our mission at Datology is to take everything around the data side of machine learning, right?”
Ari's Journey into Data and AI
2:00 to 6:30
Ari shares his background in neuroscience and transition to machine learning.
“In the pre-chat before we started recording, you mentioned that there's a cool story around how you got into data in the first place, right?”
The Bitter Lesson of Data Importance
6:31 to 10:12
Ari discusses the realization that data quality outweighs model architecture.
“So if you see enough data, and the threshold at which this changes is around like a million data points.”
The Shift in Data Research Paradigms
10:13 to 14:00
Ari explains how the role of data has changed dramatically in AI research.
“You mentioned something about the incentives in the data not being aligned.”
The Evolution of Data Challenges
14:00 to 15:00
Understanding how data challenges have evolved from the 2010s to the 2020s.
“gain, all these various things that come with these massive unlabeled data sets.”
Insights from Meta and the Llama Models
15:00 to 16:00
A discussion on the insights gained during the development of Llama 1 and 2 at Meta.
“Like, okay, we should start to spend resources working on this.”
Complexities of Data Curation
16:00 to 17:00
Examining the complexities and challenges in data curation and its necessity for AI.
“And I don't think we still know how to solve that.”
Self-Supervised Learning and Automation
17:00 to 18:00
Exploring the role of self-supervised learning and automation in data processing.
“It's actually something I think about a lot is, are we actually falling prey to the bitter lesson again here by trying to have human guided methods of data curation?”
DCLM: A Case Study in Effective Data Curation
18:00 to 19:20
Analyzing the DCLM project and its implications for data curation practices.
“So given a data point, is the system going to say keep the data point or is it going to say reject the data point?”
The Value of Data and Human Limitations
19:20 to 20:40
Discussing the limitations of human data curation and the importance of automation.
“And that's just a task that a human would never be able to do because a human can't keep the whole data set in their head, obviously.”
Show all 37 chapters
Complexity of Data Concepts and Redundancy
20:40 to 22:00
Understanding how data complexity and redundancy affect model training.
“the amount of data that I need in order to properly understand dogs is going to be a lot higher than the amount of data I need to understand elephants.”
Experimentation in Data Processing
22:00 to 23:20
The necessity of experimentation in refining data processing methods.
“And it's one of these things where, you know, I think to your point, it's why we've run hundreds and hundreds of thousands of experiments to try to figure this out.”
Sources and Quality of Code Data
23:20 to 24:20
A look into the sources of code data and their implications for AI models.
“GitHub, the source of code, maybe Stack Overflow, even though that's cut off these days.”
Legal Challenges in Data Use
24:20 to 25:40
Examining the legal challenges companies face regarding data usage.
“Books, Books 1, Books 2, and obviously Books 3, controversial.”
Scaling Laws and Their Impact
25:40 to 27:00
Understanding scaling laws and how they affect data performance.
“Yeah, that was, I think, public and part of the lawsuits.”
Future of Data Quality and AI Scaling
27:00 to 28:00
Discussing the importance of data quality for future AI scaling efforts.
“Oh, GPT-N is going to cost a trillion dollars to train.”
Understanding Power Law Scaling in Data
28:00 to 28:58
Learn about the relationship between power law scaling and information gain per data point.
“who was a really fantastic grad student I worked with on this paper.”
Measuring Dataset Quality and Performance
28:58 to 29:58
Explore how dataset quality impacts training speed and model performance.
“Are the most recent open datasets better than the older ones at a good rate or like just marginal?”
Challenges with Synthetic Data
29:58 to 30:42
Discover the challenges and strategies associated with using synthetic data in model training.
“relevant for, you know, a given model size.”
Enhancing Training with Smaller Models
30:42 to 31:46
Learn how smaller models can outperform larger ones with fewer resources.
“of tests that we only look at very occasionally.”
Future of Open Datasets in AI
31:46 to 33:12
Discuss the evolving economics and incentives surrounding open source datasets.
“So, you know, this is a big roundabout way of getting to this answer of, you know, have the open data sets, I think, kept up with this improvement.”
Building a Data-Centric Company
33:12 to 34:27
Understand the importance of focusing on data quality as a core business strategy.
“I think what you see in all the frontier labs is that they have data teams.”
Balancing Open Source and Proprietary Data
34:27 to 35:38
Examine the balance between using open source and proprietary data for training.
“And then you have companies like yourselves that are sitting on top of it.”
The Role of Data Quality in Model Training
35:38 to 38:08
Delve into how data quality influences model performance and the challenges of demonstrating its value.
“know, this was very near and dear to my heart.”
Synthetic Data Approaches and Their Implications
38:08 to 42:00
Explore different approaches to synthetic data and their impact on training models.
“about it in the data and then the Kimi paper comes out with a model and then people are like, oh, the rephrasing is important.”
Synthetic Data in Model Training
42:00 to 46:00
Learn how synthetic data impacts model training and its efficiency.
“It could be putting that information in a format that is more representative of what the model is going to be faced with downstream.”
The Importance of Data Diversity
46:00 to 48:20
Understand why diversity in data is crucial for effective model performance.
“And I think there's a lot of really great content and high quality data points like that.”
Curriculum Learning in AI
48:20 to 53:10
Explore the evolving role of curriculum learning in AI model training.
“So like epoching over higher quality data, almost always better than getting the same amount of new data of an unknown quality or of average quality.”
Post-Training Strategies and Market Demand
53:10 to 56:01
Discover strategies for post-training and the market landscape for AI models.
“And I think that that view would lead very strongly to the fact that you should be trying to optimize your pre-training data to make post-training processes more effective.”
The Importance of Training Efficiency
56:01 to 1:00:20
Learn how faster, better, and smaller training impacts AI model effectiveness.
“I think you also have these places where the funding is the country and it becomes a little unclear where it comes from.”
Exploring Data Pruning and Model Optimization
1:00:21 to 1:03:03
Discover the significance of data pruning and the challenges in model optimization.
“And I think that this is something a lot of people are investing in.”
Insights from Reducing Data for AI Training
1:03:04 to 1:07:38
Understand the process and benefits of data reduction in training AI models.
“I did a podcast with Jack Morris, who's out of Cornell.”
Challenges in Identifying High-Quality Data
1:07:39 to 1:10:01
Learn about the common misconceptions and challenges in sourcing quality data.
“how higher quality data can get you much better performance much more quickly.”
Understanding Data Quality in AI Training
1:10:01 to 1:11:41
Learn why having the right data set is crucial before AI training begins.
“They just show up with whatever they have.”
Challenges of Data Curation and Adaptation
1:11:41 to 1:13:38
Explore the complexities of adapting data curation for various use cases.
“that I am on the science side that I'm just super excited about.”
The Importance of Data in AI Strategy
1:13:38 to 1:14:24
Understand how valuing data can create an unfair advantage for companies.
“But when we think about kind of the vision for the company in the long term, it's about saying what are all the other ways we can operationalize that same core skill set.”
Meta's Super Intelligence Team and Data Focus
1:14:24 to 1:17:18
Discuss the implications of Meta's investments in AI and data optimization.
“And just to wrap on some gossip, let's talk about meta and super intelligence.”
Transcript
Automatic transcript. May contain errors.0:04Hey everyone, welcome to the Lit in Space podcast. This is Alessio, partner and CTO at Decibel, and I'm joined by Swix, founder of Small AI. Hello, hello. And we're so excited to be in the studio with Ari Morcos, CEO, co-founder of Datology. Welcome. Thank you so much for having me. Ari, so you first came across my radar. I mean, I guess Datology is like a relatively, I guess, exciting, well-hyped startup, at least with the fundraising and the higher profile of the people that you hire. I reached out to book this interview after you worked on the RC. I don't even know how to pronounce it. R-K?
0:35RC, yeah. RC. It's inspired by a real transformer that was called RC. Yeah, the RC Foundation models. You guys have been doing a lot of data work. How would you describe Datology today? Yeah, so our mission at Datology is to take everything around the data side of machine learning, right? So going from you have a bunch of data sitting in storage to you're going to feed it into a model via a data loader. There are a ton of choices you would make in that process, ranging from how you're going to filter the data, how you're going to sequence the data, what synthetic data you're going to generate, if any, how you're going to batch the data, all of those things.
1:08And those will have a tremendous impact on the performance of the model that you train on the data. One of my favorite catchphrases is models are what they eat. If you show them great data, they're going to be really high quality. If you show them low quality data, they're going to be low quality. But this is a frontier research problem. How do you actually do this effectively? How do you do this automatically at scale? It has to be automatic. to be able to process trillions of tokens, billions of images, things like that. And that's our mission at Datology, is to take that whole process, make it really easy so that anybody can get access to state-of-the-art data curation without needing to be an expert themselves, and in doing so, help the folks we work with to train models much faster to much better performance, and to also help them train much smaller models to the same or better performance, which I actually think is some of the most exciting stuff going forward.
1:53But fundamentally, that's what we do at Datology, is help people curate their data so they can trained models faster, better, smaller. So the key words for that data curation is a service, data efficiency, all those terms. In the pre-chat before we started recording, you mentioned that there's a cool story around how you got into data in the first place, right? You were at GDM, you were at Meta as a research scientist. Describe how that became an interest. My PhD is actually in neuroscience. So I come much more from an empirical science sort of background. I actually spent time trying to teach mice how to count and then analyze the activity of thousands of neurons in the brain while mice did count and try to understand how did that actually happen?
2:29What were the neural dynamics that enabled that? And that's actually initially how I got into machine learning was as a means to analyze my neural data sets. I also started my PhD 2011. So Alex came right after that, Tari D. Kuen right after that. Lots of evidence that AI was going to be very, very exciting, which led to me transitioning. But as a result, because I had this kind of somewhat different background of being trained as an empirical scientist rather than as a computer scientist. My real first mission when I joined AI was to try to build more of a science of deep learning. Something that I think is still true today in many cases is that deep learning is an empirical science, but most people that have computer science backgrounds were trained more in the context of a branch of theory, right?
3:09Everything was very provable. That was the initial pushback to deep learning, actually, was that you couldn't prove anything in it. But deep learning is, at its core, an empirical science, right? We have to run large experiments. We understand the rules for how we design these systems, but the properties that come out of them when we actually train them on a ton of data are emergent and unexpected. So I always really wanted to write these papers where they had two halves, where the first half of the paper was trying to understand why is this representation desirable or undesirable? Why is the model good or bad?
3:38And then understand that and then use that understanding to then improve the model. And that was always my goal. That was kind of the perfect paper. Rather than just throwing spaghetti against the wall and seeing what stuck, we were able to really understand why something didn't work and then use that understanding to improve it. Unfortunately, it turns out that it's not so difficult to do the first half of that, try to understand the system, but really, really difficult to actually use that understanding to improve the system. A lot of times what would happen is you go to optimize for this variable, you find, hey, here's this property of representations that makes models good.
4:09You go and you optimize for that, and then it turns out that wasn't a causal variable. That was a correlate, and it doesn't actually work. So I maybe wrote 30 papers where we did that first half and maybe only three or four where we did that second half. And that was always kind of frustrating and dissatisfying to me. And then around 2020, I had several papers that all kind of slapped me in the face at the same time with the same insight, which is that all that really matters is the data. And I had come into all three of these papers very much focused on inductive biases. How do we put better inductive biases into models, either through changing the objective or through changing the architecture, which is where most of the field was and still where you see a lot of the papers at the big conferences are about architectures and various tweaks to architectures.
4:50But I had these multiple papers, all of which made this clear takeaway that the data is the only thing that matters. I'll give you one example. There's a paper we had called Convit, where the idea was to take a vision transformer and initialize it as if it was a convolutional neural network. And that way, you could actually start with this inductive bias of convolution, but the model could choose to unlearn it if it wanted to. So the idea was it was a soft inductive bias, not a hard inductive bias. Comnets have a hard inductive bias. You can't not be convolutional in a comnet. But in this case, you initialize the transformer that way.
5:22And then if it wants, the model could learn not to be that. And the idea here was that this would be really helpful for models to give them this inductive bias, but then they could learn not to use it if they didn't want to. Just to follow up, there's a one-to-one mapping of a comfnet to a transformer, and you can map it directly onto the weights? Exactly. You can map it exactly correctly, it turns out. If you make it just, you know, say you have a 3x3 kernel, you can have nine heads, each head corresponds to a different part of that kernel, and then you can initialize it so it is exactly. So it's like a very coarse thing that can then be refined with training.
5:51Exactly. And then it can choose to change its weight so that it can undo the weight tying that you impose on it this way. We actually had a follow-up paper that showed you could take a train network and actually instantiate a train CNN as a VIT as well. So there's a way to do this. It turns out in the small data regime, and when I say small data here, I mean, say, less than 500 ,000 data points. And this was in the context of image self-supervised learning. So in that small data regime, this is super helpful. And where this paper has actually been cited is a whole bunch of kind of niche scientific problems where there's very little data.
6:21For example, volcano prediction where you have like 1 ,500 data points or things like that. But the advantage of using this soft inductive bias decays as the data size increases and eventually actually becomes harmful. So if you see enough data, and the threshold at which this changes is around like a million data points. So it's not massive by any stretch by our current model. So basically, once you get past a million data points, that soft inductive bias no longer helps you. And it actually now is mildly harmful. So I had this paper and a couple other papers that all kind of made this same point, that basically, you know, when you get to enough scale, inductive biases matter not at all.
6:59All that really matters is the learned posterior from the data distribution. And that's really what defines everything. And then, of course, the rise of the transformer really showed that actually starting with models that have fewer inductive biases built into their architecture, you know, is the right thing. So we had this combination of factors, which ultimately actually was very confronting for me because I had spent the last six years of my career working on inductive biases. And now I'm faced with several different papers, all of which show me that, hey, what you've been working on isn't actually really that important.
7:32Bitter lesson built. Bitter lesson indeed. So the bitter lesson was indeed very bitter for me. And, you know, that was really my, you know, inculcation in it, I suppose, where at the end, I kind of thought to myself, okay, clearly the bitter lesson is true here. What should I do in this new world? You know, and it became clear to me that there are really two options that made a ton of sense. Either go work on making GPUs go burr, and I'm not a hardware engineer. I don't know how to make GPUs go faster, or work on data. And for a whole bunch of reasons, data has been dramatically underinvested in relative to its impact.
8:05Something I've said before, and I'll say again, is that data is the most underinvested in area of research relative to its impact. And I don't think it's even close. And there are a whole bunch of reasons for this, which we can go into, some of which have to do with the culture of machine learning, some of which had to do with the incentives that have been set up. But data has systematically generally not been considered. And even if you go and you look at the scaling laws work from Kaplan and Ginchilla and all these other things, they all assume IID data, which is insane. We know that all data are not created equal, that garbage in, garbage out is like the oldest adage in computer science.
8:37And yet all these scaling laws assume that all data is created equal. That makes no sense whatsoever. That's what led me to start working on this problem. And it turns out that there's a really cool thing about data research. In addition to it being something that's impactful relative to the investment, which makes it a great research area and makes it an even better company. what I'd said previously was that with representations, you have this disconnect where there's questions which are kind of scientifically interesting about understanding why a representation is good. And then the questions that are practically relevant, how do I use this to improve it?
9:08And I think what was so frustrating to me early in my career was that those were different questions a lot of the time. The questions that I wanted to ask, which were curiosity-driven and really interesting to me as a scientist, ended up often not being the questions that were practically relevant downstream. But it turns out with data, this is no longer true. With data, if you can understand what makes a given data point useful or what makes a given data point not informative, you can almost always use that insight to make a data set better and therefore make a model better. So what this means is that the set of questions which are scientifically interesting and the set of questions which are practically relevant in data research are largely the same questions.
9:46And that's really rare to find in research period. And what this means is that we can ask the questions, which as scientists are extremely motivating to us, but then have very high confidence that the answers to those questions are going to help us to build models that train much faster, that train to much better performance, and that can train with far fewer parameters. So that's a little bit of a high level of kind of how I got into the data problem. And I think the pain that I had to go through to get there in the first place. You mentioned something about the incentives in the data not being aligned.
10:19Can you unpack that? Because I think from the outside, you have companies like Scaled that obviously have become super successful. So people are investing a good amount of money. But what you're basically saying, like, you know, NVIDIA is like$4 trillion and Scaled is not$4 trillion. So what do you think there's that inefficiency? Okay, so first off, we have to divide the research community from the industrial community because I think they're very different. And I think in general, data work has been far more valued in industry consistently than it had been in the research community. First and foremost, part of this is that data work has just often been considered a second-class citizen sort of work.
10:53It's the grunt work. It's the plumbing. It's the stuff that, you know, you don't want to work with as a, you know, super hoity-toity scientist. There are even some tweets recently going around people saying, you know, data cleaning is boring. It's low-value work. Whereas I think what you'd find is that if you talk to the most talented AI researchers and you ask them what's the secret to your success, they'll largely tell you that they look at the data. Ultimately, these models are a reflection of the data that you show. it. And yeah, it can be tedious. It can be challenging, but it is so critical to get this right.
11:22So I think first off, there's this general perception that this is lower quality work or not quality, but lower prestige work. And that's been there for a long time. I think part of this had to do with the way that research incentives were set up. The data set was viewed as the given. So if you think about research circa, say, 2018, given ImageNet maximized performance on the Val set or on the test set, right? But the data set ImageNet was given as something you don't change. Even Kaggle had this framework, right? Given the data set, go and make this better. People might try things like bootstrapping or stuff like that.
11:55But generally, the assumption was you're going to improve the model through better modeling, not through improving the data set. And part of this also was just in the supervised learning era, this made sense, right? We generally weren't compute limited. We were generally very data limited, right? Data was very scarce. Like if you want to assemble ImageNet, you have to go to MTurk and get a whole bunch of people to label the data set. And then there's generally some quality floor, right? Because a human has looked at every data point in this data set. Even if there's still a lot of errors there, at least it's not going to be as bad as just the internet scraped.
12:28But then in 2019, the field underwent this pretty massive change, right? We figured out how to train without labels. And one of my more controversial viewpoints, I think, is that I think the transformer is a great advance to be sure, But I think it's one of a very large set of equivalently good architectures that we could have found. And there are many, many ways we could get to the same performance without the transformer. But I do not think there's any way we could get to where we are today without self-supervised learning and the ability to train on unlabeled data. That was the real advance, to my mind, that enabled us to get these incredible increases in capabilities.
13:05Which is like the mask objective. It's not just masking objectives. I think mask language modeling objective is one, but even next token prediction, right? But generally this notion that, hey, instead of having to get an external label from a human, we can ask the model to predict one aspect of a data point from other parts of that data. And that is really powerful. Because think about it, right? That meant that we went from ImageNet, a million data points, to literally trillions of tokens, a million-fold increase in data quantity in a matter of, like, several years. That's completely unheard of.
13:34And that also changed everything because now we went from data being scarce and having a high quality floor to now all of a sudden data is absolutely massive. All of our models are basically always underfitting the data, whereas previously we would do 160 epochs on an image data set, right, where they would all be overfitting the data generally. So now we move to this underfitting the data regime. There's no more quality floor. And now we have all of these problems with redundancy, with low quality, with low information gain, all these various things that come with these massive unlabeled data sets.
14:06So I think the problem also changed pretty dramatically from the 2010s to the 2020s. And I think that's what makes it so exciting as a scientific question, is that this didn't really make sense to study prior to 2020. But now this makes tremendous sense and is, I think, absolutely critical for us to solve in order for us to enable these models to continue to improve and also to enable the cost effectiveness of these models so that they don't just stay as something that's only possible to achieve if you have hundreds and hundreds of millions of dollars. Making the data better can be a massive compute multiplier.
14:40It can change the performance per dollar by orders of magnitude. And in many ways, that's our whole goal is how do we make that easy and effective for everyone? Totally. And you were at Meta from 2018 to September 23, which is both during Lama 1 and Lama 2. At what point inside of Meta, maybe some of these learnings become apparent? Like, okay, we should start to spend resources working on this. You mentioned 2020. So I'm wondering if that was clear to you. I think Lama 1 was already a big breakthrough. Yeah, Lama 1 definitely put more effort into data filtering, I think, than many others. And definitely started to change this.
15:16But even then, I would say that actually, you know, even when I left Meta, this was still an area of kind of the idea of actually curating the data to figure out what's the high quality, high value data, I think still was fairly underappreciated. And if you talk to a lot of the folks on the data teams within the big frontier labs, what you'll find is that they've actually invested really heavily in crawling. Oftentimes, they've really worked on getting better crawlers and trying to clean up the source of the data that's coming in, which makes sense. But ultimately, you know, I think what you really need to do is you need to take this perspective of given everything that the model has seen so far and given a potential candidate set of data, what data point is going to teach the model the most the next time it sees a data point?
15:55And that's a pretty different framing for how to think about this problem. And I think we've certainly there's certainly been some great work done, although it's all secretive within, I think, the bigger labs. But that's a really hard problem. That's a frontier research problem. And I don't think we still know how to solve that. I think data curation also is a hard problem to solve, quote unquote, because it's not one where there's a single silver bullet. There's not just do this one trick and all of a sudden things work. It's rather here are these 50 different things that you can do, each of which provides a pretty modest gain on its own.
16:25But then if you can figure out how to make them combine, you then get a really big gain. But you have to figure out first off, what are all these different things you want to do? And then two, how do you make them play nice with each other? Because by default, they don't play nice with each other. Yeah. I'll make a quick observation on you mentioned self-supervised learning. I definitely agree that just getting rid of labels altogether is great or forming your own labels, right? And I have a general observation that I think that extends to things that are not just learning. So self-supervised, I don't know, optimization, self-supervised neural architecture search, self-supervised curation.
16:56If you can just automate everything, I think that's the lesson really. Just get the machines to do it because we are the rate limiters if we must label everything. Yeah, I think that's very true. It's actually something I think about a lot is, are we actually falling prey to the bitter lesson again here by trying to have human guided methods of data curation? Probably the best open effort on data curation is DCLM, DataCompLM. It was led by Ludwig Schmidt, a professor at Stanford, and about 30 students across many different institutions. Really wonderful effort to kind of curate Common Crawl style data sets.
17:33Yeah, we've actually covered Datacomp and DCLM on the podcast. Awesome. Great. But DCLM had a really cool study at the end of the paper that I don't think gets nearly enough attention as it should. So, OK, so they had these 30 grad students spend, you know, two years basically trying to design what are the optimal filtering criteria for these models. Right. And they built a system that's pretty good at this. Right. So then they asked all those students predict what that system is going to do. So given a data point, is the system going to say keep the data point or is it going to say reject the data point?
18:05These are nominally the best experts you could ever hire to do this. These are students who have just spent all of their time looking at NLP data for two years. They could not predict what the DCLM classifiers would say above chance. So, you know, this comes up a lot of times where people often ask me, how can you possibly do this without a human in the loop? You know, it just seems impossible. You need to have a human to actually rate these data. But I think that what the takeaway from that study is, and I think there's a number of other piece of evidence that also suggests this, is that obviously we have to be automated because humans just can't scale to billions of data points, trillions of tokens.
18:40It's just not possible. But even if we could, we actually wouldn't want that. Humans are not good at this task. And to give an intuition as to why humans aren't good at this task, I think the easiest way to think about this is that the value of a data point is not just a function of that data point itself. It's rather a function of how that data point relates to every other data point in the training set, right? So if I have 10 ,000 copies of slightly variable summaries of Hamlet, I don't need all of those. But if I were to look at any one of those individual summaries, I might say, hey, this is really high quality.
19:16This is a really accurate, it tracks all the characters, it's well-written, it's clear, but I don't need 10 ,000 of those. And that's just a task that a human would never be able to do because a human can't keep the whole data set in their head, obviously. So even if you could have this scale with humans, you wouldn't want to. But so what's the right number between 1 and 10 ,000? The unsatisfying answer is it depends, but it's also the right answer. So it depends on how complex the concept is. So redundancy is really useful, right? And removing all redundancy is a bad thing. If I remove all redundancy, then I'd only be able to understand, say, a golden retriever in the one situation that I've ever seen it in before.
19:53I wouldn't be able to generalize, and that would be bad. So some redundancy is good, but I think we all have the intuitive understanding that infinite redundancy is not good. It's bad. So where is this line for different concepts? Well, one example I like to give for this is elephants versus dogs. So elephants are pretty stereotyped. There are two kinds of elephants in the world. There are Asian elephants and African elephants. They're all gray. They all have floppy ears. They all have a trunk and some tusks. They all have, you know, wrinkly skin. African elephants are bigger than Asian elephants, but largely they're all pretty similar.
20:22There's not too much variability. So I don't need that much data or that much redundancy to understand the concept of elephants, you know, fully and completely. But dogs, on the other hand, are totally different, right? Dogs are super variable. There are hundreds of breeds, not to mention all the mixes of different dog breeds. There are different shapes, sizes, textures, colors, all of these different things. the amount of data that I need in order to properly understand dogs is going to be a lot higher than the amount of data I need to understand elephants. So this comes to some of the challenge when you're actually trying to do this sort of creation, at least on the filtering side, is you have to, first off, you don't get a data set where you're given, hey, these are a bunch of dogs, these are a bunch of elephants.
21:02Instead, you just get here's a bunch of data, right? So first off, you have to, in an unsupervised way, discover what these concepts are. Use something about that concept in order to make some inference about how complicated it is or how complex it is and therefore how much data you need to understand it. Figure out, okay, this is a really complicated concept. I probably should keep a lot of redundancy. This is a really simple concept. I don't need that much redundancy. And then make that appropriate choice of what do you want to remove. So this is, I think, where a lot of the challenge comes from.
21:29But these are the sorts of factors that you have to keep in mind when you're trying to design these systems. How do you draw the line of a concept, though, right? Like, because then it's like, well, the elephant and the dog, but what about mammals? And then what about, you know what I mean? It's like, how should people think about it? Maybe it's that why you need the technology because it's hard to talk. Yeah, no, I think that's right to some extent. I mean, look, it's an empirical question, like all things are, right? Is that with every data set that you can choose different level of fine grained.
21:56Ultimately, it's a hyperparameter. It's a knob that you can tune, right? For how aggressive are you going to be with respect to creating new concepts versus keeping concepts together. And it's one of these things where, you know, I think to your point, it's why we've run hundreds and hundreds of thousands of experiments to try to figure this out. I think, you know, this is something where it requires just a lot of experimentation to understand how to do this. And I think one of the challenges we have is not only do we have to make this so that this works on one data set, but we also have to build a system that can automatically adapt to any arbitrary data distribution and be able to make the appropriate inferences, you know, in zero shot on a new data distribution.
Read the full transcript
22:31So we kind of have these two sets of questions. First off is like, how do we push the frontier of data curation forward? And then second of all, how do we do out of distribution generalization where we say, hey, we have this great data curation approach. How do we make sure that this generalizes to a novel data distribution? I don't know if this is like a good time, but I was going to ask for like a brief history of data sets. It might be too much. I don't know. I'll just list off because we've done a data sets one on one episode. I think that was like one of our earliest episodes by far, because we want people to know the data sets.
23:00and I think everyone starts a common crawl. I think every lab has their own web scrape. Would you say that's true or do they start from common crawl? At this point, yeah. I think, like I said, this is where most of the labs I think have actually invested most of their time and effort is in building better versions of common crawl for themselves. Yeah. I'll just name check some of these. If you have commentary, just chime in. GitHub, the source of code, maybe Stack Overflow, even though that's cut off these days. I don't know. Do people get code from anywhere else? I mean, I think there are obviously places where you buy code data, But for public code, I think those are the most common.
23:32I think some interesting things about those that I just personally find surprising. Stars are not a good predictor of whether data is useful for models or not. Not surprised. Like, I think that's, like, the most popular repos are not necessarily higher quality, at least with respect to do they improve in models coding capabilities. You've ablated this. I haven't done it, but the Star Coder paper has done it. And there have been a couple other papers that have all shown that. Something that I just consistently have found to be a little bit surprising. There's a lot of things that are kind of counterintuitive about data curation.
23:58Did they, this shows that I haven't read the paper, but did they find anything good that was like a sign of a good code base? There wasn't anything that was super predictive. Oh, man. Like, honestly, in some ways, like some of them were length. Like some of these like simple heuristics actually ended up being better, but nothing was super discriminative there, which is kind of interesting. Okay, cool. I'm going to keep going. Archive, which is, you know, GitHub for papers. Books, Books 1, Books 2, and obviously Books 3, controversial. I think Anthropics is getting sued over Books 3. Yeah, I think a bunch of people are getting sued.
24:28Meta is also getting sued over Books 3. In some sense, can we just look past it? I don't know. Books are a transformative use. I don't know if you have a view on this. Well, the recent ruling was interesting, although it was an appellate court ruling, so presumably it's going to go to a higher court afterwards. But what they ruled was that it's fair use so long as you purchase the book. So, you know, if you can't download Books 3 and then use it because that's piracy in that you've stolen the books in the first place. But if you bought a copy of all of those books, then you can train it on, and then it just counts as fair use, which I think is an interesting, and to me, it feels pretty reasonable line there.
25:06One fun thing about Books 3 is that it also has a lot of not-safe-for-work stuff in Books 3, which is kind of interesting if you actually go and look through it. There should be a Stripe one-click checkout with Books 3. Just buy Books 3 and then get a warehouse and then get the mall shit there. I wonder what the cost would be. I'm sure somebody run the numbers. I'll look it up. I don't know if you can comment on this at all, but in the Meta lawsuit, I remember there was an email thread with some of the research scientists inside of Meta talking about Books3, and Zuck was like, just do it. This is public, right?
25:40Yeah, that was, I think, public and part of the lawsuits. Yeah. Any reflections, comments? All I can say is that when I was at Meta, certainly legal stuff around data sets was very challenging and becoming increasingly challenging. And there are a number of situations where, you know, the only person that could approve things was Zuck because of the scale of the risk, I think. But it definitely made publishing at Meta near the end more challenging around just what we could do with any data set. Because, I mean, realistically, companies like Meta and Opening Iantropic are big targets for these lawsuits.
26:11Yeah. So my conspiracy theory for what happened to Llama 4 is the lawyers got to it. The lawyers got to the data sets. And they had to change what they used. Yeah, they were just like tied behind their back when other labs were not, just because Matt had an active lawsuit. I think that's possible. I think probably more of it just has to do with the challenges of just continuing to scale and having that be the goal. This is actually a lot of the reason why I got into data and started Datology was that the scaling laws always were terrible. What the scaling laws paper showed was that there was a predictable relationship between...
26:42The Kaplan one. Yeah, the Kaplan one. There's a predictable relationship between performance and computer data, right? That's really useful. But it was a bad predictable relationship. Power law scaling is terrible. It means that every time you 10x your data, you get a diminishing marginal return on performance. This is why you had these prognostications. Oh, GPT-N is going to cost a trillion dollars to train. It's because you take that scaling curve and you just naively extrapolate it out. I think that's what we've seen to some extent with the failure of the mega models with 4.5 and Lama 4 and others.
27:13I think that there is a challenge of just continuing to do that naively. and you have to figure out how to break it. I think there are a number of theories of ways how to break it, and I don't think they're mutually exclusive. My bet is that data quality is a massive way to do this. And in many ways, actually, the paper that was the foundational paper for datology, it's called Beyond Neural Scaling Laws, and was fortunate to get a best paper at NeurIPS. And what that paper showed was that if you use your data correctly, you can actually bend the scaling laws themselves. And an interesting kind of technical part of this is that, you know, I mentioned what we really care about is this, how much new information do you learn from the next data point?
27:47So technically, that's the marginal information gain per data point. Perplexity is another variant of it. There's a duality between them. It turns out that we were able to prove in perceptrons, at least, because that's generally what all you can ever prove makes in. So in small scale, and this work was led by Ben Sorcher, who was a really fantastic grad student I worked with on this paper. And what he showed was that there's a direct duality between power loss scaling and the fact that you also see that the marginal information gain per data point also decays as a power law. And that's why you get power law scaling, because every successive data point is teaching you less and less and less, and it follows a power law.
28:22So then you get performance decaying as a power law as well. So if instead you can keep that so it's flat, then you bend the scaling law. And now all of a sudden you learn dramatically faster because the amount of information you're learning is not decaying with data set size. Now that was all in theory what you could accomplish, and we proposed a couple metrics that got us one step there. But in many ways, I would actually say that the whole point of datology is how do we realize the potential that was shown in that paper? How do we actually make that a reality? And I think fundamentally, if we want to get scaling to work well, fundamentally, we need to do a better job here.
28:57Are you measuring the quality of these open datasets over time? Are the most recent open datasets better than the older ones at a good rate or like just marginal? They do get better, but I think they're not relative to the headroom and potential, I would say, right? Like, like, Nematron is actually pretty similar in quality to DCLM. It's, it came out about six months later. It has more unique tokens. They made a really big deal about it having more unique tokens, but on average, the quality is, is pretty straightforward. So, you know, when we think about what we are able to accomplish at Tateology, we usually think about along these three axes I mentioned, train faster, train better, train smaller.
29:31So typically, basically that's a, like, first question, train faster, given a certain baseline data set, how much faster can we achieve the same performance? So, you know, and how many fewer tokens? So we're able to now get to the same performance as DCLM about 12x faster. So, you know, in fewer than 10 % of the tokens, we can match what you get from training to convergence. And when you say performance, you mean like GPQA or you mean loss? Yeah, so we typically take the accuracy across 15 kind of standard benchmark tasks that are relevant for, you know, a given model size. So your MMLUs, your arcs, your races, you know, et cetera.
30:06The problem with those is like, are you training to the test, right? Like, are you, you know, I'm sure you know this. And that's something that we're super careful about, because it's really easy to overfit to these benchmarks, of course, and then end up with models that are really brittle. And I think this is something that we've seen, especially with synthetic data. And synthetic data is a big part of what we do at Datology. We found that it can drive like pretty dramatic gains if you do it correctly. There are lots of ways to do synthetic data incorrectly. We've seen a number of models, right, that are trained on a lot of synthetic data and end up doing really well on benchmarks, but then kind of don't pass vibe checks and people don't really use.
30:39So we do a lot to try to prevent this. First and foremost, we keep a held out set of tests that we only look at very occasionally. And we also don't evaluate on a whole bunch of other evals that we then have, you know, models that end up getting evaled on later to try to really ensure this. But yeah, this is fundamentally how we measure. We look at an average of benchmarks just trying to kind of think what's fair and reasonable with respect to what we can do. So, So, you know, that's like the first thing we typically look at. Then we look at train better, of course, under the same compute budget.
31:03How much better can you do with a given data set? We're able to beat kind of the best open data sets by anywhere from four to five points, depending on the specific data set and eval. Some of the evals actually are much bigger than four to five points, four to five points on average. And those are absolute points. We generally find that in order to get that same performance from training longer on the baseline data sets, you'd have to train on those baseline data sets, you know, at least five to ten times longer to try to match that performance. because every successive point of accuracy, of course, gets harder and harder to achieve.
31:33And then finally, train smaller bases. Say, okay, holding performance constant, what's the smallest parameter count model that we can get to outperform? We can already get models that have fewer than half the parameters and also train faster and also outperform the larger models trained on the uncurated or alternatively curated datasets by a large margin. So, you know, this is a big roundabout way of getting to this answer of, you know, have the open data sets, I think, kept up with this improvement. You know, with a fairly small team, we're now a team of about 30. You know, most of the results that I've discussed, like, were achieved with a team of under 20, because we've grown quite a bit in the last couple months.
32:09And with not that much compute by kind of common standards, you know, more than academics, but certainly nowhere close to the frontier lab, we've been able to achieve, I think, pretty dramatic results. I think the reason for this is because there's so much headroom here. You know, we've already been able to get 10x gains. I think there's at least another 100x behind this that are still to be done. There's so much stuff that we're just not even doing right now that I know makes sense to do, let alone all the things that we are doing that I know we can be doing better, that we're still very suboptimal with respect to how we're doing this.
32:39Like, I know that the way we do our synthetic data right now could be much better, that the way we do our filtering could be much better, the way we do our model-based filtering, our embedding-based filtering, all these different aspects could be much stronger. So I think there's just so much headroom here. I think the challenge is that there's not a huge incentive to do this in the open data set community. I mean, the labs which have the biggest incentives obviously have strong incentives not to share anything with respect to that. So you're left to kind of, you know, the Allen Institute, things like DCLM, Hugging Face, et cetera, to make progress there.
33:10But I do think that this is a hard enough problem that it really demands a whole company that is really focused on this. I think what you see in all the frontier labs is that they have data teams. And if you talk to the folks that work on those data teams, what you'll kind of systematically hear is that typically they're under-resourced relative to the gains that they're delivering, that they're always having to fight for attention. And this is just like a fundamental thing that I saw at Meta, I saw at DeepMind, and I've heard at all these other places. It was a big part of why I decided to start Datology instead of doing this within Meta.
33:43You know, I had the opportunity to start a data team there and that would try to centralize this. But fundamentally, I think that this is such an important problem that it's a problem that needs to be the end itself, not just the means to the end, which I think is what you see in many of these big groups. You need to have a large team of really talented people who are really passionate about looking at the data. And there aren't that many people who are that passionate about it to just focus on how do we build the best possible data sets for model training. I think it's hard to do this as a data team.
34:14I think there's a real benefit of being a data company. And that's a lot of why I started Datology. How do you think the almost economics of the open source data sets world evolve? Because you basically have this like open source data sets that are like good, but maybe they're not quite as good to make production data systems. And then you have companies like yourselves that are sitting on top of it. Do you think at some point there's going to be some sort of rupture between like, hey, why are you just taking my open source data set and making it better in private for people without contributing back?
34:46and do you guys have plans to then open source other sets? I think there's like kind of this open question of are these things actually useful in the open or should you just do it in private? Yeah, that's a great question. And one that we've thought a lot about. I mean, so first off, one thing to note is, right, is that while we do work with folks who are just training on open models, in general, we really built our product and designed it to be able to work with companies that are training on a combination of open source and proprietary data. And that proprietary data could just be data they've been collecting as a matter of business for the last decade, or that could be data that they've sourced from a data annotator or, you know, another data provider.
35:21And some folks we work with have all three, right? They're going to use open data, they're going to use data that they've acquired, and then they're going to use data that's part of their business to begin with. So, you know, and that's, like, I think a lot of where our focus goes, although, of course, we are excited about working with lots of folks who are training on more open data sets. So, I published for, you know, a decade, more than that, even like, you know, this was very near and dear to my heart. And it's something that we thought a lot about at Datology. I think one of the challenges of building a startup today, especially a startup for which science is a critical component, which, as I mentioned, is one of the things that really attracted me to starting Datology, is this tension, right?
35:57Fundamentally, we have to build a business. In order to do that, we have to have a moat. And you can think about kind of three places, I think, where our moat could come from. You know, one is from science know-how. One is from engineering infrastructure and the challenge of just implementing this yourself. And then finally, there's a brand moat that you can eventually reach. We're very far from a brand moat at this point in our journey. Eventually, I would love to have a brand moat where whenever anyone thinks data and AI, they think datology and, oh, that's where I should go first. I hope that we get to that point.
36:26But in the meantime, we have to rely on the other two moats, on the science know-how and the engineering infrastructure. I think on the open data side, what we've seen is that the engineering infrastructure definitely can be a moat, but unfortunately, I think that science know-how mode is actually pretty important. And a lot of the evidence that we've seen so far has suggested that that is something that's meaningful. As an example, you know, many of the customers we talk to, one of the first things they'll ask is, hey, compare to the best open source data set, right? So if we were giving away everything we needed to in order to build that best open source data set, some folks would just go there.
36:58So I think that's been where our challenge has been. Now, what we've tried to do, and I think we've done a good job of, and I'm generally happy with the balance we've struck, is try to, in the blog posts that we put out, give a lot of intuition as to kind of what we're doing and how it works without necessarily getting to that point of reproducibility. You know, that's, I think, much more open than you see most of the big labs be. Yeah. If you look at like the data section of like the Gemini tech report, it basically says like data quality was the single most important thing for making great model.
37:28One paragraph. We used algorithms and heuristics. It's like, great. You know, it's like, I think some people were even pointing out, you know, like recently, there's been a lot more attention on rephrasing as a method for using synthetic data. Was it the Apple paper? The Apple paper, the Kimi paper has mentioned this, a bunch of others. And, you know, some folks recently pointed out that like, hey, in our blog post from November, we were talking a lot about that. That's something that we do a lot of. Pratouche Maney, the guy who first came up with rephrasing, was one of our first employees. So, you know, we've improved on that pretty dramatically and taken it to new places.
38:02But that's something that, you know, we've like, I think that there would have been an incentive to just like not even talk about that at all. Sorry, just on that, do you feel like this is like a great example of you were talking about it in the data and then the Kimi paper comes out with a model and then people are like, oh, the rephrasing is important. But you're like, hey, I was telling you that before, but I just didn't have a model to show you that it was important. Do you think that's still even in open science, like a limiter for people that like if you don't have a model, people don't care?
38:28Same with DeepSeek. A lot of the things in the paper were like kind of known. But then once you have them applied, people care. I think that's certainly something that happens and I think speaks to the same sort of cultural incentives that we talked about earlier, where I think that, you know, people tend to think about this very much in, you know, ultimately it being a means to an end. And I understand why that is, of course. And ultimately, like, you know, when we sell better data, like ultimately we're selling a better model at the end of it or, you know, more cost effective model. But I think that the fact that people don't care about it as much, unless they're smacked in the face with it, I think is both a tragedy and an opportunity.
39:05And, you know, I would love it if it weren't that case. But given that it is, you know, that's, I think, the opportunity we see at Datology to really make an impact here. This might be a little bit of a tangent, but you mentioned synthetic data, you mentioned rephrasing. So I figured now's a good time to go into it. But, you know, I figured that most of the work of datology is filtering, but I see synthetic data as something slightly different. It is in a general domain of improved data quality, but it's different than filtering. Yeah. Am I right to recreate synthetic data with rephrasing or are there other parts to synthetic data in your mind?
39:36Yes, I think there are different parts of synthetic data. There are two parts. But let me first actually just comment on the filtering versus things. So I used to actually use the word data filtering or data pruning. And actually, that paper I mentioned that was at NeurIPS, that one actually has data pruning in the title. And that's how you beat scaling laws through data pruning. When I started Datology, I really changed the language to be data curation over data pruning or data filtering. And that's because curation is a lot more than just filtering. Filtering and saying, hey, this is a bad data point.
40:05We want to get rid of it is absolutely an important part of what we do. But it's also about rebalancing data sets, upweighting, upsampling certain data distributionally and downsampling others. That might not mean filtering. It might just be changing the weighting with which you take it. The order in which you present data can be really impactful. Curricula, and we now have seen this with discrete curricula, you know, for multi-phase training and things like that. That's not filtering. You know, the way you batch the data can be an important factor. Synthetic data can be an important factor. The way you mix sources, all of these sorts of things beyond just filtering.
40:35So filtering is a very important part of what we do, and it will always be something that we care a lot about, but it's much more than that. Okay, so now to the question about synthetic data. I think at a high level, there are two approaches to synthetic data, and we have focused more on one of them, the rephrasing one than the other, although I think there is opportunity in the other one. So the first approach is create new data where the knowledge that's in that data is largely coming from the model that's generating that synthetic data. Oh, that's distillation then. It's a version of distillation, and I think that this version of synthetic data could be construed as distillation in disguise.
41:10And I think it is a very clear version of this. And when you think about like the criticisms of synthetic data around model collapse and stuff like that, I think they largely apply to this version of you have a net new data creation that's coming out of these models. So that's like path one. I'll slip one in there. There's also model steganography where you can sort of hide preferences in a model and distill it down. Absolutely. And now we've seen like the recent like owl stuff around that. If people search anthropic owls, you'll see it. Yeah, exactly. The other way is this rephrasing, rewriting approach.
41:40So this is the information that's in the data is actually coming from the data that you're conditioning the rephrasing on in the first place. And all the model's doing is it's reformatting the data or presenting it in a new way that maybe is easier for a model to learn. Yeah, cleaning, right? Cleaning it in some way. It could be cleaning it. It could be making the information more accessible. It could be putting that information in a format that is more representative of what the model is going to be faced with downstream. So I do think that one of the things that definitely happens with synthetic data is we are bringing more post-training-like data into pre-training.
42:14Yeah, sounds like SFT. And in general, one of my beliefs is that most of what we do in post-training is better done in pre - and mid-training and earlier on in training in general. It's just the scale. You don't have that scale until now. It's just that. Exactly. Exactly. I think if you assume this paradigm where, you know, pre-training is incredibly expensive and something that you can only do very, very rarely and then post-training is cheap, then it makes sense. But as soon as you break that assumption, and I think DeepSeek showed that already you can get a frontier model for a marginal cost of a couple million dollars.
42:47That's gone down since then because we've gotten better at it and compute has come down in price since then. I believe that getting to a frontier model should cost a million dollars or less for most organizations, at least in a specialized domain, right? And when you think about what enterprises need, that's generally what they need. They don't need a model that can do everything. They need a model that can do a constrained set of tasks to very high accuracy for as low an inference cost as possible. And I think that that will be under a million dollars very, very soon. And that changes a lot of these dynamics.
43:19But going back to the synthetic data question of these two different types. So I think there's one towards this net new creation. I think that's where you have a lot of risk. That's where you get the model collapse concerns where, you know, I train a model, I train a generative model on a given data distribution. It overfits the modes and it underfits the tails. So then if I have it generate a bunch of data, it's going to be more mode and less tail. And then I do that a bunch of times and eventually I get a spike. I get a delta function. Only mode. Only mode. Exactly. Like that makes sense why that happens.
43:46I will note that if you filter the data after each point, that's now information injection, and that can break all of this and I think can prevent model collapse. Which a little bit is what RL is. Which is a little bit what RL is. I think you can absolutely view it that way. And I think actually a lot of the work that has suggested that RL is really just eliciting the capabilities of pre-trained models like random rewards or a single example, and then it's just changing the distribution. It's like aligning to the distribution the model has in the first place are, I think, very in line with that way of thinking about it.
44:14You're distilling from a perfect model, which is the environment or the verifier or whatever, and then you're distilling that into the thing. So it's amazing. It's beautiful. But the cool thing about rewriting is that because the model that's doing the rephrasing just needs to know how to rephrase, it doesn't need to know anything about the content itself. It doesn't need to understand it. it means you can use a pretty weak model to do the rephrasing and have it generalize and generate data that can teach a model that's much better than the model that's doing that rephrasing. So I think with this distillation in disguise, I'm generally quite skeptical that you can get a model that will be better than the teacher that's generating the synthetic data when you do this sort of net new data creation.
45:02It's possible you could through some sort of heavy rejection sampling on the big model because you're effectively inserting new information when you say which of the synthetic outputs is good or bad, right? There's some new supervision coming in there. But I'm generally skeptical of that. Whereas we've seen this, we actually have a blog post coming out in the next week or two about kind of our synthetic data generation, which we call Beyond Web. And we'll have some cool scientific experiments in there too, to our point of trying to figure out this balance where we can share some of the science, but also do so in a way that, you know, is sustainable for our business.
45:33And one of the things we show there actually is that by doing this, you can actually go get a model to do much, much better than if you had trained on all of the data, all raw tokens in the first place. So that by doing this rephrasing effectively, you actually can break this data wall and now get models that are better than either of the models that generated the data. With rephrasing, I think this is super possible because most of the information is coming from the data. It's not coming from the model itself. A couple of follow-ups on that, just things I've always wondered. Are textbooks all you need?
46:03No, they are not all you need. I think textbooks are great. And I think there's a lot of really great content and high quality data points like that. But obviously, textbooks are also a very narrow data distribution. And if there's only one thing that you should take away from this entire interview about what is good for data quality, it's diversity. Like in many ways, right, there was this, like, I used to do all this work on out of distribution generalization. And we had all of these, like, you know, very careful studies where we would say, okay, let's, you know, make this corner of the data distribution.
46:36Then we leave this held out where it's never seen this combination of things. And let's see if it can generalize. And then, like, you know, LLMs and the modern way of training models came along and said, hey, what if nothing was out of distribution? What if we just made it so that we train on everything? And everything's now in distribution. And by the way, that is in line with AGI, right? So you might as well. And that's basically what we've done. And it's worked. It's worked shockingly well, like way beyond anyone, I think, or most people would have expected. I certainly was shocked by it. I made a strong bet that there is no way you can get compositionality just from scaling.
47:10And, well, you can. It turns out it does work when you get big enough. What I was really referencing was, this is the Microsoft V papers, right? One, two, three, four. A lot of them do the rephrasing or rewriting in textbook format. And I feel like that's a little bit of cargo culting of like, oh, just because you write like Wikipedia or write like textbooks, the models learn better. That's not, I don't know, that's not automatically proven to be the case. I think that's also probably part of the reason why you see a big difference between the benchmark scores of those models and their real world use.
47:40They went to too narrow a distribution. And I think this is the problem with synthetic data fundamentally is that you're always going to have some bias here. I think you can do a lot to make it more diverse. And we have put a lot of effort into finding ways to do that. For example, we rephrase into many, many, many different styles and formats. That's really important to get stuff that's good. But I think this is the risk, right, that you go on way too narrow a distribution and models are always going to be fairly peaky with their output distribution. And then that actually results in reducing diversity.
48:08That said, I will say that there is a takeaway of that or textbooks all you need that I think is correct, which is repeating higher quality tokens is almost always better than seeing net new lower quality tokens. So like epoching over higher quality data, almost always better than getting the same amount of new data of an unknown quality or of average quality. Average in this case being like what you just get from an internet dump or something like that, or even a reasonably filtered internet dump. It's always better. The modification I made or the study I would want to commission out of that is like instead of having another epoch on high quality data, if you found high quality data, good, go and paraphrase it and then train on that.
48:48Maybe that'll get additional gains. I don't think I've seen any papers that have been to that effect. The Kimi paper actually had an experiment to that effect where they tried adding multiple epochs and they looked at how many rephrasing they did of each of them and had some results there that were interesting to that effect. Amazing. And then the other question was more on curriculum. Curriculum learning had a bad rep. for a while. How come it's back? What's changed? Yeah. So a bunch of things. And this was really interesting because when I was going out and, you know, initially deciding whether to start tautology and raising and like talking to various, you know, initial recruits and stuff, it was like mid-23.
49:21And at the time I was saying, you know, curricula are going to be a really important aspect. And a lot of people were basically just like, no, curricula don't work. Like we tried this a bunch of times and curricula don't work. Curricula are one of these ideas that I think always like had to work in the sense that it just made too much sense. There are a number of these things where it's like, it might be hard to figure out how to make it work well, but like it always had to work. There was actually a really cool paper from Stanford that had a nice way of conceptualizing this, which is imagine a graph where each of the nodes are a different concept or, you know, idea that you want the model to understand.
49:51And then the edges are basically the dependency between those concepts, right? So if, if concept A helps you learn concept B, there would be an edge from concept A to concept B, right? So now this is the graph. Imagine this graph of all concepts in the world and all the different edges between them, right? Huge graph. If that graph is empty, then it would mean that nothing is helpful for learning anything else, right? And then curricula would not make any sense. You should just randomly order things. If that graph was complete so that there is an edge of equivalent weight between every pair of nodes, then similarly, it would mean that everything is equally useful for learning everything else and curricula don't work and you shouldn't use them.
50:29Any other graph besides those two graphs, curricula makes sense. I think it's pretty obvious that neither of those is the graph of the actual world that we live in. Clearly, the world does have dependencies, some very, very obvious, like the fact that it'd be hard for me to do division and multiplication if I don't understand addition and subtraction, and some much more vague. But I have always believed like this has to work. And the challenge has largely been that if you're fully saturating your data, then there's really no advantage of a creek, unless if you wouldn't be able to learn it otherwise.
51:02Generally, I think the idea behind curricula is that it makes you much more efficient. But in the supervised learning world, we were fully saturating these data sets. So, you know, maybe a curricula would get you there faster, but that wasn't the bottleneck or the limiting factor. So there wasn't a clear incentive to actually go and do these hard experiments to try to figure out how to make a good curriculum because like who cares if I can get you to image net performance in 80 epochs instead of 160 epochs like that's nice but like it's it's not a big deal in the first place but now we're in this totally different world where now all of a sudden all of our models are underfitting the data this is super important and getting a curriculum right could literally make the difference between you know spending 10 times as much on a model training you know hundreds of millions of dollars potentially and now all of a sudden curricula make a ton of sense.
51:44So I think that's why the problem didn't really make sense to really put a lot of effort into previously. And, you know, now we've seen pretty clearly with discrete curricula that this makes a big impact. And like largely what we talk about when we say mid-training is really just like a later phase of your discrete curriculum, I think, is another way of thinking about it, right? You could even think of post-training as part of a curriculum. In fact, one of the things that I'm really excited about is, you know, we've mostly focused on pre - and mid-training at Datology so far, one of the kind of most consistent asks from every one of our customers has been, can you do more on post-training?
52:16Can you also help us curate the post-training data? So we're starting to invest pretty heavily there. And one of the things I'm really excited about is actually viewing this whole thing from pre-training to mid-training to post-training holistically as a single process. And then asking questions like, how do we optimize our pre-training data to make post-training more effective or things like that? You know, these are, I think, really exciting questions and something that you don't see happen even at the big labs because they have entirely separate teams, right? There's a pre-training team, there's a mid-training team, there's a post-training team.
52:42And like the mid-training team is a customer of the pre-training team. And the post-training team is like a customer of the mid-training and pre-training team. But it's quite hard to actually have signals propagate through all these. So I think this is a really exciting area. I'll push you a bit on this. You know, I think a popular view is post-training is elicitation of capabilities that you already trained in pre-training. So what dependencies can you have that feedback into pre-training? So I'm inclined to agree with that view. And I think that that view would lead very strongly to the fact that you should be trying to optimize your pre-training data to make post-training processes more effective.
53:20So you should try to figure out how do I optimize my pre-training data so that the slope of the test time compute curve or so that the slope of the RL curve is as steep as you possibly can be. Or alternatively, how do I optimize my pre-training data so that the slope of the jailbreaking curve is as shallow as possible? Fundamentally, I think alignment in post-training doesn't really make sense as a long-term solution. If you can easily align a model through post-training, you can easily misalign a model through post-training. If it's easy to put it in, it's easy to take it out. If it's really hard to put it in, it's really hard to take it out.
53:49That's just like a truism of models, right? So if you do alignment during pre-training, you'll actually end up with models that are, I think, largely impossible to misalign without putting a massive amount of data into them. I think there are a lot of benefits to that. And I think we've also seen evidence for this, like looking at the difference between Lama and Quen with respect to their ability to be post-trained, right? It's much easier to RL Quen than it is to do Lama. Likely that has to do with the fact that Quen put a lot of synthetic reasoning traces into their training data. Even with wrong examples.
54:15Yeah, but even with wrong examples, that's where it's still going there, which is wild, right? But I think that pretty clearly shows that it's the base model that's doing it. It's not the rewards you're giving. If you give random rewards and the model still learns, it's probably not the reward signal that's doing it. That's cool. I'm just curious on the customer usage. How many people are doing post-training? Obviously, nobody today because you don't have it. But when people come to you, are people looking mostly to do post-training on open models, on open AI models, or what do they ask for? Yeah, so we usually work with folks who are either training their own models from scratch or doing continued pre-training on an open model with a bunch of domain-specific data that they have that's unique to their use cases and their business.
55:02We typically focus on folks that are doing training at significant cost. So typically that means at least a couple tens of billions of tokens, oftentimes more. So kind of the standard small-scale post-training fine-tuning case, we don't focus as much on. That said, I think this has been a question that a lot of people have asked us consistently, like, hey, who's actually training their own models? Like, why don't I just rely on this, rely on the open models? And I think there are a number of reasons why we see people do this. So first off, I think Sovereign AI has been a pretty big place where we've seen a lot of demand.
55:32Lots of countries, they want to have models that they own that are unique to their language, their culture. And, you know, that requires them to have really good data curation, of course, in order to do this effectively. Just to double click, countries owning models isn't actually a thing that I know about. I'm from Singapore. We have the SEAL model, but it's not owned by a country. And I can't name any other country that owns a model. Yeah, I think that's actually correct. It's largely what you see right now is these public-private partnerships where governments are making pretty large grants.
56:01TII UAE is like the closest. Yeah, I think you have those. I think you also have these places where the funding is the country and it becomes a little unclear where it comes from. But yeah, I think usually what you see is that countries are doing big grants to private companies or public-private partnerships to go and build that sort of thing. So that's a big thing. I think we've seen a lot of larger enterprises that have a lot of their own data that want to do this. And when you think about this, ultimately what we see is that, okay, across those three value plots, train faster, train better, train smaller, like which matters and when.
56:33Like train faster, in principle, that's the easiest one to compute. I say, okay, this model would have cost you$10 million to train. I get it to you for$1 million or for$800 ,000 or whatever, right? Great. I saved you a ton of money. In practice, though, nobody wants to train a$10 million model for$1 million. But they already have the model. They already have that. They want to train a$100 million model for$10 million. You know, they want train better. So train faster usually doesn't matter so much from the perspective of, hey, this model is now a lot cheaper. It does matter a lot more from the perspective of you can iterate much faster, right?
57:04Because when you think of the workflow of most ML engineers, you start a training, you go and you sit on your hands until the training finishes. You know, you find something else to do, but largely you're waiting and your iteration is bounded by how long that takes. If you can take something from taking 10 days for a model to finish training to being overnight, now your existing team is way more productive and can do far more iterations and stuff like that. So that's where we usually see that matter the most. Most people care the most about train better, right? I can get a better model for the same compute and we can absolutely deliver that through data.
57:32Data is effectively a compute multiplier, right? Because all models are underfitting their data sets, if you can make your model more data efficient, you effectively make your compute more valuable. Because if you think about compute as I inject a certain number of dollars and I get a certain performance back, if I use better data, then I will get more performance back per dollar invested and now my compute is more valuable. So that's where train better, I think, tends to be the most meaningful thing. But interestingly, for the most companies that are most advanced on their AI transformation transformation journey.
58:00Train smaller is the one that I think actually means the most. Because when you think about the total cost of ownership of these models, it's going to be very, very heavily weighted towards inference. It's all inference. And, you know, you think about a company that's spending, say, 50 mil a year on inference, which in the scheme of things is not very much, right? If you deploy a model that's twice as big as it needs to be, that's going to cost you 25 mil in year one. The cost to train a model that has fewer than half the parameters but is just as good or even better at your particular use cases is, say,$2 million or$3 million.
58:32That's a no-brainer if you can do it easily, right? If it's really hard, then you're never going to do that. But if you can do it easily and you can get it right on the first try, that's a no-brainer. And then 50 million years is not going to be very much, right? We know that all of these products have a tiny, tiny fraction of what their eventual user bases will be, right? We're still very much in the first inning here. You know, everyone that listens to this podcast is using AI nonstop, but the rest of the world is not yet. So the inference costs are going to skyrocket with these models. And if you use a general purpose model, then you constrain to say, hey, this model knows about everything, but now only do this one thing.
59:09That model is going to have a ton of parameters that do not need to be there that are going to massively increase the cost of serving that model. So I think that, you know, when you think about the use case of an enterprise where they need a model that's an inch wide and a mile deep. It can do a small handful of things, but it can do that really, really effectively to five nines of reliability, and it can do it for as low a cost as possible. The economics make it so that it really makes a lot of sense to do this yourself if you can do it easily. And the way we think about it is that there were kind of two big barriers.
59:41First, you have to get training right, and then you got to get data right. And on the training side, I think three years ago, this was super hard, right? But Mosaic was the first one to really recognize that there was a huge opportunity and making this easy. And now this has largely been commoditized by things like SageMaker and Together and lots of different folks that help you on the training side. But on the data side, the barrier is just as high as ever. And in many ways, that's our mission at Datology is how do we bring that barrier down so that anyone who wants to train a model can do so with the best quality data on their first try.
1:00:09They don't have to go and spend 40 years in the desert. They don't have to get it wrong 100 times first, which is what will happen if you don't have this experience. But instead on the first shot, they get a really great model. Yeah. Yeah. Just a follow-up question on train smaller. Yeah, I fully agree. And I think that this is something a lot of people are investing in. You are primarily doing work on the data side, data pruning, which maybe is a bad word now, data curation, whatever. I think a lot of people, you know, Jonathan Franco was on the podcast very early on, but a lot of people were betting on pruning the model itself.
1:00:41Like you have a working model at size and you just lop off anything above like a certain epsilon. Is that confirmed to just be dead? So it's funny. Jonathan actually interned with me when I was at Meta, and we worked on this stuff together. You know, he had the lottery ticket hypothesis, which is a really beautiful paper. Which he now completely disowns. Which he largely disowns. You know, I had this whole idea when Jonathan and I worked together that we wanted to create a lottery ticket initialization. It would just be an initialization you'd sample from for initializing the weights that would then be one of these, like, perfect winning ticket initializations.
1:01:14But we actually found out that the problem was that the lottery ticket was actually data dependent. And that was where the fundamental problem came, that as soon as you change the data distribution a little bit, like the winning tickets changed in a really big way. I don't think pruning is dead. Parameter pruning still absolutely has a place. But I think certainly we found it challenging to really realize the potential of it. I think one of the big tricks with pruning, parameter pruning, just to be clear, was that unstructured pruning, when you would prune weights randomly. So you view all the weights as a smorgasbord and just prune them randomly.
1:01:48That worked really well. And you could remove massive quantities of the weights with unstructured pruning. The problem is that unstructured pruning doesn't really give you a clear compute advantage because you need to have a sparse matrix now to reflect this. And there's a pretty huge overhead of sparse matrix multiplies. GPUs are not very good at sparse matrix multiplies. Like, there's some support for them now. There's some hardware optimizations for that. And there's some hardware, and people talked about like building ASICs that would be really good at unstructured pruning, but I don't think I've seen one that works super well.
1:02:19I think if someone did make something that worked really well for kind of models that were pruned in an unstructured way, that could be effective. Structured pruning, in which case you just like remove a unit, you just remove a neuron, that is really easy to make as a faster in a GPU, but that just doesn't work nearly as well. So, you know, I think there's still potential here. I don't think it's the panacea that I and I think many others had hoped. That said, I think one thing that's cool about using better data to train smaller models is that it's complementary with any other approaches for optimizing inference.
1:02:52So, you know, I think pruning and quantization obviously still have a lot of role to play in helping inference go faster. And that would stack on top of anything that we're doing, which I think is kind of cool. Yeah. One also, I think, kind of a grand challenge, golden question that'd be very valuable for you, and just in general, is this idea of like, what is the smallest possible model for a given capability? Do you have any insights on that? I did a podcast with Jack Morris, who's out of Cornell. And, you know, I think like there's like some information limit. And I think he had some answer, like, you know, it's like eight bits per parameter or something like that.
1:03:27I forget what the conclusion was. Yeah, I'm not sure if I would put out a specific number, but I would definitely say far, far smaller than what our current models are trained to be. Right. Like, we are nowhere close to this. And, like, I am generally of the belief that most of the models that the vast majority of people will be using in, say, three years will be single-digit B or smaller. I think we've seen this very clearly. Like, you look at just, like, the Llama series. You know, if you want to exclude Llama 4, do so. But, you know, LAMA 1 through 3, you can see pretty clearly that, you know, the 7B variant from N plus 1 generation is, like, pretty close to the 7B variant from the prior generation, you know, if it's not quite there.
1:04:11But there's still a very clear trend here. We're seeing this with the QN models, right? You look at some of these small QN models, and they're just incredibly performant relative to what state-of-the-art was, you know, a year ago. I think it's pretty clear that these models are way too big. I personally would bet against kind of the next frontier being trillion parameter models and rather that, you know, we're going to really optimize the inference cost of that. I think also test time compute as a paradigm really pushes you towards smaller models, right? Because if your cost of solving a problem is cost of inference times number of thinking steps and you have to do a lot of thinking steps, well, now this is like a really – like minimizing the cost of inference is really important.
1:04:54And I think that, you know, anything we can do to make it so that you can just make that inference model that is doing the one step of thinking a lot faster enables test time compute to be a lot more effective. Yeah, I think there's another version of this, which is the sort of Andre Karpathy cognitive core concept of a model that doesn't know anything, but can use tools a lot to figure out. again another information theoretical limit that would be very helpful to figure out is what is the minimal viable model for that stuff like a zero on gpqa 100 on browse conf i really like that idea and i think it's very possible to do that because like knowledge storing takes a lot of capacity yeah it takes a lot of parameters you don't need it and you don't need it and you know we can just look like there are there like actually one of my first papers that i ever wrote was actually about showing that when you train models on randomized labels because this was something that was kind of a common test to do.
1:05:48That was the one way you could prove that a model was memorizing would be that you randomize all the labels and now there's no actual true association and would have to memorize it. And like models could do this really well. There was like an iClear best paper from 2017 that showed this, that people were really surprised that models could memorize all of ImageNet. Now this seems crazy because of course models can memorize the whole internet. But at the time that was like crazy. Wait, they could just memorize a million labels? Like that's wild. And what we found there actually was that if you went and you just deleted units with a model that memorized, it would be really damaging to the model that memorized.
1:06:17But a model that actually learned a generalizing solution, you could delete a lot of units and it would be pretty robust to that. So it's actually a very clear demonstration of exactly this concept that the more you memorize, the more capacity you're using. Dropout regularization. There's a lot of dualities to drop out. And I think there's an argument to me that dropout helps to prevent memorization and it helps to learn more generalizable solutions. And that's part of why it worked well. But yeah, I think it's very possible to do this. And like, I think we're wasting a ton of capacity in these models on knowledge that is just totally unnecessary for them to have.
1:06:49Before we wrap, just because we started with the RC models and then we never talked about them. I think the most interesting thing to me was they started with 23 trillion tokens of data and then you help them get down to 6.6 trillion. Any learnings from that? And this is a 4.5B model, which is par with Gemma 4B and a little worse than QAN3. but roughly the same. Any learnings there, experiences, things that other open models should adopt? So yeah, so we started for that one. We started with a combination of DCLM, Nemetron, and FineWeb. We basically just concatenate them all together. It's about 25 trillion tokens to combine for all those to produce 7 trillion out of that.
1:07:27You know, I mean, I think what was exciting to us about that was in general, you know, seeing the speed at which the model learned. So, you know, it was beating Gemma pretty consistently before the 1 trillion mark, which was pretty cool to see. And I think really highlighted in many ways, how higher quality data can get you much better performance much more quickly. General insights, I think, or takeaways from that. I mean, I think it was exciting for us as kind of one of our first real, like R.C. is the first customer that we're talking about and being public about since starting the company.
1:07:55So obviously that was an exciting moment. But I think really generally it's a good showcase about the fact that combining all of these different techniques can give you a really big gain. I think that's one of the things we've been saying, but it's nice to have a real demonstration about that. You know, this is not something where it was synthetic data taking us here or it was filtering taking us here. It was really about thinking about how do we actually combine all of these techniques. And one of the things we've consistently found, actually, is that when you take these different techniques and you try to make them work together, they don't generally.
1:08:23You can make them work together, but it's quite hard to do so. So I think what was quite exciting for us there was showing that that's possible. And then combined with that, I think people, first off, tend to think that you can't stack curation. I think the fact that we started with some of the best curated open data sets and were able to make them dramatically better is a pretty good insight to the fact that there's still a ton of headroom left here. Like, we didn't need to go to Common Crawl to get those tokens. We are, of course, doing work on that. And we think there's a lot we can do to improve there.
1:08:52But just starting from that, and we actually now are making bigger data sets from that, I think we can get up to$15 trillion just starting from that corpus and still have pretty identical quality to that, which is pretty neat. So I think showing that you can get there and then the other and that really stacks. Like one of the other things we consistently find is that if we apply our curation on top of, say, DCLM and then we apply it on top of FineWeb, the gap between FineWeb and DCLM is maintained in the gap between kind of Datology curated DCLM and Datology curated FineWeb. They both get a lot better, but Datology DCLM is still better than Datology FineWeb.
1:09:25So, you know, there really is a lot that we can do here. And I think that would be the biggest thing that I would just say. There's so much still left to do here. we're just scratching the surface. We're pretty excited about what these results showed. We already have better data sets than what RSC trained on because that model was largely trained in May and pretty excited about all the next trainings that we'll have that go even bigger. I have a couple more lightning fun questions. What data does everyone want, based on your customer conversation, what data does everyone want, but it's really hard to get?
1:09:54I mean, I think expert data is the pretty obvious thing. Just domain experts. Domain expertise. That said, I would also note that most people don't know what data they actually should be getting. They just show up with whatever they have. Yeah. And I think something we've actually found shockingly frequently is we talked to folks who have been planning for a really expensive training run, millions and millions of dollars training run. They've been thinking about the architecture they're going to use. They've been thinking about all this stuff. And then they reach out to us and they're like, hey, we realized we need a good data set and we're planning to kick off training in two weeks.
1:10:24Can you help us? And a lot of it's like, hey, you probably should be thinking about your data set before all the other things. If anything, that's actually the most important thing. So I think, honestly, the most surprising thing is maybe how often people don't even have a conception of what good data is. And oftentimes, I think when people, what they think is good data often isn't, which goes to the DCLM point, I think that we mentioned in the past. It's very counterintuitive and really hard for humans to identify this is high quality, this is low quality. This is a little bit of a recruiting question.
1:10:55What data efficiency question, if somebody had an answer, they should join Datology immediately? The first thing I would just say is like, if you are one of these people that keeps on finding yourself, just like staring at the data, you keep on going into the data set. If you can tell me what your favorite and least favorite C4 example is, like you belong at Datology, you should come join us and join a bunch of other nerds that love doing that exact same thing. I think in many ways, that's kind of the single biggest predictor of whether someone is going to be really happy at Datology is like, how much do you just look at the data in your own work?
1:11:30Because I think you'd be surprised by how many really talented researchers don't do it very often, that they really just view it as a given. I think it's been pretty surprising across the board. That said, there are so many questions that I am on the science side that I'm just super excited about. I mentioned the interaction between pre and post training. That's definitely one that we're really excited about. One of the things that we really care a lot about is making it so that our product and curation automatically adapts to novel data distributions, right? If you have this where it has to be fully automated, and, you know, we didn't talk about this too much, but one of our challenges often is if we're working with an enterprise that has a lot of proprietary data, they obviously don't want to give that to us.
1:12:09So we bring our curation to their data, but this means that it has to adapt automatically. You know, we have pretty limited access into going and looking at that data. So that's actually a really hairy and interesting out-of-distribution generalization problem, but it's also really important because there's no golden curation. A curation is only optimal with respect to a given set of downstream use cases or tasks, right? So we need to be able to define based off of, you know, if the model needs to be able to do X, Y, Z, how should we use that information to adjust the curation that we do to make sure that we're giving the data that's most relevant for solving tasks X, Y, Z?
1:12:45And that needs to happen automatically. So we have a number of ways that we can do that for a number of our techniques, but that's a very broad and general question that we want to apply to every part of our pipeline So that the way we do synthetic data differs based off of the downstream use cases, the way we're doing this, the way we're doing every different part, filtering, et cetera, is going to change based off of that. So that's another question that we're just really excited about. And fundamentally, you know, anything about really trying to answer this question about, you know, how do you value data with respect to a target?
1:13:12You know, when I think of Datology and our core competency, I think every company needs to have an unfair advantage or some core competency that they do better than anyone else. And for us at Datology, I want us to be, and I think we already are, the best in the world at valuing data with respect to a downstream use case. In many ways, I think that's kind of the NP-complete problem of AI. If you can do that, you can kind of do anything. And that's the thing that we're really focused on. And, of course, curation is like the very obvious direct application of that core competency. But when we think about kind of the vision for the company in the long term, it's about saying what are all the other ways we can operationalize that same core skill set.
1:13:50And I think there are tons of really interesting ways, things you can do there. But that's the fundamental question that we really want to answer. And then there are tons of different, you know, entry points to that question. But if that's a question that excites you, if you have, you know, been working on data somewhere else and you have felt this pain of being, you know, a second class citizen or having the data team be kind of dismissed and you want to be in a place where literally the only reason that the company exists is because data is all we care about. I mean, the name of the company, Datology, the science of data, that's why we're here.
1:14:22Then you should absolutely talk to us. Awesome. And just to wrap on some gossip, let's talk about meta and super intelligence. So and just in the notes, you know, when you talk about science moat and whatnot, you raised a lot of money from very prominent people. So you have, you know, Yann LeCun as one of your investors, Jeffrey Hinton, Jeff Dean. And so when Ari says that they have a science mode, believe it. So maybe since you have Jan as an investor, this is more of a touchy question, but what do you make of the whole meta super intelligence team? And, you know, Jan was also on LinkedIn and he was like, hey, you know, I'm actually working on, you know, I fear we're focused on the next generation of AI, not on this current generation.
1:15:06So my role is the same. but then maybe people might say, you know, then why didn't you do the current generation 10 years ago? What do you make of the whole change and whether or not you think this is an interesting direction for Meta, especially given the large platform and user base that they have? Well, first, with respect to Jan specifically, I mean, Jan's an incredibly talented scientist, of course, but I think that, you know, his preference has always been to do science rather than to run an organization. So I think he ran fair, like, organizationally for a year or two right at the very beginning, but pretty quickly he handed that off to other people.
1:15:38And like when I was there, it was Joelle Pinot and Antoine Bords and then Joelle for most of it that really were running for us. And she was an incredible leader. I really respect her deeply and couldn't have asked for a better kind of advocate for science within FAIR. When she left, people were saying like, this is the end of FAIR. I hope that's not true. But I also had that concern. But I think Jan always really wanted to just actually do the science himself. And, you know, he's generally for much of, most of the time I was at FAIR, He kind of operated with his own group of a couple kind of postdocs and visiting scientists.
1:16:10And then he'd have a couple of students through NYU and he would kind of do his own research there. So I don't think he was ever, you know, or at least not since the beginning in a role where he was defining AI strategy for meta. I don't think that's the role he wanted at any point. You know, I think he really wanted to be doing that research. And I think so I don't think that his role probably is changing very significantly in the sense that he wasn't doing that previously. And I don't think it was what he wanted to do. I mean, I think one thing that's pretty cool about it, obviously, is it showcases the importance of data that Meta is willing to spend quite this much on, you know, scale, kind of acquisition, not acquisition that we're seeing today.
1:16:44Alex Wang is not going to underrate data. Let's put it that way. Yes, he's not going to underrate the importance of data. And I do think that this is an area where the stuff we've done is quite different than I think what we've seen from the data annotators, which have been more focused on collecting the data versus actually optimizing and curating it. I think there's quite a bit you can do on top of those things. So I think it definitely draws some attention to that. I will also just say generally when Zuck makes a very big bet, it's not proven wise to bet against him. Just historically, that's been the case.
1:17:16And most of the big bets, I think, have panned out. I think the one that's still really up in the air is the metaverse. But I would actually argue that I think that's going to end up paying off in the long run. I think the Ray-Ban glasses are pretty darn cool. And a lot of the foundations of what was in Reality Labs will go into those. Also, FAIR was part of Reality Labs, actually, for like a year and a half after one re-org. Like initially, FAIR wasn't, and then it got re-org into Reality Labs. So I think when I left, actually, FAIR was officially part of Reality Labs, if I recall correctly. And there's at least a one and a half, two-year period where that was the case.
1:17:46So some of the AI investment actually that like laid the foundations came out of that metaverse investment in the first place. You know, that said, I think, you know, we talk about data as being a compute multiplier all the time. Talent, I think, obviously is a compute multiplier. And given the amounts that they're spending on compute, I think you can make a good argument as to why spending a crazy amount on talent is also worth it. So I'm excited to see what they do. I hope that they put a lot of focus on data. And become customers. Yes. Awesome. Well, thank you so much for chatting and coming by and insisting on in-person because you're actually very charismatic in person.
1:18:22So I'm glad you did this. Well, thank you very much. Thanks for having me and a joy to get to chat in real life. Awesome. Cool.
From the publisher
Our chat with Ari shows that data curation is the most impactful and underinvested area in AI. He argues that the prevailing focus on model architecture and compute scaling overlooks the “bitter lesson” that “models are what they eat.” Effective data curation—a sophisticated process involving filtering, rebalancing, sequencing (curriculum), and synthetic data generation—allows for training models that are simultaneously faster, better, and smaller. Morcos recounts his personal journey from focusing on model-centric inductive biases to realizing that data quality is the primary lever for breaking the diminishing returns of naive scaling laws. Datology’s mission is to automate this complex curation process, making state-of-the-art data accessible to any organization and enabling a new paradigm of AI development where data efficiency, not just raw scale, drives progress.
Full Video Episode
Timestamps
00:00 Introduction
00:46 What is Datology? The mission to train models faster, better, and smaller through data curation.
01:59 Ari’s background: From neuroscience to realizing the “Bitter Lesson” of AI.
05:30 Key Insight: Inductive biases from architecture become less important and even harmful as data scale increases.
08:08 Thesis: Data is the most underinvested area of AI research relative to its impact.
10:15 Why data work is culturally undervalued in research and industry.
12:19 How self-supervised learning changed everything, moving from a data-scarce to a data-abundant regime.
17:05 Why automated curation is superior to human-in-the-loop, citing the DCLM study.
19:22 The “Elephants vs. Dogs” analogy for managing data redundancy and complexity.
22:46 A brief history and commentary on key datasets (Common Crawl, GitHub, Books3).
26:24 Breaking naive scaling laws by improving data quality to maintain high marginal information gain.
29:07 Datology’s demonstrated impact: Achieving baseline performance 12x faster.
34:19 The business of data: Datology’s moat and its relationship with open-source datasets.
39:12 Synthetic Data Explain
ed: The difference between risky “net-new” creation and powerful “rephrasing.”
49:02 The Resurgence of Curriculum Learning: Why ordering data matters in the underfitting regime.
52:55 The Future of Training: Optimizing pre-training data to make post-training more effective.
54:49 Who is training their own models and why (Sovereign AI, large enterprises).
57:24 “Train Smaller”: Why inference cost makes smaller, specialized models the ultimate goal for enterprises.
01:00:19 The problem with model pruning and why data-side solutions are complementary.
01:03:03 On finding the smallest possible model for a given capability.
01:06:49 Key learnings from the RC foundation model collaboration, proving that data curation “stacks.”
01:09:46 Lightning Round: What data everyone wants & who should work at Datology.
01:14:24 Commentary on Meta’s superintelligence efforts and Yann LeCun’s role.
This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit www.latent.space/subscribe



