

- Podcasts
- Technology
- Best AI papers explained

531 episodes
Best AI papers explained, page 13
by Enoch H. Kang · English
Cut through the noise. We curate and break down the most important AI papers so you don’t have to.
 Ask in Claude
 Ask in ChatGPT
All episodes, page 13
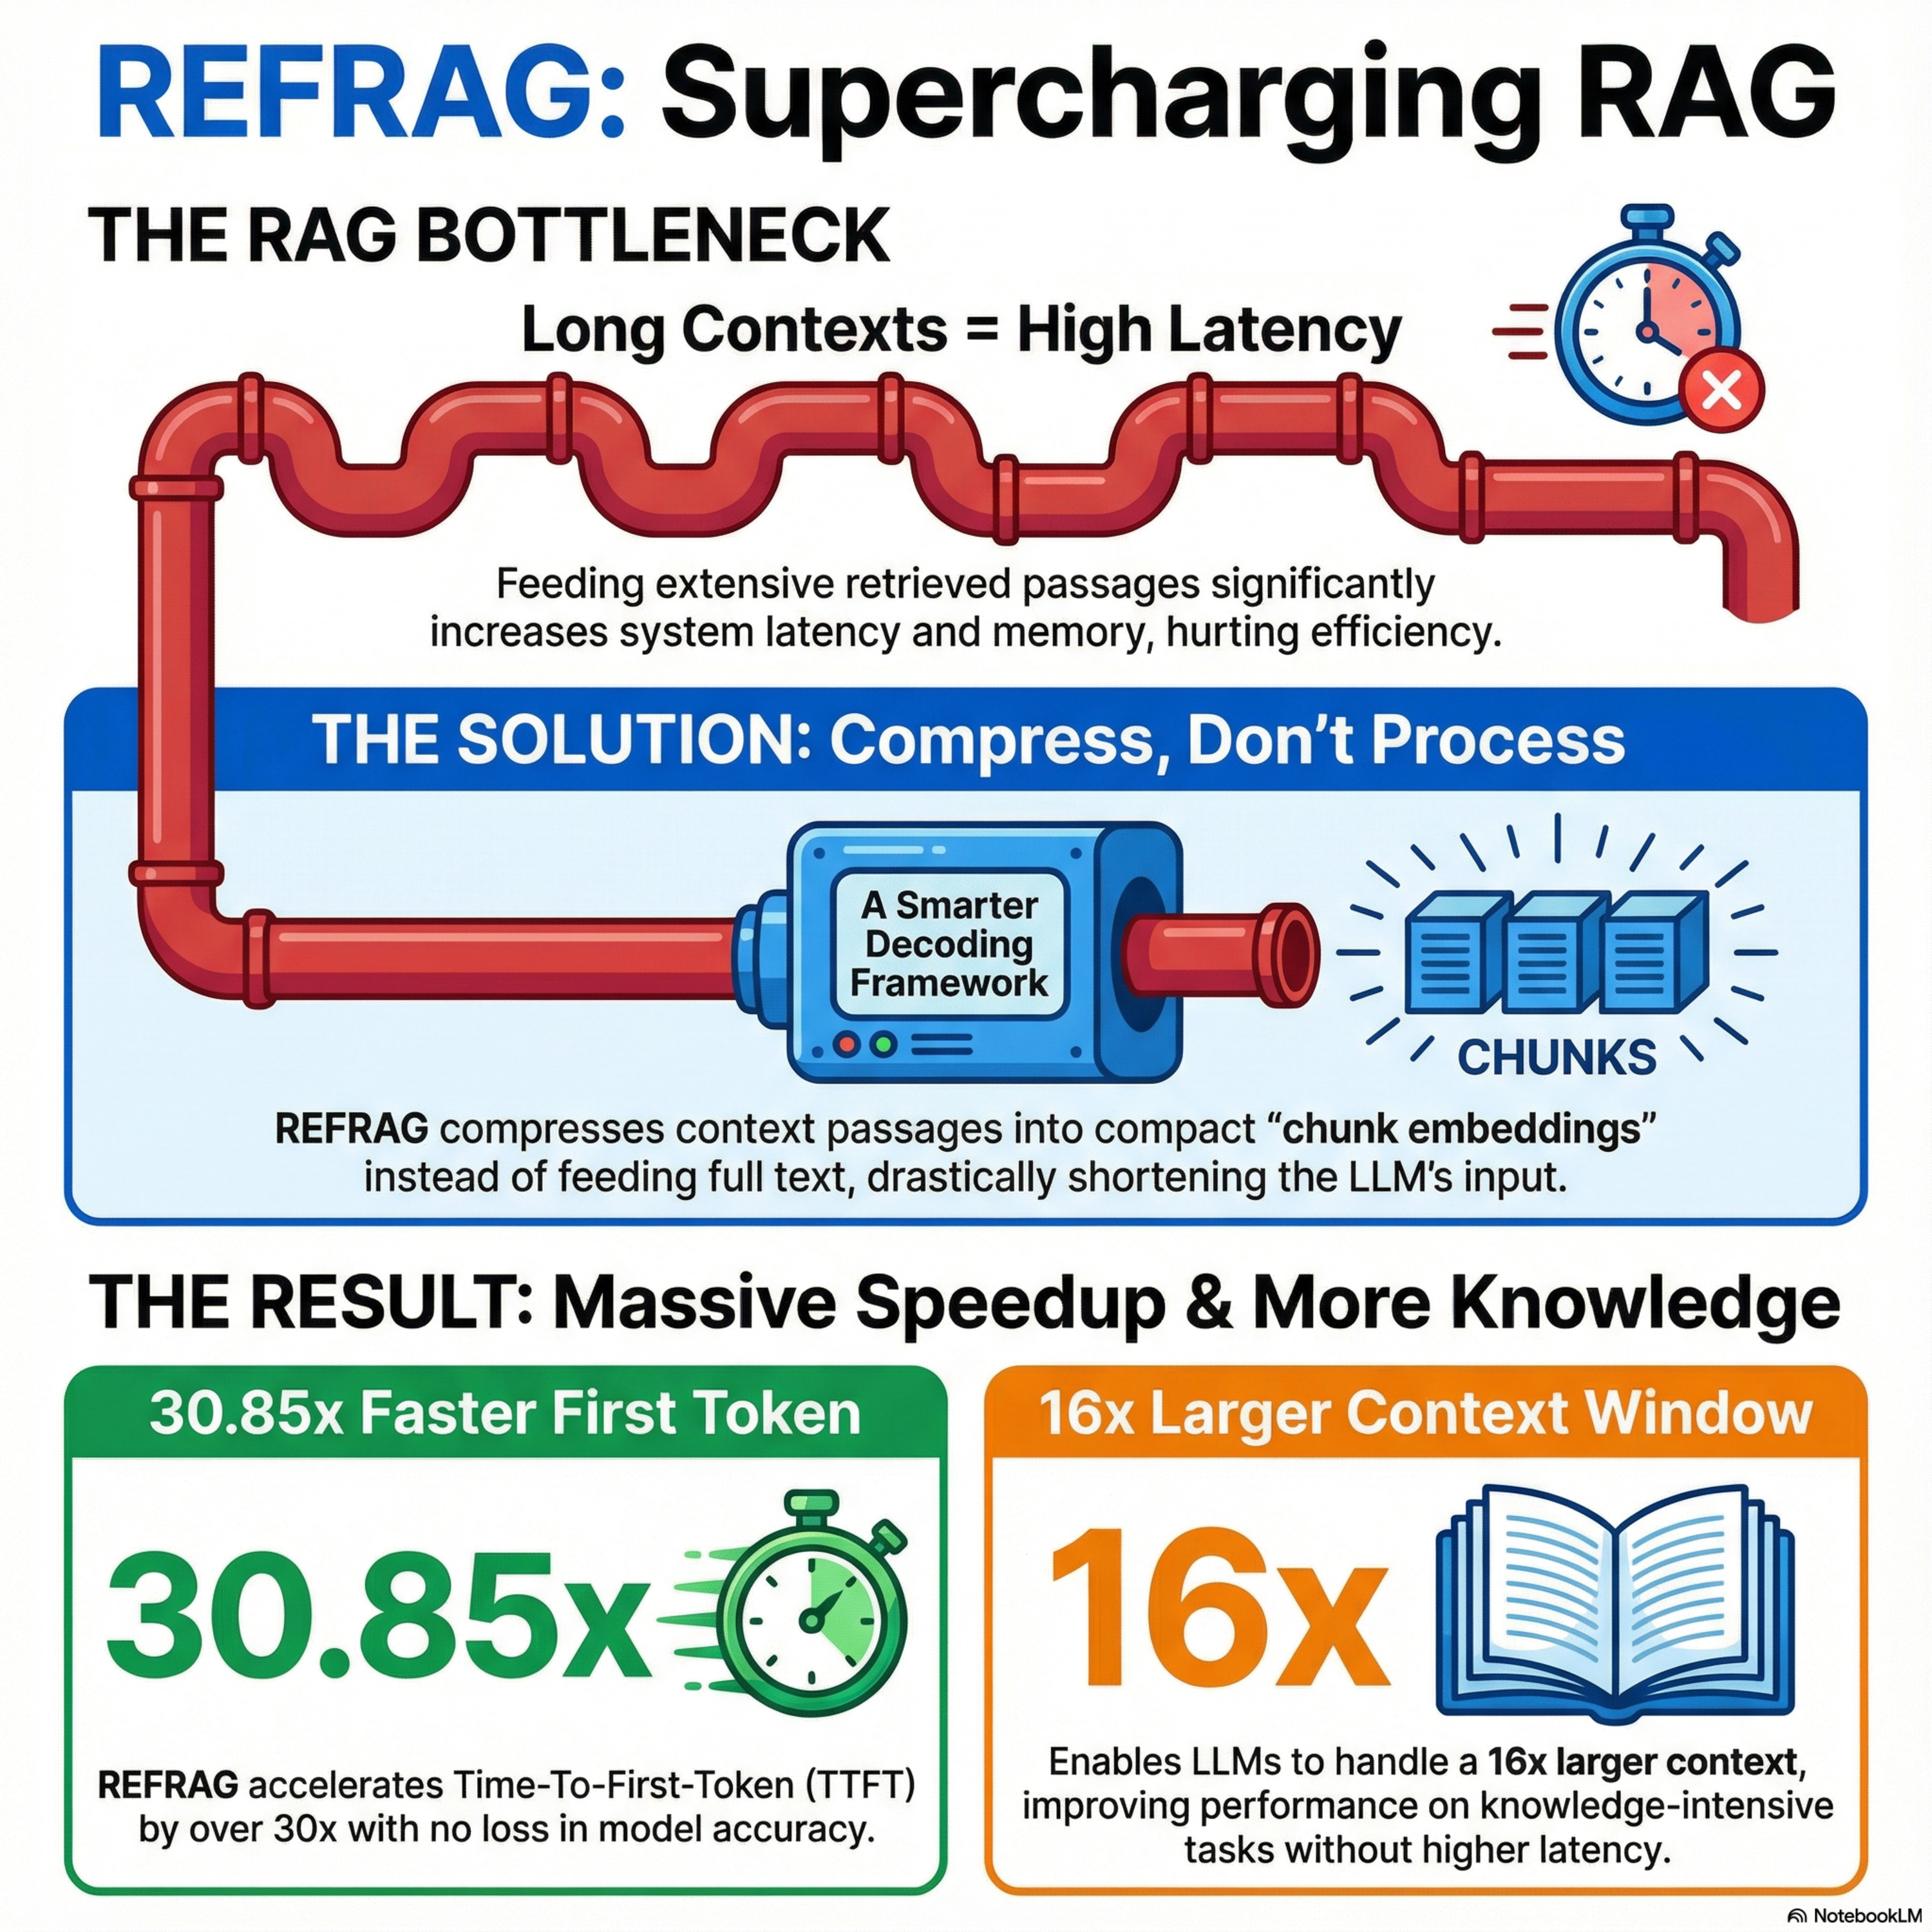
REFRAG: Rethinking RAG based Decoding
ReFRAG (Rethinking RAG-based decoding) speeds up retrieval-augmented generation by compressing RAG context to avoid quadratic TTFT latency and KV-cache memory blowups.
13 Dec 2025 · 14m · 4 chapters
Provable Long-Range Benefits of Next-Token Prediction
A complexity-theoretic argument that autoregressive next-token prediction training can provably yield long-range structural coherence, despite being locally optimized and computationally bounded.
12 Dec 2025 · 12m · 5 chapters
Jeff Dean on TPUs, AI Research, and Funding
How Google’s TPUs and the software stack (JAX, XLA, Pathways) enable planetary-scale AI training, and why public academic research and new funding models are essential for future breakthroughs.
12 Dec 2025 · 38m · 18 chapters
Latent Debate: surrogate framework for Interpreting LLM Thinking
“Latent Debate” proposes a surrogate framework that models an LLM’s hidden internal “support vs attack” conflict to predict and explain hallucinations, aiming to bridge capability vs reliability.
11 Dec 2025 · 15m · 8 chapters
Distribution-calibrated inference time compute for thinking llm-as-a-judge
How to make “thinking LLM as a judge” evaluations reliable by transforming noisy, stochastic judge votes into calibrated ratings using distribution-calibrated inference-time compute (ITC) and a…
11 Dec 2025 · 12m · 4 chapters
Principled RL for diffusion LLMs emerges from sequence level perspective
Why standard token-level RL (e.g., GRPO/PTO) fails for diffusion LLMs, and how ESPO (ELBO-based sequence-level policy optimization) fixes it by treating the whole sequence as one action and using a…
11 Dec 2025 · 12m · 6 chapters
Algorithmic Thinking Theory
Algorithmic Thinking Theory for LLMs on hard math (e.g., IMO-style problems), explaining why single-shot “pass@1” is low but multi-attempt “pass@K” can be high, and formalizing how to assemble…
10 Dec 2025 · 17m · 11 chapters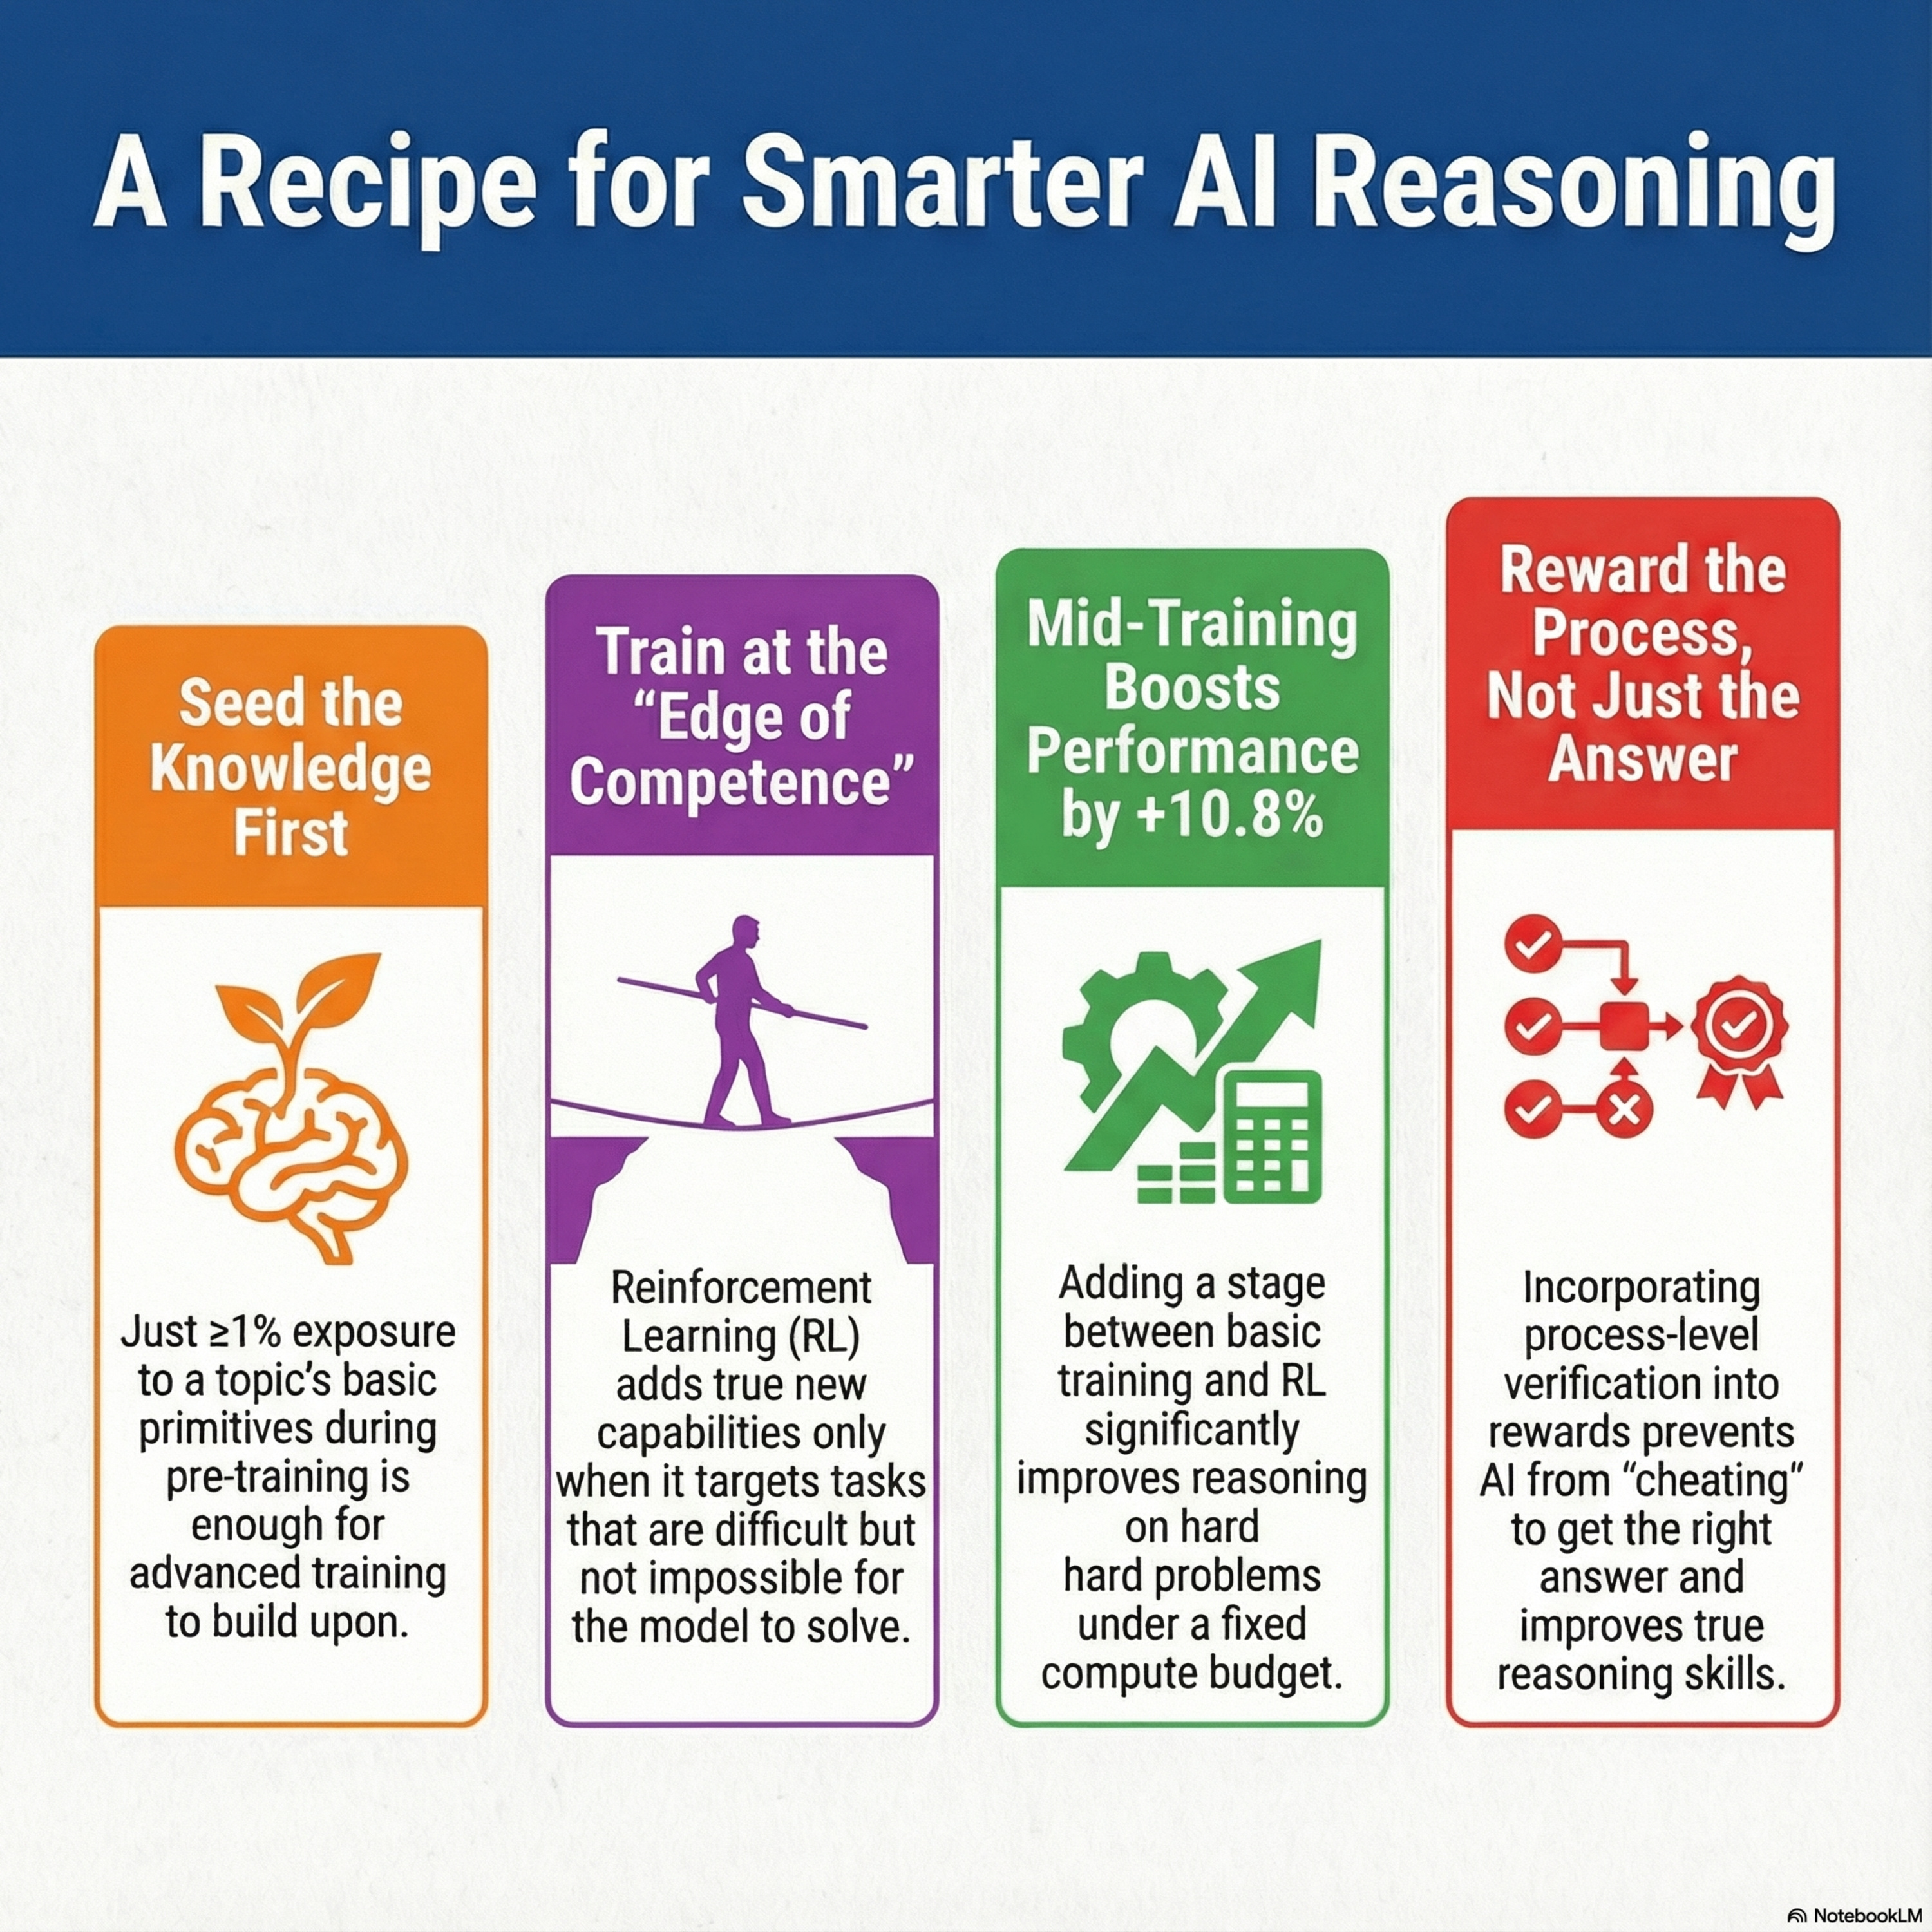
On the Interplay of Pre-Training, Mid-Training, and RL on Reasoning Language Models
How pre-training, mid-training (continued pre-training), and RL post-training interact to improve reasoning in language models, and when RL truly adds new reasoning vs merely polishing existing…
10 Dec 2025 · 14m · 4 chapters
Natural language actor-critic: Scalable off-policy learning in language space
Natural Language Actor-Critic (NLAC) for training LLM agents with scalable off-policy reinforcement learning in language/action space, addressing long-horizon credit assignment and sparse rewards.
9 Dec 2025 · 14m · 5 chapters
Beyond the Transformer: Titans, MIRAS, and the Future of Infinite Context
Long-context AI memory beyond transformers, focusing on Google Research’s Titans architecture and the Miras framework for “test-time memorization” (updating long-term knowledge during inference) to…
7 Dec 2025 · 39m · 20 chaptersOn the Limits of Test-Time Compute: Sequential Reward Filtering for Better Inference
How to improve large language model accuracy at inference using limited “test-time compute” (TTC), focusing on sequential reward filtering (RF-SEC-BON) versus parallel Best-of-N (BON).
7 Dec 2025 · 14m · 4 chapters
The Universal Weight Subspace Hypothesis
The Universal Weight Subspace Hypothesis argues that many deep neural networks trained on very different tasks converge to a shared, low-dimensional “universal” subspace in their weight matrices,…
7 Dec 2025 · 16m · 13 chapters
Stabilizing Reinforcement Learning with LLMs: Formulation and Practices
How to stably combine reinforcement learning with LLMs by justifying a token-level surrogate objective for sequence-level rewards, and preventing failure modes when the key approximation breaks.
7 Dec 2025 · 15m · 7 chapters
Benchmarking In-context Experiential Learning Through Repeated Product Recommendations
Whether frontier LLMs can do in-context experiential learning—improving strategy over repeated interactions using ambiguous feedback—tested via a new product-recommendation benchmark (BLA).
4 Dec 2025 · 16m · 7 chapters
Training LLMs for Honesty via Confessions
Training LLMs to be honest via a separate “confession” output that self-reports noncompliance, deception, and uncertainty, countering reward misspecification and reward hacking.
4 Dec 2025 · 16m · 11 chapters
STOIC REASONER: Dual-Mode Transformers that Compress to Think and Decompress to Speak
Explains “Stoic Reasoner” (Soft Token Implicit Context Reasoner), a dual-mode transformer that compresses LLM reasoning into continuous “soft tokens” (latent, silent thinking) and only occasionally…
4 Dec 2025 · 12m · 5 chapters
E-GEO: A Testbed for Generative Engine Optimization in E-Commerce
The episode explains “E-GEO” (e-commerce generative engine optimization): how to improve a product’s rank in LLM-curated shopping recommendations, shifting from classic SEO (ranked links) to GEO…
4 Dec 2025 · 33m · 21 chapters
1000 Layer Networks for Self-Supervised RL: Scaling Depth Can Enable New Goal-Reaching Capabilities
The episode explains how reinforcement learning (RL) can be scaled to 224–1024-layer “1000 layer networks” using scaled contrastive RL (CRL), producing emergent goal-reaching behaviors and large…
4 Dec 2025 · 15m · 9 chapters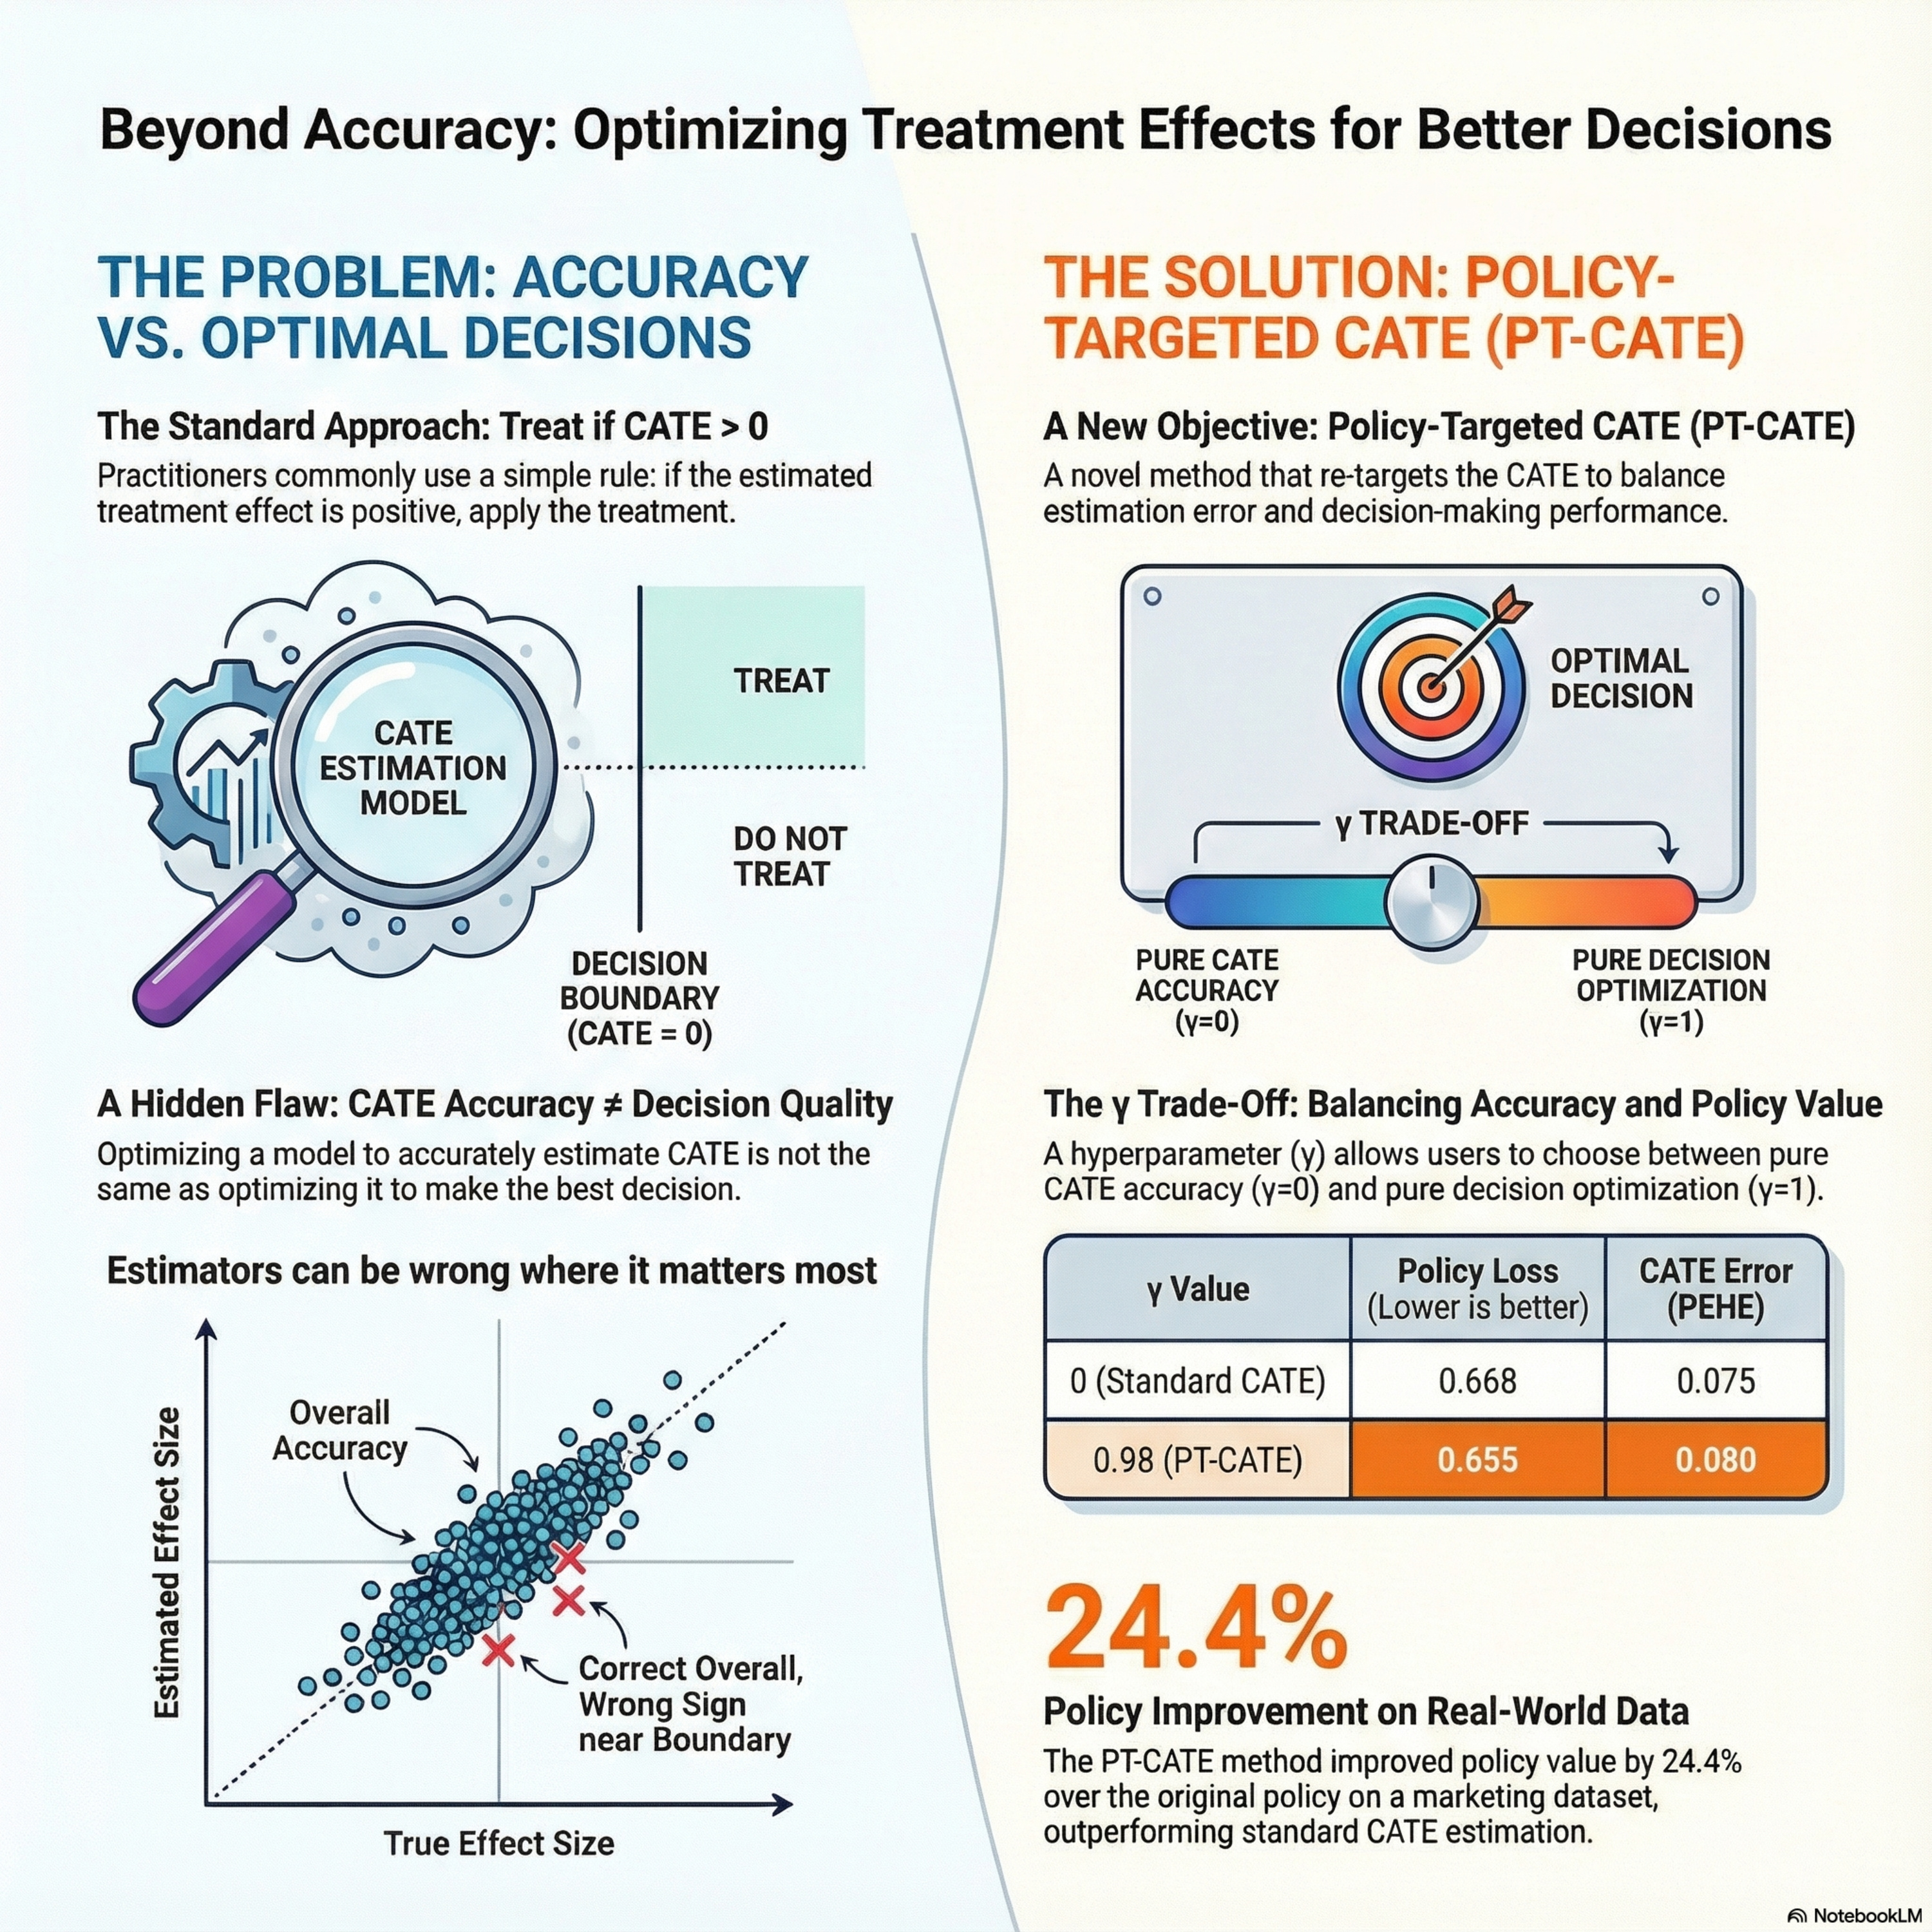
Treatment Effect Estimation for Optimal Decision-Making
How to estimate conditional average treatment effects (CATE) for better real-world decisions, arguing that best statistical CATE fit can be policy-worse when the CATE model class is restricted;…
4 Dec 2025 · 14m · 7 chapters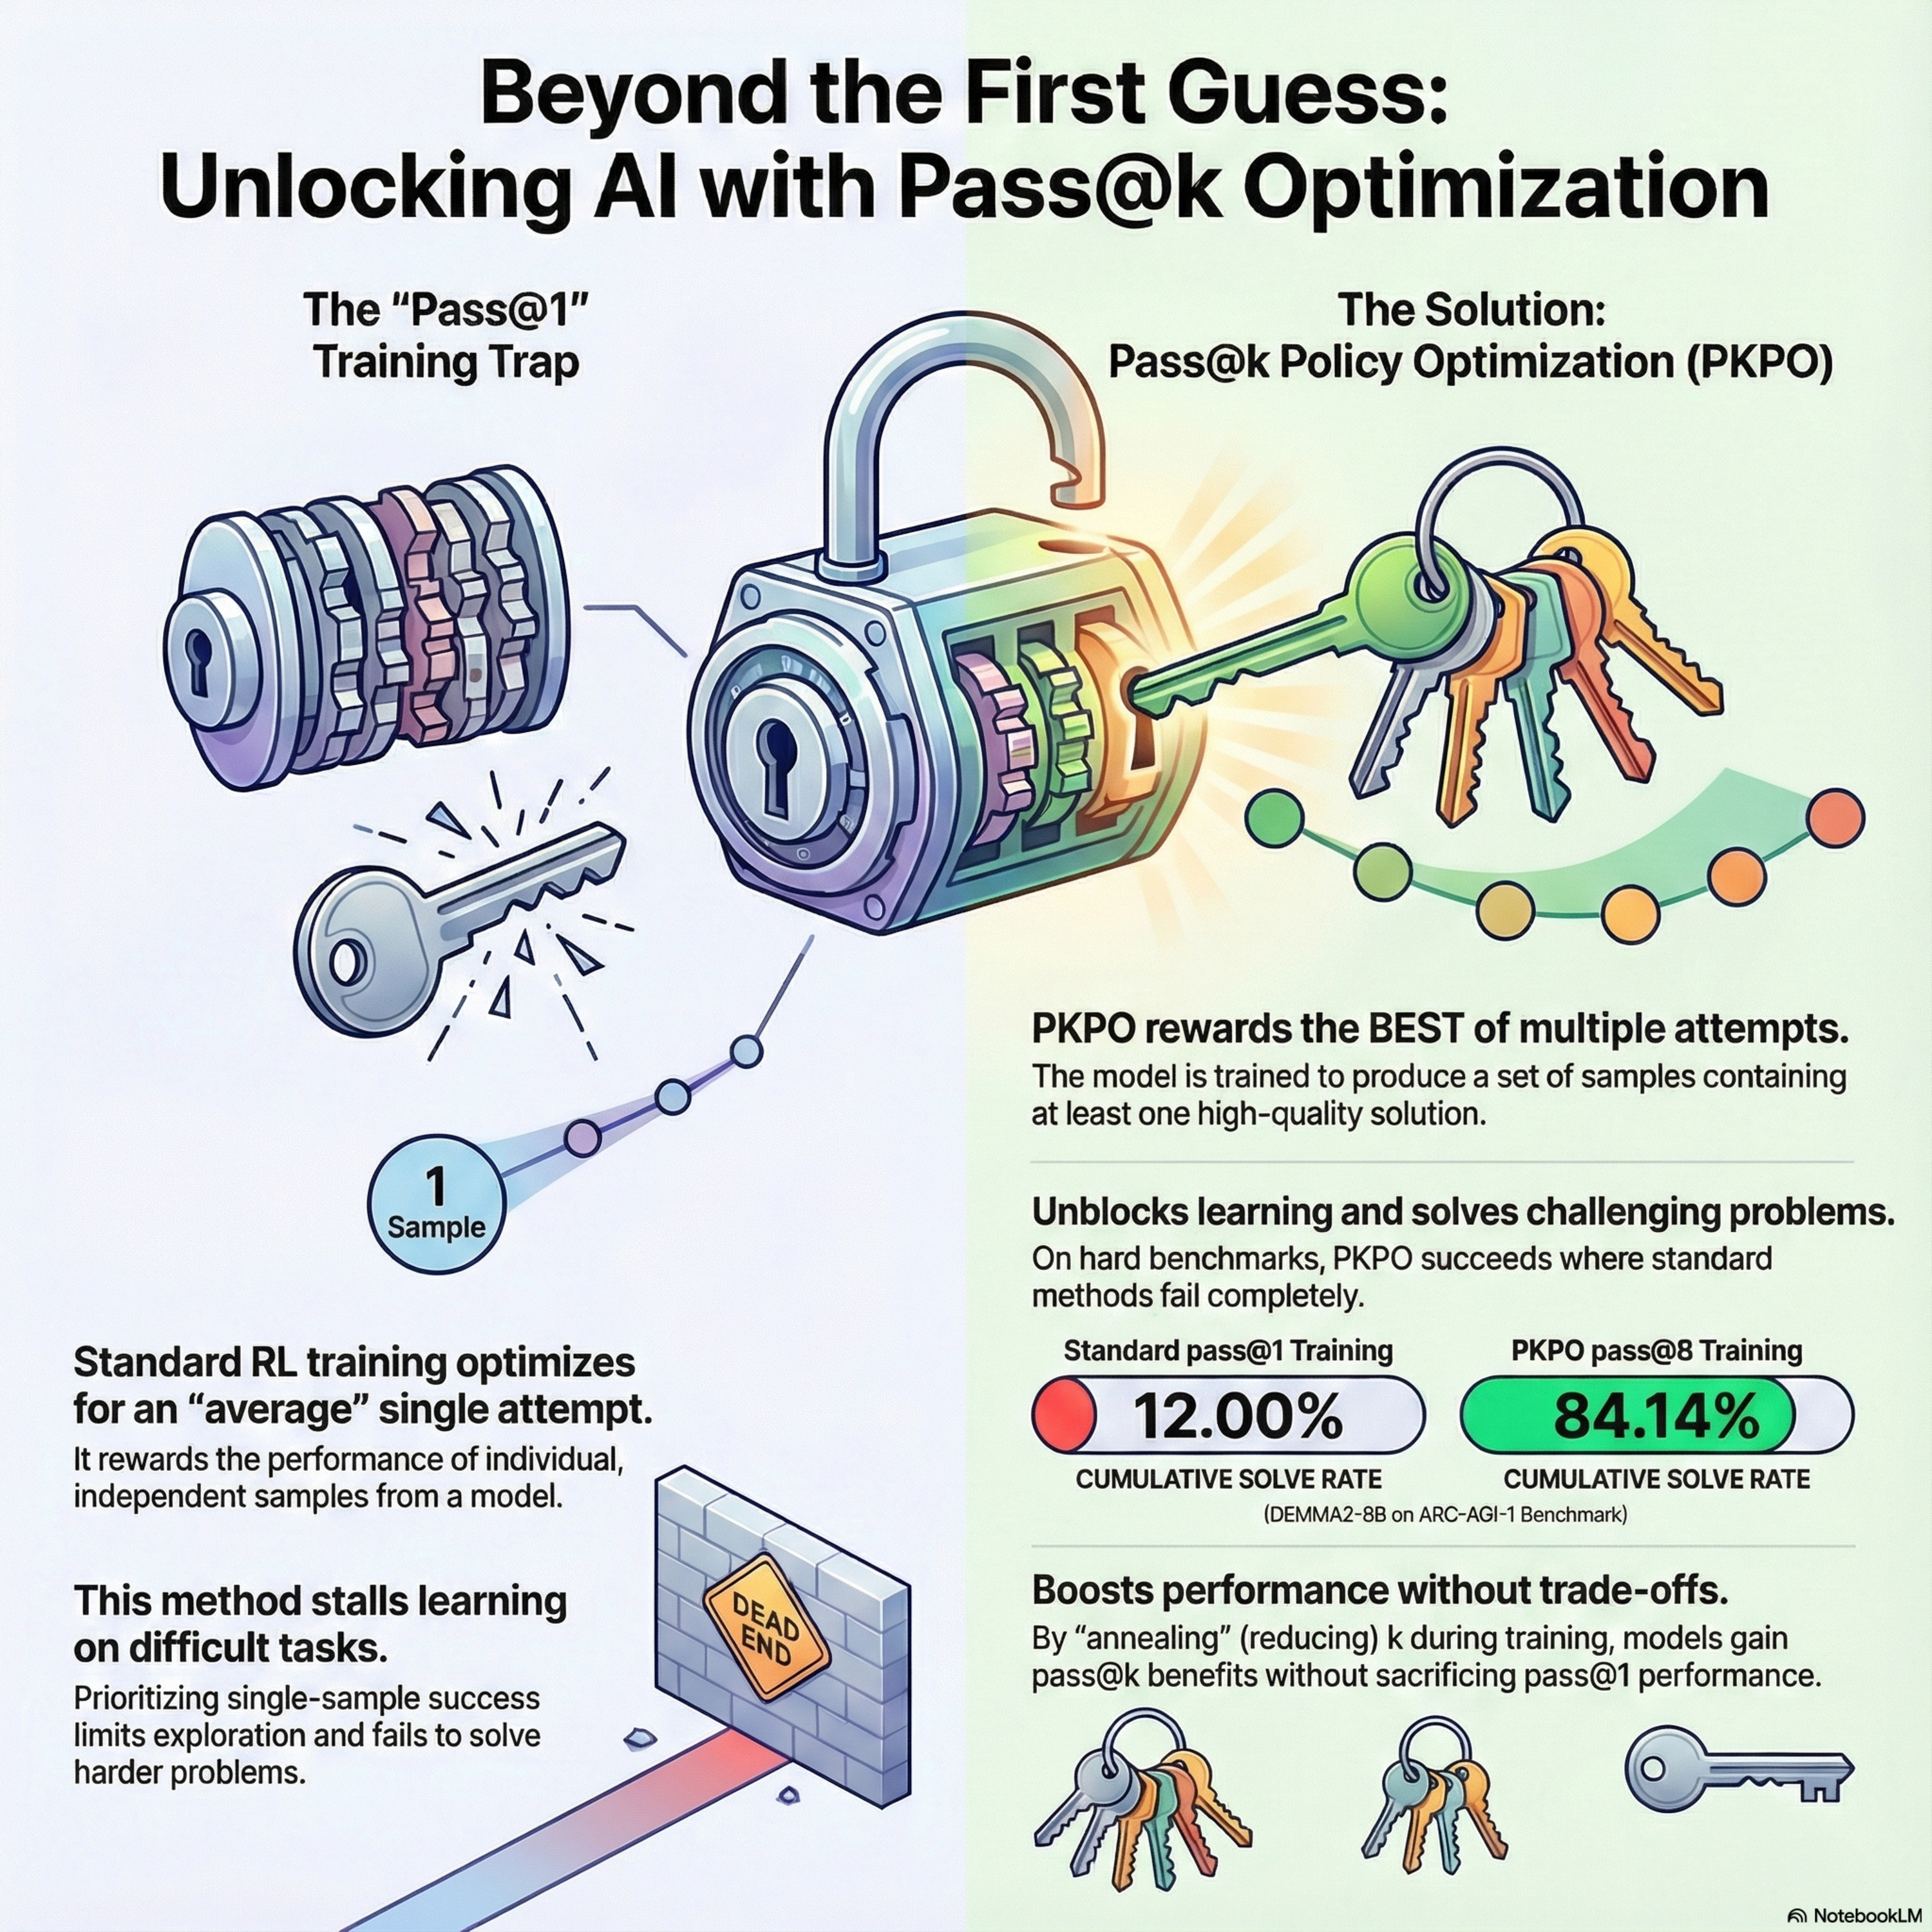
Pass@K Policy Optimization: Solving Harder Reinforcement Learning Problems
Pass@K Policy Optimization (PKPO) for reinforcement learning of LLMs on objective, high-stakes tasks (code/unit tests, theorem correctness).
3 Dec 2025 · 14m · 8 chapters
Debugging misaligned completions with sparse-autoencoder latent attribution
Debugging LLM misalignment by using sparse autoencoder (SAE) latent attribution to identify causal internal features, avoiding “model diffing” limits (correlation, need for sibling models, expensive…
2 Dec 2025 · 30m · 12 chapters
Building Effective AI Agents \ Anthropic
How to build reliable “AI agentic systems” from Anthropic, emphasizing least complexity, transparency, and especially the agent-computer interface (ACI) for tool reliability.
2 Dec 2025 · 39m · 15 chapters
How to Correctly Report LLM-as-a-Judge Evaluations
How to report evaluations when an LLM judges another model’s outputs, arguing that “raw accuracy” is statistically biased and that confidence intervals must account for judge error.
2 Dec 2025 · 12m · 5 chapters
In-Context Learning with Hypothesis-Class Guidance
Explains in-context learning (ICL) using a testbed called ICL-HCG, where an instruction prefix describes the “hypothesis class” (the rule set to search for).
2 Dec 2025 · 13m · 6 chapters