

- Podcasts
- Technology
- Best AI papers explained

531 episodes
Best AI papers explained, page 12
by Enoch H. Kang · English
Cut through the noise. We curate and break down the most important AI papers so you don’t have to.
 Ask in Claude
 Ask in ChatGPT
All episodes, page 12

Parallel Token Generation for Language Models
Parallel Token Prediction (PTP) for language models to reduce slow sequential token-by-token generation latency by predicting multiple interdependent future tokens in a single forward pass.
2 Jan 2026 · 16m · 11 chapters
Posterior Behavioral Cloning: Pretraining BC Policies for Efficient RL Finetuning
Posterior Behavioral Cloning (POSTBC) improves reinforcement learning (RL) fine-tuning by better pretraining policies, focusing on sample efficiency in expensive continuous robotics.
31 Dec 2025 · 16m · 12 chapters
Activation oracles: training and evaluating llms as general-purpose activation explainers
Activation oracles (AOs) as “universal translators” that decode an LLM’s internal activations into natural-language answers for auditing and safety.
30 Dec 2025 · 15m · 10 chapters
Emergent temporal abstractions in autoregressive models enable hierarchical reinforcement learning
How “internal reinforcement learning” leverages temporally abstract sub-goals already encoded in frozen autoregressive models to enable efficient hierarchical RL under sparse rewards.
29 Dec 2025 · 14m · 6 chapters
Joint-Embedding vs Reconstruction: Provable Benefits of Latent Space Prediction
Self-supervised learning “label problem” and a theory comparing reconstruction-based SSL (SSLRC) vs joint-embedding SSL (SSLJE), showing why more data can’t fix bad augmentations.
29 Dec 2025 · 14m · 6 chapters
Monitoring Monitorability/ OpenAI
The episode argues that as frontier AI becomes more autonomous, “monitorability” is a load-bearing safety layer: reliable, verifiable detection of harmful or misaligned behavior during deliberation…
28 Dec 2025 · 14m · 7 chapters
Detailed Balance in Large Language Model-Driven Agents
LLM-driven agents (with memory, tool use, code, iteration) are modeled as state-space dynamics that obey “detailed balance,” implying an underlying macroscopic potential function learned during…
28 Dec 2025 · 12m · 6 chapters
Learning to reason in LLMs by expectation maximization
The episode explains a research paper that frames LLM “chain-of-thought” training as a latent-variable model approximated by expectation maximization (EM).
28 Dec 2025 · 14m · 7 chaptersExploratory Causal Inference in SAEnce
Exploratory causal inference (ECI) for modern science using learned measurements from foundation models and sparse autoencoders, addressing the “Matthew effect” and a paradox where higher power…
25 Dec 2025 · 15m · 10 chapters
Detailed balance in large language model-driven agents
LLM-driven agents (with memory, tool use, and code) exhibit “detailed balance,” implying a macroscopic physical law: transitions between agent states follow a global potential function.
24 Dec 2025 · 12m · 5 chapters
The Prism Hypothesis: Harmonizing Semantic and Pixel Representations via Unified Autoencoding
The episode explains the PRISM hypothesis and its model implementation, Unified Autoencoding (UAE), which aim to unify semantic (meaning) and pixel (visual detail) representations in one latent space…
24 Dec 2025 · 16m · 7 chapters
Adaptation of Agentic AI
Agentic AI adaptation roadmaps—four paradigms (A1, A2, T1, T2) for making AI autonomous and improving it, plus safety risks and the move toward hybrid co-adaptation.
23 Dec 2025 · 13m · 6 chapters
Posterior Behavioral Cloning: Pretraining BC Policies for Efficient RL Finetuning
Challenges with standard behavioral cloning (BC) as pretraining for robotics RL fine-tuning; proposes Posterior Behavioral Cloning (POSTBC) to improve “demonstrator action coverage” and sample…
22 Dec 2025 · 11m · 6 chapters
Let’s (not) just put things in Context: Test-Time Training for Long-Context LLMs
Long-context LLMs fail at “needle in a haystack” retrieval due to score dilution in self-attention; the episode explains the math and presents Query-only Test-Time Training (QTTT) as a fix.
21 Dec 2025 · 14m · 7 chapters
TabPFN-2.5: Advancing the State of the Art in Tabular Foundation Models
TabPFN-2.5, a “tabular foundation model” for structured data that aims to eliminate per-dataset hyperparameter tuning while improving accuracy, calibration, and scalability.
20 Dec 2025 · 15m · 10 chapters
What’s In My Human Feedback? Learning Interpretable Descriptions of Preference Data
Explains “WIMHF” (What’s In My Human Feedback), a method to make human preference data interpretable by discovering sparse, human-readable features behind which response wins in pairwise comparisons.
19 Dec 2025 · 16m · 8 chapters
Bolmo: Byteifying the Next Generation of Language Models
The episode explains tokenization as a foundational barrier in LLMs and introduces BOLMO, a byte-level “tokenization-free” (UTF-8 bytes) open LLM family that removes subword tokenization issues via…
19 Dec 2025 · 13m · 7 chapters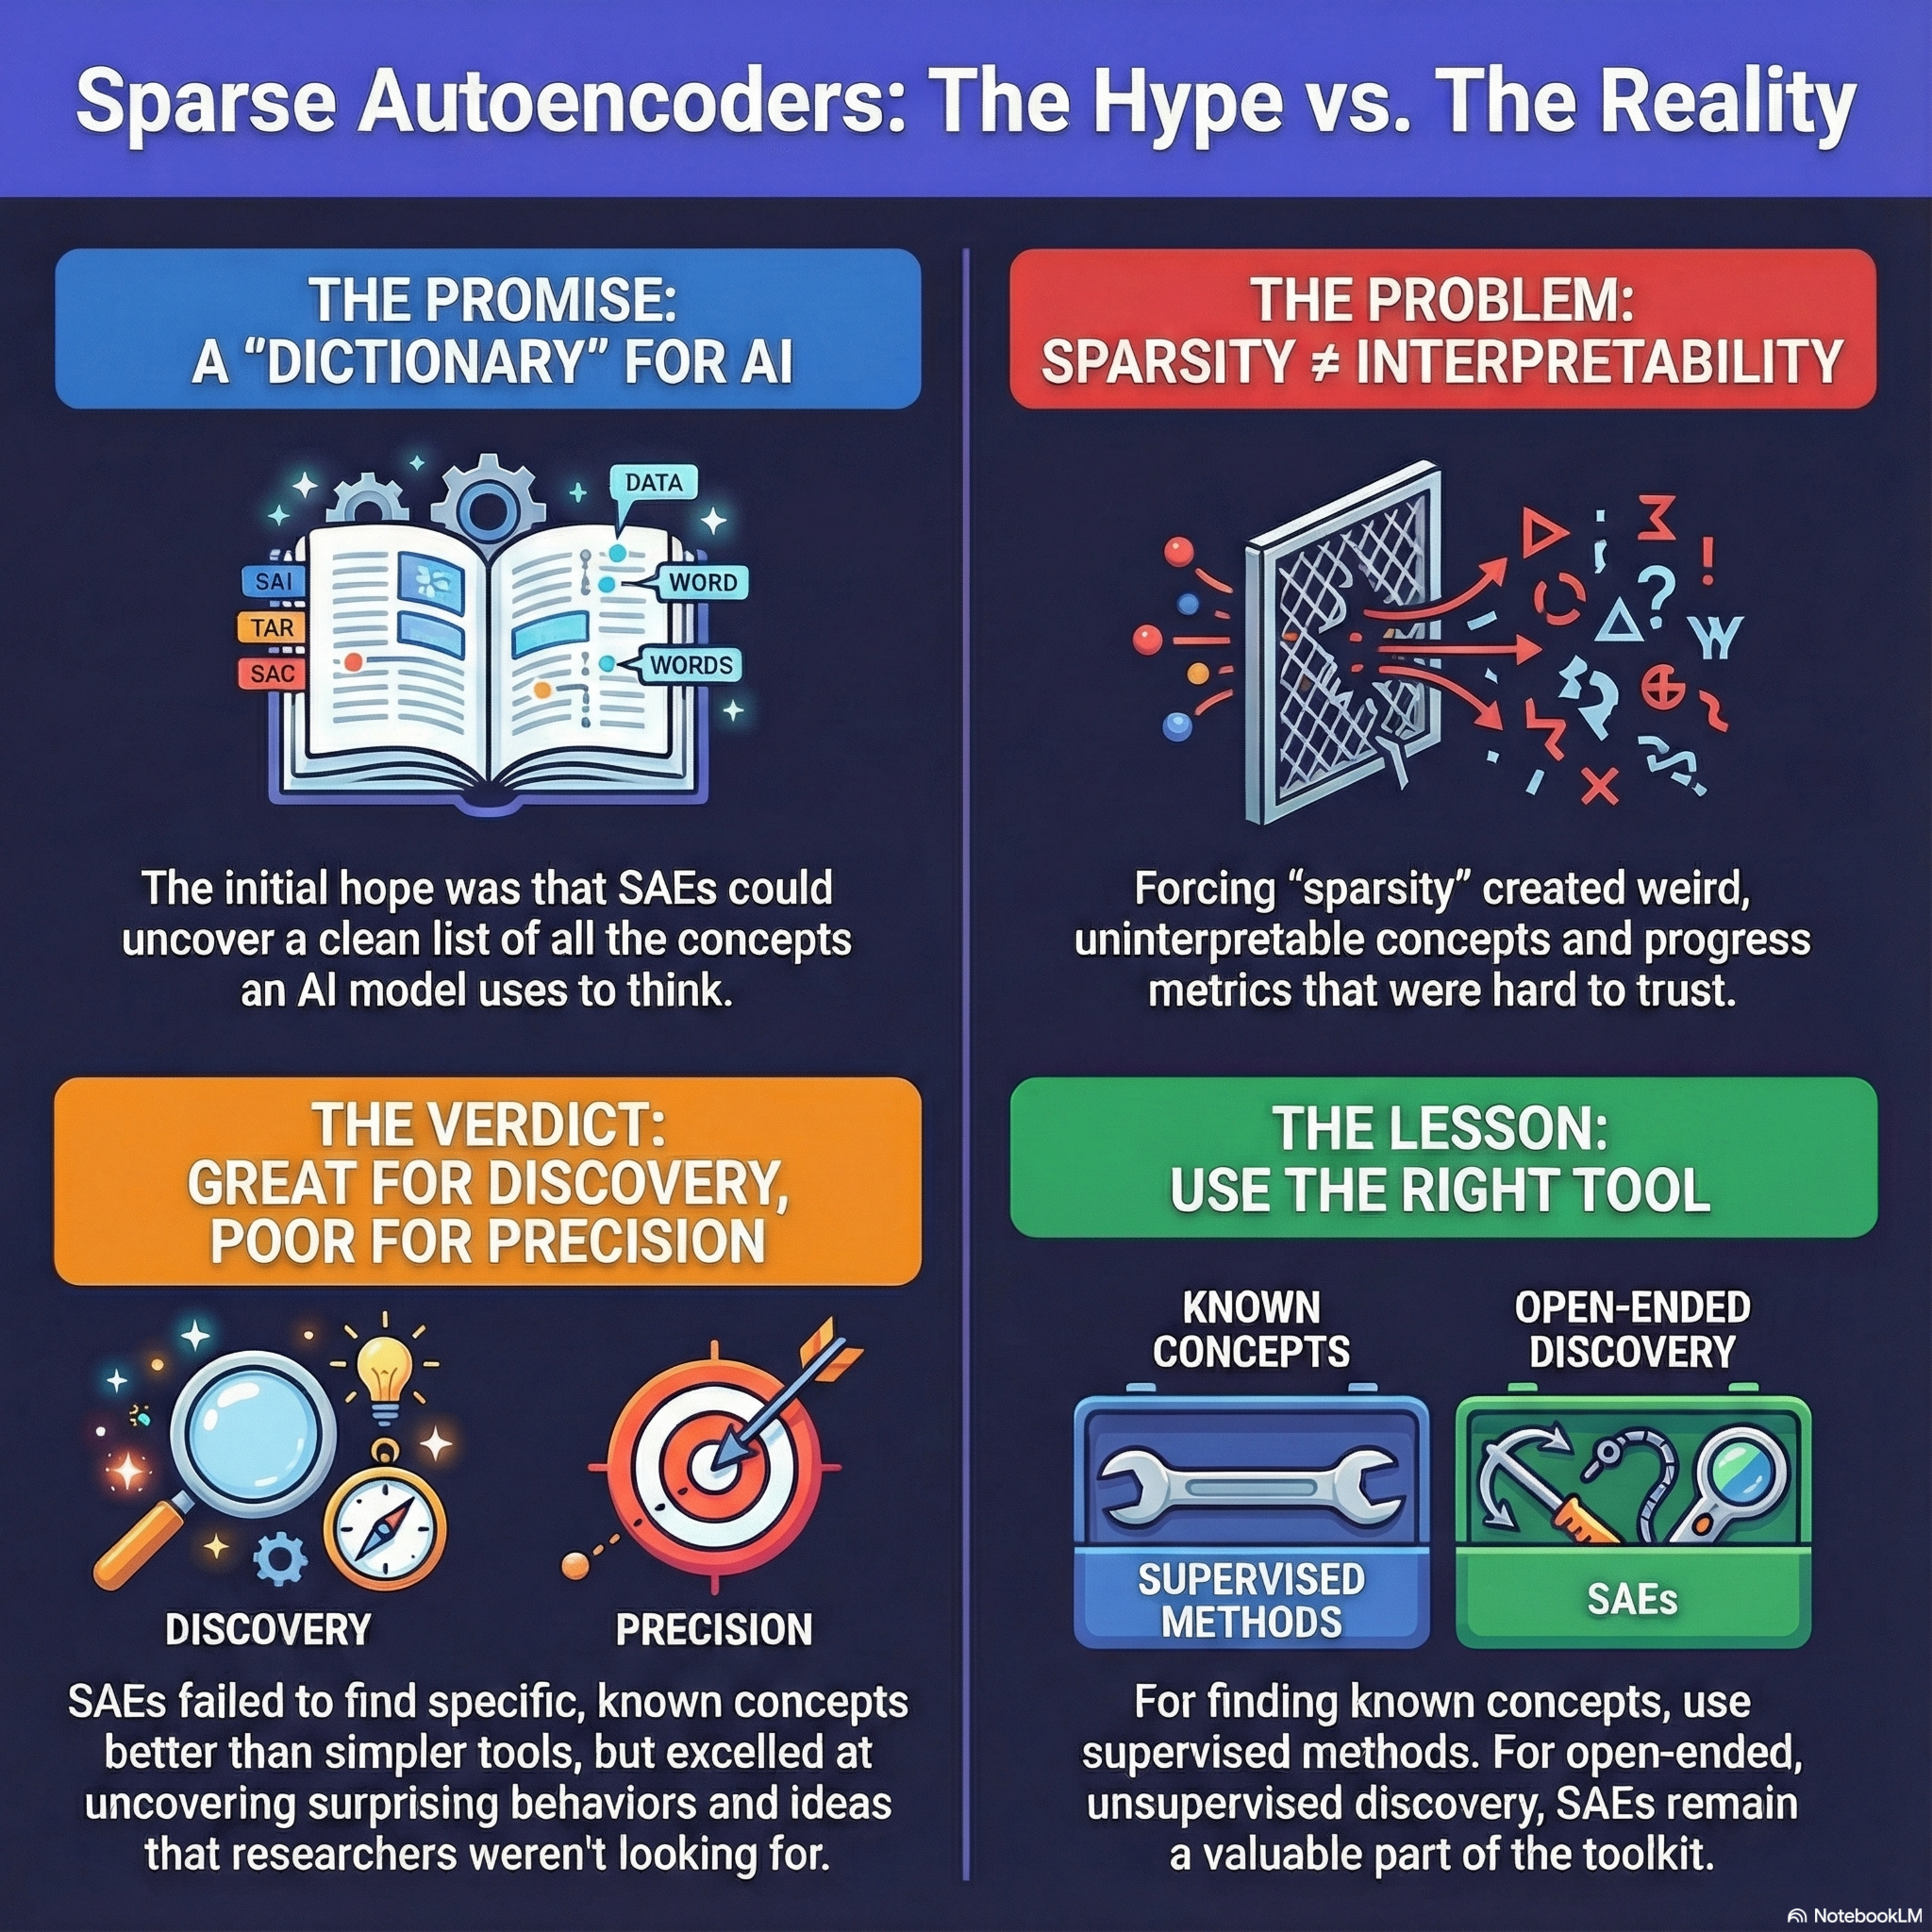
What happened with sparse autoencoders?
The “sparse autoencoder (SAE) saga” in AI interpretability—why SAEs initially looked like they could recover monosemantic features, how evaluation/analysis traps broke that optimism, and how the…
17 Dec 2025 · 30m · 17 chapters
What Matters Right Now in Mechanistic Interpretability
Mechanistic interpretability (MI) must pivot to keep up with newer, more capable “agentic” and reasoning models, focusing on diagnosis for safety rather than surgical control.
16 Dec 2025 · 33m · 15 chapters
CLaRa: Bridging Retrieval and Generation with Continuous Latent Reasoning
Retrieval-Augmented Generation (RAG) inefficiencies and hallucinations; introduces CLaRa (Continuous Latent Reasoning) to unify retrieval and generation via continuous compressed “memory tokens,”…
16 Dec 2025 · 15m · 7 chapters
Self-Improving AI and Human Co-Improvement for Safer Co-Superintelligence
Whether AI should pursue autonomous self-improvement (recursive, potentially unbounded) versus “co-improvement” with humans to achieve safer “co-superintelligence,” accelerating discovery while…
16 Dec 2025 · 13m · 10 chapters
Towards a Science of Scaling Agent Systems / Google Deepmind
DeepMind research argues there’s no universal “more agents is better” rule; multi-agent LLM performance depends on task structure and coordination topology, with major cost/fragility tradeoffs.
15 Dec 2025 · 16m · 10 chapters
Emergent hierarchical reasoning in LLMs through reinforcement learning
How reinforcement learning reveals emergent hierarchical reasoning in LLMs, explaining “aha moments” and length scaling, and proposing Hierarchy Aware Credit Assignment (HICRA/IICRA) to target…
14 Dec 2025 · 13m · 8 chapters
AI revolution finally comes to Relational foundational models for structured data
Relational foundation models (RFMs) for structured enterprise data—treating databases as graphs so a frozen, pre-trained transformer can make fast, forward-looking predictions without manual feature…
13 Dec 2025 · 15m · 10 chapters